> ## Documentation Index
> Fetch the complete documentation index at: https://notes.kodekloud.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Tokens and Tokenization
> Explains tokens and tokenization for LLMs, their impact on cost, speed, context windows, tokenizer differences, and practical guidance for estimating and optimizing token usage.
Large language models (LLMs) do not read text the way humans do. You see words; an LLM sees tokens.
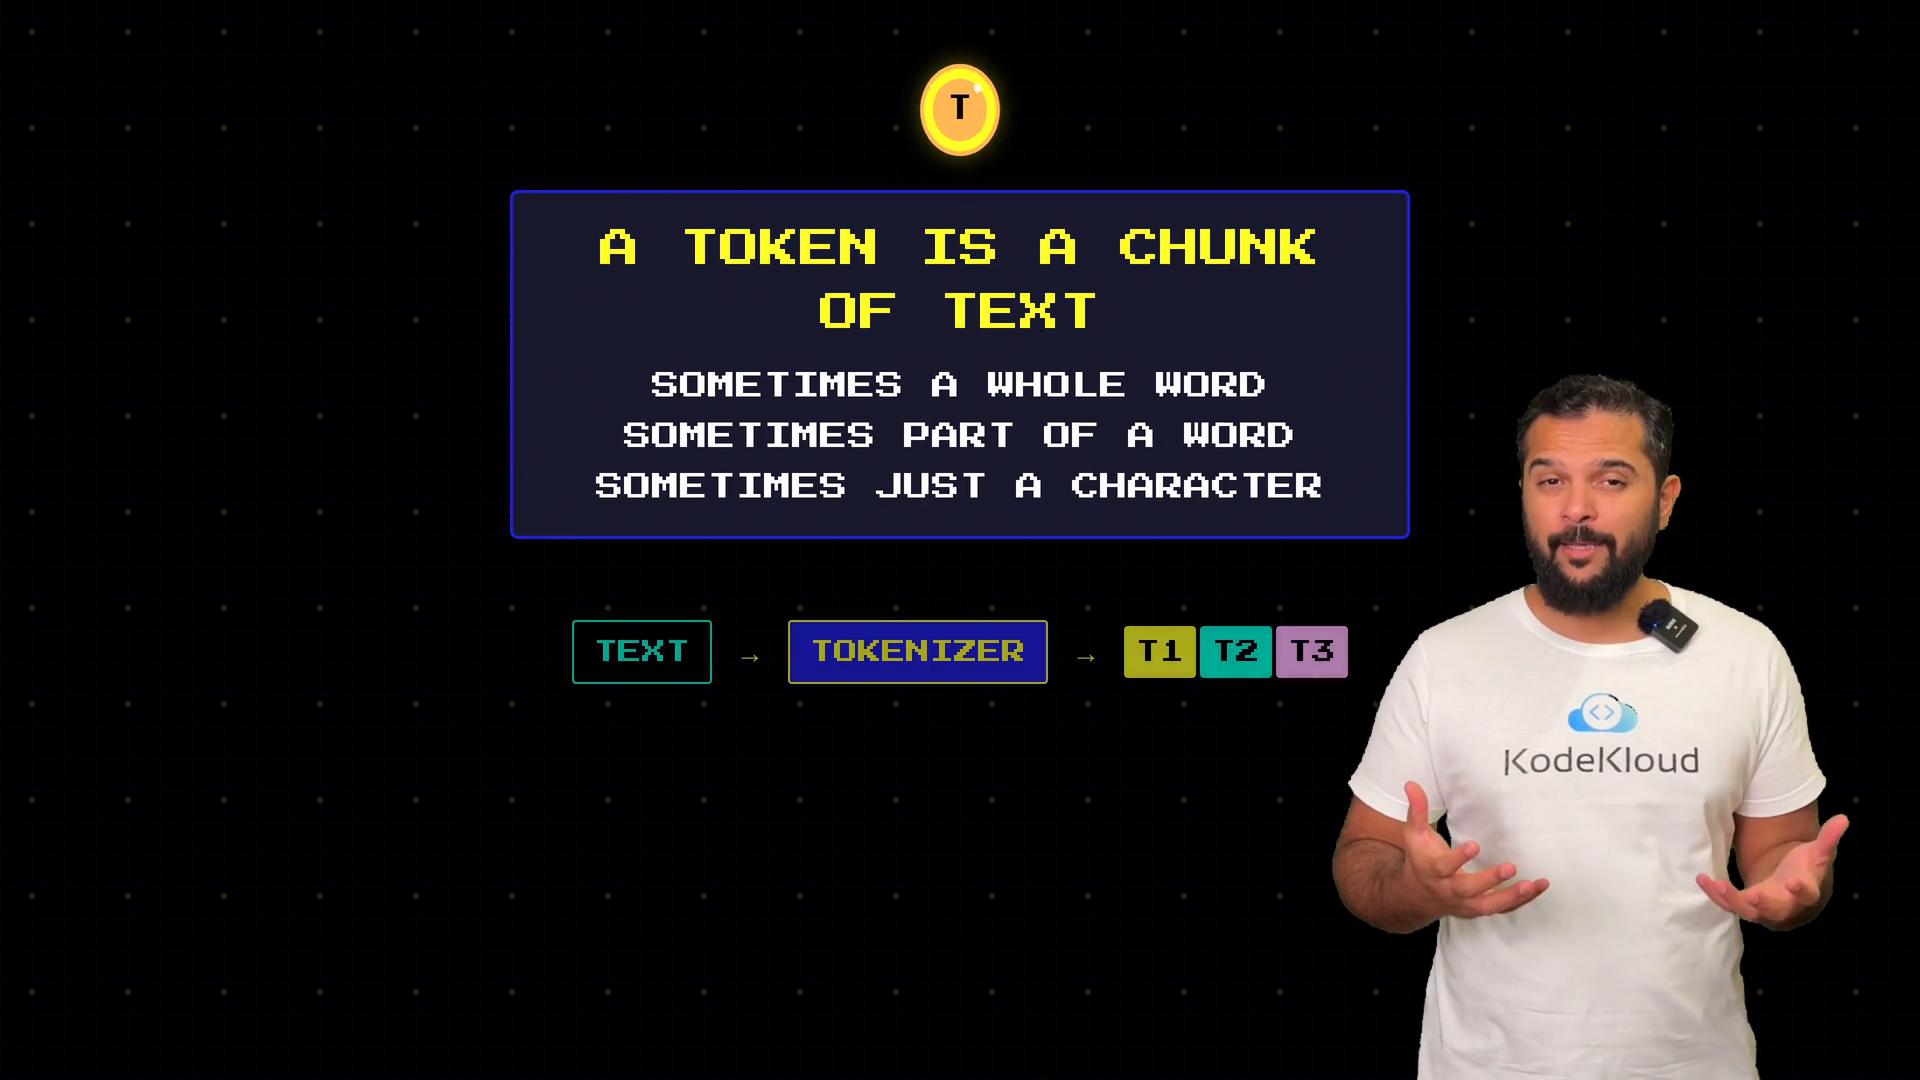
A token is a chunk of text — sometimes a whole word, sometimes part of a word, and sometimes a single character. Before an LLM processes anything you type, it first breaks your text into these tokens. This step is called tokenization.
 Why tokenization matters
* Tokens determine cost: providers bill per token for both input and output.
* Tokens determine speed: models generate text token-by-token.
* Tokens determine what the model can consider at once: the context window limit is measured in tokens.
Concrete example
* Sentence: `The tokenization process is fascinating.`
* One possible tokenization: `The`, `token`, `ization`, `process`, `is`, `fascinating`.
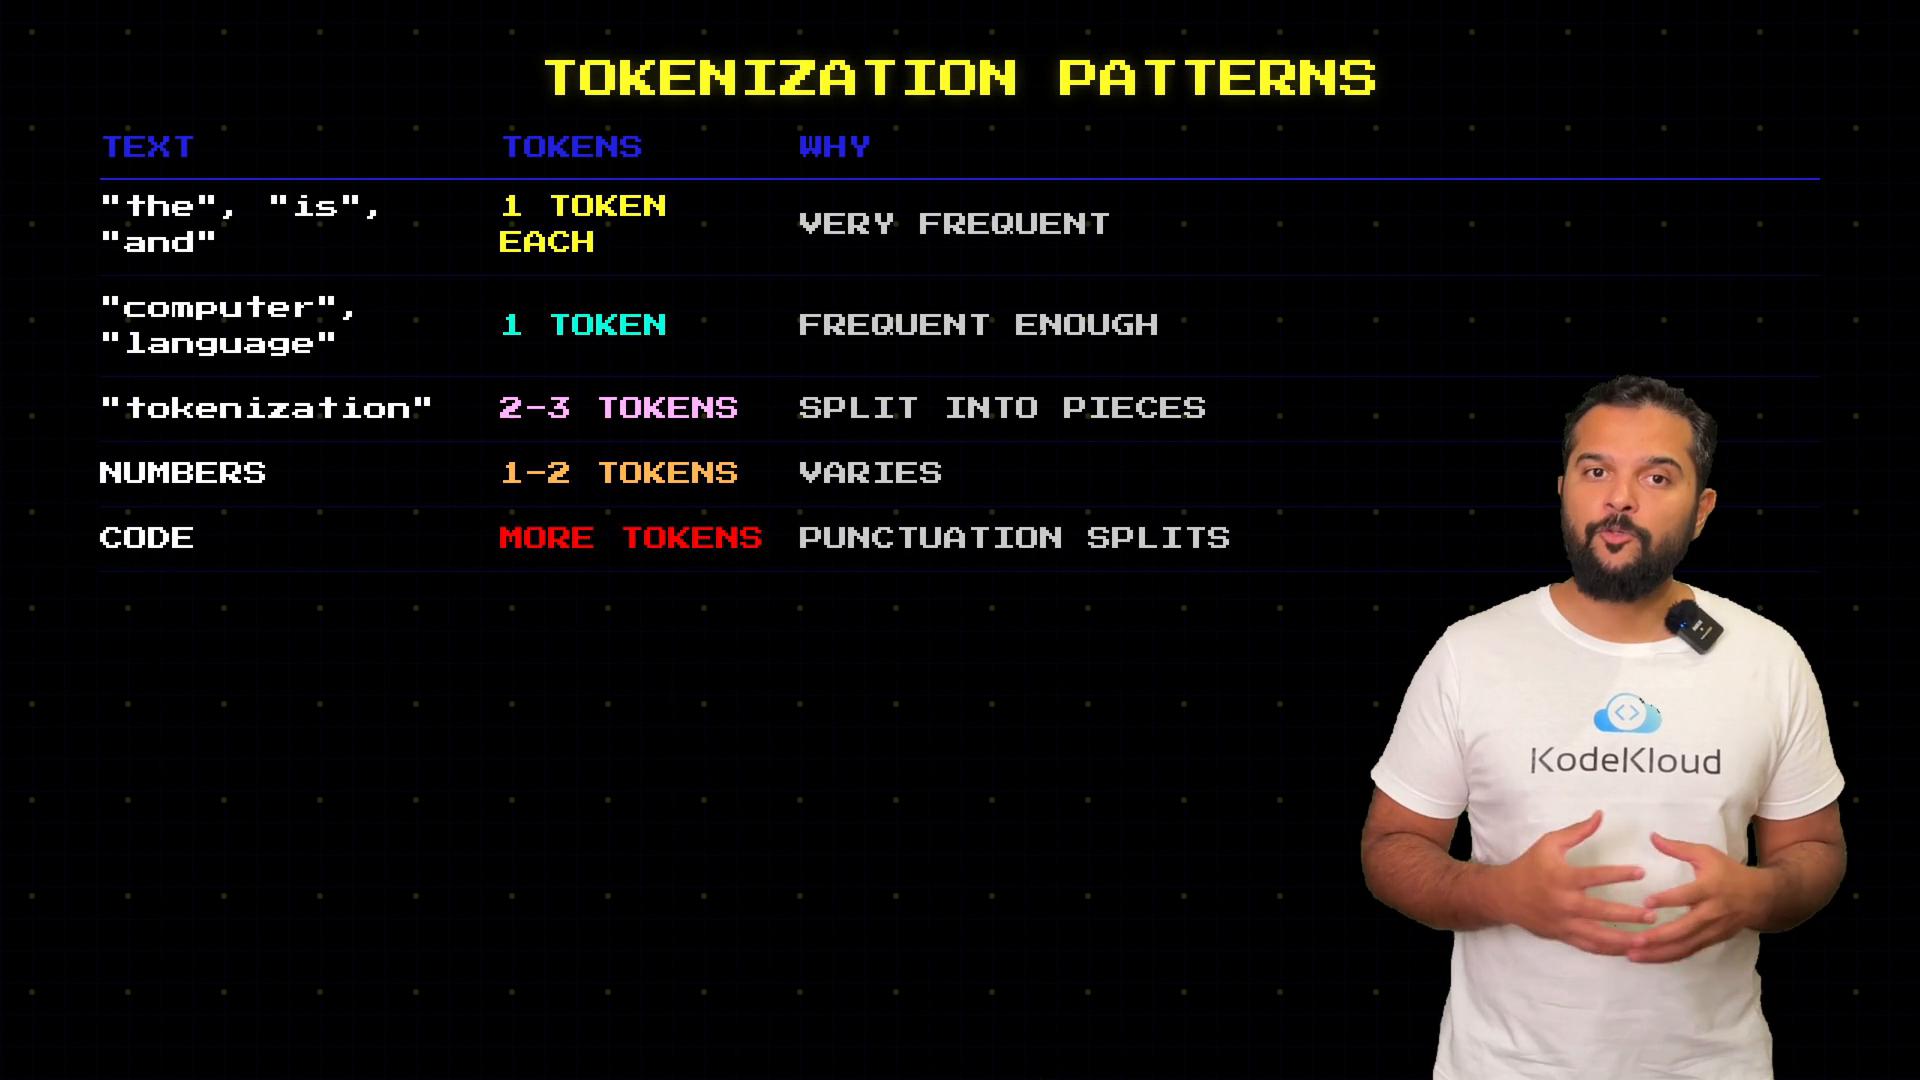
Most common words remain single tokens because they occur frequently in training data. Less common or technical words are split into sub-word pieces. Tokenizers learn these reusable sub-word units so the model can handle words it has never seen before (for example, if it knows `token` and `ization`, it can generalize to `visualization`, `globalization`, etc.). Rare or highly specialized terms usually break into more tokens and therefore cost more to process. Code and punctuation often increase token counts because tokenizers split punctuation and keywords separately; non-English text can also use more tokens per word depending on tokenizer training data.
 Quick rules of thumb
| Concept | Approximate value | Notes |
| - | -: | - |
| Characters per token (English) | ≈ 4 characters | Rough average; depends on language and punctuation. |
| Tokens per word (English) | ≈ 0.75 words | A 1,000-word essay ≈ 1,300–1,500 tokens (approximate). |
| Tokenization behavior | Frequency-based | Common words often map to single tokens; rare words split into more tokens. |
Why tokens directly affect your applications
Cost
* Providers usually charge per token for both input (prompt/context) and output (model-generated tokens).
* Output tokens are often costlier because generation is autoregressive: the model processes input once but generates output token-by-token.
Example pricing (illustrative — check current rates with your provider):
* Input tokens: \~\$2.50 per 1,000,000 tokens
* Output tokens: \~\$10.00 per 1,000,000 tokens
Token costs can accumulate quickly, especially for agents that make many LLM calls or generate long outputs. Always check the latest pricing and estimate token usage before deploying at scale.
Speed
* LLMs predict one token at a time. Responses with many tokens take longer to produce.
* Shorter outputs and more compact prompts improve response latency.
Context window (input + output)
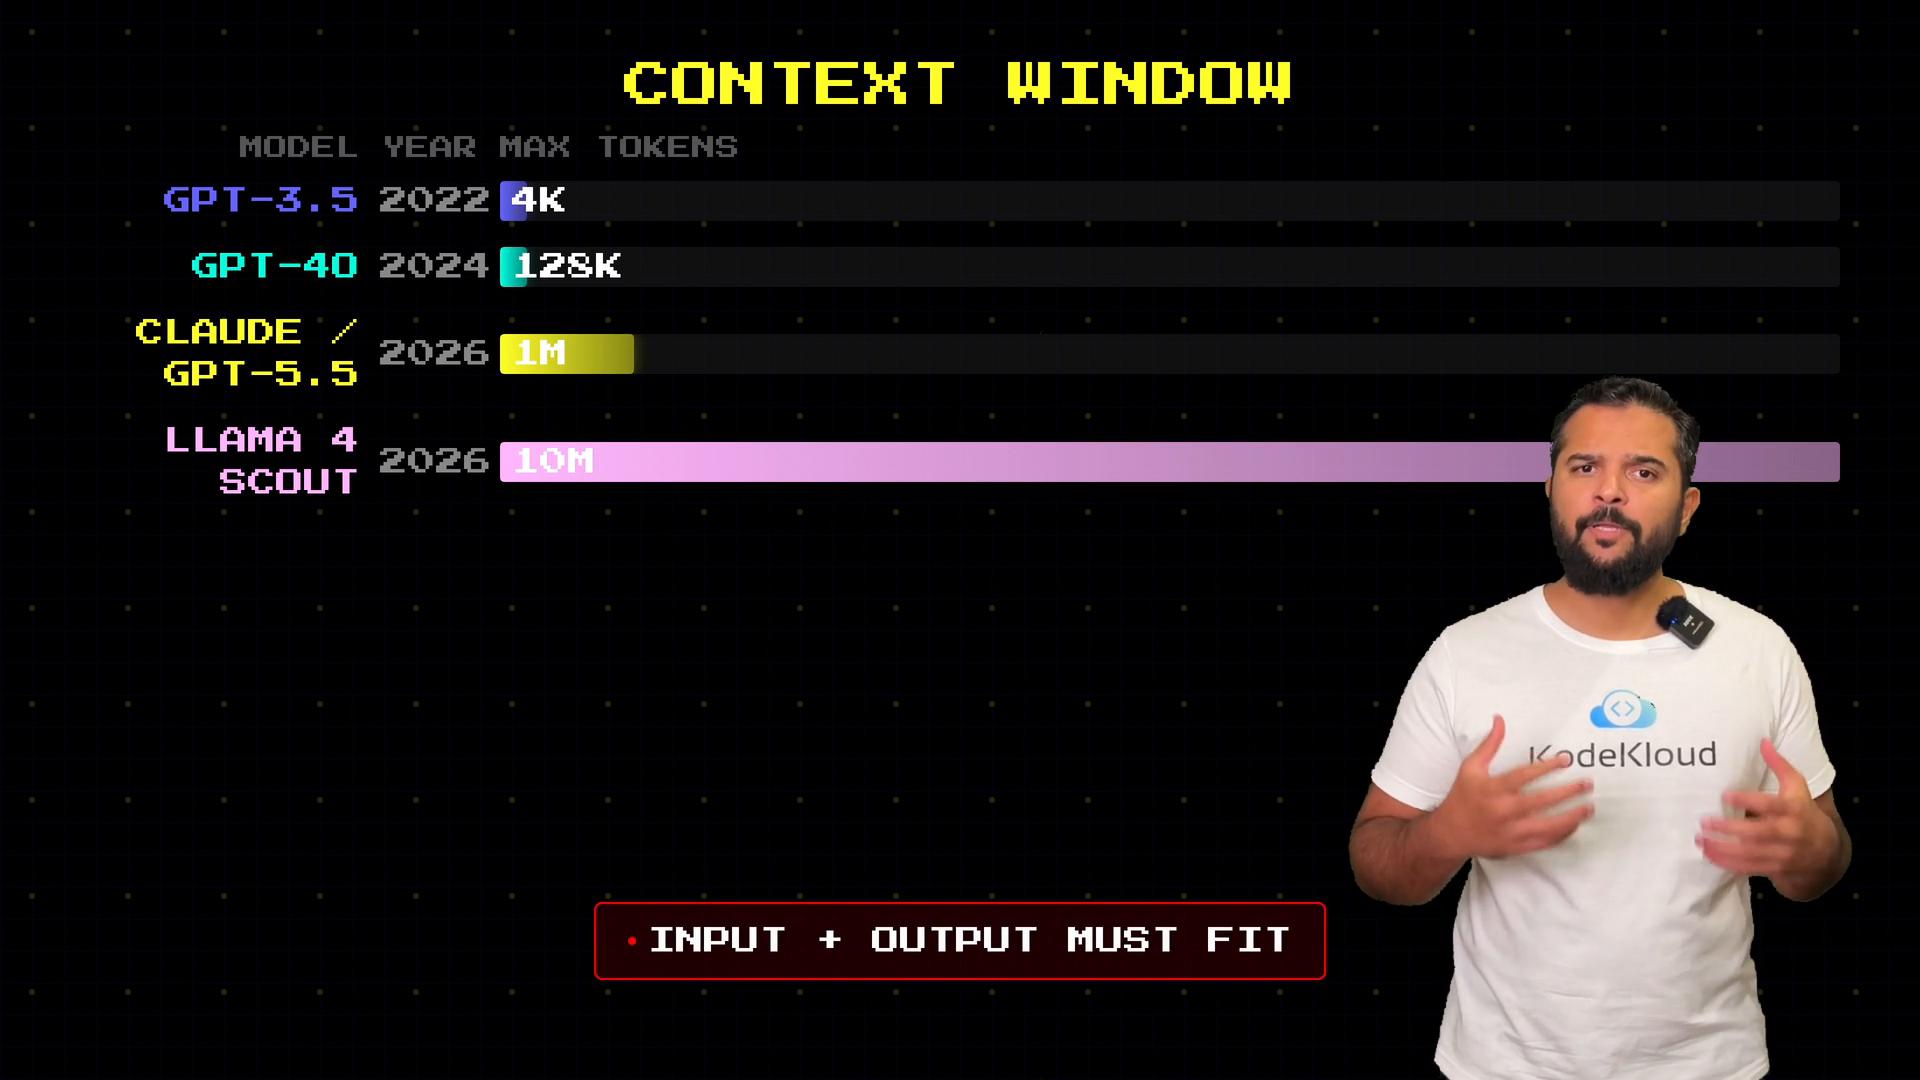
* Every model has a maximum context window measured in tokens. This is a hard limit that includes both your prompt and the model’s generated output.
* If your prompt plus the desired output exceed the context window, the model cannot process the full request.
To illustrate how context windows have expanded over time:
* GPT-3.5 (2022): \~4,000 tokens
* GPT-4o (2024): variants up to \~128,000 tokens
* Research and vendor announcements describe models supporting contexts on the order of hundreds of thousands to millions of tokens — exact limits vary by model and provider. Always check model specs.
If your combined input and output exceed the model’s context window, you must truncate, summarize, or otherwise reduce the content before sending it to the model. Later sections cover strategies for working within and around context limits.
 Different tokenizers, different counts
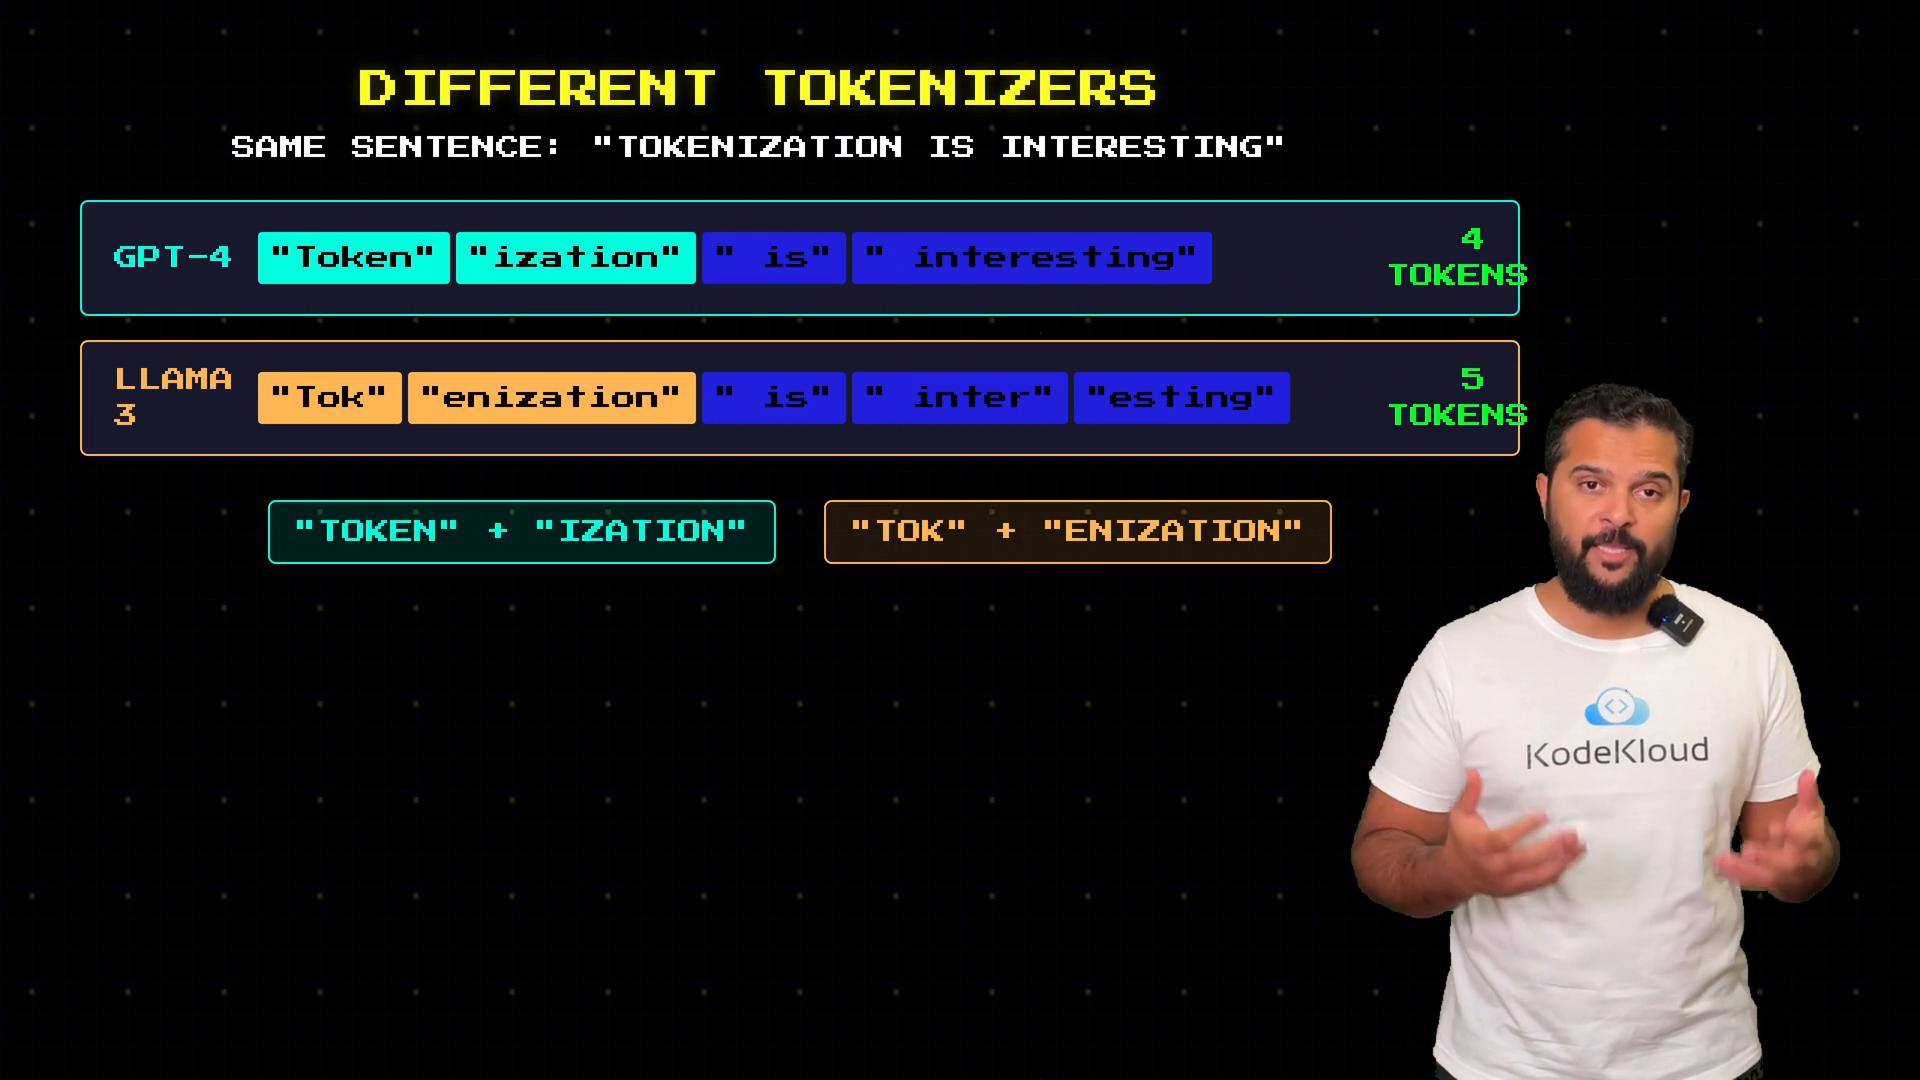
* Tokenization is not standardized across all models. Each company designs tokenizers based on its own vocabulary and training data.
* The same sentence may be 15 tokens with one tokenizer and 18 with another. Use model-specific tokenizers/tools to get accurate counts.
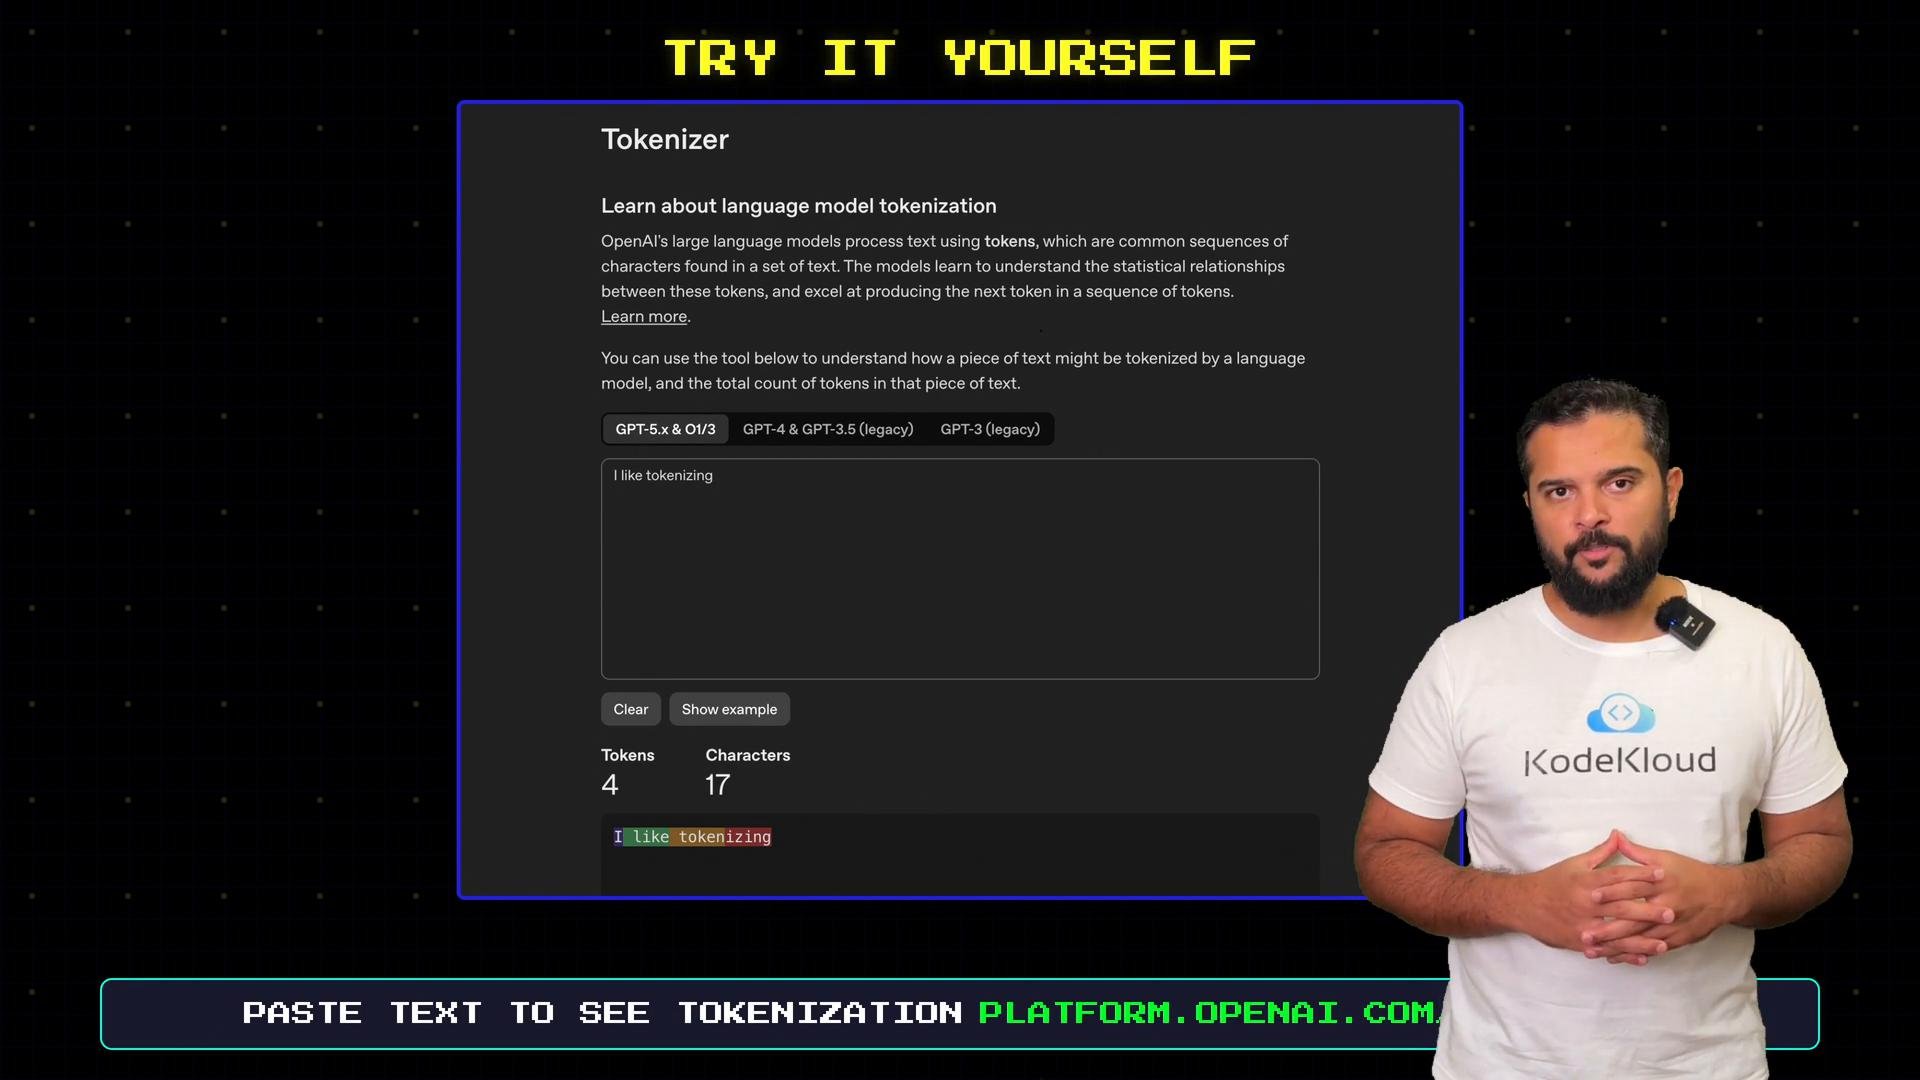
 Try it yourself
* OpenAI provides a Tokenizer tool where you can paste text and see the exact token splits for their tokenizer.
* Experiment with natural language, code, technical jargon, and non-English text to estimate token costs for your prompts and applications.
 Resources and next steps
* Tokenizer tool: [https://platform.openai.com/tokenizer](https://platform.openai.com/tokenizer)
* Check your target model’s documentation for exact context window and pricing details.
* When building agents, measure and optimize token usage for cost, latency, and context constraints.
Try several different text samples — natural English, code snippets, technical jargon, and non-English text — to see how tokenization patterns change and to estimate the token cost of your prompts.
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.