> ## Documentation Index
> Fetch the complete documentation index at: https://notes.kodekloud.com/llms.txt
> Use this file to discover all available pages before exploring further.

# AWS Infrastructure for building Gen AI Applications

> Overview of AWS infrastructure, managed services, and tools for building, training, deploying, securing, and operating generative AI applications at scale.

This lesson reviews AWS’s global infrastructure and managed services for building, training, deploying, and operating generative AI applications. It’s designed for learners with a Cloud Practitioner–level foundation (see the [AWS Cloud Practitioner (CLF-C02)](https://learn.kodekloud.com/user/courses/aws-cloud-practitioner-clf-c02) course). You don’t need to be an ML expert, but you should be familiar with Regions, Availability Zones (AZs), IAM, and managed services.

<Callout icon="lightbulb" color="#1CB2FE">
  Recommended prerequisites: basic AWS concepts (Regions, AZs, IAM), and familiarity with managed services such as S3, EC2, and RDS will help you follow the material faster.
</Callout>

Key operational questions this guide answers:

* How do you access and provide data to AI services?
* How do you select, train, tune, and deploy models?
* How do you monitor and operate those applications at scale and securely?

AWS provides tooling and managed services that lower barriers to entry, accelerate time-to-market, and deliver enterprise-grade security and governance. Pay-as-you-go and token-based pricing further reduce upfront infrastructure costs for many generative AI use cases.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/C1XsHNz87Kii35nH/images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/aws-global-infrastructure-ai-map.jpg?fit=max&auto=format&n=C1XsHNz87Kii35nH&q=85&s=3e313e312faf2565225995c508bdcc62" alt="A dark world map labeled &#x22;AWS Global Infrastructure for AI&#x22; showing white continents with AWS logos placed over several regions to indicate global service locations." width="1920" height="1080" data-path="images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/aws-global-infrastructure-ai-map.jpg" />
</Frame>

## Global footprint and deployment choices

AWS operates a global network of Regions, Availability Zones, Local Zones, and an extensive edge network. Managed services are built to leverage this footprint so you can:

* Deploy models and services in specific Regions for latency, data residency, or compliance.
* Improve fault tolerance and availability by distributing workloads across AZs or multiple Regions.
* Serve global users with edge caching and low-latency endpoints.

At scale, elasticity and pay-as-you-go models let you ramp capacity up or down. For many projects, calling hosted foundation models via token or request pricing is cost-effective because you avoid provisioning GPU fleets. For sustained, high-volume demands, dedicated accelerator-backed infrastructure (Trainium, Inferentia, GPU instances) can be more economical.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/C1XsHNz87Kii35nH/images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/cost-effectiveness-scalability-pay-per-use.jpg?fit=max&auto=format&n=C1XsHNz87Kii35nH&q=85&s=b6d59509d35567aa9d8cc18f956535e6" alt="A presentation slide titled &#x22;Cost-Effectiveness and Scalability&#x22; with three dark blue panels describing pay-for-use/token pricing, scaling generative AI without high infrastructure costs, and suitability for businesses with variable workloads. Each panel shows a simple white icon: a hand with a coin, a resize/scale arrow, and a briefcase." width="1920" height="1080" data-path="images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/cost-effectiveness-scalability-pay-per-use.jpg" />
</Frame>

## Multi-layered generative AI stack

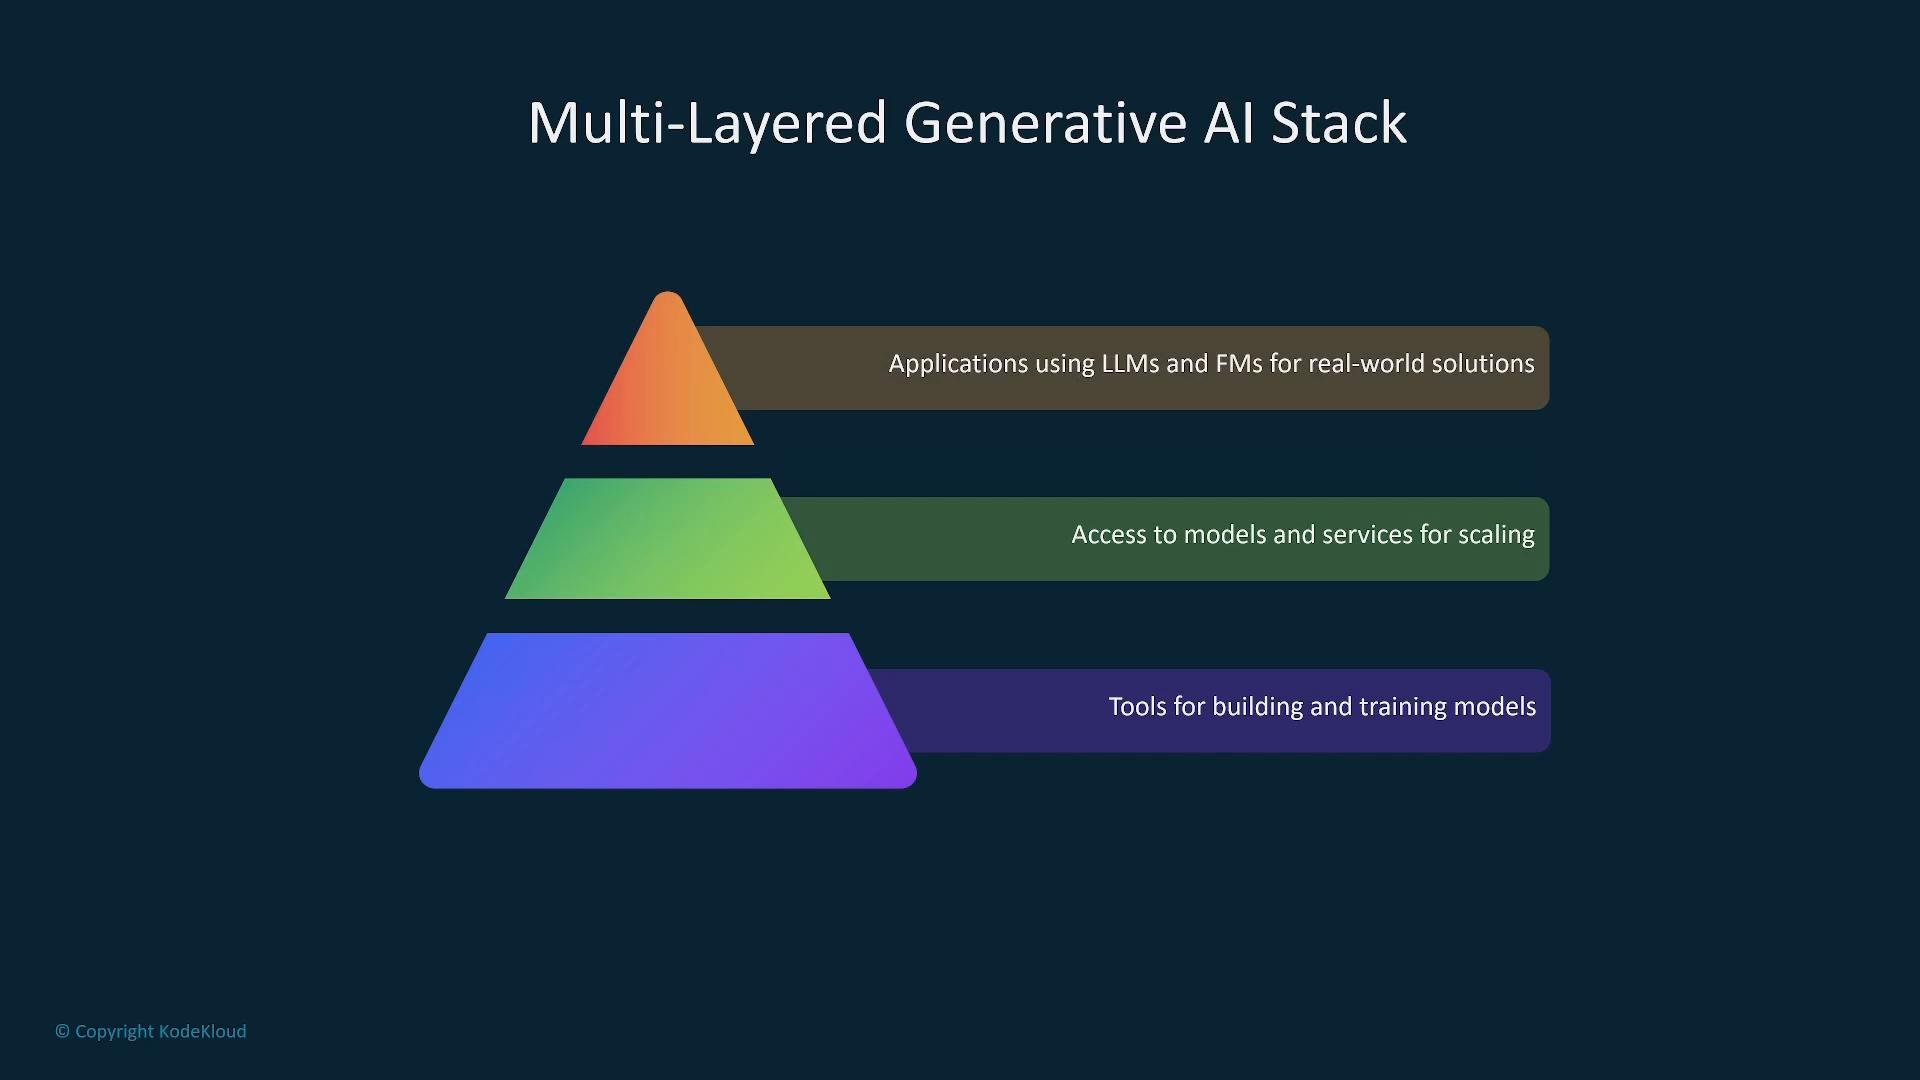
Think of the generative AI stack as three layers:

* Bottom: infrastructure and hardware (instances, accelerators, networking).
* Middle: model access and managed services (hosted foundation models, model management, MLOps).
* Top: applications (chatbots, analysis, content generation, code assistants).

Choose the right abstraction for your project—fully managed APIs, a managed ML platform like SageMaker, or custom infrastructure for training and inference.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/C1XsHNz87Kii35nH/images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/multi-layered-generative-ai-stack.jpg?fit=max&auto=format&n=C1XsHNz87Kii35nH&q=85&s=7d4211eda815aaf8d0a70190c82db4a8" alt="A dark-slide graphic showing a three-layer pyramid titled &#x22;Multi-Layered Generative AI Stack.&#x22; Each colored layer is labeled: top — applications using LLMs and FMs, middle — access to models and services, and bottom — tools for building and training models." width="1920" height="1080" data-path="images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/multi-layered-generative-ai-stack.jpg" />
</Frame>

## Key managed services and developer tooling

SageMaker and related tooling cover the full ML lifecycle: development, fine-tuning, training, deployment, and MLOps. SageMaker JumpStart is a curated catalog of pre-trained models, notebooks, and templates to bootstrap projects and adopt best practices.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/C1XsHNz87Kii35nH/images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/sagemaker-jumpstart-quickstart-models-deploy.jpg?fit=max&auto=format&n=C1XsHNz87Kii35nH&q=85&s=e696e5f9b1e8f7965a6f84361422f16a" alt="A presentation slide titled &#x22;SageMaker JumpStart – A Quick Start for AI Projects&#x22; showing two numbered panels: 01 — &#x22;Access pre-built models and datasets&#x22; with a folder/database icon, and 02 — &#x22;Industry best practices for fast deployment&#x22; with a rocket icon." width="1920" height="1080" data-path="images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/sagemaker-jumpstart-quickstart-models-deploy.jpg" />
</Frame>

Amazon Bedrock offers managed API access to foundation models from AWS and third-party providers. Bedrock abstracts infrastructure management so you can call multiple model providers via a unified API and leverage built-in tooling for safety controls and scaling.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/C1XsHNz87Kii35nH/images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/amazon-bedrock-model-playground-generative-ai.jpg?fit=max&auto=format&n=C1XsHNz87Kii35nH&q=85&s=df5cdcac41c15e7b89d4da98a3fbd5a4" alt="A presentation slide titled &#x22;Amazon Bedrock — Model Playground for Generative AI&#x22; showing three boxed points: managed API access to foundation models, choice of AWS‑curated or third‑party models (e.g., Cohere, Stability AI), and developing generative AI applications at scale." width="1920" height="1080" data-path="images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/amazon-bedrock-model-playground-generative-ai.jpg" />
</Frame>

Developer playgrounds and purpose-built application frameworks let teams experiment with prompt workflows, retrieval strategies, alignment, and fine-tuning before production. These environments are useful for verifying application behavior and integration patterns.

For conversational analytics and interactive Q\&A, the "Amazon Q" family (and backend models such as Amazon Titan) supports chat interfaces, developer tools, and analytics dashboards; they can incorporate both AWS-curated models and third-party models.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/C1XsHNz87Kii35nH/images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/foundation-models-aws-titan-cohere.jpg?fit=max&auto=format&n=C1XsHNz87Kii35nH&q=85&s=d0406831c625fd726026e816eb7c7bc6" alt="A slide titled &#x22;Foundation Models on AWS&#x22; showing logos for Amazon Titan and Cohere alongside icons labeled Text Generation, Image Generation, Code Generation, and More. The design uses a dark blue background with boxed content panels." width="1920" height="1080" data-path="images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/foundation-models-aws-titan-cohere.jpg" />
</Frame>

### Quick reference: core services and typical uses

| Service | Primary use case | Notes |
| - | - | - |
| SageMaker / SageMaker JumpStart | Model development, training, deployment, MLOps | JumpStart = pre-built models & templates |
| Amazon Bedrock | Hosted access to foundation models via API | Multi-provider choice and safety tooling |
| Amazon S3 | Durable storage for datasets and artifacts | Often used as canonical data lake |
| Amazon OpenSearch | Search + k-NN vector similarity | Good for semantic search workloads |
| Amazon Neptune | Graph-based retrieval and relationship-aware ML | Useful for knowledge graphs & RAG |
| EC2 / GPU instances, Trainium, Inferentia | Custom training/inference on dedicated accelerators | Cost-effective at high scale |

## Data infrastructure and retrieval (vectors)

To support long context windows, semantic search, and retrieval-augmented generation (RAG), convert documents to vector embeddings and store/index them for efficient retrieval. Common AWS options:

* Purpose-built search engines: Amazon OpenSearch with k-NN and vector search plugins.
* Graph databases and graph ML: Amazon Neptune / Neptune ML for relationship-aware retrieval.
* Standard data stores: RDS, Aurora, DocumentDB for metadata and pointers; specialized services or external vector DBs can store the actual embeddings and indexes.

These components let you compress/index embeddings, perform semantic search, and integrate retrieval pipelines with model inference.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/C1XsHNz87Kii35nH/images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/optimizing-ai-vector-databases-slide.jpg?fit=max&auto=format&n=C1XsHNz87Kii35nH&q=85&s=54a2fb38bf1c57816130ae66e0ad25a5" alt="A dark-themed presentation slide titled &#x22;Optimizing AI With Vector Databases&#x22; with three labeled feature boxes on the left (vector embeddings, compressed/indexed vectors, and AWS data management). On the right is a large cylindrical database graphic containing colorful connected nodes representing vector data." width="1920" height="1080" data-path="images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/optimizing-ai-vector-databases-slide.jpg" />
</Frame>

| Vector storage option | When to use it | Short example |
| - | - | - |
| Amazon OpenSearch (k-NN) | Semantic search with integrated search capabilities | Use k-NN indexes for approximate nearest neighbor queries |
| Amazon Neptune | Relationship-aware retrieval, knowledge graphs | Link entities and context for graph-based RAG |
| Managed vector DBs / external solutions | When you need specialized vector features or scale | Offload indexing and high-throughput similarity queries |

## Security, governance, and operational controls

Security and confidentiality are integral to production AI workloads. AWS offers controls across identity, infrastructure, and runtime:

* IAM policies and least-privilege roles.
* Hardware and hypervisor isolation via the AWS Nitro System.
* Dedicated ML accelerators (Inferentia, Trainium) and GPU families for isolated, performant instances.
* Monitoring and observability: CloudWatch, CloudTrail, Amazon Inspector.
* Encryption at rest and in transit, MFA, and model-specific monitoring for inputs/outputs.

These features mitigate risks such as data exfiltration, prompt injection, and compliance violations while enabling auditability and operational visibility.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/C1XsHNz87Kii35nH/images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/aws-security-generative-ai-data-protection.jpg?fit=max&auto=format&n=C1XsHNz87Kii35nH&q=85&s=8e79dd706c995d87d8bd42a271950a10" alt="A presentation slide titled &#x22;AWS Security for Generative AI Applications&#x22; showing a large AWS logo on the right. On the left are three points: &#x22;Secure data and AI workloads,&#x22; &#x22;Compliance and confidentiality,&#x22; and &#x22;Multi-layered protection for sensitive AI data.&#x22;" width="1920" height="1080" data-path="images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/aws-security-generative-ai-data-protection.jpg" />
</Frame>

| Security area | Best practices |
| - | - |
| Identity & Access | MFA, least-privilege IAM roles, temporary credentials |
| Data protection | Encrypt data in transit and at rest, use KMS for key management |
| Runtime & network | Isolate workloads with VPCs and security groups, use Nitro-backed instances where applicable |
| Monitoring & compliance | Enable CloudTrail, CloudWatch alarms, and vulnerability scanning (Inspector) |

<Callout icon="warning" color="#FF6B6B">
  Operational security considerations: implement prompt-injection defenses, content filtering, and model guardrails. Treat model inputs and outputs as data requiring logging, access controls, and retention policies.
</Callout>

<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/C1XsHNz87Kii35nH/images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/ai-systems-aws-security-features.jpg?fit=max&auto=format&n=C1XsHNz87Kii35nH&q=85&s=317b518b307b90dacff83eaad2dabbd0" alt="A presentation slide titled &#x22;AI Systems on AWS — Key Security Features&#x22; showing three numbered items: 01 Multi-factor authentication (MFA), 02 Continuous monitoring and encryption, and 03 Policies to mitigate vulnerabilities like prompt injection, each with a small icon." width="1920" height="1080" data-path="images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/ai-systems-aws-security-features.jpg" />
</Frame>

## AWS Nitro System and ML accelerators

The AWS Nitro System is a foundational platform that isolates customer workloads from the host and other tenants and delivers the I/O and security features required for many ML instance types. Specific accelerators and instance families (Trainium, Inferentia, GPU instances) are available when you need dedicated training or inference performance.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/C1XsHNz87Kii35nH/images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/aws-nitro-secure-ai-hardware-gpu.jpg?fit=max&auto=format&n=C1XsHNz87Kii35nH&q=85&s=fbbdfb5306be1995758a5da99101c14a" alt="A presentation slide titled &#x22;AWS Nitro System — Enhanced Security and Performance&#x22; showing three numbered panels with icons: a chip for specialized hardware, a shield for secure AI infrastructure, and a GPU chip indicating support for ML accelerators and GPUs." width="1920" height="1080" data-path="images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/aws-nitro-secure-ai-hardware-gpu.jpg" />
</Frame>

## Summary

AWS supports generative AI development across three layers: infrastructure and accelerators, managed model APIs and ML platforms, and application frameworks. You can:

* Use fully managed foundation models (Bedrock) for rapid prototyping and production.
* Use SageMaker for end-to-end model lifecycle, fine-tuning, and MLOps.
* Provision accelerator-backed instances for custom training or inference at high scale.

Security, governance, and cost models are central to design choices: pick managed APIs for faster delivery or dedicated infrastructure for fine-grained control and long-term cost optimization.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/C1XsHNz87Kii35nH/images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/aws-generative-ai-success-benefits.jpg?fit=max&auto=format&n=C1XsHNz87Kii35nH&q=85&s=ba9e7dee95ecee5f81e544eba8c43d8f" alt="A slide titled &#x22;AWS for Generative AI Success&#x22; with three dark, numbered panels.The panels list benefits: accessibility/efficiency/security; accelerating development with pre-built models and scalable services; and achieving cost-effective business objectives." width="1920" height="1080" data-path="images/AWS-Certified-AI-Practitioner/Fundamentals-of-Generative-AI/AWS-Infrastructure-for-building-Gen-AI-Applications/aws-generative-ai-success-benefits.jpg" />
</Frame>

Whether you use high-level managed services, containers, or provision GPUs, AWS gives you the flexibility to design architectures that meet latency, cost, and compliance needs.

Thanks for reading.

## Links and references

* [AWS Documentation](https://docs.aws.amazon.com/)
* [Amazon SageMaker](https://aws.amazon.com/sagemaker/)
* [Amazon Bedrock](https://aws.amazon.com/bedrock/)
* [Amazon OpenSearch Service](https://aws.amazon.com/opensearch-service/)
* [Amazon Neptune](https://aws.amazon.com/neptune/)
* [AWS Nitro System overview](https://aws.amazon.com/ec2/nitro/)

<CardGroup>
  <Card title="Watch Video" icon="video" cta="Learn more" href="https://learn.kodekloud.com/user/courses/aws-certified-ai-practitioner/module/34a4e82e-7538-4fac-a622-dbc6a28ffcbb/lesson/4cb761d2-cfba-4b06-859b-90094b28672b" />
</CardGroup>


This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.