> ## Documentation Index
> Fetch the complete documentation index at: https://notes.kodekloud.com/llms.txt
> Use this file to discover all available pages before exploring further.
# RAG Essentials
> Guide to building a Retrieval-Augmented Generation pipeline using embeddings, vector databases, chunking, and a Flask demo to search and generate grounded answers from large private document repositories.
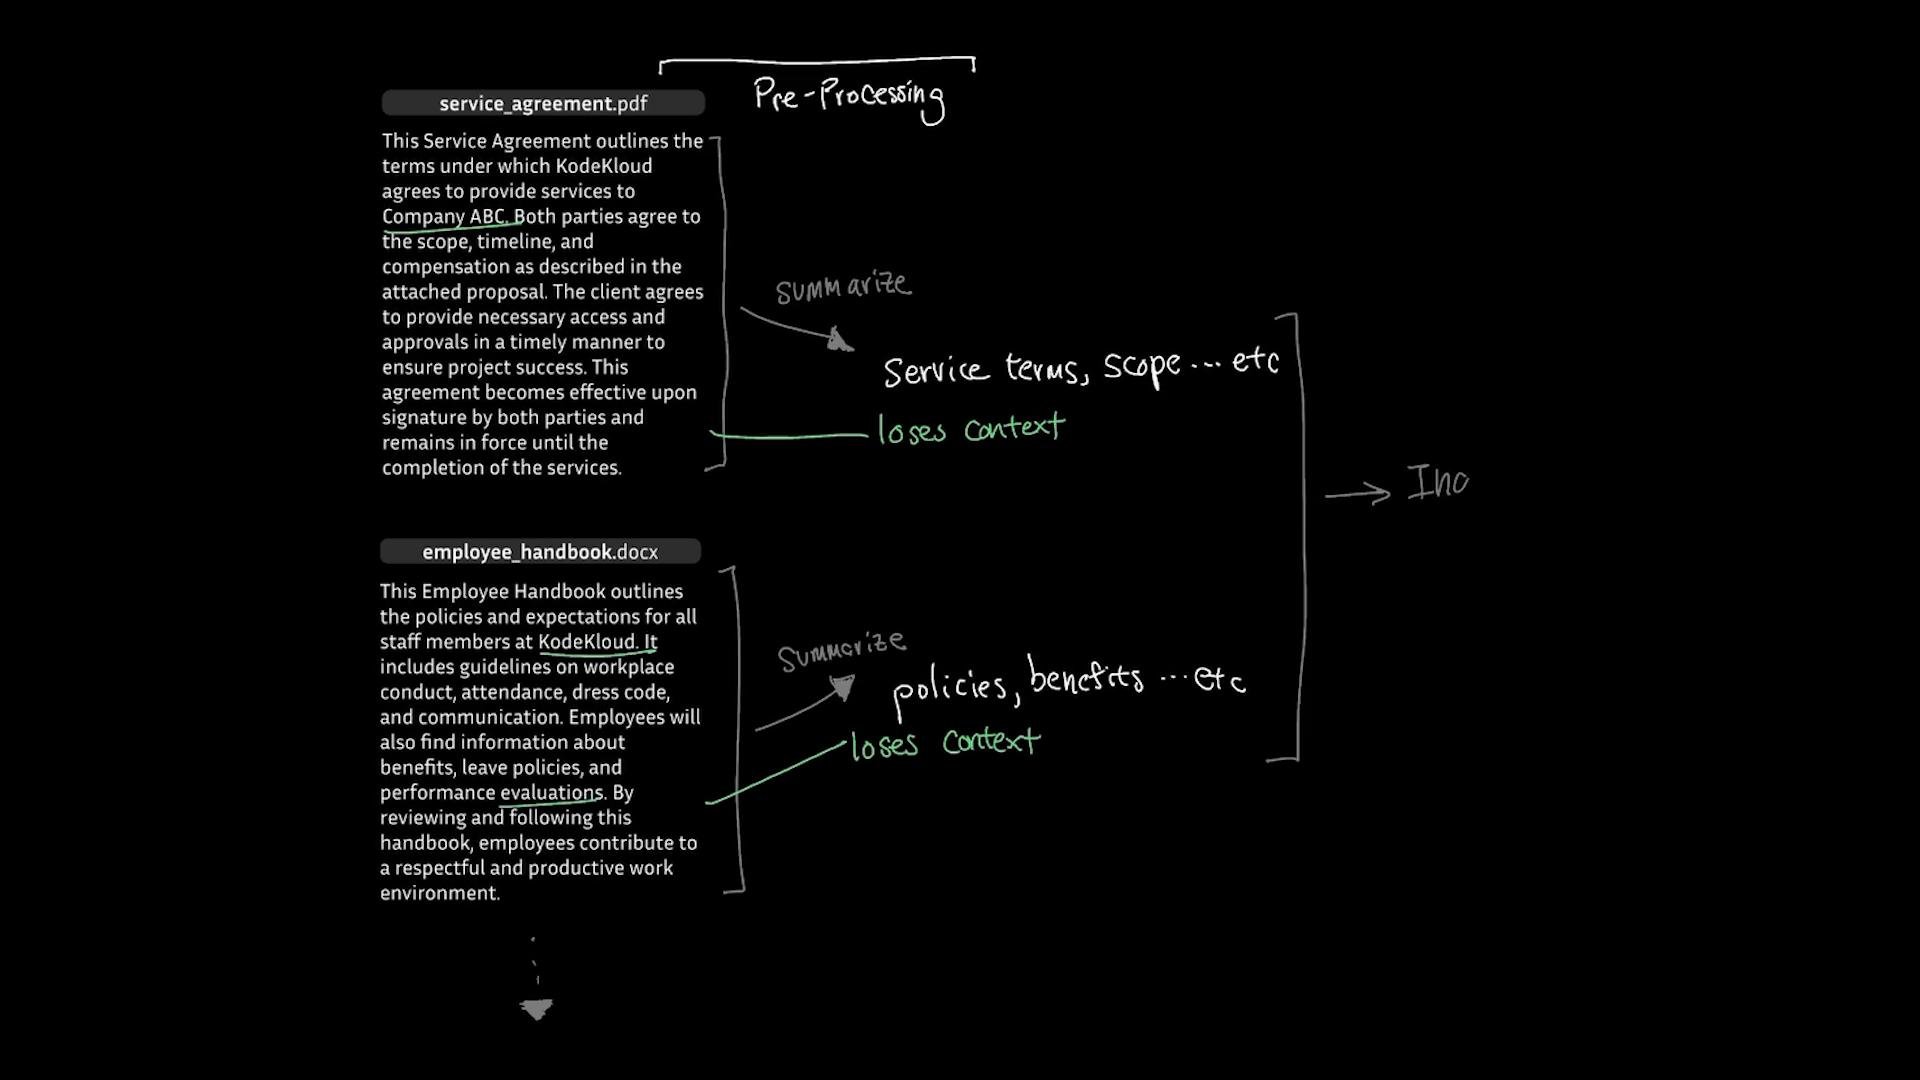
You’re asked to connect an AI assistant (e.g., ChatGPT) to a company repository containing 500 GB of documents so the assistant can answer questions about that data. Typical chat UIs can only accept a few files, so you need a solution that lets the LLM search, read, and reason over the entire dataset without rescanning 500 GB on every query.
A naive approach — scanning raw files or running fresh summarization on every query — is too slow or loses important context. The recommended pattern is Retrieval-Augmented Generation (RAG): convert documents and queries into semantic vectors (embeddings), store them in a vector database, and at query time retrieve the most relevant chunks to augment the LLM prompt.
 ## What RAG does (high-level)
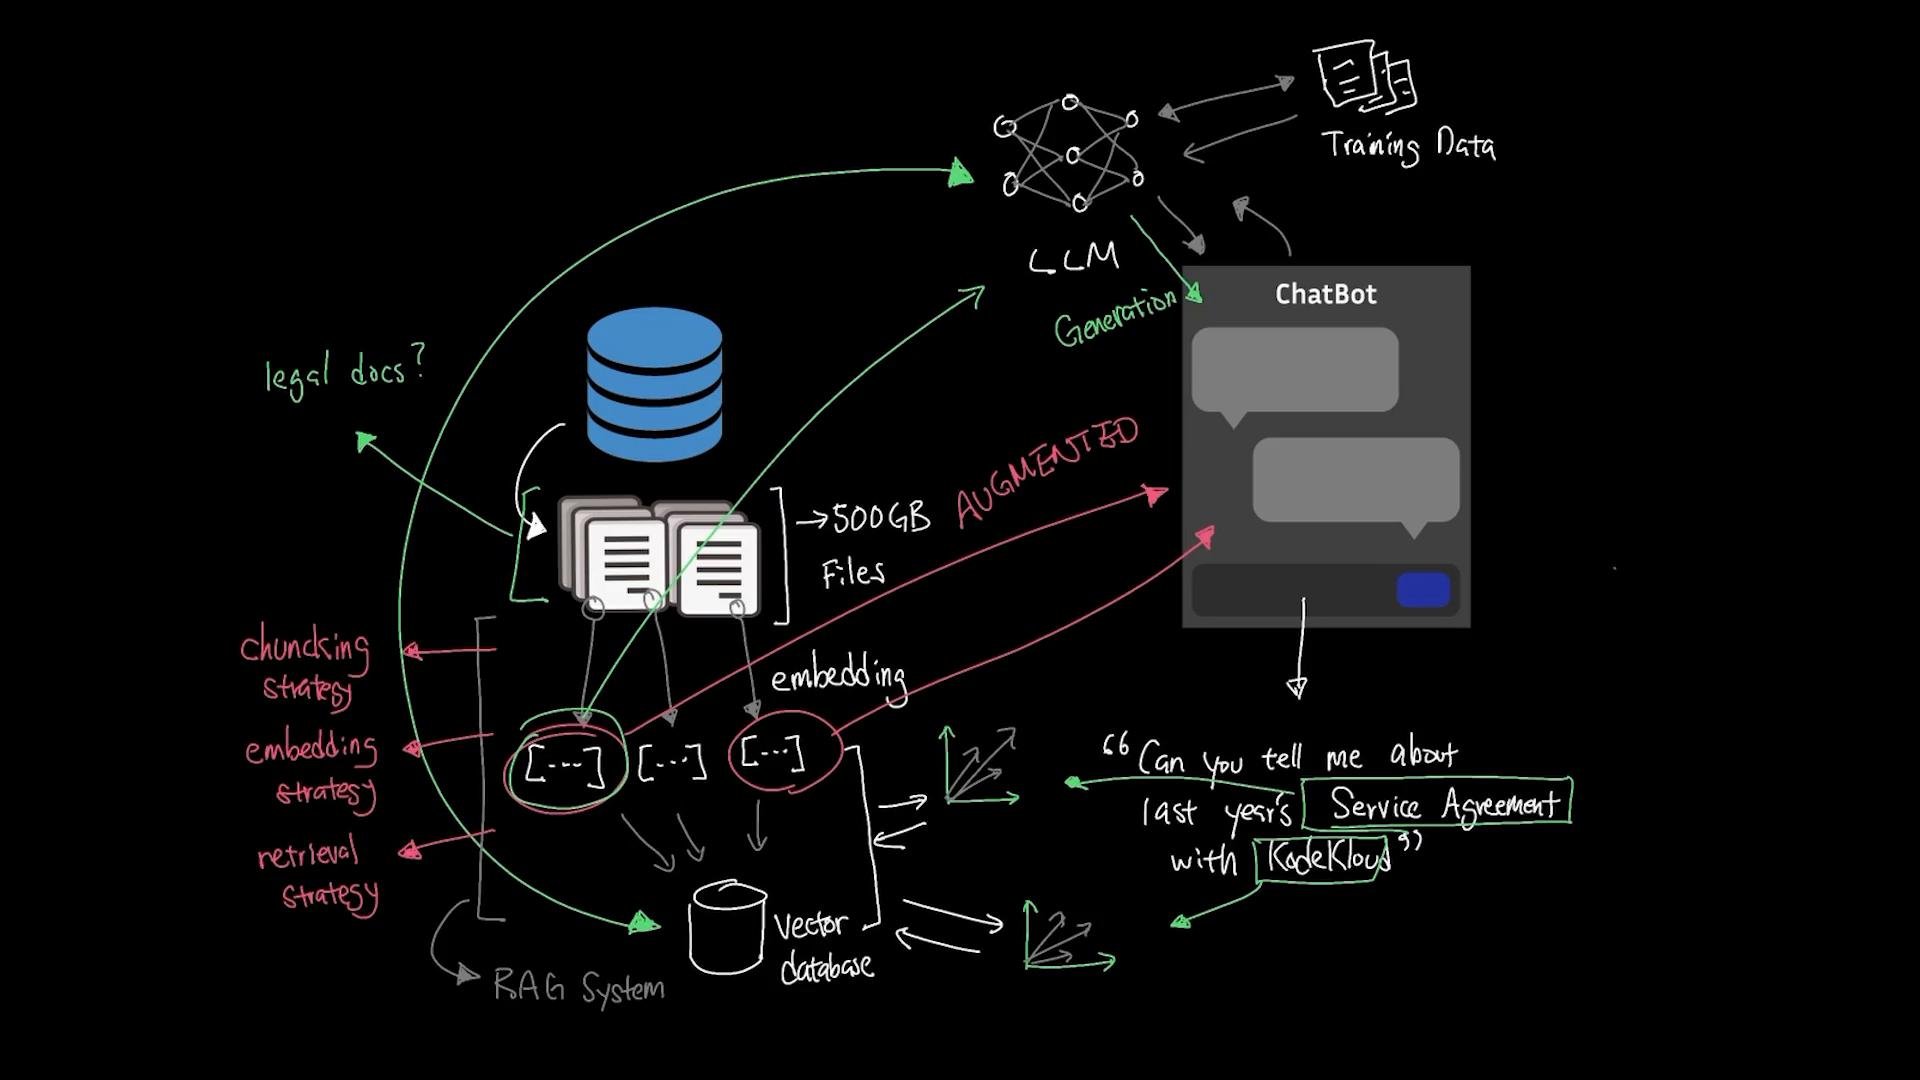
RAG splits the work into three clear stages:
* Retrieval\
Convert documents and the incoming query into embeddings. Use semantic search against stored vectors to find the most relevant chunks (meaning-based matches, not keyword-only).
* Augmentation\
Inject the retrieved chunks into the LLM prompt at runtime so answers are grounded in current, private data. No need to fine-tune the base LLM.
* Generation\
The LLM generates the final answer using the augmented prompt. Ideally the response cites source chunks to improve traceability.
This approach dramatically improves the assistant’s recall on private content, but it requires careful tuning: chunking strategy, embedding model choice, retrieval thresholds, and filtering all influence result quality.
Chunking strategies vary by document type:
* Legal/contract documents → larger chunks preserving structure.
* Conversational transcripts → finer-grained chunks with more overlap to preserve context.
For a quick architecture overview:
 ***
## Practical walk-through: from repo to demo UI
This section provides an end-to-end example demonstrating the core components: environment setup, vector DB initialization, chunking, embedding, ingestion, semantic search, and a minimal web UI (Flask) that ties retrieval → augmentation → generation together.
### Environment setup (example commands)
Create a project directory, virtual environment, install packages, and write a ready marker:
```bash theme={null}
cd /root && mkdir -p rag-project && cd rag-project
python3 -m venv venv && source venv/bin/activate
pip install uvicorn chromadb sentence-transformers openai flask
echo "READY" > /root/rag-setup-complete.txt
```
### Example repository layout (simulated TechCorp)
```text theme={null}
TechCorp Knowledge Repository
employee-handbook/
pet-policy.md (CEO's dog!)
remote-work-policy.md
benefits-overview.md
product-specs/
cloudsync-pro.md ($1M product)
datavault.md
meeting-notes/
q3-planning-meeting.md
product-launch-review.md
customer-faqs/
general-faqs.md
Total: 500GB simulated as focused docs
```
Inspect and count Markdown files:
```bash theme={null}
cd /root/techcorp-docs
ls -la
find . -name "*.md" | wc -l
find . -name "*.md" | wc -l > /root/doc-count.txt
```
### Initialize the vector database (ChromaDB)
Use a persistent ChromaDB collection to store embeddings, documents, and metadata:
```python theme={null}
# init_vectordb.py
import chromadb
from chromadb.config import Settings
print("Initializing AI Brain...")
client = chromadb.PersistentClient(
path="./chroma_db",
settings=Settings(anonymized_telemetry=False)
)
collection = client.get_or_create_collection(
name="techcorp_docs",
metadata={"hnsw:space": "cosine"}
)
print(f"Brain Created: {collection.name}")
print(f"Memories: {collection.count()}")
print("AI Brain Ready!")
```
Run:
```bash theme={null}
cd /root/rag-project && python init_vectordb.py
```
### Chunking documents (keeps context via overlap)
A robust chunker uses overlapping windows to preserve context between chunks:
```python theme={null}
# chunk_documents.py
import os
def chunk_text(text, size=500, overlap=100):
"""Split `text` into chunks of up to `size` characters with `overlap` to preserve context."""
if size <= 0:
raise ValueError("size must be > 0")
if overlap < 0 or overlap >= size:
raise ValueError("overlap must be >=0 and < size")
chunks = []
start = 0
text_len = len(text)
while start < text_len:
end = min(start + size, text_len)
chunks.append(text[start:end])
if end >= text_len:
break
start += size - overlap
return chunks
if __name__ == "__main__":
repo_dir = "/root/techcorp-docs"
total_chunks = 0
for root, _, files in os.walk(repo_dir):
for fname in files:
if fname.endswith(".md"):
path = os.path.join(root, fname)
with open(path, "r", encoding="utf-8") as f:
text = f.read()
chunks = chunk_text(text, size=500, overlap=100)
total_chunks += len(chunks)
with open("/root/chunk-count.txt", "w") as out:
out.write(str(total_chunks) + "\n")
print(f"Document chunking complete. Total chunks: {total_chunks}")
```
### Embedding basics (semantic vectors)
Use the SentenceTransformers family (example: all-MiniLM-L6-v2) to convert text into vectors and compute cosine similarity:
```python theme={null}
# test_embeddings.py
from sentence_transformers import SentenceTransformer
import numpy as np
print("Loading embedding model (all-MiniLM-L6-v2)...")
model = SentenceTransformer('all-MiniLM-L6-v2')
print("Model loaded!")
sentences = [
"Dogs are allowed in the office on Fridays",
"Pets can come to work on Furry Fridays",
"Remote work policy allows 3 days from home"
]
print("Converting text to vectors...")
embeddings = model.encode(sentences)
def cosine_sim(a, b):
return float(np.dot(a, b) / (np.linalg.norm(a) * np.linalg.norm(b)))
sim_1_2 = cosine_sim(embeddings[0], embeddings[1])
sim_1_3 = cosine_sim(embeddings[0], embeddings[2])
print("Semantic Similarity Analysis:")
print(f"'Dogs allowed' ↔ 'Pets permitted' -> {sim_1_2:.3f} (Related)")
print(f"'Dogs allowed' ↔ 'Remote work' -> {sim_1_3:.3f} (Not related)")
with open('/root/embedding-test.txt', 'w') as f:
f.write(f"SIM_PET:{sim_1_2:.3f},SIM_REMOTE:{sim_1_3:.3f}\n")
```
Takeaway: both documents and queries become vectors; similarity measures semantic relatedness, not just token overlap.
### Ingesting documents into ChromaDB
Read files, chunk, embed each chunk, and store IDs, documents, embeddings, and metadata:
```python theme={null}
# ingest_documents.py
import os
import uuid
from sentence_transformers import SentenceTransformer
import chromadb
from chromadb.config import Settings
from chunk_documents import chunk_text
# Connect to the same persistent client/collection created earlier
client = chromadb.PersistentClient(
path="./chroma_db",
settings=Settings(anonymized_telemetry=False)
)
collection = client.get_or_create_collection(name="techcorp_docs")
model = SentenceTransformer('all-MiniLM-L6-v2')
repo_dir = "/root/techcorp-docs"
all_ids, all_embeddings, all_documents, all_metadatas = [], [], [], []
for root, _, files in os.walk(repo_dir):
for fname in files:
if not fname.endswith(".md"):
continue
path = os.path.join(root, fname)
with open(path, "r", encoding="utf-8") as f:
text = f.read()
chunks = chunk_text(text, size=500, overlap=100)
if not chunks:
continue
embeddings = model.encode(chunks)
for i, (chunk, emb) in enumerate(zip(chunks, embeddings)):
uid = str(uuid.uuid4())
all_ids.append(uid)
all_embeddings.append(emb.tolist())
all_documents.append(chunk)
all_metadatas.append({
"file": fname,
"path": path,
"chunk_index": i,
"category": os.path.basename(root)
})
# Bulk add to collection
collection.add(
ids=all_ids,
documents=all_documents,
metadatas=all_metadatas,
embeddings=all_embeddings
)
print("Ingestion complete. Chunks added:", len(all_ids))
```
A full ingestion run typically logs progress and prints totals (documents processed, chunks ingested).
### Semantic search example
Encode the query and retrieve the top N most similar chunks:
```python theme={null}
# search_test.py
from sentence_transformers import SentenceTransformer
import chromadb
from chromadb.config import Settings
model = SentenceTransformer('all-MiniLM-L6-v2')
client = chromadb.PersistentClient(
path="./chroma_db",
settings=Settings(anonymized_telemetry=False)
)
collection = client.get_collection("techcorp_docs")
queries = [
"What is the pet policy at TechCorp?",
"Tell me about CloudSync Pro features",
"How many days of remote work are allowed?"
]
with open('/root/search-results.txt', 'w') as results_file:
for query in queries:
print(f"Query: '{query}'")
results_file.write(f"QUERY:{query}\n")
query_embedding = model.encode(query).tolist()
results = collection.query(
query_embeddings=[query_embedding],
n_results=3
)
print("Top Results (by semantic similarity):")
for i, (doc, meta) in enumerate(zip(results['documents'][0], results['metadatas'][0]), start=1):
print(f"{i}. [{meta['category']}] {meta['file']}")
print(f" Preview: '{doc[:100].replace('\\n',' ')}...'")
results_file.write(f"RESULT:{meta['category']}/{meta['file']}\n")
print("="*50 + "\n")
```
A search for “bring my dog” should surface the pet policy chunk even if wording differs—this is the power of semantic retrieval.
### Minimal UI: Flask app for retrieval → augmentation → generation
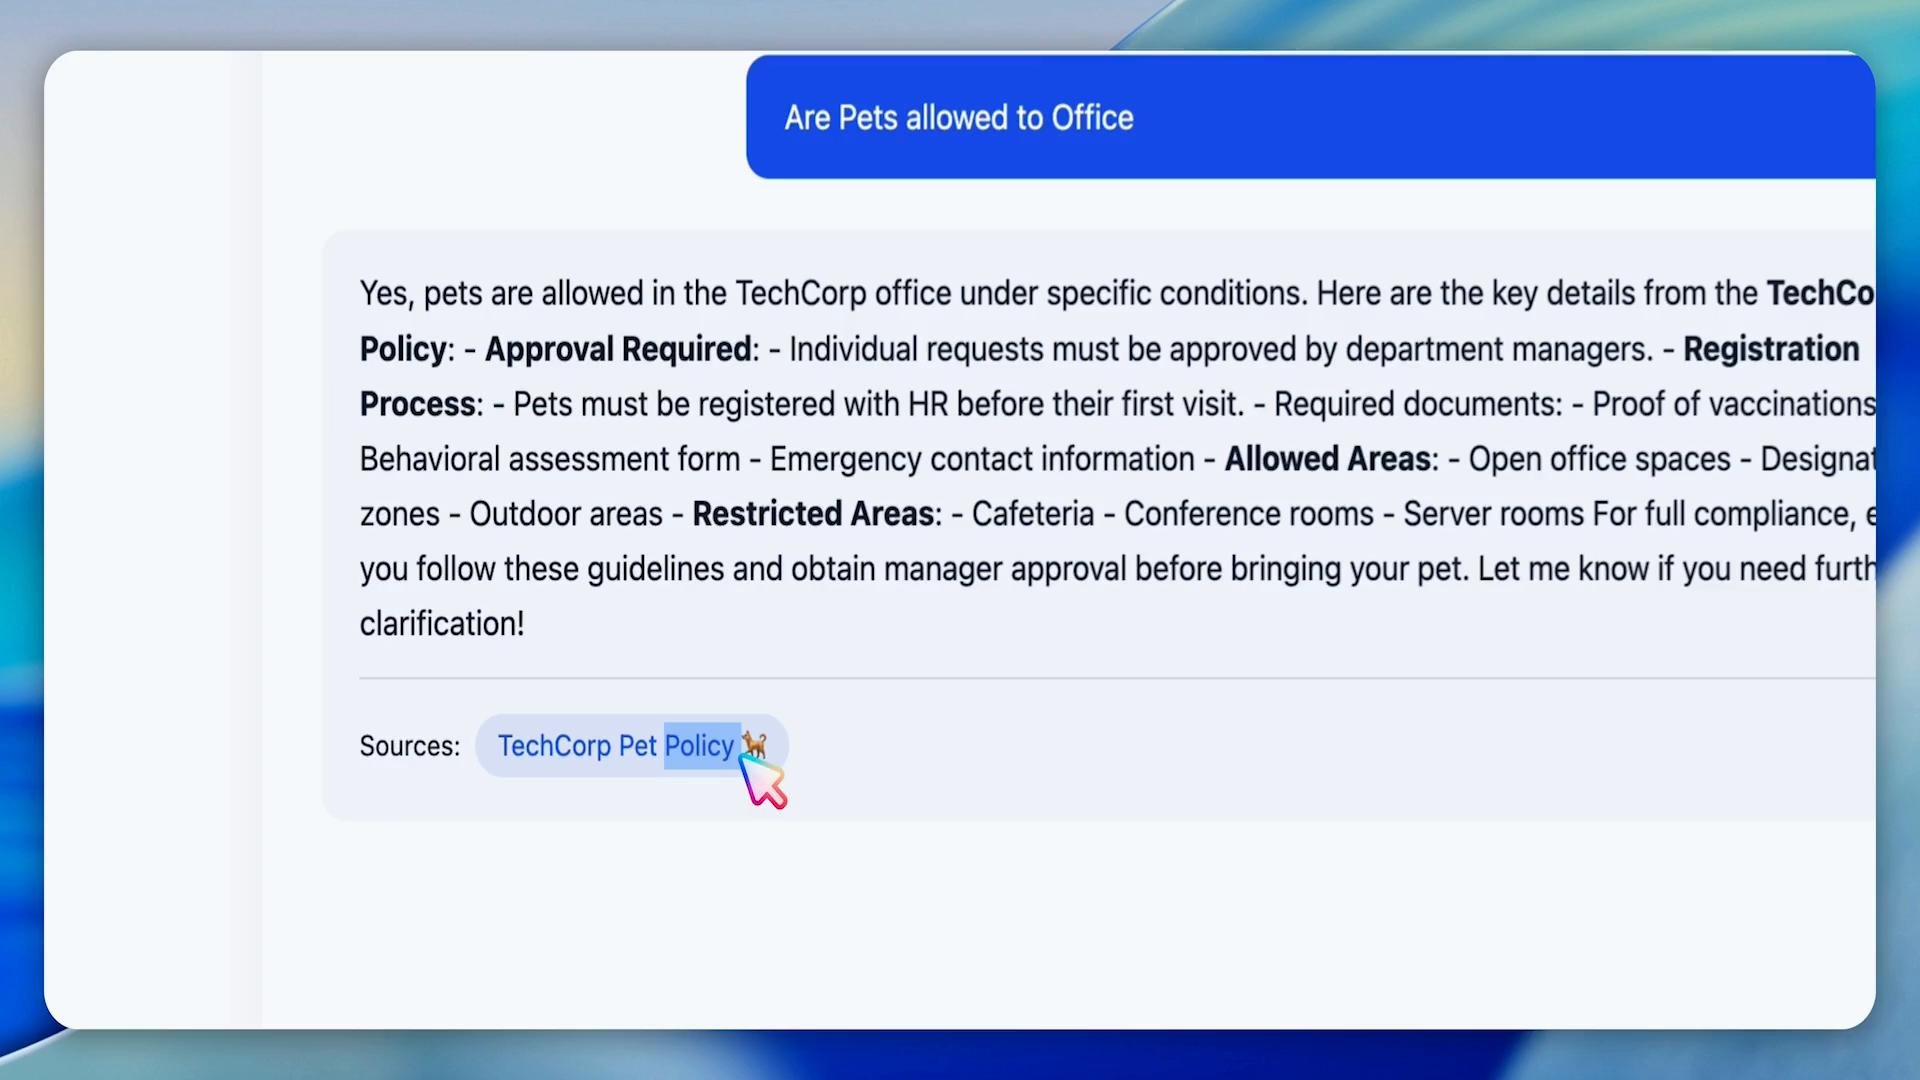
A lightweight Flask app receives a question, runs semantic search, assembles a prompt with retrieved chunks, and calls an LLM (e.g., OpenAI) to generate a grounded answer. Include provenance (metadata + similarity scores) in responses to reduce hallucination.
High-level notes:
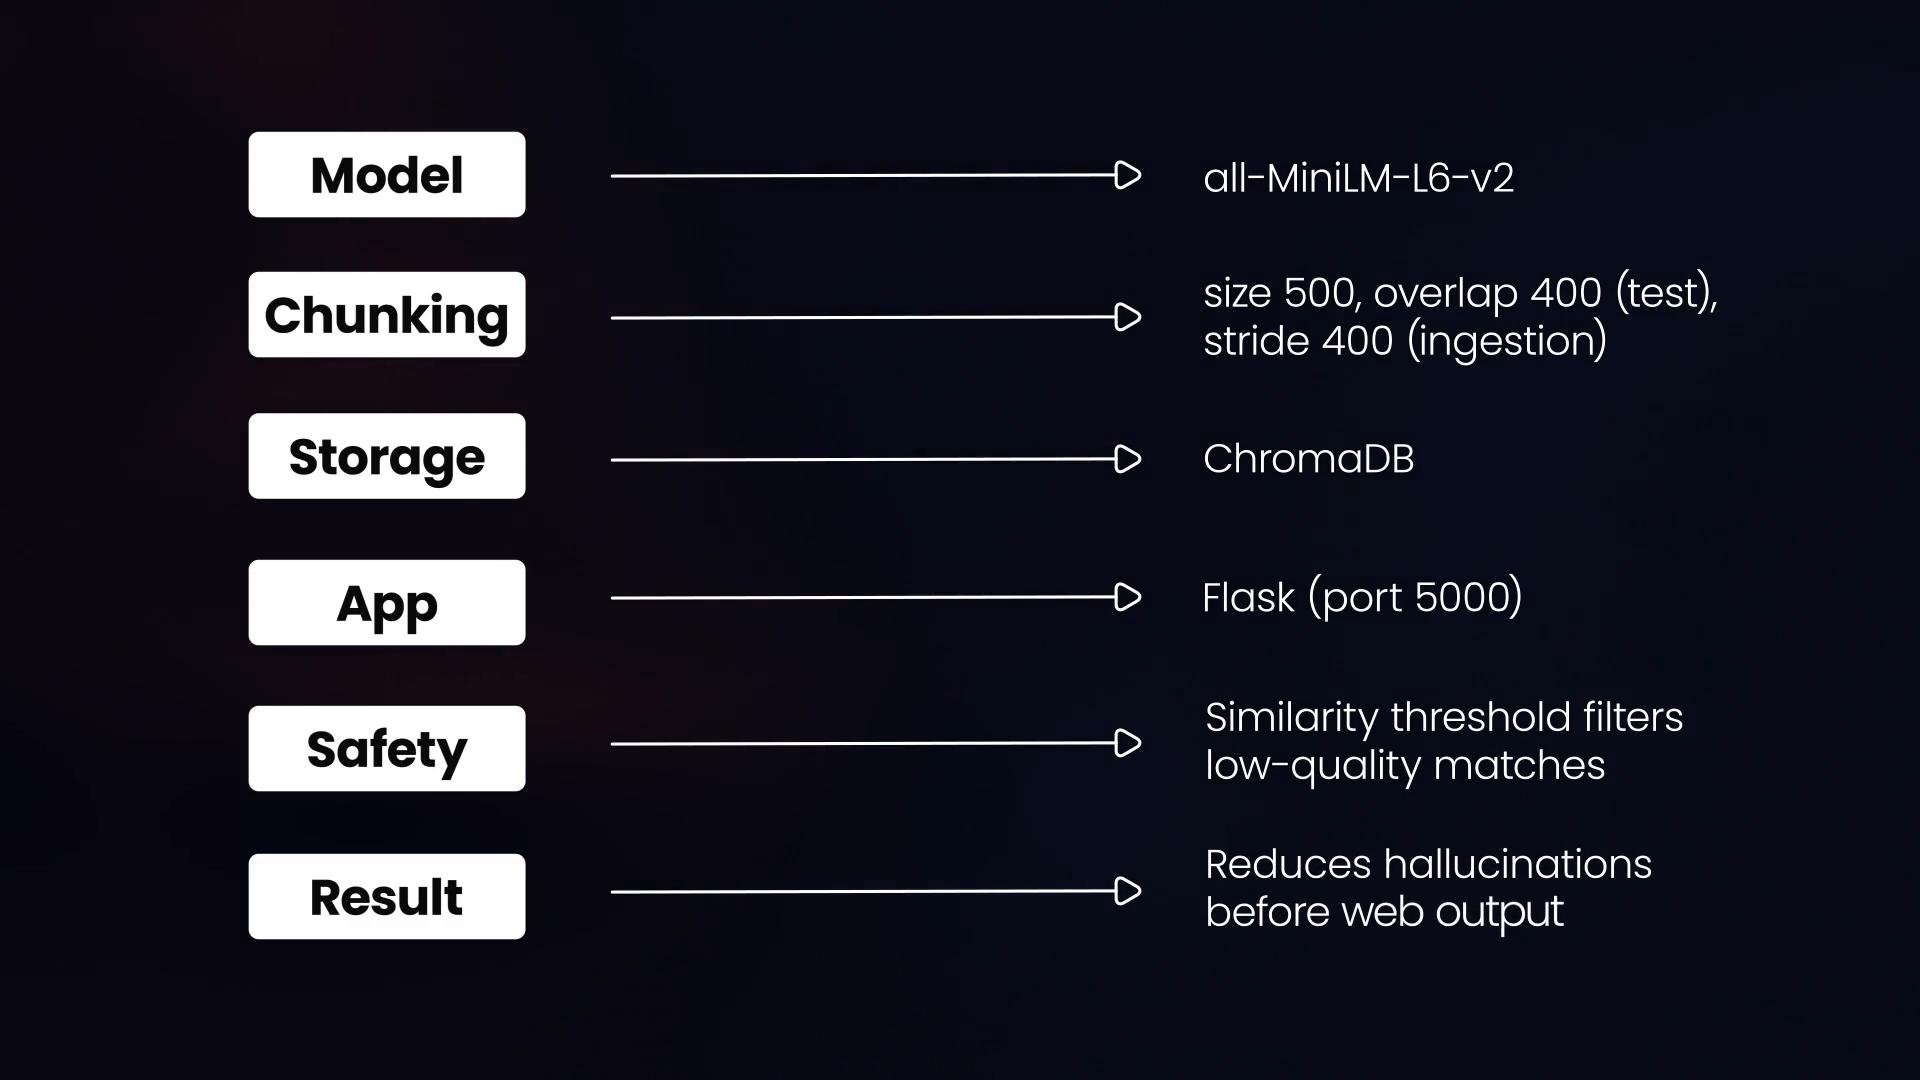
* Embedding model: `all-MiniLM-L6-v2` (compact, performant).
* Chunking: size 500 chars; overlap 100–400 depending on content density.
* Storage: ChromaDB persistent collection `techcorp_docs`.
* Web: Flask app for quick prototyping (port 5000).
* Safety: apply similarity thresholds, metadata filters, and return provenance links to mitigate hallucinations.
 ***
## Operational advice and tuning knobs
Key tuning variables to monitor and iterate on:
* Chunk size and overlap (balance context vs. prompt cost).
* Embedding model (trade-offs: cost, latency, semantic quality).
* Retrieval n\_results and similarity threshold to reduce noise.
* Provenance reporting in responses to help debugging and reduce hallucinations.
Best practices:
* Legal/technical docs → larger chunks, higher overlap to keep structure.
* Conversational logs → smaller chunks with more overlap to preserve turn-level context.
* Run embedding and retrieval tests (e.g., the test\_embeddings script) to validate semantic distances for your corpus.
Table: quick component summary
| Component | Purpose | Example |
| - | -: | - |
| Embedding model | Convert text → vectors | `all-MiniLM-L6-v2` |
| Vector DB | Persist vectors + metadata | ChromaDB (persistent collection) |
| Chunker | Split files while preserving context | `size=500`, `overlap=100` (tune per-corpus) |
| Retriever | Find top-k similar chunks | `n_results=3` (increase for recall) |
| App | Orchestrate RAG and serve UI | Flask on port 5000 |
| Safety | Reduce hallucinations | similarity thresholds, provenance |
Be careful with sensitive data. Embeddings and vector indexes may leak information if not properly secured. Ensure access controls, encryption at rest, and a clear data policy before indexing PII.
 ***
## Final checklist before production
* Tune chunk size and overlap on a representative sample of your corpus.
* Choose an embedding model that balances cost, latency, and semantic fidelity.
* Implement retrieval filtering (similarity thresholds, metadata) to reduce noise.
* Log provenance and similarity scores to help debug and explain answers.
* Secure your vector DB and restrict access to sensitive data.
That’s it — with a vector DB, embeddings, a robust chunker, and a small web app you can move from zero to a working RAG system that returns grounded, explainable answers over large private corpora.
Further reading and references:
* [Retrieval-augmented generation (Wikipedia)](https://en.wikipedia.org/wiki/Retrieval-augmented_generation)
* [ChromaDB](https://www.trychroma.com/)
* [SentenceTransformers (SBERT)](https://www.sbert.net/)
* [Flask documentation](https://flask.palletsprojects.com/)
* [OpenAI platform](https://platform.openai.com/)
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.