> ## Documentation Index
> Fetch the complete documentation index at: https://notes.kodekloud.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Replica Promotion
> How to safely promote a database replica to primary by checking replication lag, fencing the old primary, performing promotion, and repointing applications to avoid split brain.
Let's walk through a common database interview scenario: it's 2:00 AM and your primary database server has crashed. Fortunately you planned for this: a replica (a second database server) keeps a copy of everything.
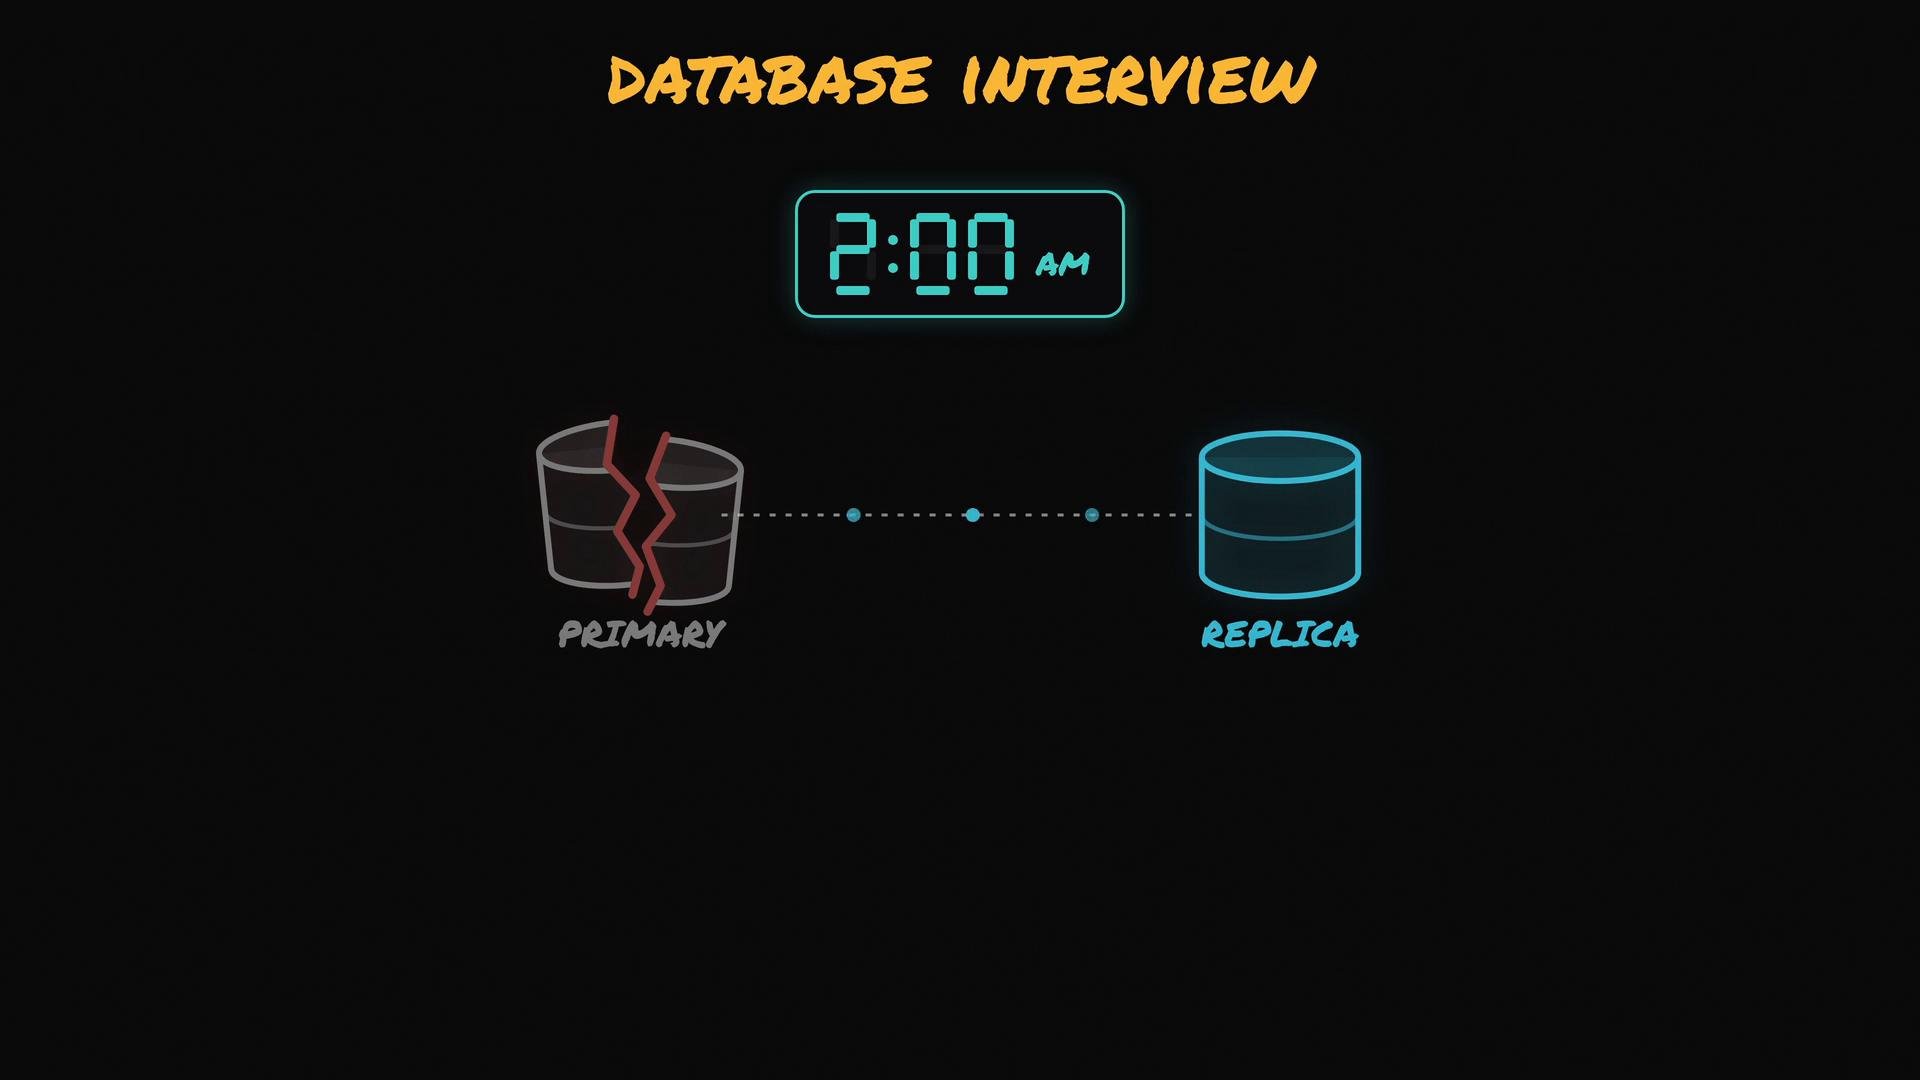 Blindly promoting the replica to primary is rarely the best move. The primary dying does not mean your users lost read access — reads typically still work from the replica. What stops is writes, because writes are generally accepted only by the primary. That gives you a small window to perform a clean, safe failover instead of risking data divergence.
Follow these stages to promote a replica safely.
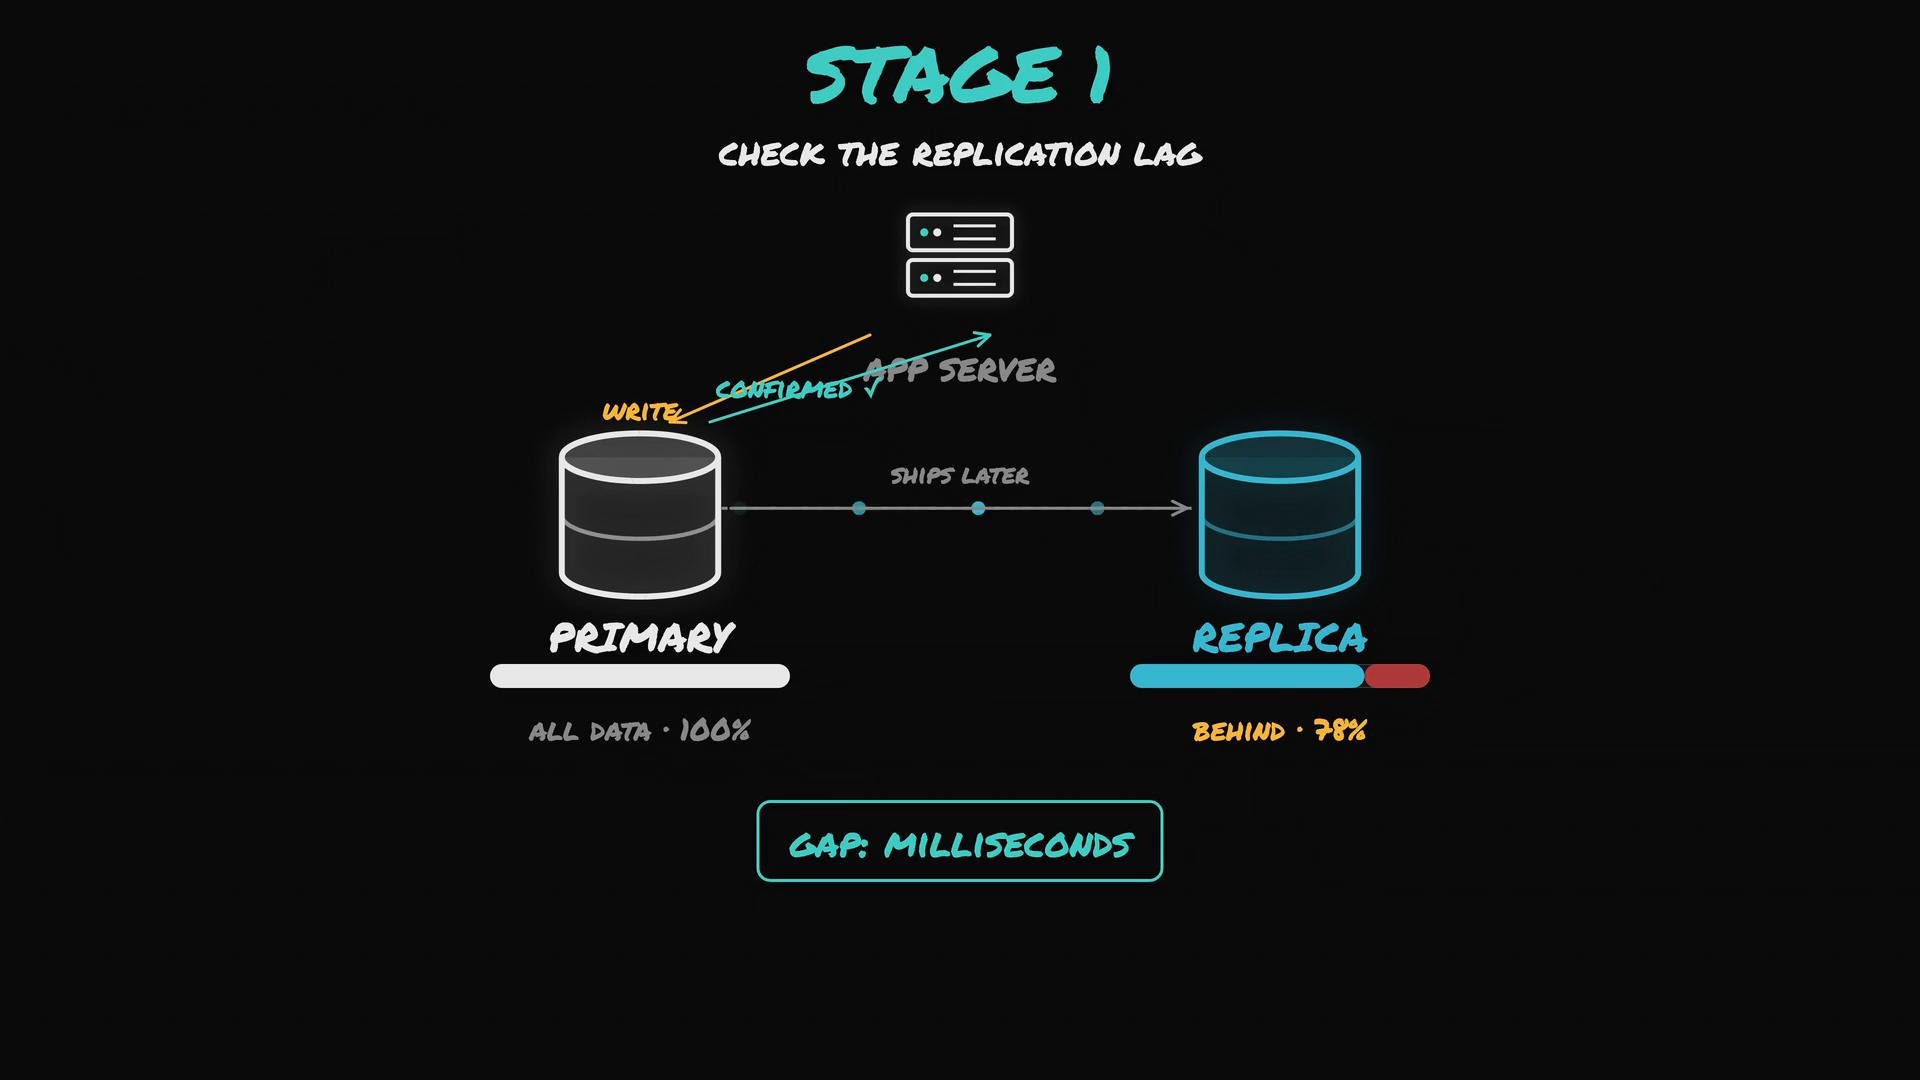
Stage 1 — Check the replication lag
Replicas are usually slightly behind the primary because replication is often asynchronous: the primary confirms writes to clients first, then ships them to replicas. Under normal conditions the gap is milliseconds; under heavy load it can be seconds or more.
Ask the replica how far behind it was when the primary died. Both PostgreSQL and MySQL expose this information.
* PostgreSQL (on the replica)
```sql theme={null}
-- Returns the time difference between now and the last replayed transaction timestamp
SELECT now() - pg_last_xact_replay_timestamp() AS replication_lag;
```
Note: this can return `NULL` if the replica has not replayed any WAL yet.
* MySQL (on the replica)
```sql theme={null}
-- Shows replication state, including Seconds_Behind_Master
SHOW SLAVE STATUS\G
-- (In newer MySQL/MariaDB versions this may be labeled as SHOW REPLICA STATUS\G)
```
Note: `Seconds_Behind_Master` (or equivalent) can be `NULL` or misleading in some situations (for example, when replication threads have stopped or during long-running transactions). Check IO/SQL thread states, relay log positions, and last executed positions to get a reliable picture.
Measure replication lag carefully before promoting. For critical data (payments, invoices), estimate which time window of writes might be missing and prioritize recovery of those writes from the failed primary's disk if possible.
If the replica was fully up to date, you lost nothing. If it was behind, estimate the missing window and plan to recover critical writes from the old primary when possible.
 Stage 2 — Cut off the old primary (fence it)
A dead primary can come back unexpectedly. If the old primary wakes and starts accepting writes while the replica has been promoted, you can end up with split-brain: two servers both believing they are primary and diverging data. That is worse than temporary downtime.
Before promotion, ensure the old primary cannot accept writes again. Options include:
* Power it off.
* Isolate it from the network (firewall rules, route changes).
* Use a fencing mechanism supported by your environment (for example, STONITH in clustered systems).
Do not promote a replica until you have a reliable way to prevent the old primary from accepting writes again. Split-brain leads to irreconcilable data divergence.
Stage 3 — Promote the replica
Promotion is usually straightforward; exact commands depend on your database and tooling. If you have an orchestrator (e.g., Orchestrator, MHA) it can automate safe promotion and topology updates.
* PostgreSQL (common methods)
```bash theme={null}
# Using pg_ctl to request promotion of the standby
pg_ctl promote -D /var/lib/postgresql/data
```
or, on newer PostgreSQL versions:
```sql theme={null}
-- Trigger a promotion from SQL (run on the standby)
SELECT pg_promote();
```
* MySQL
MySQL replicas can be promoted by stopping replication and making the server writable, or by using orchestrators that handle configuration changes safely.
```sql theme={null}
STOP SLAVE; -- (or STOP REPLICA;)
RESET SLAVE ALL; -- optional: removes replication config (use with caution)
-- then ensure server is writable:
SET GLOBAL read_only = OFF;
SET GLOBAL super_read_only = OFF;
```
Be careful with `RESET SLAVE` / `RESET REPLICA` because they remove stored replication configuration. Prefer orchestrator tools to avoid mistakes when possible.
Stage 4 — Repoint the application
Your application is likely still trying to connect to the old primary address. Many teams put a single endpoint in front of databases (virtual IP, load balancer, or DNS) so you only need to update that endpoint to redirect traffic to the new primary.
Actions to take:
* Update connection strings, failover DNS, or move the virtual IP to the new primary.
* Verify application connectivity with health checks and smoke tests.
* Monitor error rates and replication status for other replicas.
Quick reference: common checks and promotion commands
| Database | Check replication lag | Promote replica |
| -: | - | - |
| PostgreSQL | `SELECT now() - pg_last_xact_replay_timestamp() AS replication_lag;` | `pg_ctl promote -D /var/lib/postgresql/data` or `SELECT pg_promote();` |
| MySQL / MariaDB | `SHOW SLAVE STATUS\G` (or `SHOW REPLICA STATUS\G`) | `STOP SLAVE;` / `RESET SLAVE ALL;` then `SET GLOBAL read_only = OFF;` |
Links and further reading
* [PostgreSQL documentation](https://www.postgresql.org/docs/)
* [MySQL documentation](https://dev.mysql.com/doc/)
* [Orchestrator for MySQL](https://github.com/openark/orchestrator) — automated topology management
* [STONITH (fencing)](https://en.wikipedia.org/wiki/STONITH)
Summary — safe failover checklist
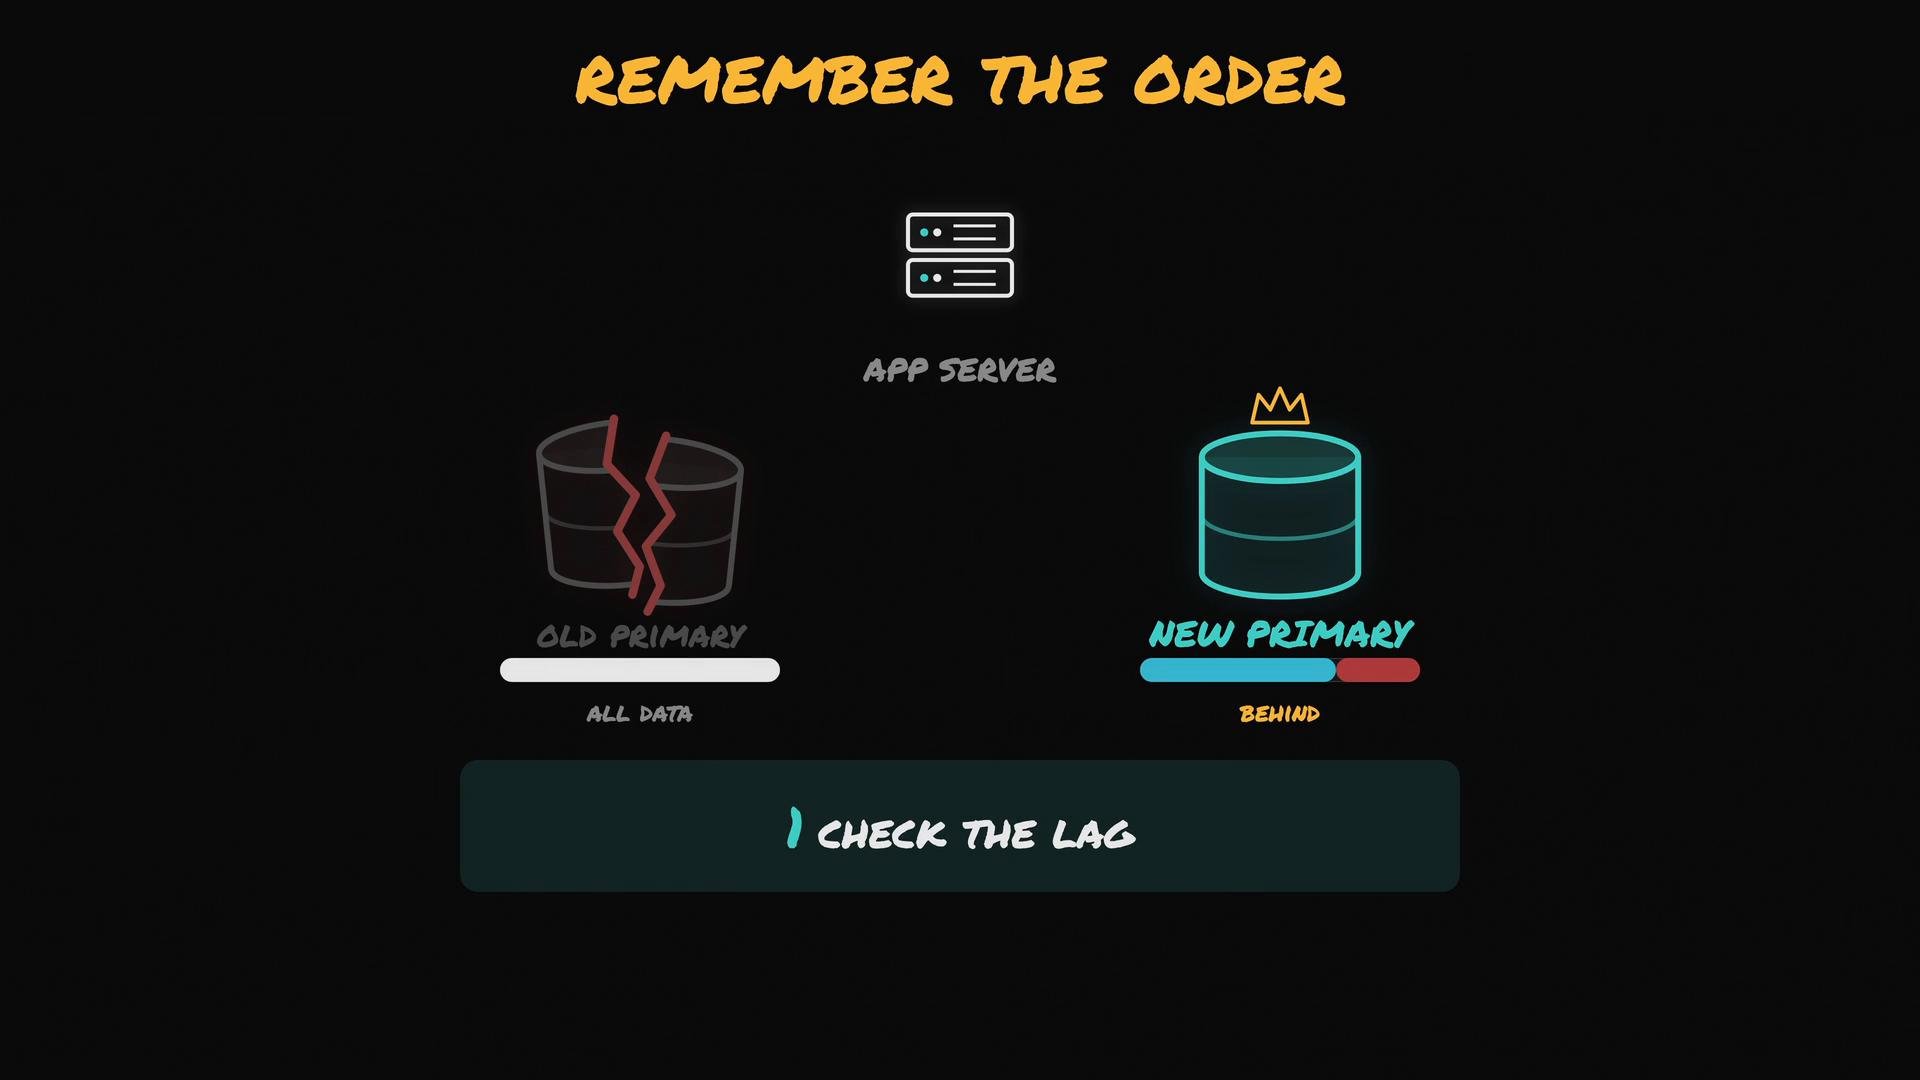
1. Check replication lag to understand any potential data loss.
2. Fence (isolate) the old primary to prevent split-brain.
3. Promote the chosen replica to primary using the appropriate commands or orchestrator.
4. Repoint the application (virtual IP, DNS, or client configs) and verify functionality.
 This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.