

- Teams often default to a popular large language model because it’s well-known rather than because it’s the best fit for the task.
- Without a centralized catalog, each model requires separate integration and evaluation — slow and error-prone.
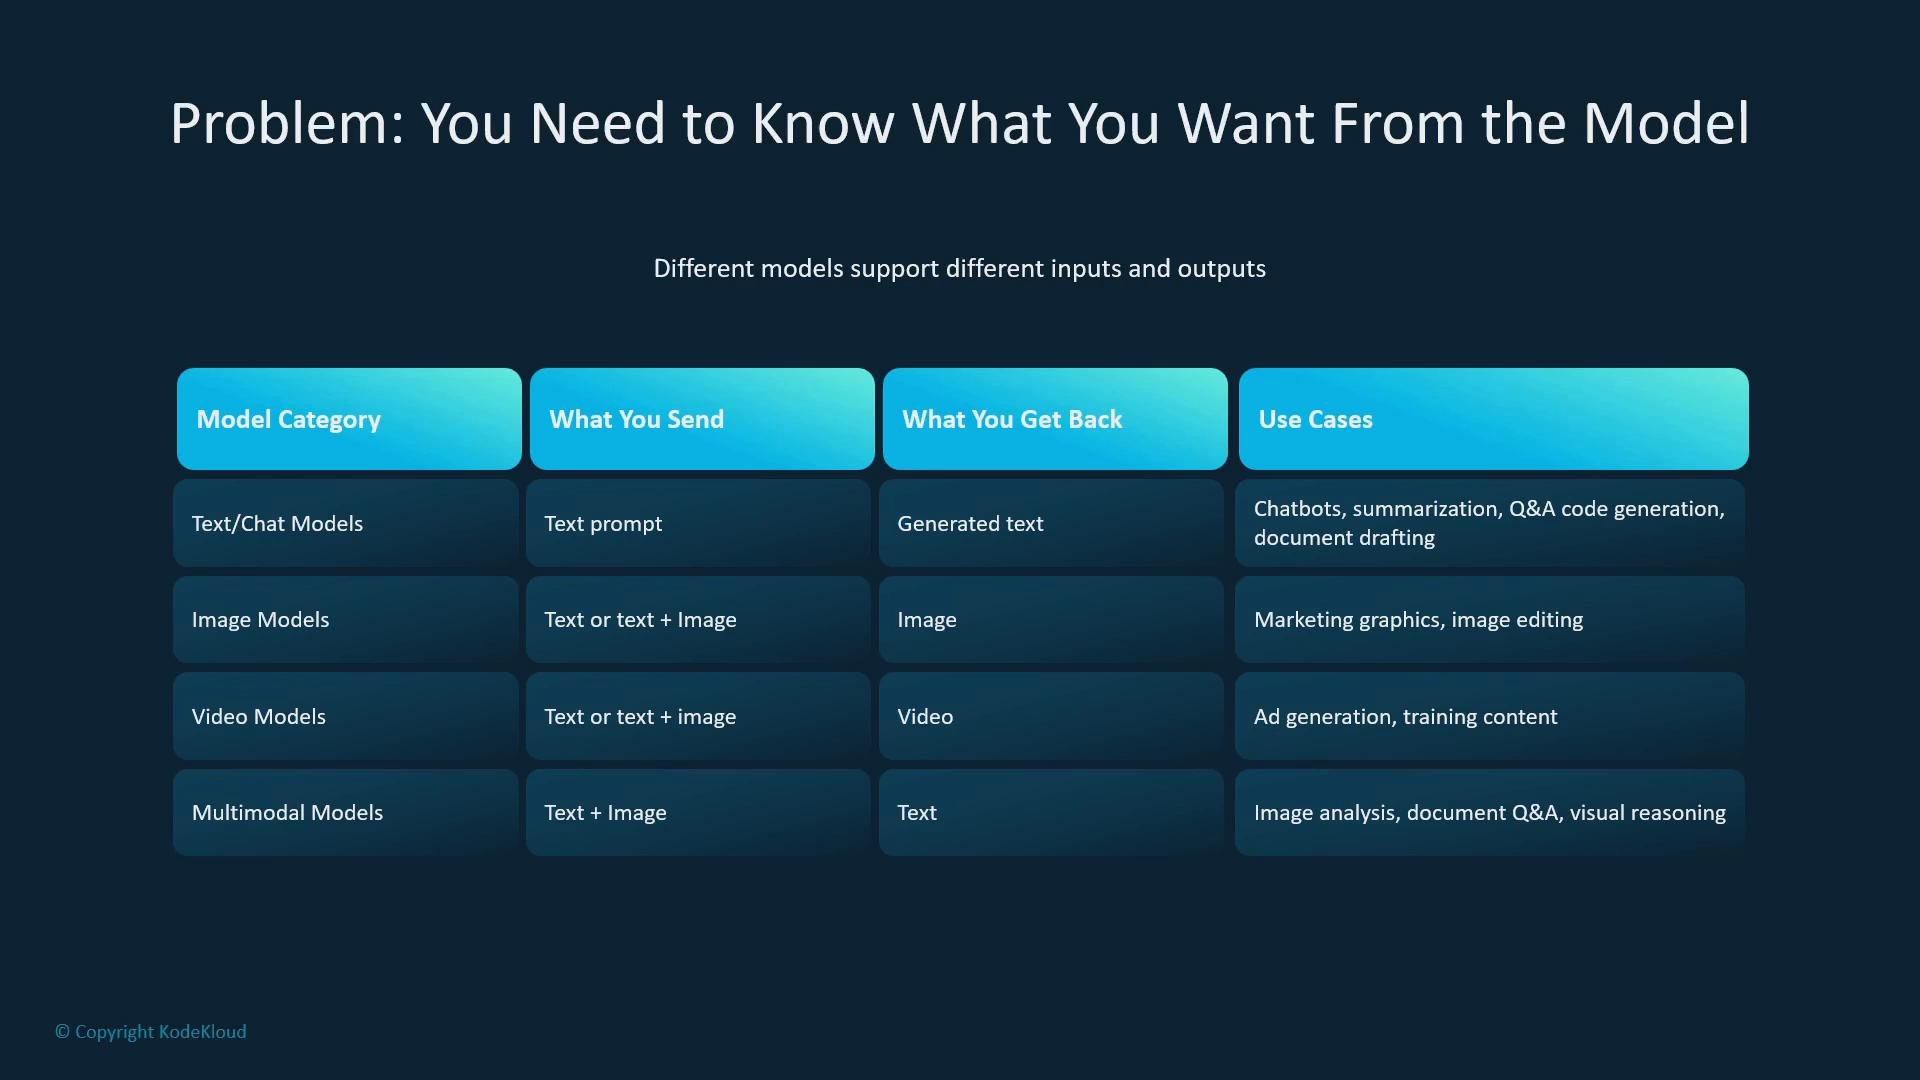
Design with intent: different components of the same application can use different models. For example, route routine classification to a smaller model and reserve a larger model for complex reasoning tasks.
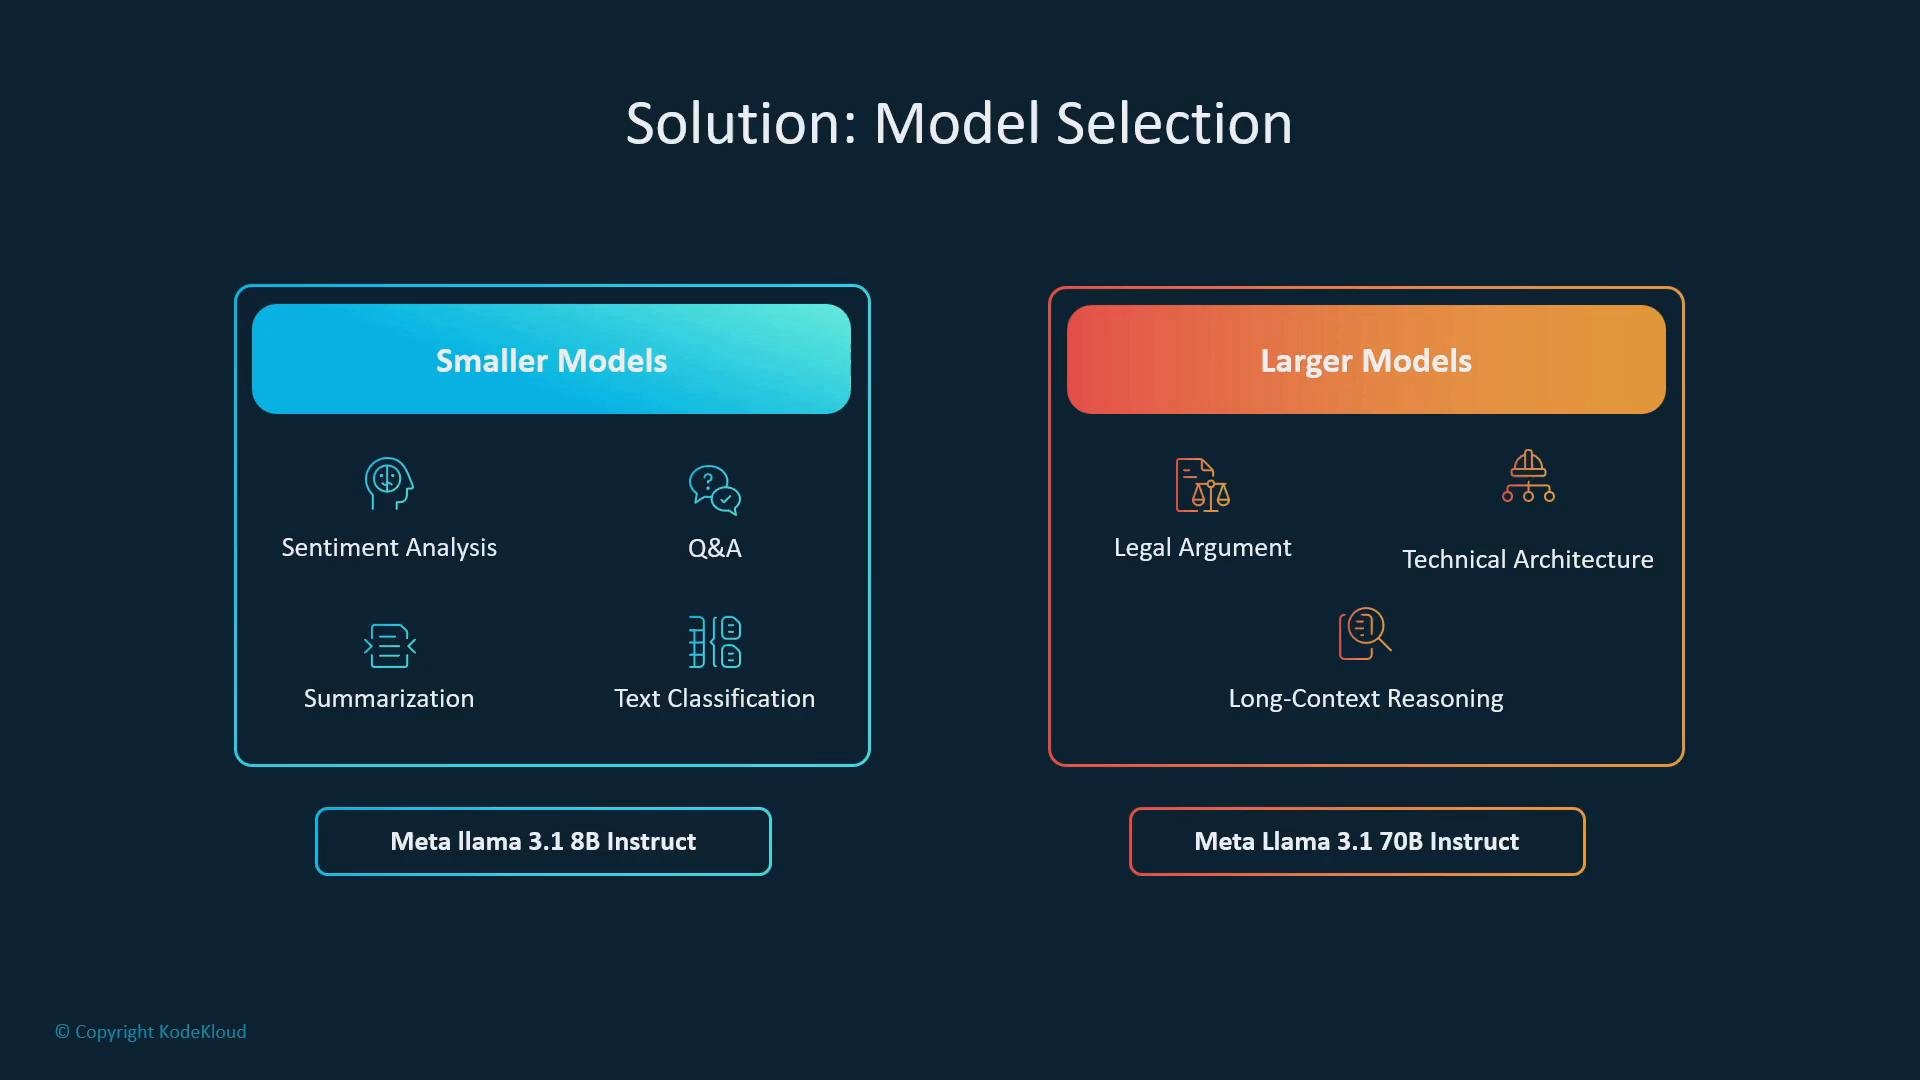
- Regions and availability: Choose an AWS Region near your users to reduce latency, but verify Bedrock and the specific model are available in that Region. If your preferred image or multimodal model (for example, Stable Diffusion) is not available locally, decide whether to accept extra cross-region latency or pick an available alternative.
- Provider variety: Bedrock hosts models from multiple vendors (Meta, Anthropic, NVIDIA, Amazon, Stability AI, and others). Bedrock abstracts away infrastructure and gives you consistent access to these pre-trained foundation models.
- Billing and throughput: Serverless (on-demand) pricing commonly bills by processed tokens for text/chat models and may bill per image or per-generation unit for image/multimodal models. Larger models usually cost more per token or per request. If you need predictable performance and throughput, consider Bedrock’s provisioned throughput options.
- Overview and recommended use cases
- Supported input/output modalities
- Supported languages
- Deployment options (serverless, provisioned throughput, Marketplace)
- Max tokens / context window
- Programmatic model ID — the exact identifier you supply in API requests
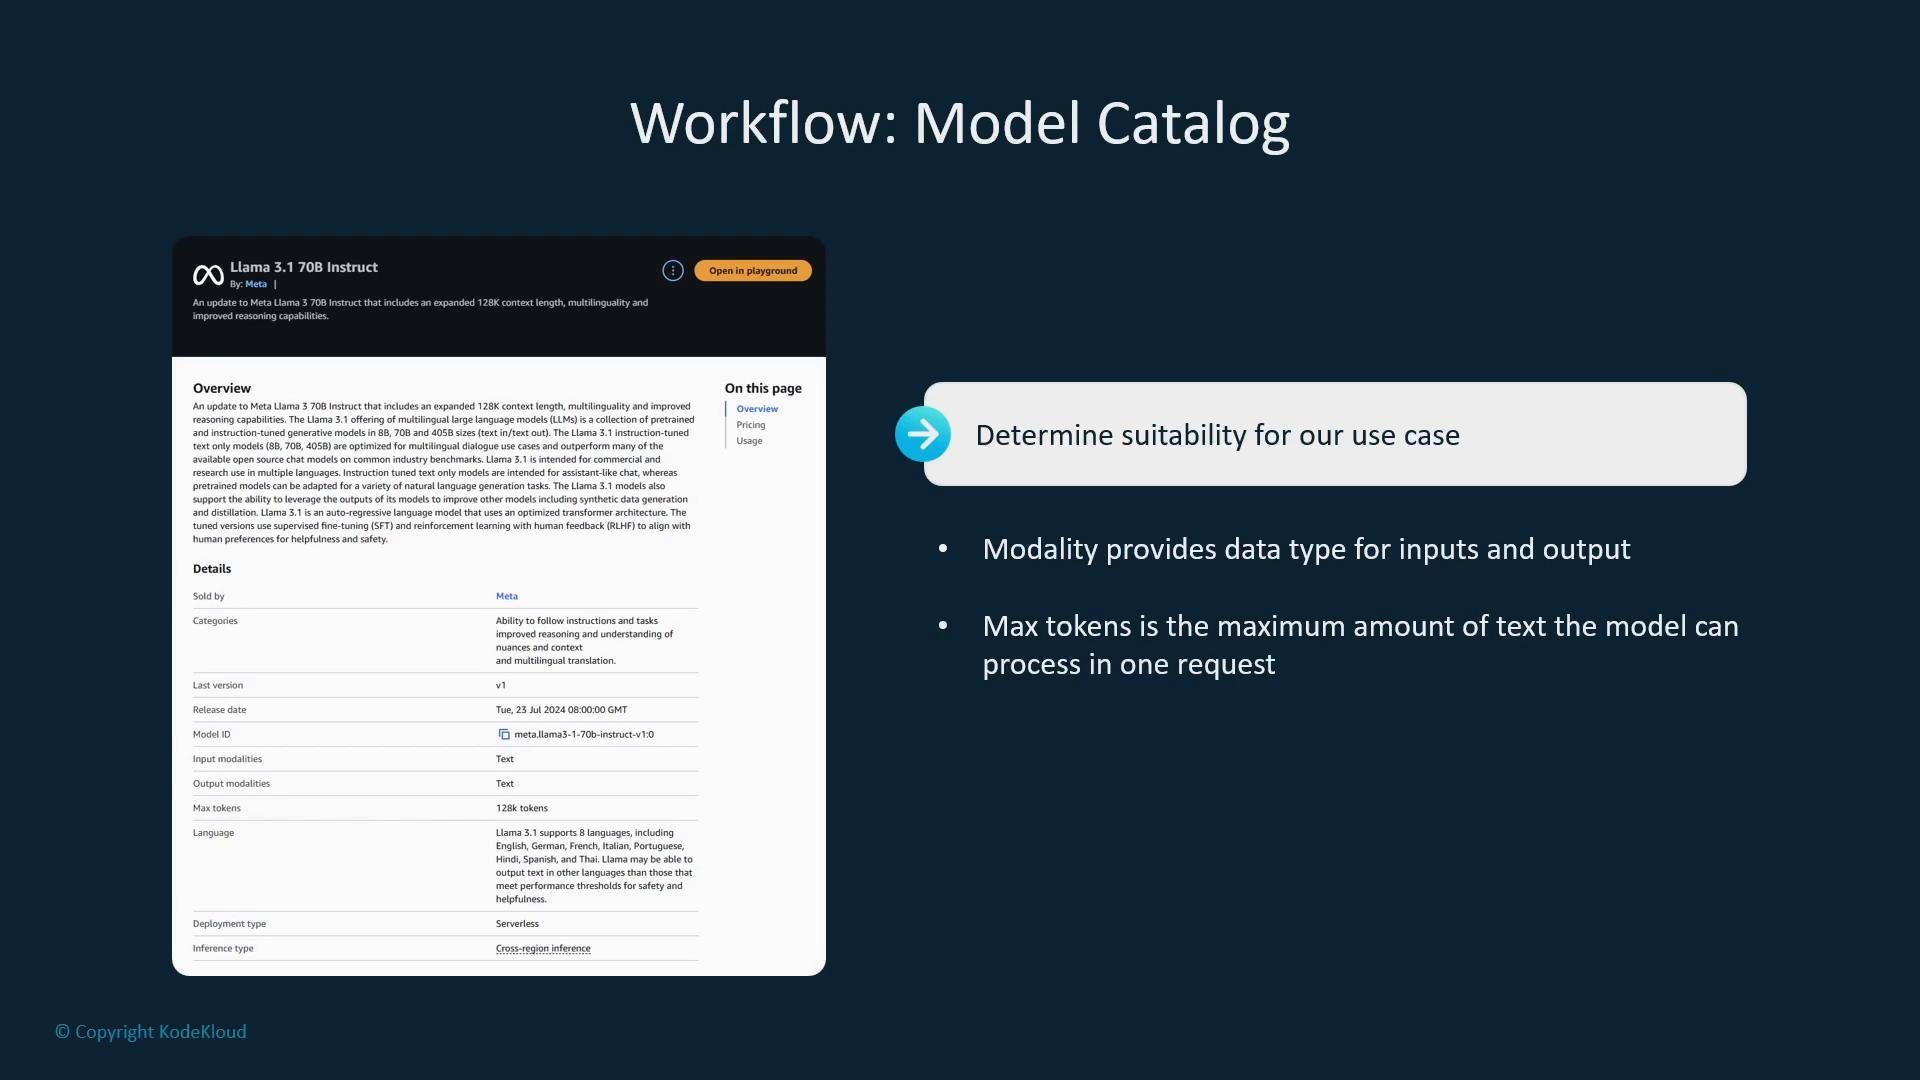
Tokens measure the size of data you send to and receive from a model. A model’s context window (max tokens) constrains the combined size of prompt input plus expected output. For long-document summarization or long-context reasoning, confirm the model’s max tokens and ensure input + output fit within that limit.
- Open the Bedrock console in the AWS Management Console and inspect models in your preferred Region.
- Evaluate models by modality, max tokens, and pricing.
- Prototype a routing pattern: small model for bulk tasks, large model for complex analysis.
- If you require predictable latency or high throughput, explore Bedrock’s provisioned throughput options.
- Amazon Bedrock documentation: https://docs.aws.amazon.com/bedrock
- Model provider pages (e.g., Meta Llama 3, Anthropic, Stability AI)
- Best practices for prompt design and token budgeting