> ## Documentation Index
> Fetch the complete documentation index at: https://notes.kodekloud.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Training vs Inference
> Explains the differences between training and inference in machine learning, outlining goals, processes, computation costs, state changes, and when models are updated or served.
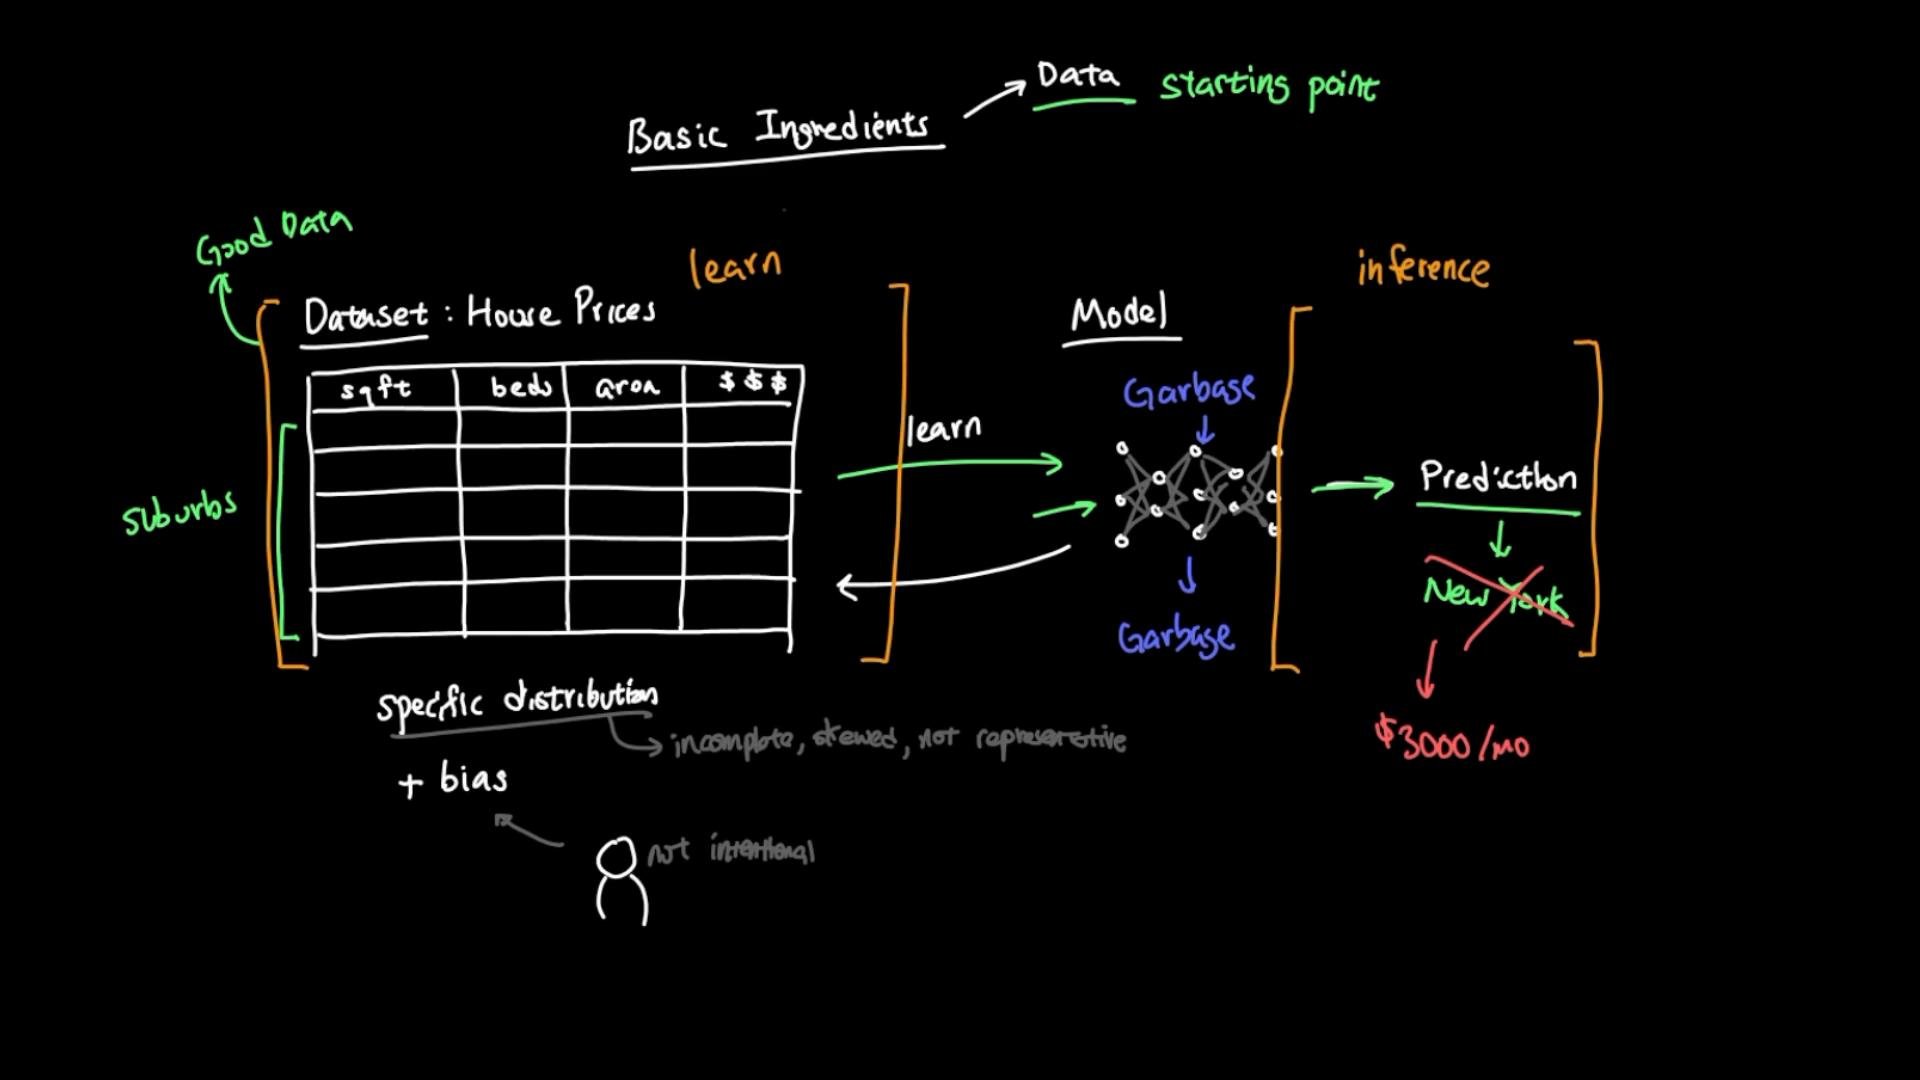
Having the data is only the starting point. The model must first learn from that data (training) and later apply what it learned to new examples (inference). These are two distinct phases with different goals, compute patterns, and operational considerations.
 ## Quick overview
* Training = learning phase: the model sees labeled examples and updates internal values so future predictions improve.
* Inference = usage phase: the trained model makes predictions on new inputs without updating the learned parameters.
## Training — the learning phase
Using the housing-prices example, training is when we show the model historical homes for which the final sale price is known. For each training example the model:
1. Examines features (square footage, number of bedrooms, location, etc.).
2. Produces a prediction.
3. Compares that prediction to the known sale price (the label).
4. Adjusts internal parameters to reduce the error on future examples.
Example: the model predicts $700,000 for a house that sold for $800,000. During training the model computes the difference (the loss) and uses an optimizer (for example, gradient descent) to change parameter values so similar future predictions are closer to the true value.
Two important concepts:
* Loss function — a scalar that quantifies how wrong the model’s prediction was (examples: mean squared error for regression, cross-entropy for classification).
* Optimization algorithm — the method used to update parameters to reduce loss (examples: gradient descent, Adam).
For practical guides and implementations see:
* [Gradient Descent (Wikipedia)](https://en.wikipedia.org/wiki/Gradient_descent)
* [TensorFlow Training Guide](https://www.tensorflow.org/guide/keras/train_and_evaluate)
* [PyTorch Optimization](https://pytorch.org/docs/stable/optim.html)
## Inference — the usage phase
After training finishes, inference is when you give the model a new input with an unknown true label and ask it to predict. Inference uses the parameters learned during training; it does not compare the prediction to a label nor update those parameters (unless you explicitly run a retraining or fine-tuning workflow).
Example: a real-estate website that predicts price estimates for new listings performs inference. The model’s parameters remain fixed so responses are stable and predictable across requests.
Common misconception: everyday interaction with a deployed model (e.g., a chat assistant) usually does not change the model’s weights. Most production systems separate inference from training; model updates happen only when engineers schedule explicit retraining or fine-tuning steps.
## Side-by-side comparison
| Aspect | Training | Inference |
| - | - | - |
| Purpose | Learn parameters from labeled data | Use learned parameters to make predictions |
| Input | Labeled examples (features + labels) | Unlabeled examples (features only) |
| Outputs | Updated model parameters, training metrics | Predictions, probabilities, or scores |
| Computation cost | Typically high (backpropagation, large batches) | Typically lower (forward pass only) |
| State changes | Parameters and some optimizer/training state change | Parameters remain fixed (unless online learning enabled) |
| Examples | Model development, fine-tuning | Production prediction, serving |
## What changes during training?
The values that change are primarily the model’s parameters (often called weights). These parameters encode the patterns the model learns. Other training-time state that may change includes:
* BatchNorm running mean/variance
* Optimizer state (momentum terms, Adam’s moment estimates)
* Learning-rate schedules or other training hyperparameters (when intentionally adjusted)
In production inference runs with the learned parameters fixed so behavior is stable until a deliberate retraining or fine-tuning operation occurs.
## When does inference update a model?
By default, inference does not update model parameters. However, some systems are designed for online learning or continuous fine-tuning where new observations are incorporated into the model during operation. These are deliberate architecture choices and require safeguards (data validation, drift detection, access control, and monitoring) because they can introduce instability or unintended bias.
Note: Online learning and continuous fine-tuning are valid design patterns for some applications, but they are not the default. Standard production inference uses the trained model without changing its parameters; updates are performed through controlled retraining processes.
## Further reading and resources
* [Machine Learning — Coursera / Andrew Ng](https://www.coursera.org/learn/machine-learning)
* [Deep Learning Book — Ian Goodfellow et al.](https://www.deeplearningbook.org/)
* [TensorFlow Model Deployment](https://www.tensorflow.org/tfx/guide/serving)
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.