> ## Documentation Index
> Fetch the complete documentation index at: https://notes.kodekloud.com/llms.txt
> Use this file to discover all available pages before exploring further.

# Recovery Incident Management and Restoration

> Guide to incident management, recovery, resilience, MTTR, runbooks, chaos testing, communication, SLAs, and blameless postmortems for reliable platform engineering.

Welcome. This lesson covers incident management, recovery, and restoration for modern platform engineering. You'll learn the operational foundations—why recovery matters, how to measure it, and practical practices to make recovery reliable at scale.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/why-recovery-matters-modern-platform-engineering.jpg?fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=773537d4aefa7329f7722fea3cd736dc" alt="A presentation slide titled &#x22;Why Recovery Matters in Modern Platform Engineering&#x22; showing four highlighted reasons: Global Scale, Real-Time Expectations, Business Impact, and Continuous Operations, each with a short explanatory line and an icon." width="1920" height="1080" data-path="images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/why-recovery-matters-modern-platform-engineering.jpg" />
</Frame>

Swati, Allen, and Fong must ensure recovery is reliable for global pony spawning at SPR (Sparkle Pony Ranch). In practice, design for resilience and plan for recovery—then measure both.

## Resilience vs. Recovery

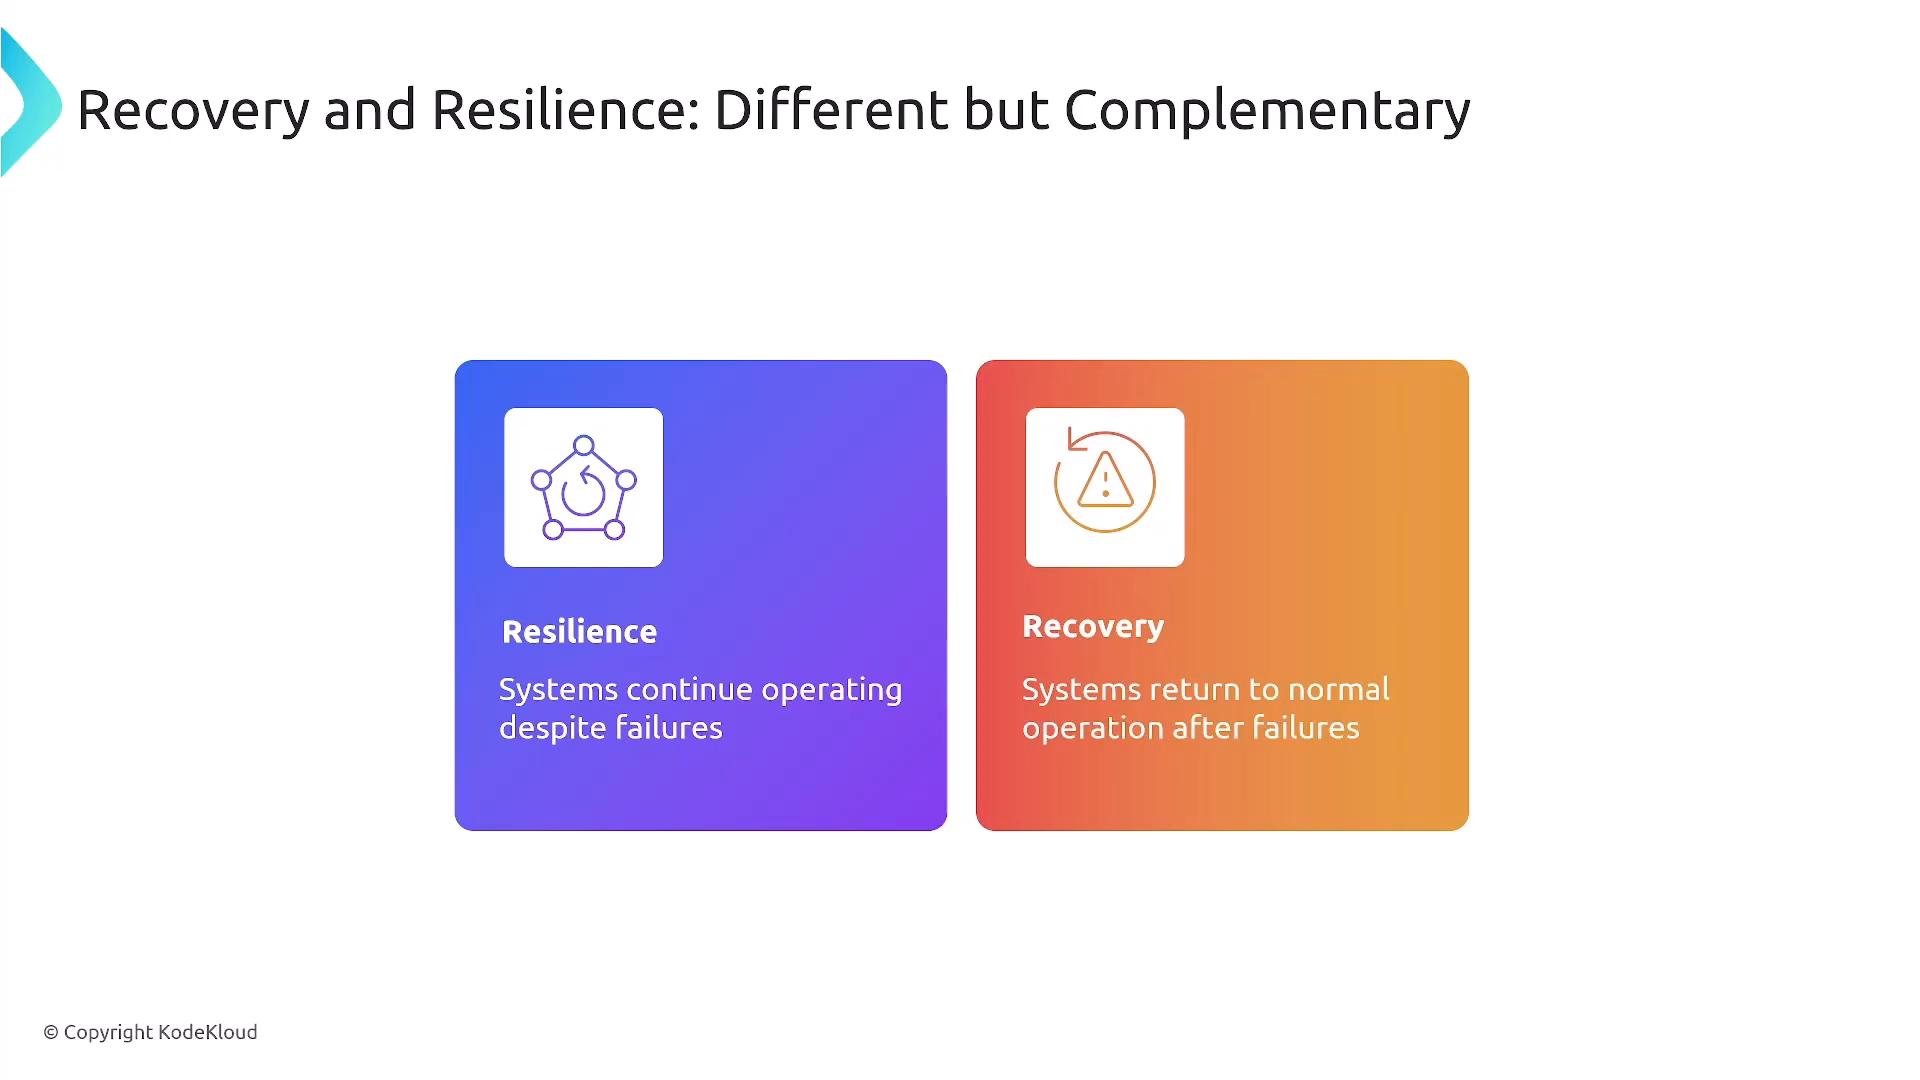
Resilience and recovery are related but distinct concepts:

* Resilience: the system continues operating despite failures (for example, Kubernetes restarting pods, or redundant load balancers routing around a failed node).
* Recovery: returning the system to its normal state after a failure (for example, restoring from backups after a data center outage).

Design systems to be resilient and maintain explicit recovery plans and runbooks for when failures exceed resilience mechanisms.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/recovery-resilience-slide-kodekloud.jpg?fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=30ecf7c1660ed2a2572592b96a765ea9" alt="A slide titled &#x22;Recovery and Resilience: Different but Complementary&#x22; showing two colored panels: a purple &#x22;Resilience&#x22; card stating &#x22;Systems continue operating despite failures&#x22; and an orange &#x22;Recovery&#x22; card stating &#x22;Systems return to normal operation after failures.&#x22; The slide is copyrighted to KodeKloud." width="1920" height="1080" data-path="images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/recovery-resilience-slide-kodekloud.jpg" />
</Frame>

## Measuring Recovery: MTTR and Performance Tiers

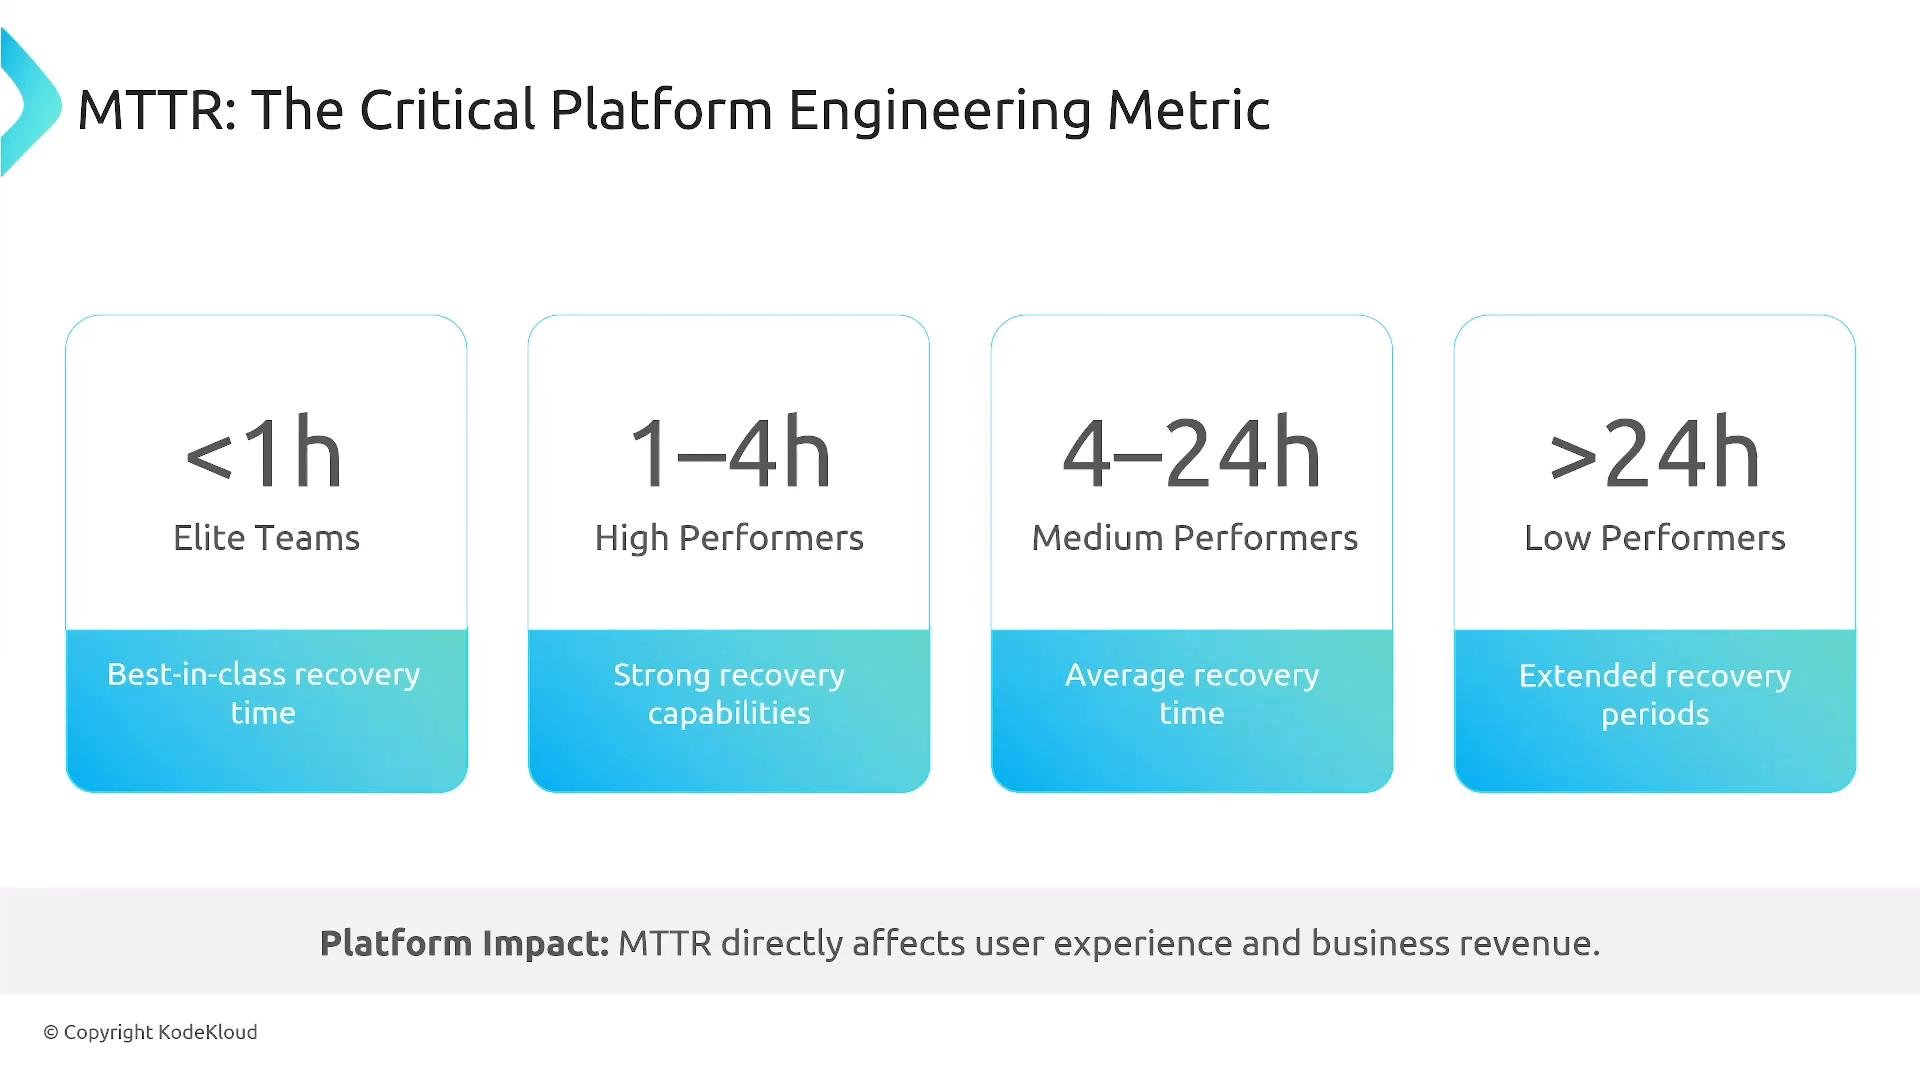
A key recovery metric is MTTR (mean time to recovery). MTTR measures the time from incident start until the service is fully restored. It directly affects user experience, developer velocity, and revenue.

| Performance Tier | MTTR Range | What it implies |
| - | - | - |
| Elite teams | `< 1 hour` | Best-in-class recovery; rapid automation and playbooks |
| High performers | `1–4 hours` | Strong monitoring and practiced runbooks |
| Medium performers | `4–24 hours` | Manual recovery steps likely; partial automation |
| Low performers | `>24 hours` | Significant manual effort; gaps in detection/response |
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/mttr-recovery-tiers-impact-revenue.jpg?fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=f11eaa139e570f78f8103e8d3b1a992c" alt="A slide titled &#x22;MTTR: The Critical Platform Engineering Metric&#x22; showing four recovery categories: <1h (Elite Teams, best-in-class recovery), 1–4h (High Performers), 4–24h (Medium Performers), and >24h (Low Performers). It notes MTTR's impact on user experience and business revenue." data-og-width="1920" width="1920" data-og-height="1080" height="1080" data-path="images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/mttr-recovery-tiers-impact-revenue.jpg" data-optimize="true" data-opv="3" srcset="https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/mttr-recovery-tiers-impact-revenue.jpg?w=280&fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=3d853c841bee559422aa6a210a35e0ba 280w, https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/mttr-recovery-tiers-impact-revenue.jpg?w=560&fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=ccfce7e29a2a19ec2eb4a13eaeba443a 560w, https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/mttr-recovery-tiers-impact-revenue.jpg?w=840&fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=6e8c703d50ff877a0c06c6cf9ec6b679 840w, https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/mttr-recovery-tiers-impact-revenue.jpg?w=1100&fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=7bd696fd1abacc89066177b34805d3e5 1100w, https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/mttr-recovery-tiers-impact-revenue.jpg?w=1650&fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=04da97df5f3f81242e8739f93a9a7222 1650w, https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/mttr-recovery-tiers-impact-revenue.jpg?w=2500&fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=b8d47d5e945a9c52b81520e410d8734f 2500w" />
</Frame>

## Classifying Incidents (Severity Levels)

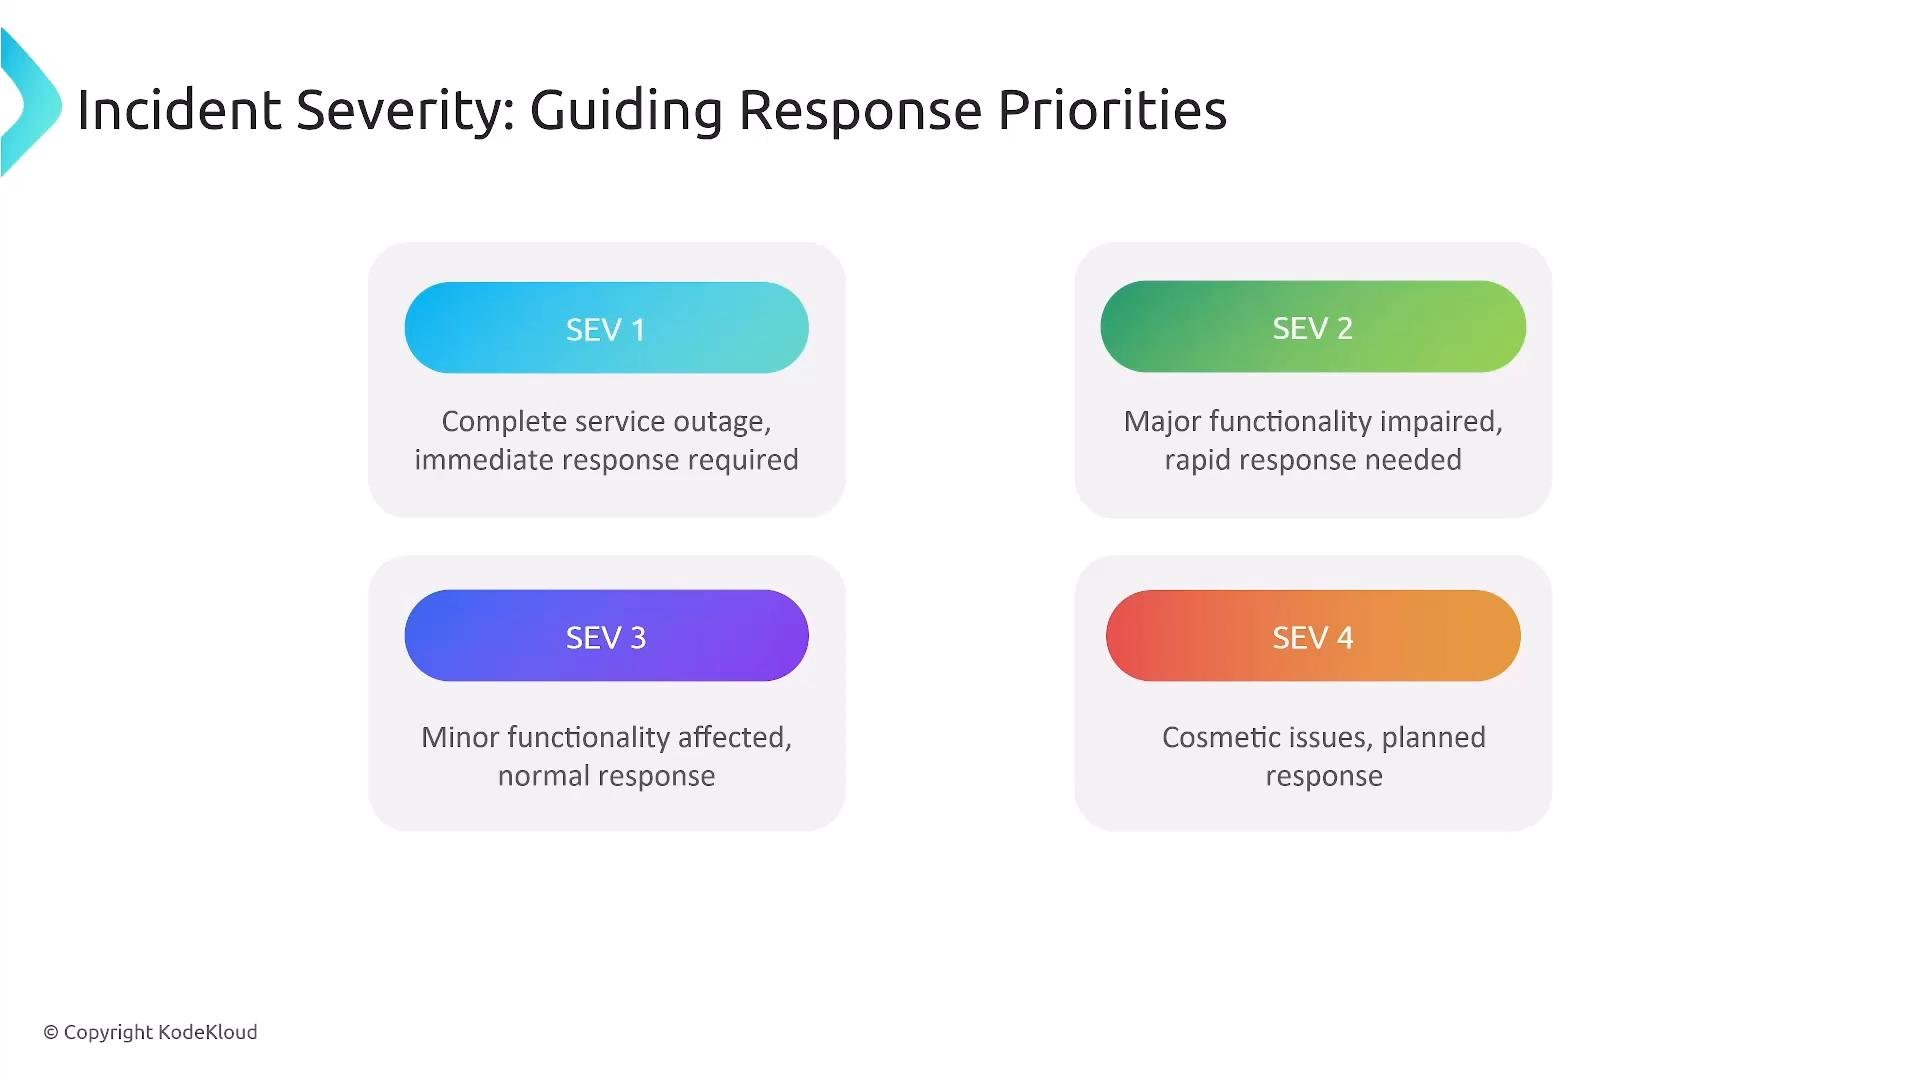
Classify incidents to set response priorities and ensure the right people and processes are engaged.

| Severity | Description | Typical Response |
| -: | - | - |
| `SEV1` | Complete service outage (e.g., no ponies can spawn) | Immediate, all-hands response |
| `SEV2` | Major degraded functionality (e.g., rainbow ponies unavailable) | Rapid response from owners |
| `SEV3` | Minor functionality affected | Triage during business hours |
| `SEV4` | Cosmetic or low-impact issues | Planned maintenance or backlog |
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/incident-severity-sev1-4-response-priorities.jpg?fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=d0814f26005176bb4db8482ff61550dc" alt="A slide titled &#x22;Incident Severity: Guiding Response Priorities&#x22; showing four color-coded severity boxes (SEV 1–4) that describe response urgency from immediate for complete outages to planned responses for cosmetic issues." width="1920" height="1080" data-path="images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/incident-severity-sev1-4-response-priorities.jpg" />
</Frame>

## Structured Incident Response Process

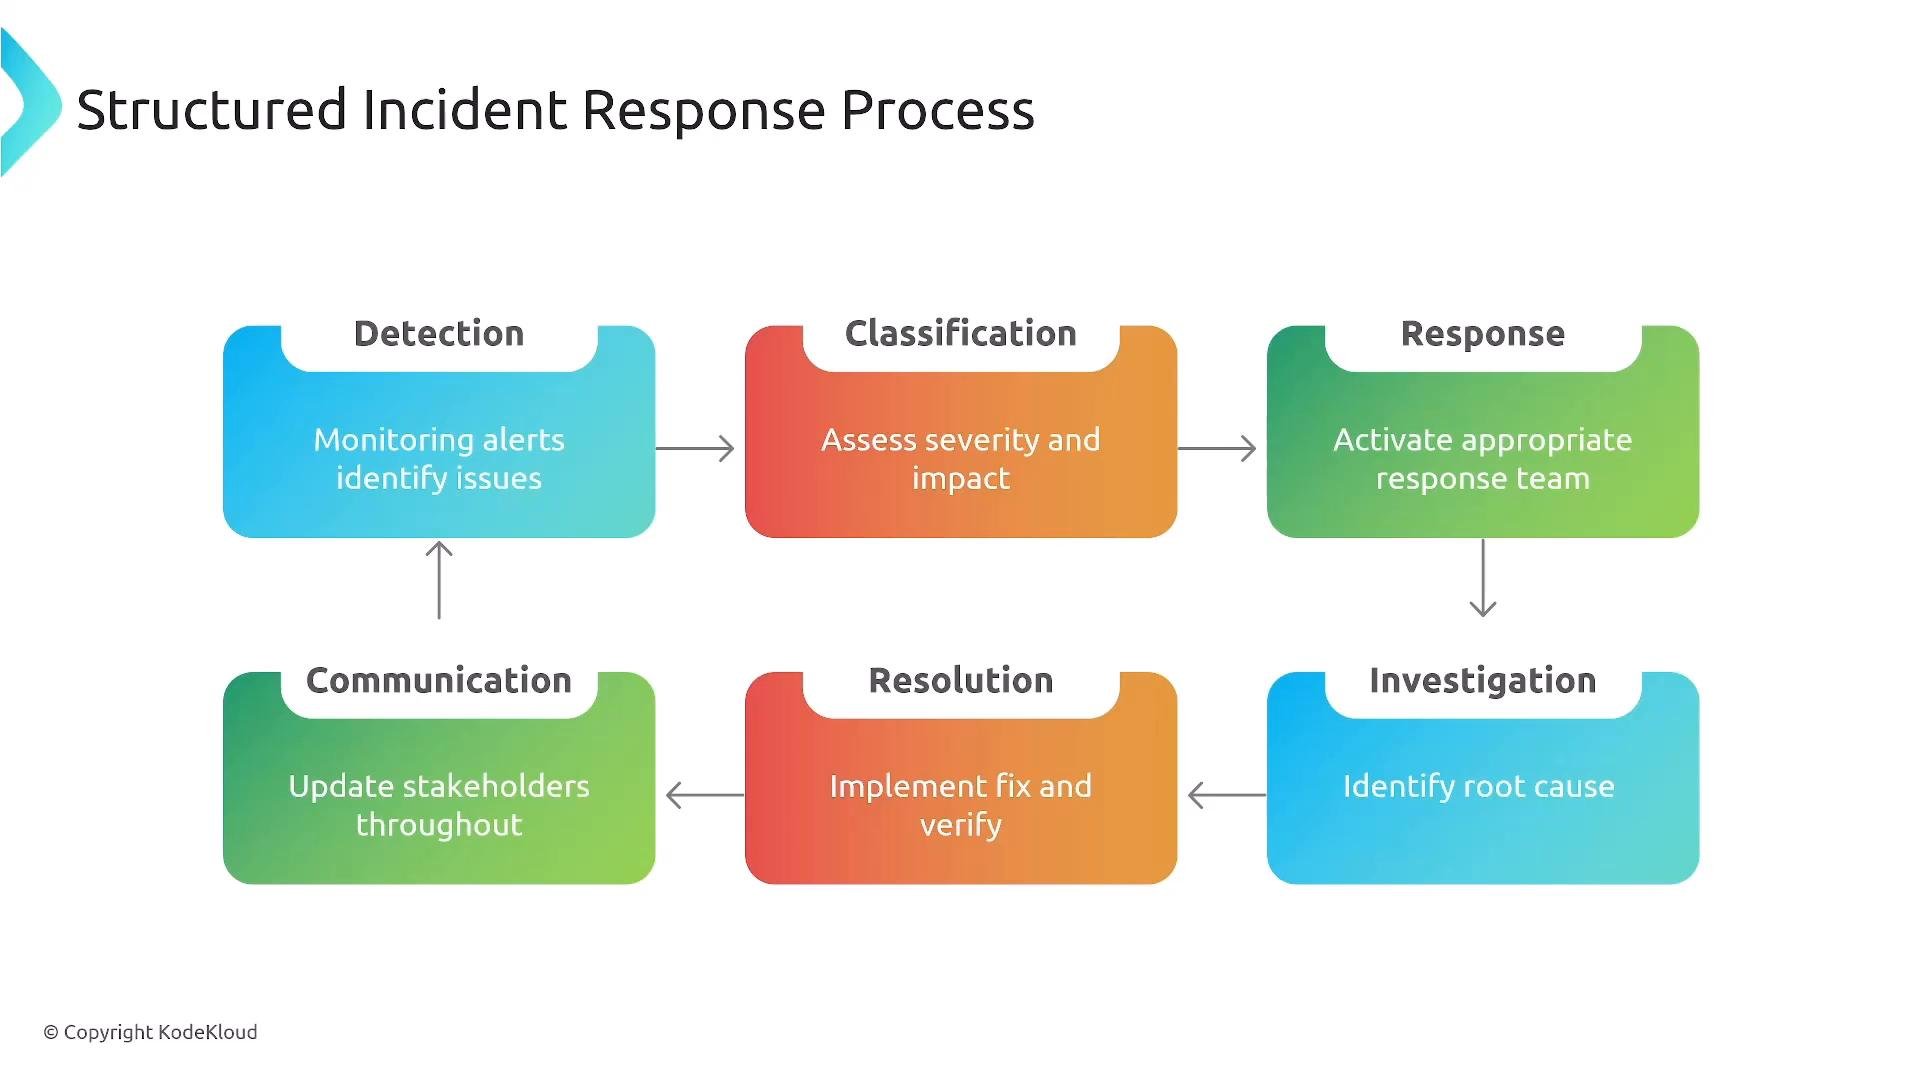
A repeatable incident response flow reduces confusion and shortens MTTR. Common stages:

1. Detection
2. Classification / Evaluation
3. Response (including decisions to defer or escalate)
4. Investigation
5. Resolution (implement fix)
6. Communication

Investigation, resolution, and communication are iterative until the service is recovered. Lessons learned should feed back into detection and prevention.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/structured-incident-response-flowchart.jpg?fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=09f409363d05b17958db4d3a0318de85" alt="A colorful flowchart titled &#x22;Structured Incident Response Process&#x22; showing stages like Detection, Classification, Response, Investigation, Resolution, and Communication. Each stage has a short action (e.g., monitor alerts, assess severity, activate response team, identify root cause, implement fix, update stakeholders)." width="1920" height="1080" data-path="images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/structured-incident-response-flowchart.jpg" />
</Frame>

## Early Detection: Sources and Best Practices

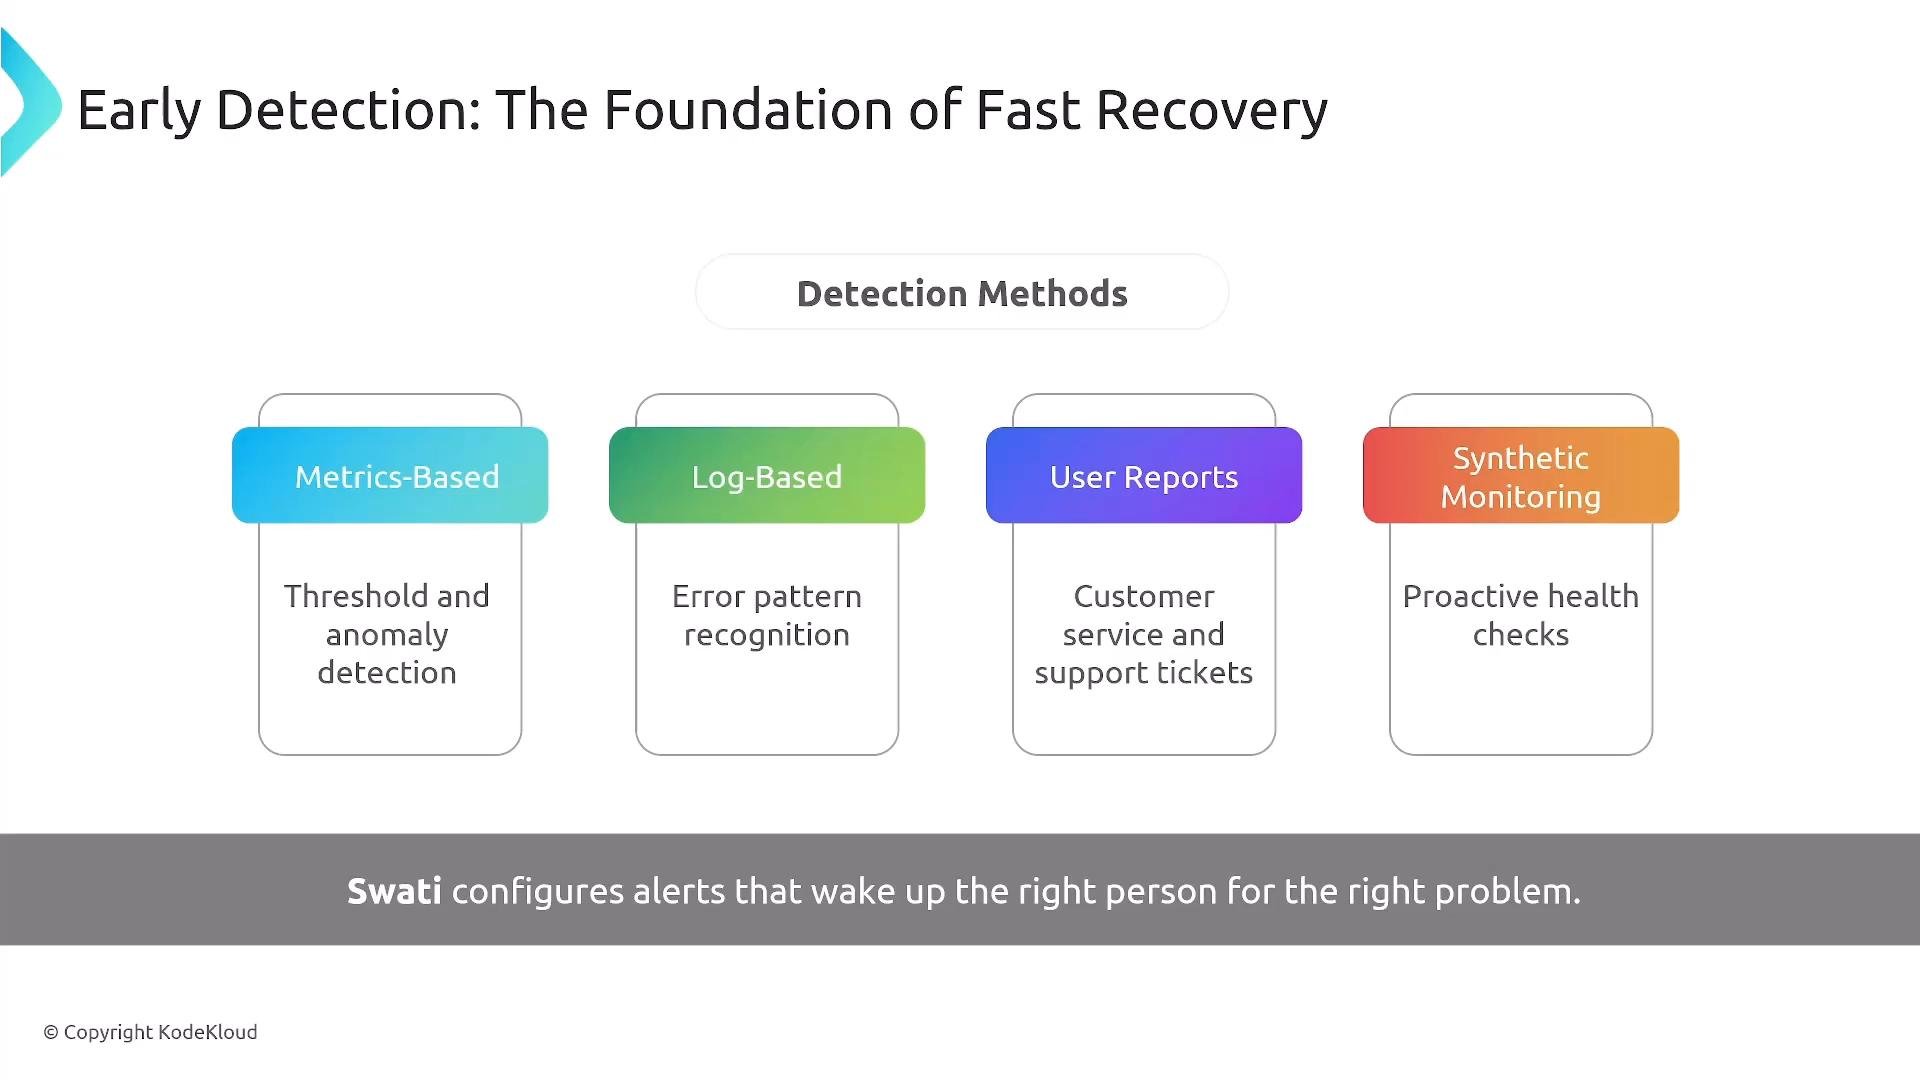
Early detection is essential for fast recovery. Typical sources:

* Metrics-based alerts (thresholds, anomaly detection)
* Log-based alerts (error rates, state changes)
* User reports (support tickets, social channels)
* Synthetic checks (automated probes and health checks)

SRE and monitoring teams should ensure alerts route the right notification to the right person or team, avoiding alert fatigue.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/early-detection-alerts-synthetic-logs-metrics.jpg?fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=2b39125d263f35e3716740b818e42ee7" alt="A presentation slide titled &#x22;Early Detection: The Foundation of Fast Recovery&#x22; showing four detection methods—Metrics-Based, Log-Based, User Reports, and Synthetic Monitoring—each with a short description. A footer reads &#x22;Swati configures alerts that wake up the right person for the right problem.&#x22;" width="1920" height="1080" data-path="images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/early-detection-alerts-synthetic-logs-metrics.jpg" />
</Frame>

## Communication During Incidents

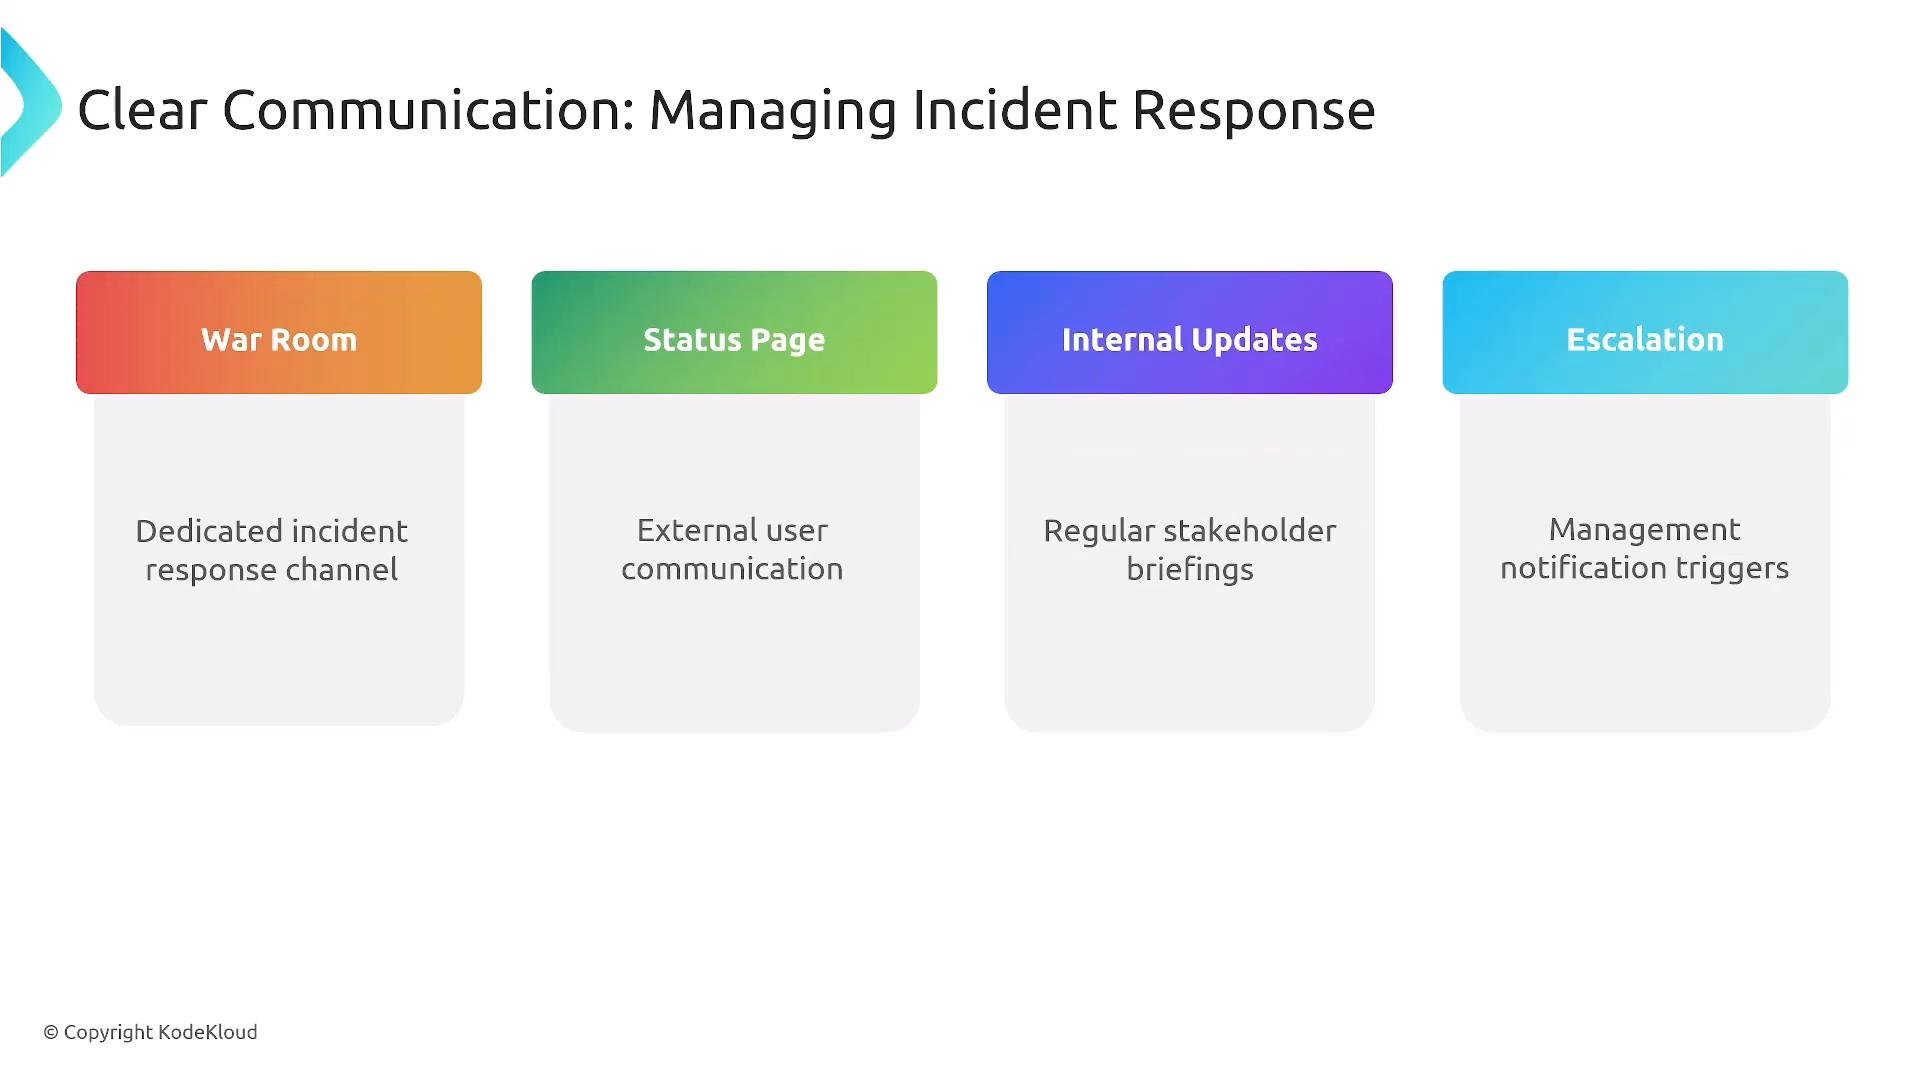
Define channels and policies ahead of time so communication is clear and consistent:

* War room: a dedicated incident response channel (Slack, Teams, Discord)
* Status page: public updates for users
* Internal updates: scheduled stakeholder briefings
* Escalation rules: automated triggers for management notification

Decide in advance when to use external channels (status page, social media) to avoid ad hoc messaging.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/clear-communication-incident-response-channels.jpg?fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=708367158a964dc4f8ab3c2d4f26bb18" alt="A slide titled &#x22;Clear Communication: Managing Incident Response&#x22; showing four colored boxes for communication channels. The boxes are War Room (dedicated incident response channel), Status Page (external user communication), Internal Updates (regular stakeholder briefings), and Escalation (management notification triggers)." width="1920" height="1080" data-path="images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/clear-communication-incident-response-channels.jpg" />
</Frame>

<Callout icon="lightbulb" color="#1CB2FE">
  When communicating externally, provide an estimated recovery time and update cadence. SPR should notify users when Sparkle Pony Ranch is impacted and include an estimated recovery timeframe and next update ETA.
</Callout>

## Runbooks: Codify Diagnosis and Resolution

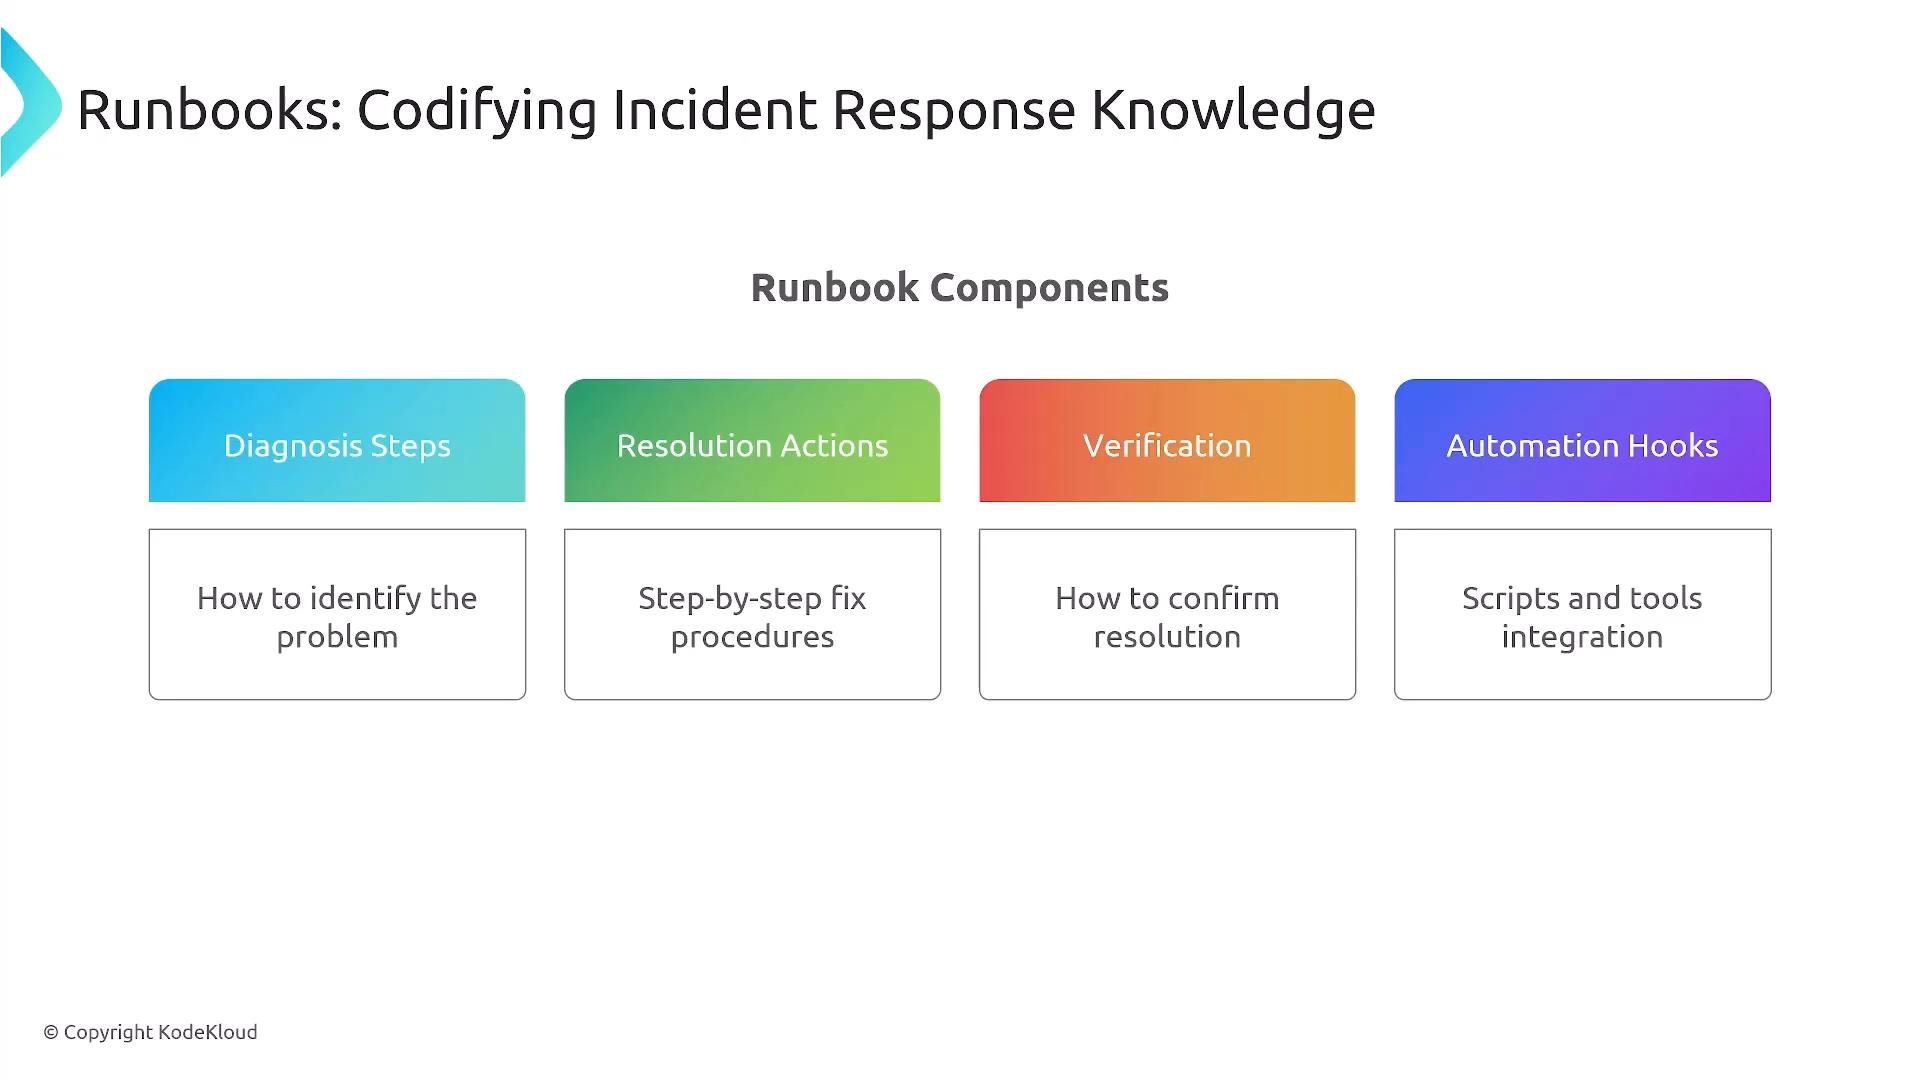
Runbooks capture the step-by-step knowledge needed to diagnose and resolve incidents. Typical components:

* Diagnosis steps (how to identify the problem)
* Resolution actions (ordered, explicit fixes)
* Verification (how to confirm the service is recovered)
* Automation hooks (scripts/playbooks to run)

Runbooks let less-experienced team members follow documented procedures and are the precursor to safe automation.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/runbooks-codifying-incident-response.jpg?fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=0a0d122b3da5043b88d1aa3a017931ca" alt="A presentation slide titled &#x22;Runbooks: Codifying Incident Response Knowledge&#x22; that lists four runbook components. The components are Diagnosis Steps (how to identify the problem), Resolution Actions (step-by-step fixes), Verification (how to confirm resolution), and Automation Hooks (scripts and tools integration)." width="1920" height="1080" data-path="images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/runbooks-codifying-incident-response.jpg" />
</Frame>

Runbooks should be integrated with monitoring and alerting so diagnostic steps or playbooks can be triggered automatically. In modern setups teams also use runbooks to train or guide AI-assisted responders.

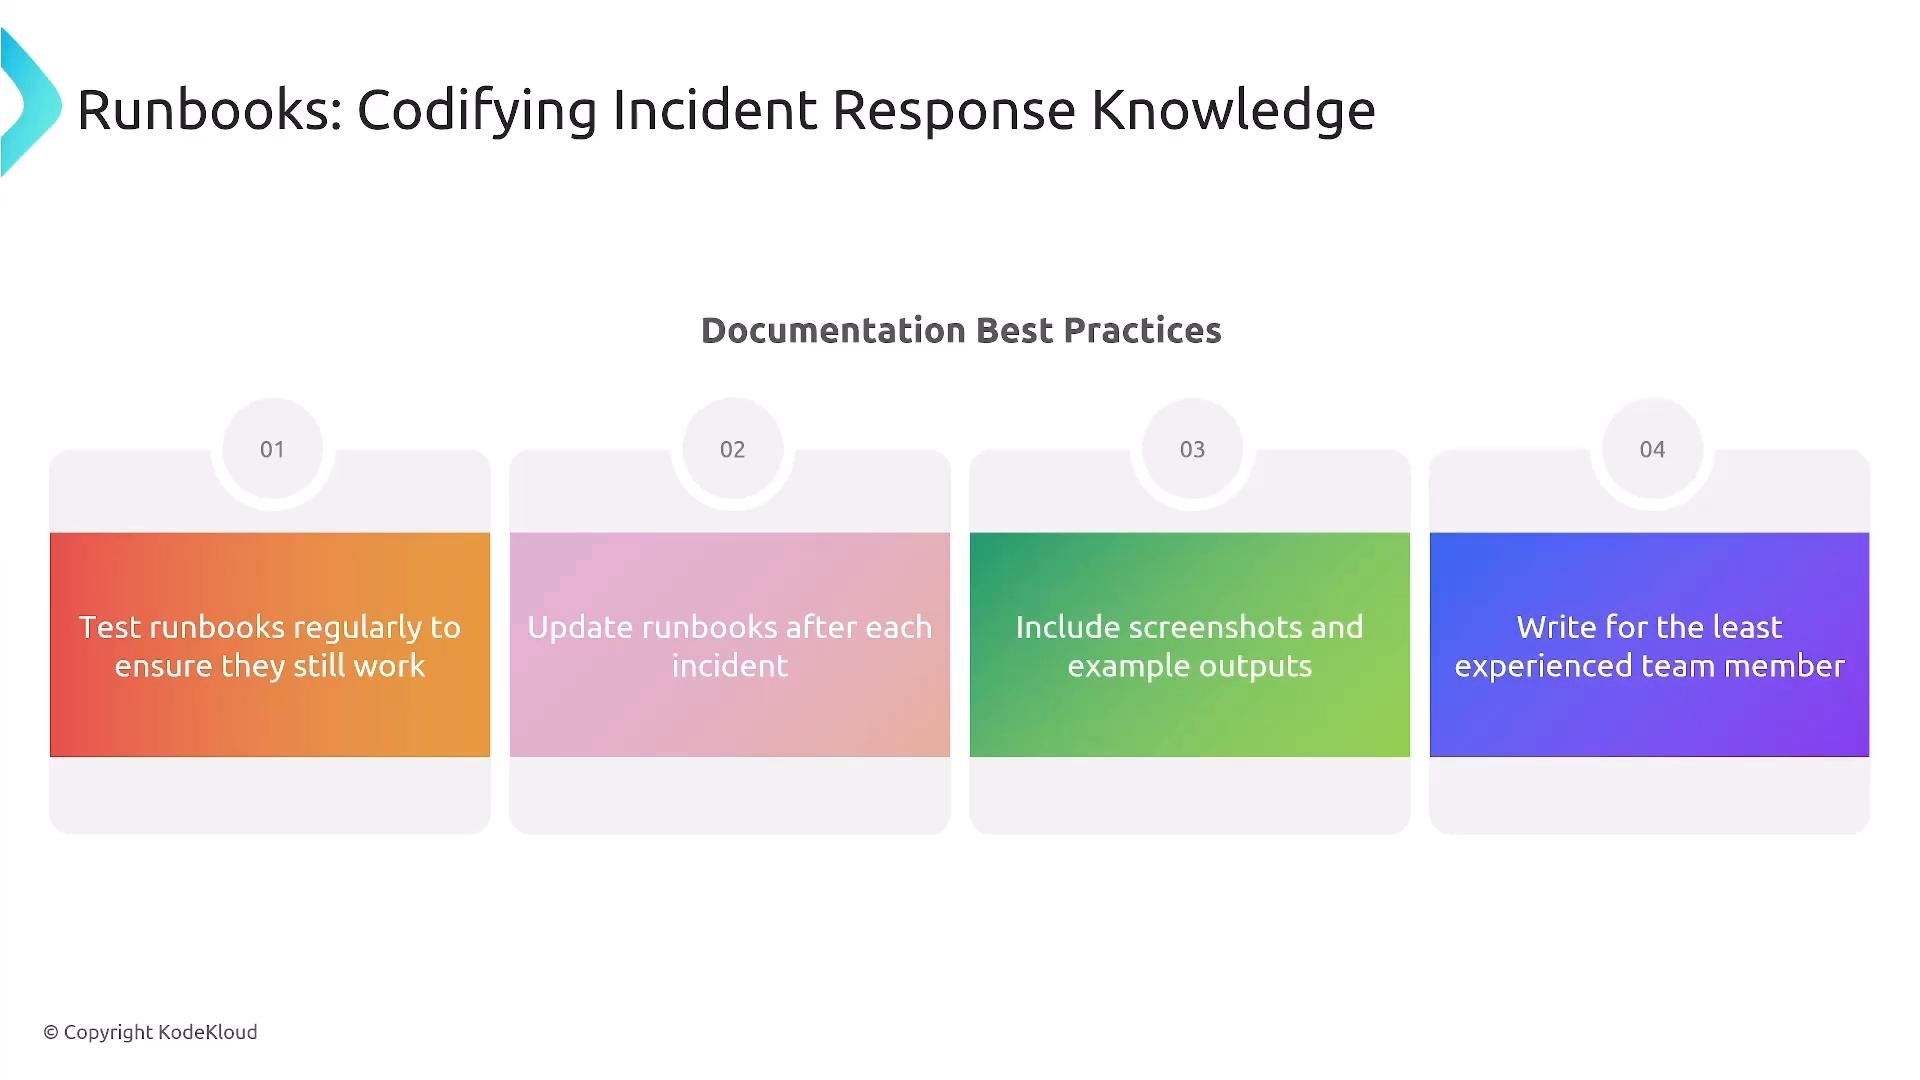
Best practices:

* Test runbooks regularly
* Update them after every incident
* Include screenshots, example outputs, and media where useful
* Write for the least-experienced person who might execute them
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/runbooks-incident-response-best-practices.jpg?fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=100165e6e4f8bd1647df6d0c401f71b4" alt="A presentation slide titled &#x22;Runbooks: Codifying Incident Response Knowledge&#x22; showing &#x22;Documentation Best Practices.&#x22; It lists four tips: test runbooks regularly, update them after each incident, include screenshots/example outputs, and write for the least experienced team member." width="1920" height="1080" data-path="images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/runbooks-incident-response-best-practices.jpg" />
</Frame>

<Callout icon="warning" color="#FF6B6B">
  Automate only after runbook steps are validated through manual practice and testing. Automation without practice can create hidden failure modes and increase MTTR.
</Callout>

## Chaos Engineering: Validate Recovery Under Real Conditions

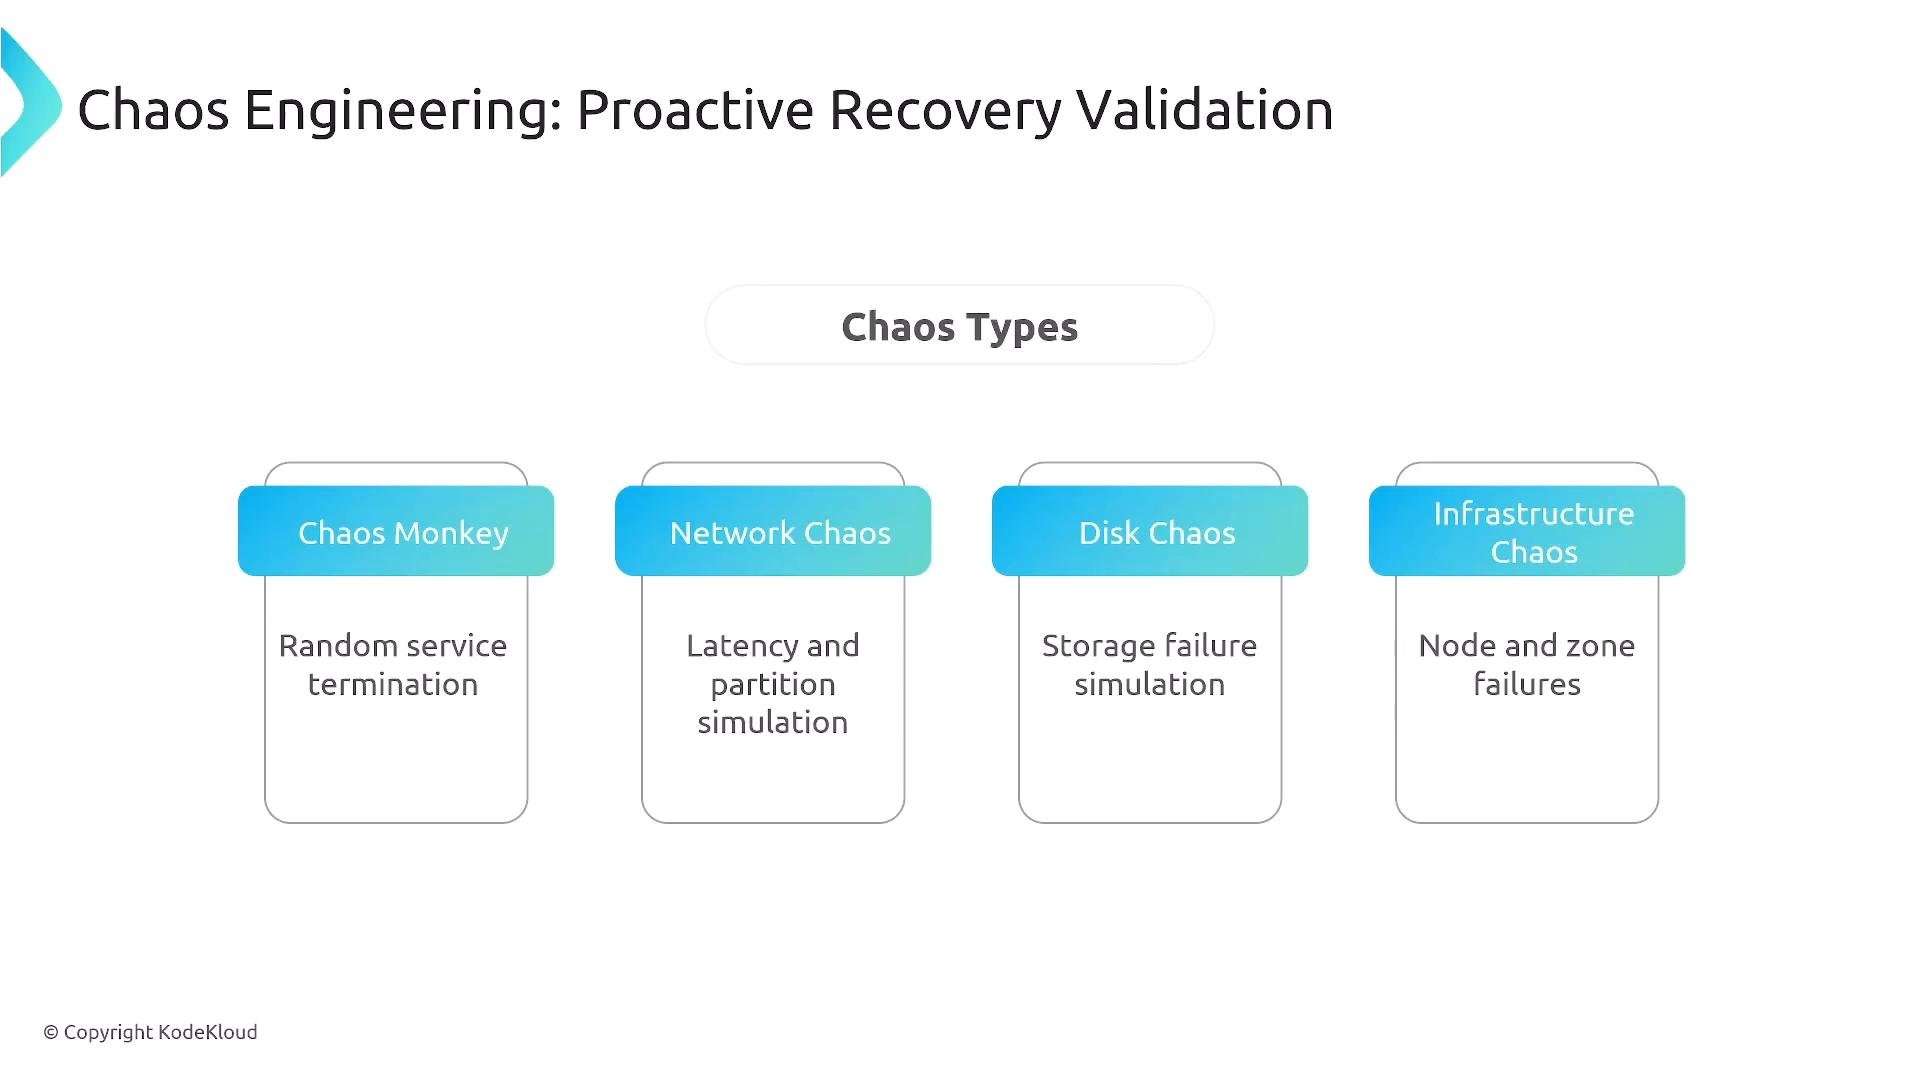
Use controlled chaos engineering experiments to validate resiliency and recovery procedures. Common types:

* Chaos Monkey: random service termination
* Network chaos: latency, packet loss, partitioning
* Disk chaos: storage failure simulation
* Infrastructure chaos: node/zone/data-center failures

The goal is to verify that recovery and rollback procedures work under pressure. See the Chaos Engineering course for practical guidance: [Chaos Engineering](https://learn.kodekloud.com/user/courses/chaos-engineering).
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/chaos-types-monkey-network-disk-infra.jpg?fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=6946ed66d29b41eaebd64a320c47a90a" alt="A presentation slide titled &#x22;Chaos Engineering: Proactive Recovery Validation&#x22; with a &#x22;Chaos Types&#x22; section. It shows four boxes: Chaos Monkey (random service termination), Network Chaos (latency and partition simulation), Disk Chaos (storage failure simulation), and Infrastructure Chaos (node and zone failures)." width="1920" height="1080" data-path="images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/chaos-types-monkey-network-disk-infra.jpg" />
</Frame>

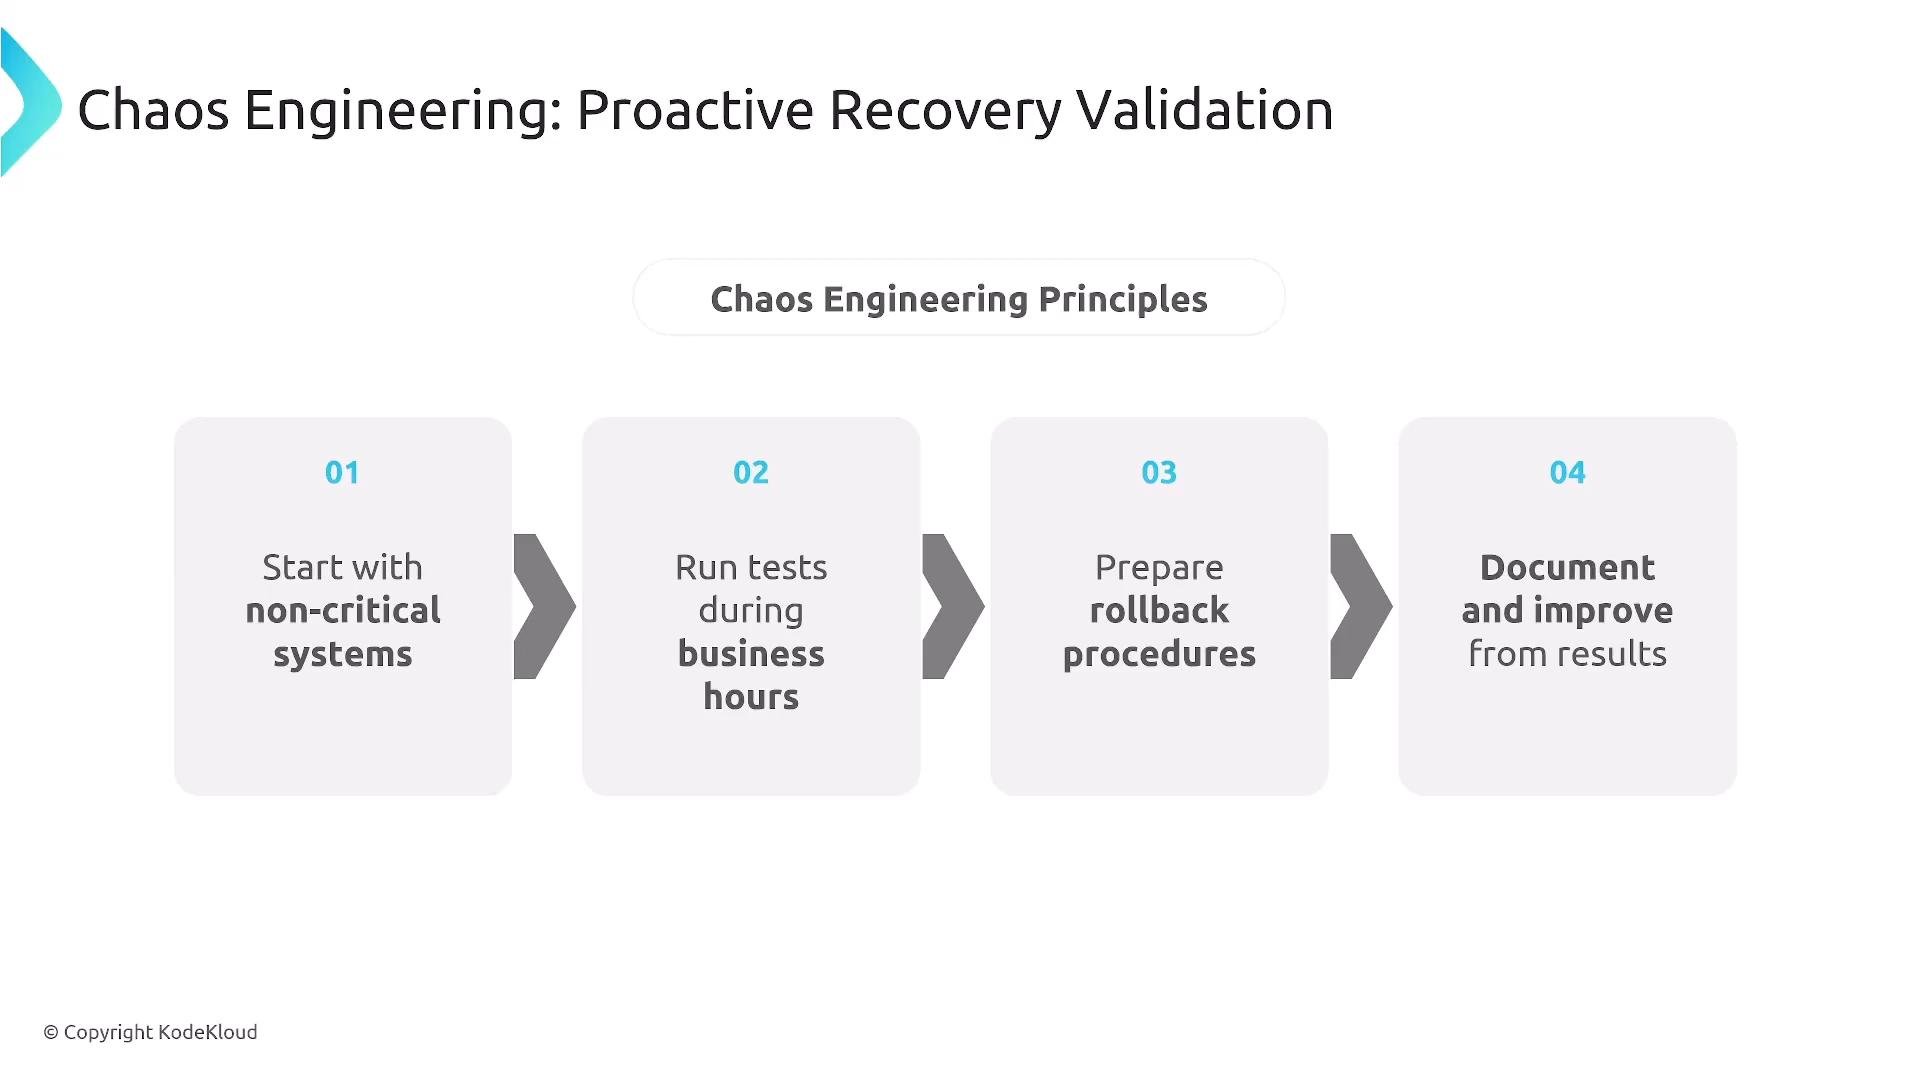
Principles for running chaos experiments:

* Start small and non-critical (usually non-production)
* Run tests during business hours initially so teams can respond
* Prepare rollback and mitigation procedures before you start
* Document results and iterate to improve resiliency

As maturity increases, scale experiments to higher-traffic and more-critical systems.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/chaos-engineering-proactive-recovery-slide.jpg?fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=9589484e71738a03a09eadd0c25b94bb" alt="A presentation slide titled &#x22;Chaos Engineering: Proactive Recovery Validation&#x22; showing four numbered principles: 01 start with non-critical systems, 02 run tests during business hours, 03 prepare rollback procedures, and 04 document and improve from results." width="1920" height="1080" data-path="images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/chaos-engineering-proactive-recovery-slide.jpg" />
</Frame>

## Recovery Objectives, SLAs, and Cost Tradeoffs

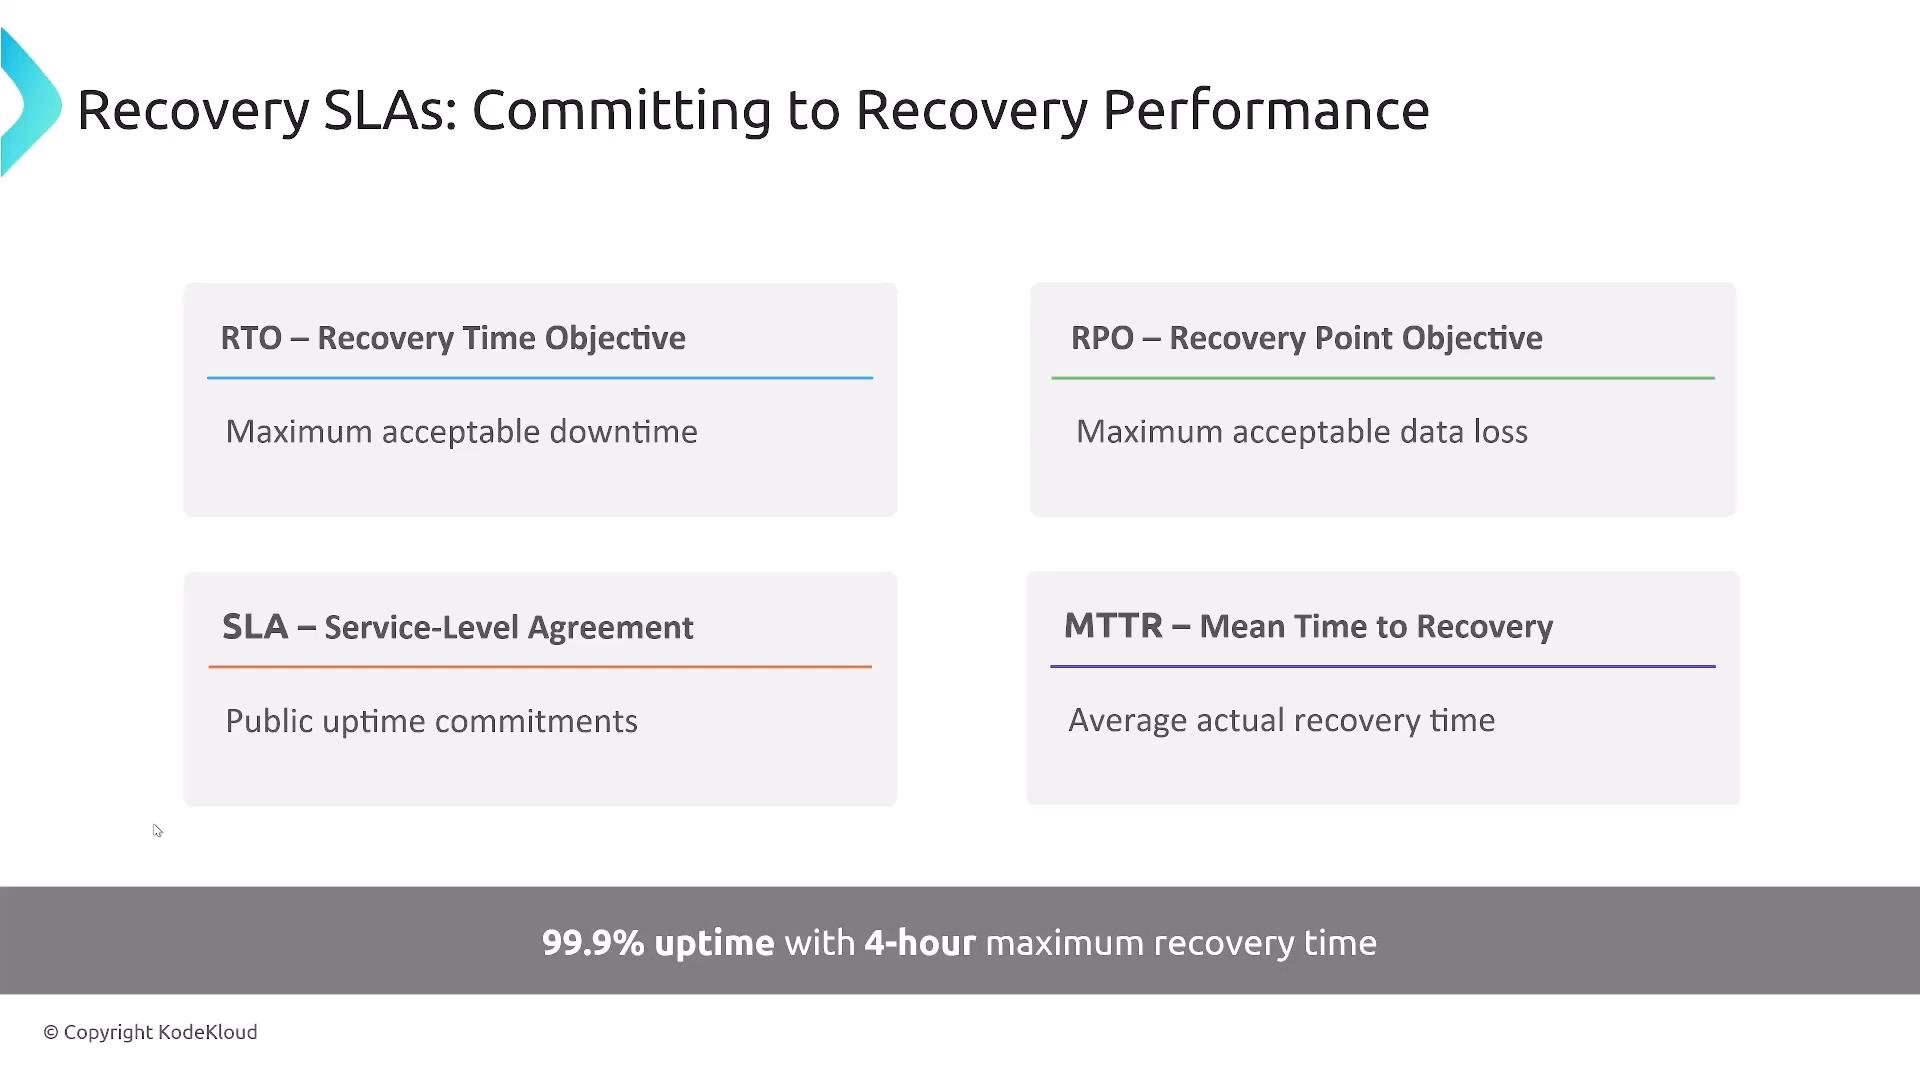
Understand and document recovery commitments with the business:

| Concept | Meaning | Example |
| -: | - | - |
| RTO (Recovery Time Objective) | Maximum acceptable downtime | `4 hours` |
| RPO (Recovery Point Objective) | Maximum acceptable data loss | `2 hours` (for 2-hour backups) |
| SLA (Service Level Agreement) | Public uptime commitment to customers | `99.9% uptime` |
| MTTR | Average actual recovery time | Measured metric from incidents |

SPR might commit to `99.9%` uptime with a 4-hour maximum recovery time—explicit RPO and MTTR definitions are essential.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/recovery-slas-rto-rpo-sla-mttr.jpg?fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=20fb965e3b34ff8204b6cac482699b8c" alt="A presentation slide titled &#x22;Recovery SLAs: Committing to Recovery Performance&#x22; that lists RTO, RPO, SLA, and MTTR with short definitions (maximum acceptable downtime, maximum acceptable data loss, public uptime commitments, average actual recovery time). A footer notes &#x22;99.9% uptime with 4-hour maximum recovery time.&#x22;" width="1920" height="1080" data-path="images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/recovery-slas-rto-rpo-sla-mttr.jpg" />
</Frame>

Understand the cost of extra "nines" in availability:

| Availability | Approx. downtime per year |
| -: | -: |
| `99.9%` | ≈ 9 hours |
| `99.99%` | ≈ 52 minutes |

Decide with the business what level of availability is justified and affordable—each additional nine usually requires disproportionate investment.

## Blameless Postmortems: Learn and Improve

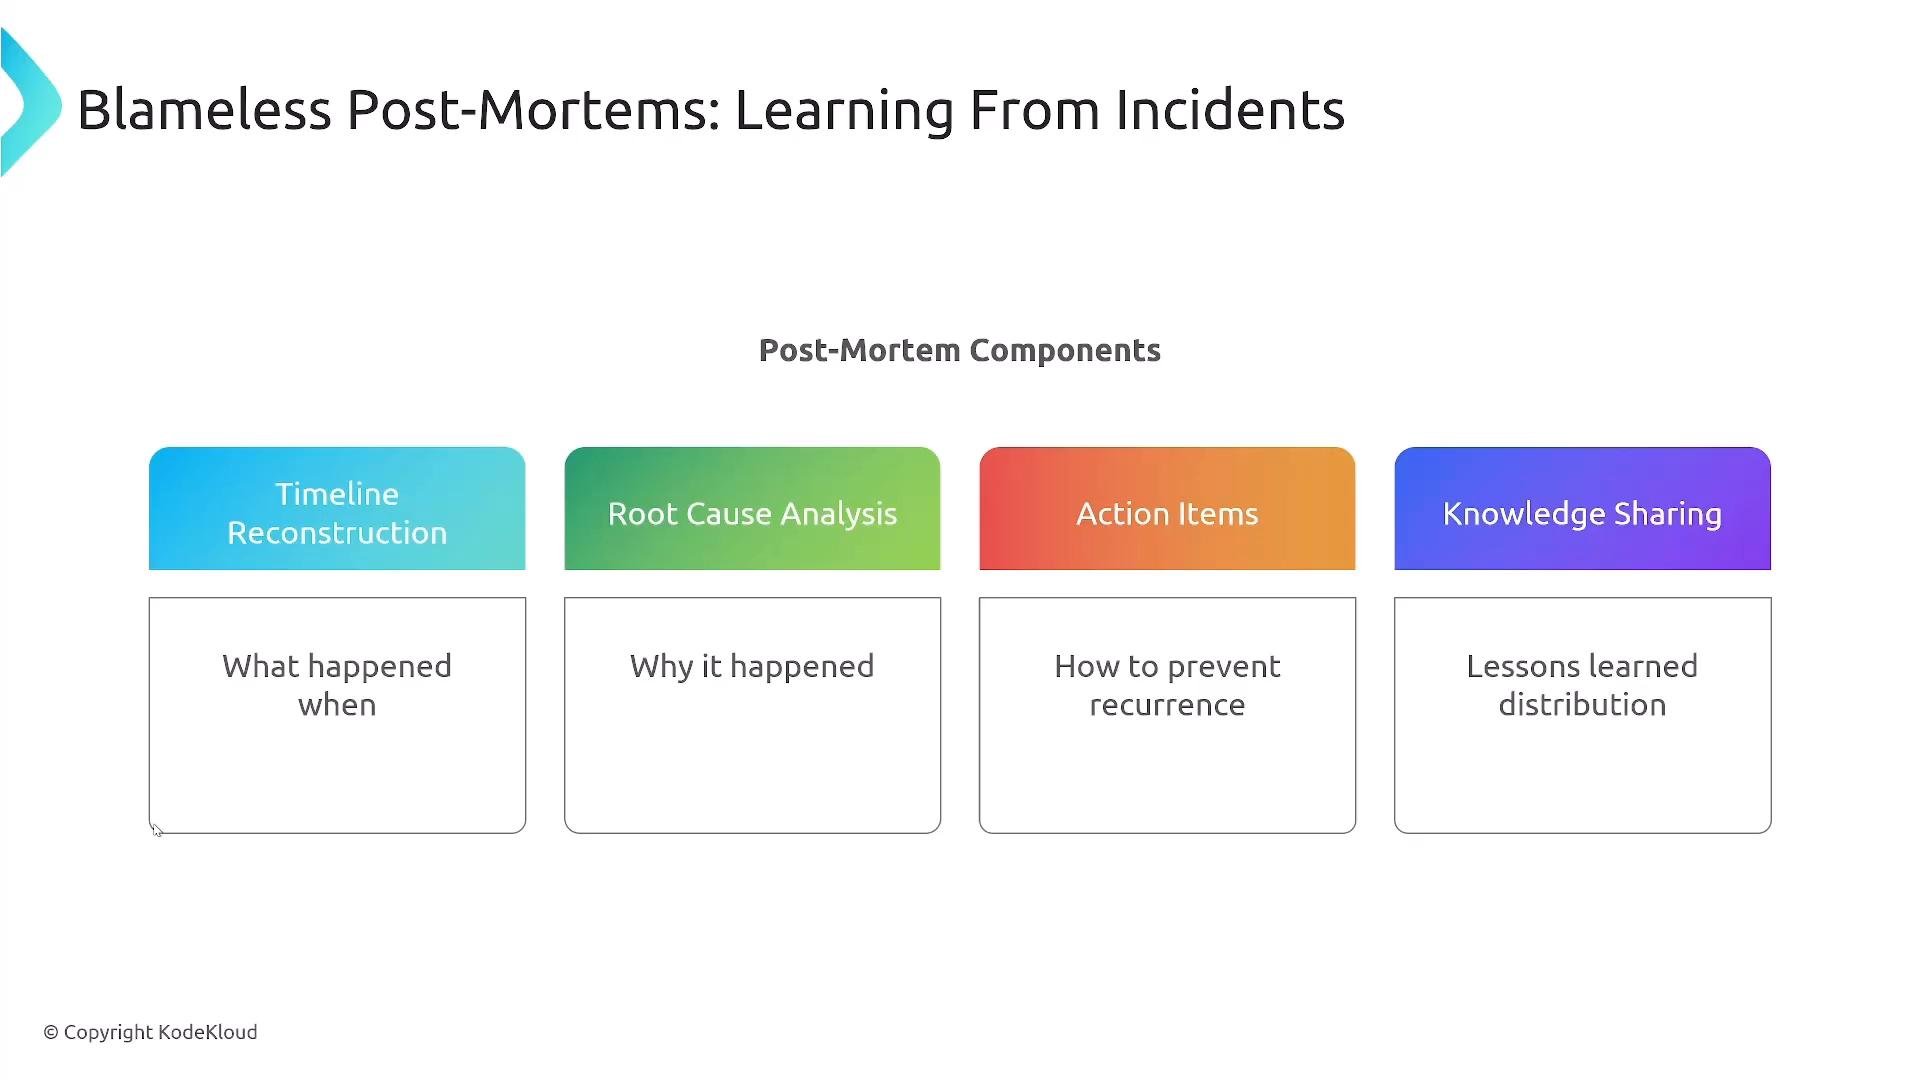
Blameless postmortems reconstruct incident timelines, identify root causes, and define action items. Core principles:

* Assume good intent—people acted with the information they had
* Focus on improving systems, not punishing individuals
* Treat incidents as learning opportunities and share findings

If the same incident reoccurs, it signals a failure to act on prior learnings.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/blameless-postmortems-components-slide.jpg?fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=a17e3675d809921100808c85d732500d" alt="A presentation slide titled &#x22;Blameless Post-Mortems: Learning From Incidents&#x22; that outlines four post-mortem components. The components listed are Timeline Reconstruction, Root Cause Analysis, Action Items, and Knowledge Sharing with brief descriptions under each." width="1920" height="1080" data-path="images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/blameless-postmortems-components-slide.jpg" />
</Frame>

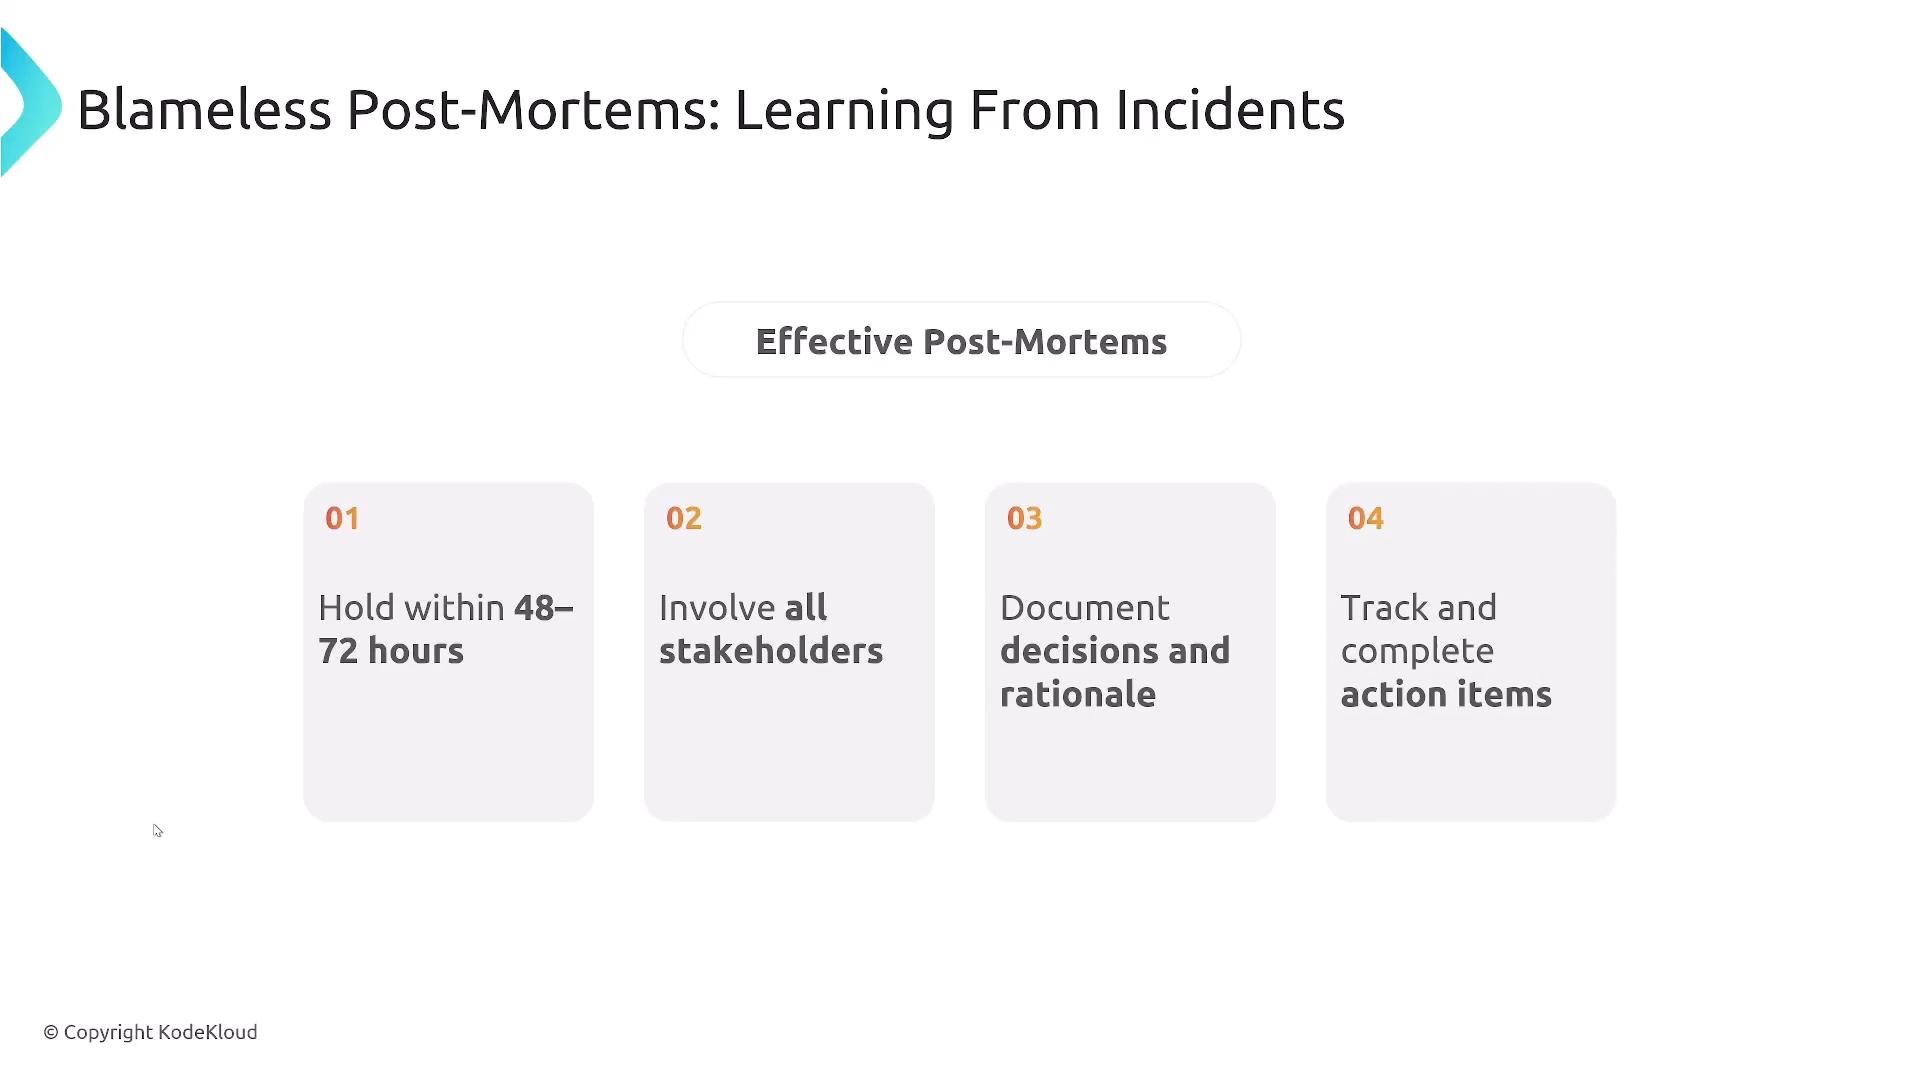
Effective postmortem practices:

* Hold the postmortem within 48–72 hours of incident stabilization
* Include all relevant stakeholders (SRE, product, support, management)
* Document decisions, rationale, and a complete timeline
* Track action items to completion and verify fixes

Record responders' voice recollections quickly, consolidate with logs/screenshots, and build a reliable timeline.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/blameless-postmortems-48-72h-tips.jpg?fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=0dd37cd5bb2844862db5c666dd30895a" alt="A presentation slide titled &#x22;Blameless Post-Mortems: Learning From Incidents&#x22; showing four tips for effective post-mortems: hold within 48–72 hours, involve all stakeholders, document decisions and rationale, and track/complete action items. The slide is © KodeKloud." width="1920" height="1080" data-path="images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/blameless-postmortems-48-72h-tips.jpg" />
</Frame>

## Key Takeaways

* Automate recovery where safe to reduce manual intervention and MTTR.
* Fast detection (metrics, logs, synthetic checks, user reports) minimizes impact.
* Keep runbooks current, testable, and integrated with monitoring and alerting.
* Practice chaos engineering in controlled ways to validate recovery and rollback procedures.
* Define RTO, RPO, SLA, and MTTR clearly with the business; understand the cost of extra “nines.”
* Use blameless postmortems to learn, improve systems, and prevent repeat failures.
<Frame>
  <img src="https://mintcdn.com/kodekloud-c4ac6d9a/SqNNLQOBWbMCTBts/images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/recovery-excellence-platform-automated-fast-detection.jpg?fit=max&auto=format&n=SqNNLQOBWbMCTBts&q=85&s=5f6f5b421c8eab062e370fe77cdbcbec" alt="A presentation slide titled &#x22;Key Takeaways: Recovery Excellence – Platform Engineering Essentials&#x22; showing two colorful cards: 01 Automated Recovery (&#x22;self-healing systems reduce manual intervention&#x22;) and 02 Fast Detection (&#x22;early identification minimizes impact duration&#x22;)." width="1920" height="1080" data-path="images/Prep-Course-Certified-Cloud-Native-Platform-Engineering-Associate-CNPA/Domain-6-Measuring-Your-Platform/Recovery-Incident-Management-and-Restoration/recovery-excellence-platform-automated-fast-detection.jpg" />
</Frame>

Finally, balance cost and risk with business priorities. Recovery and resiliency should serve the business: if the business will not fund five nines, determine what they will accept and design accordingly. Strong recovery increases developer confidence, supports frequent deployments, and turns failures into opportunities to learn and improve.

This is the next-to-last lesson before the end of the section. Thanks for reading.

## Links and References

* Chaos Engineering course (KodeKloud): [https://learn.kodekloud.com/user/courses/chaos-engineering](https://learn.kodekloud.com/user/courses/chaos-engineering)
* Kubernetes Concepts: [https://kubernetes.io/docs/concepts/overview/what-is-kubernetes/](https://kubernetes.io/docs/concepts/overview/what-is-kubernetes/)
* SRE and incident response best practices: search for "Google SRE book" and "Incident Management playbooks" for additional reading.

<CardGroup>
  <Card title="Watch Video" icon="video" cta="Learn more" href="https://learn.kodekloud.com/user/courses/certified-cloud-native-platform-engineering-associate-cnpa/module/81bcce1e-27d9-429e-86dc-64d7ef657530/lesson/ffc8b64b-256c-480f-b1e8-28c19ef683f3" />
</CardGroup>


This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.