

Understanding vector database internals helps you trade off latency, accuracy, memory, and cost intentionally — rather than guessing.
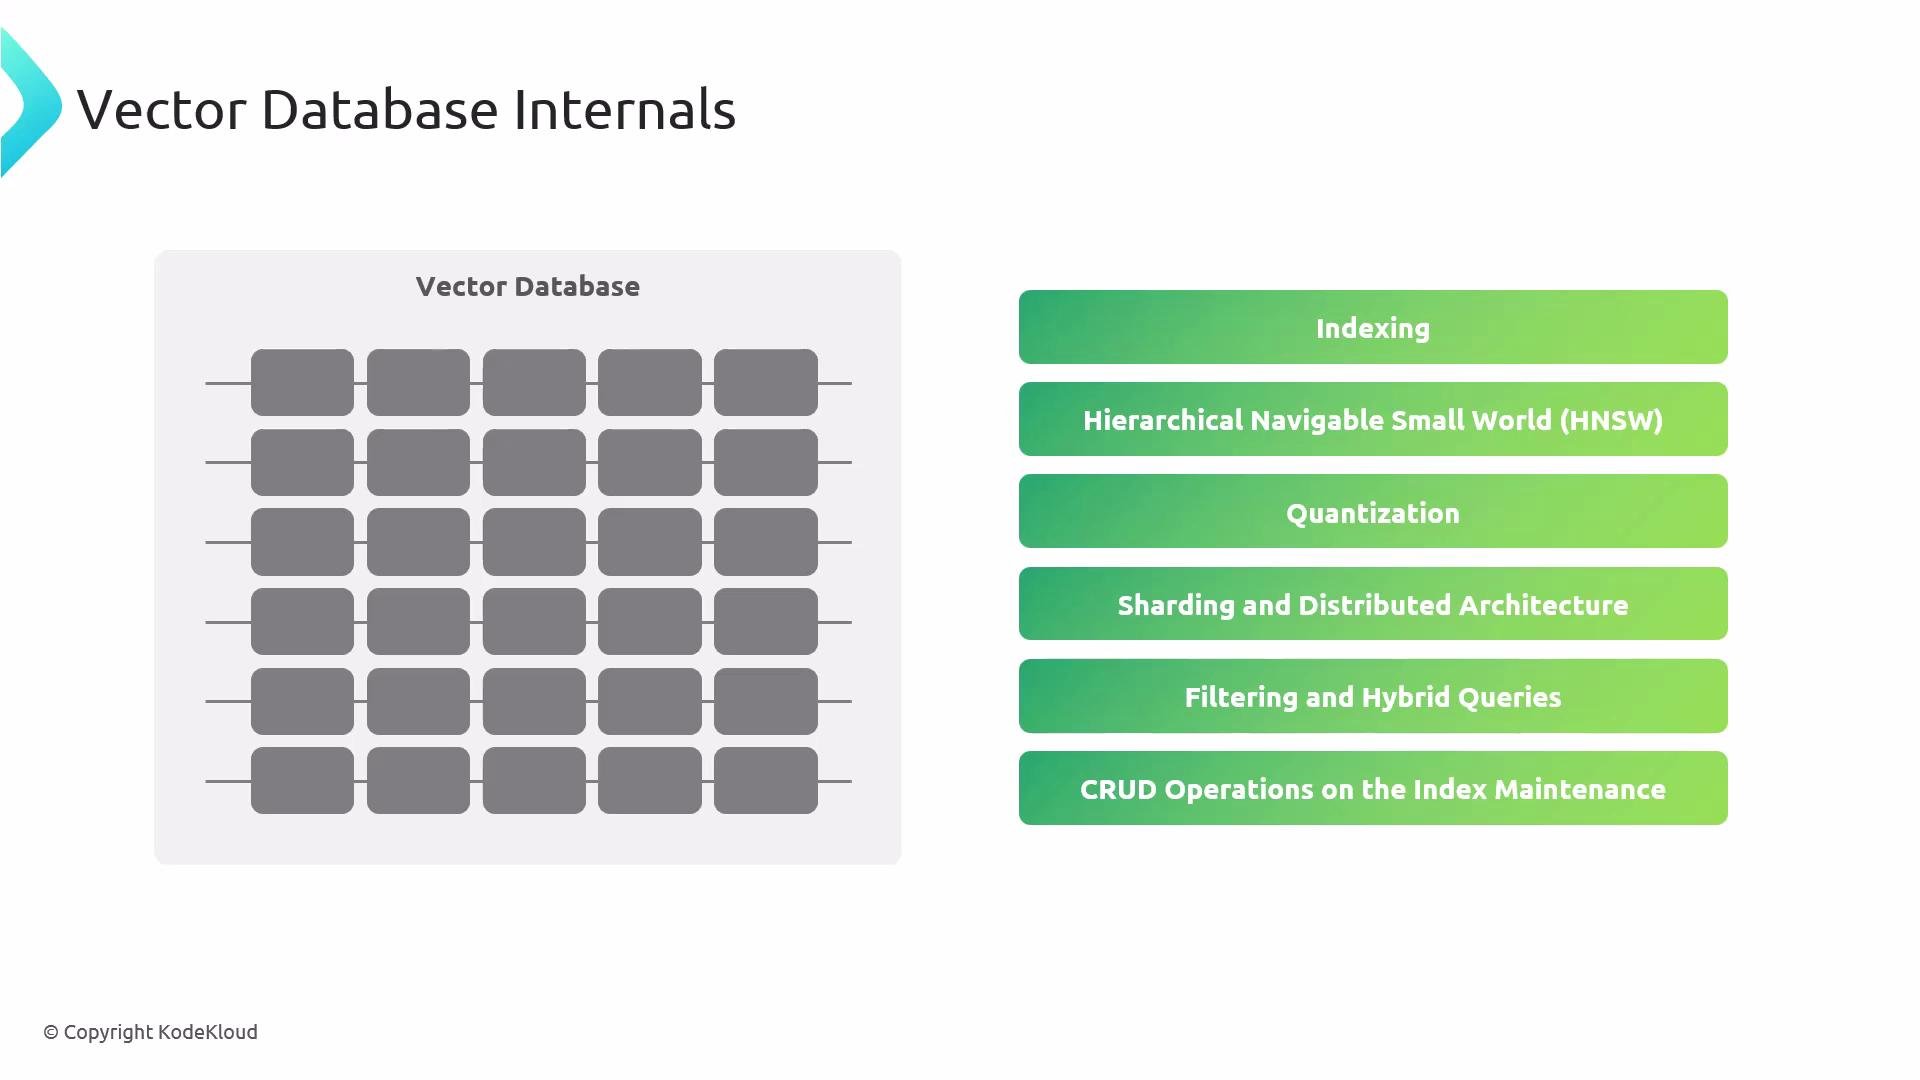
- Indexing is the foundational step: choosing the right index affects search latency, memory use, and the complexity of later components such as HNSW or quantization.
- HNSW is the de facto production ANN algorithm because it builds small-world graphs across layers that permit fast greedy traversal to nearest neighbors.
- Quantization (e.g., scalar quantization, product quantization, asymmetric quantization) lets you compress vectors to reduce RAM and disk costs while maintaining acceptable retrieval quality.
- Sharding and distributed systems let you horizontally scale and provide redundancy; partitioning strategy (range, hash, or vector-clustering-based) affects load balancing and query fan-out.
- Filtering and hybrid queries let you combine classical database predicates with vector similarity to support richer application logic and better precision.
- CRUD and index maintenance describe how to safely add, change, or remove vectors without expensive full-index rebuilds — techniques include lazy deletion, background merges, and incarnation/versioning.
- Latency vs. accuracy: Tighter approximate search parameters yield higher recall at the cost of latency and CPU.
- Memory vs. cost: Quantization and offline compression reduce memory but can reduce recall; choose compression level by SLA and budget.
- Consistency vs. availability: Online updates and deletes introduce complexity — strategies like lazy deletion or eventually consistent replicas trade immediacy for throughput.
- Operational complexity: Sharded, replicated systems require monitoring, rebalancing, and careful rollout of index rebuilds.
Design choices (index type, quantization level, shard strategy) drive production behavior. Test with representative workloads (size, query rate, and distribution) before committing to a configuration.
- HNSW overview and implementation notes: https://arxiv.org/abs/1603.09320
- Product quantization and compression techniques: https://hal.inria.fr/inria-00514401/document
- Vector search best practices and scaling: Kubernetes for scalable vector services and vector DB vendor docs