

Open-source typically means you self-host and operate the software (you control the code, configuration, and upgrades). Managed/cloud services reduce operational overhead but often incur ongoing costs. Commercial vendors may offer both open-source and managed variants—always check licensing, feature sets, and hosting options when comparing projects.
Categories at a glance
Vector databases commonly fall into three categories: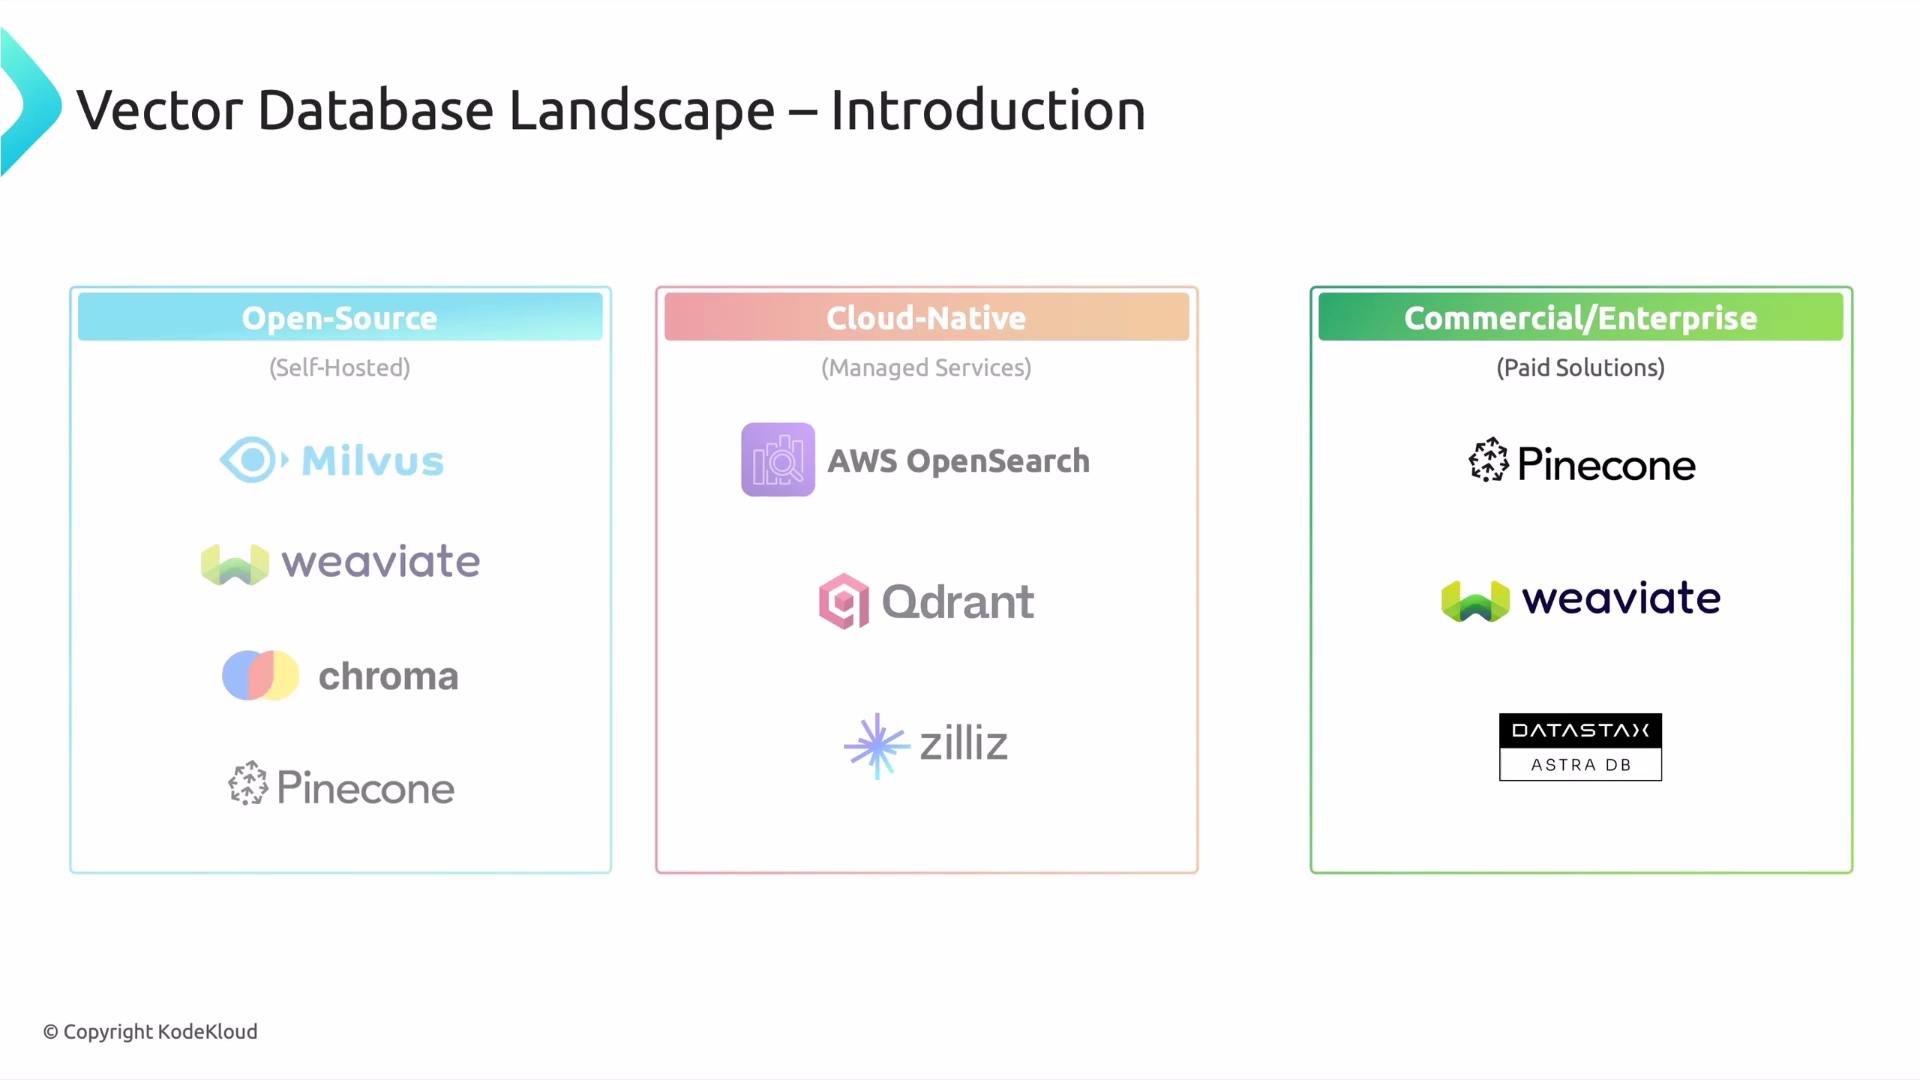
Detailed category notes
-
Open-source / self-hosted
- Description: You deploy and operate the database yourself (on-prem or in your cloud account). You can modify source code and tune infrastructure to fit requirements.
- When to choose: You need full control, strict compliance, custom features or on-prem deployments.
- Trade-offs: Requires dedicated DevOps effort for scaling, backups, monitoring, and upgrades.
-
Cloud-managed / cloud-native
- Description: A vendor/cloud provider operates the service; you interact via APIs/SDKs.
- When to choose: You want to minimize operational overhead and focus on application logic.
- Trade-offs: You trade some control for convenience and pay recurring costs.
-
Commercial / enterprise (SaaS)
- Description: Turnkey vector search with enterprise SLAs, advanced tooling, and support.
- When to choose: You need rapid production deployment with guaranteed support, security, and compliance.
- Trade-offs: Price and long-term vendor dependency.
Some projects appear in multiple categories (open-source core + managed/enterprise offerings). When evaluating, verify the licensing, hosted options, and feature parity between open-source and paid versions to avoid unexpected limitations.
A few important clarifications
- Projects often span categories:
- Milvus is an open-source project (maintained by Zilliz) and also available as a managed/enterprise offering.
- Weaviate and Qdrant provide both open-source software and managed cloud services.
- Pinecone is primarily a commercial SaaS vector database (managed service) rather than an open-source project.
- Compare vendors on technical features and operational guarantees. Important dimensions include:
- Indexing algorithms (e.g., HNSW, IVF, PQ)
- Distance metrics supported (cosine, dot-product, L2)
- Metadata filtering and query capabilities
- Hybrid search (dense vectors + sparse retrieval)
- Vector compression/quantization approaches
- Throughput, latency, and scalability (sharding/replication)
- Durability, backups, and recovery semantics
- SDKs, language support, and ecosystem connectors
- Pricing model, SLAs, compliance, and enterprise support
Key decision factors
When choosing a vector database, prioritize the items below based on your product and operational requirements:Recommended evaluation checklist
- Run a small proof-of-concept with realistic data volumes and query patterns.
- Measure latency and recall for your indexed data and query types.
- Validate metadata filtering and complex query behavior.
- Test scaling behavior (index building, rebalancing, replica handling).
- Verify backup/restore workflows and failover behavior.
- Audit security, access controls, and compliance features.
Further reading & references
- Milvus documentation
- Chroma
- Qdrant documentation
- Weaviate documentation
- Pinecone
- AWS OpenSearch Service