

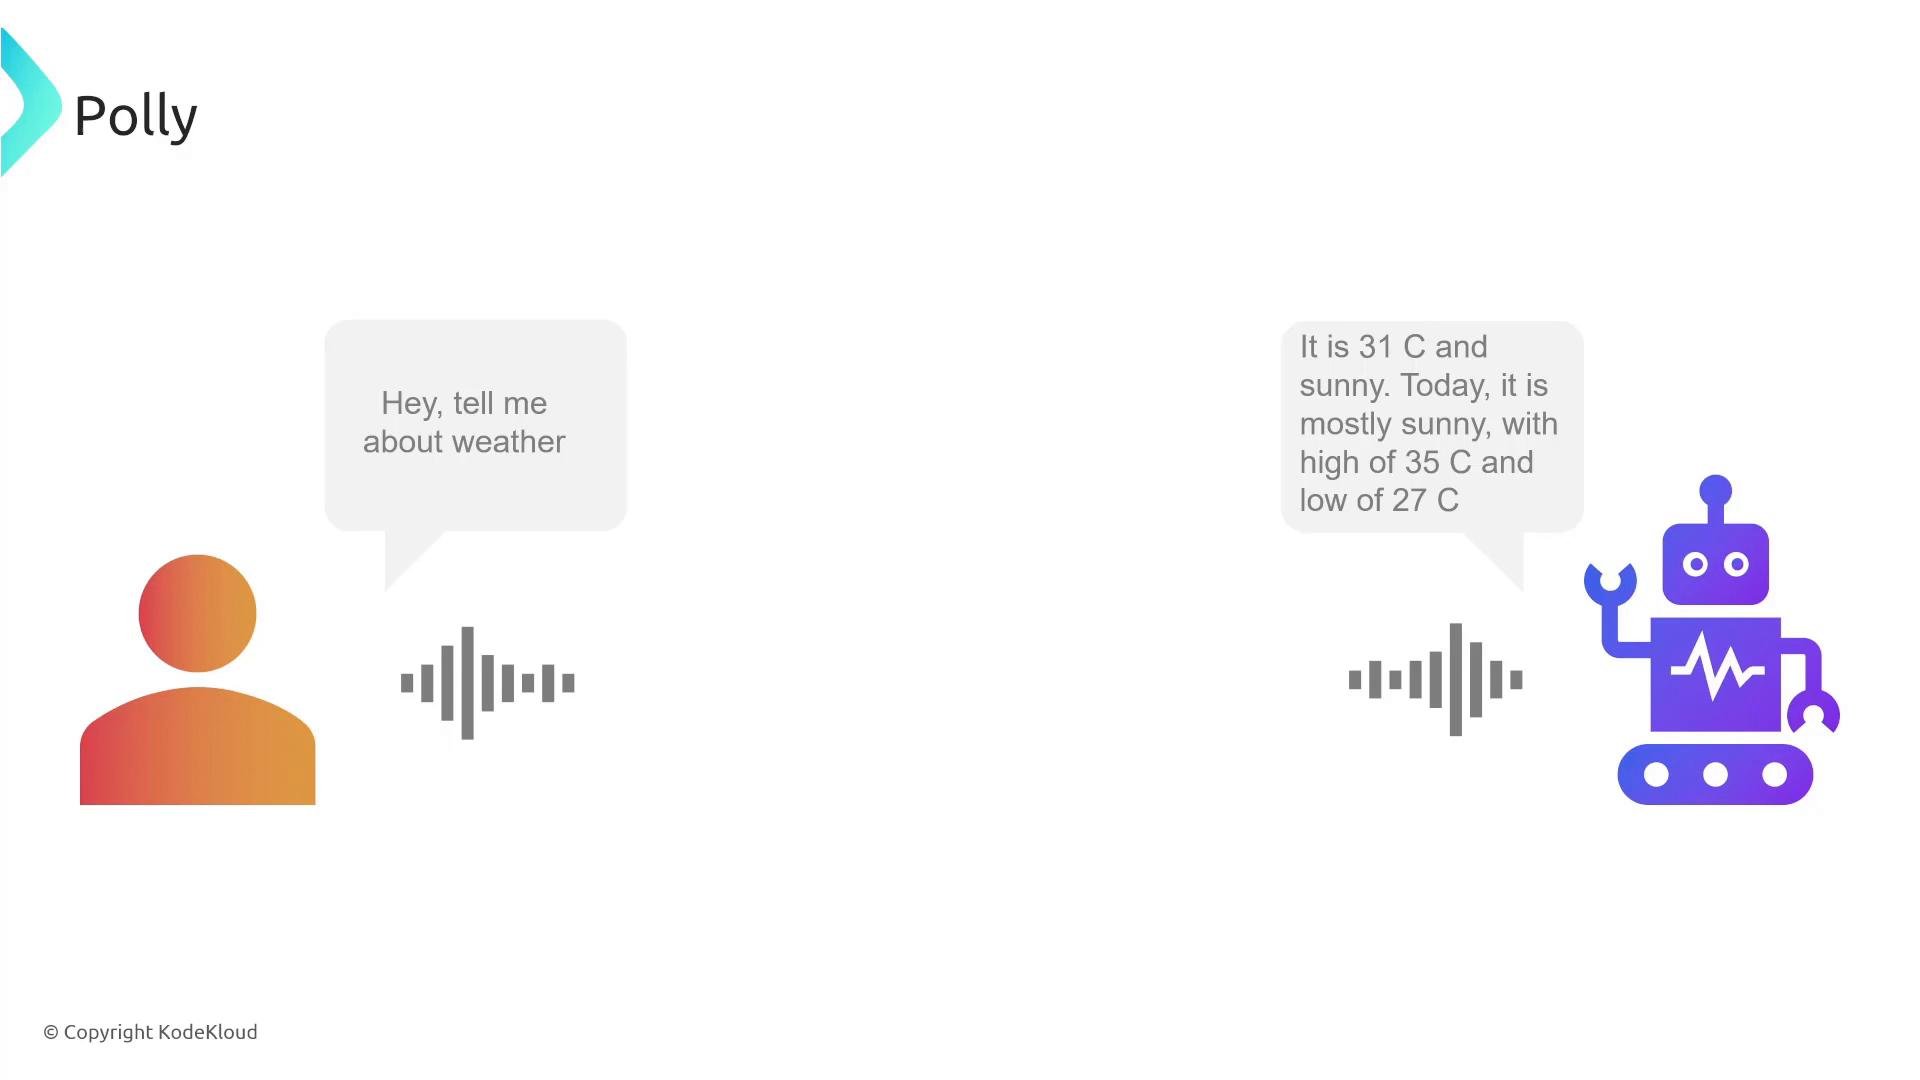
How Amazon Polly works — high level
- Input: plain text or SSML-enhanced text.
- Polly synthesizes the text using managed models (including neural voices) and returns audio output.
- Output can be streamed in real time to a client or written as an audio file (MP3, OGG, PCM) to persistent storage such as S3.
- Text-to-speech with multiple voices, including neural voices for more natural prosody.
- Real-time streaming and file generation (store results to Amazon S3).
- SSML support to control pronunciation, pauses, pitch, and speaking rate.
- Custom lexicons for domain-specific pronunciations.
- Seamless integration with AWS Lambda, S3, IoT Core, Transcribe, and other services.
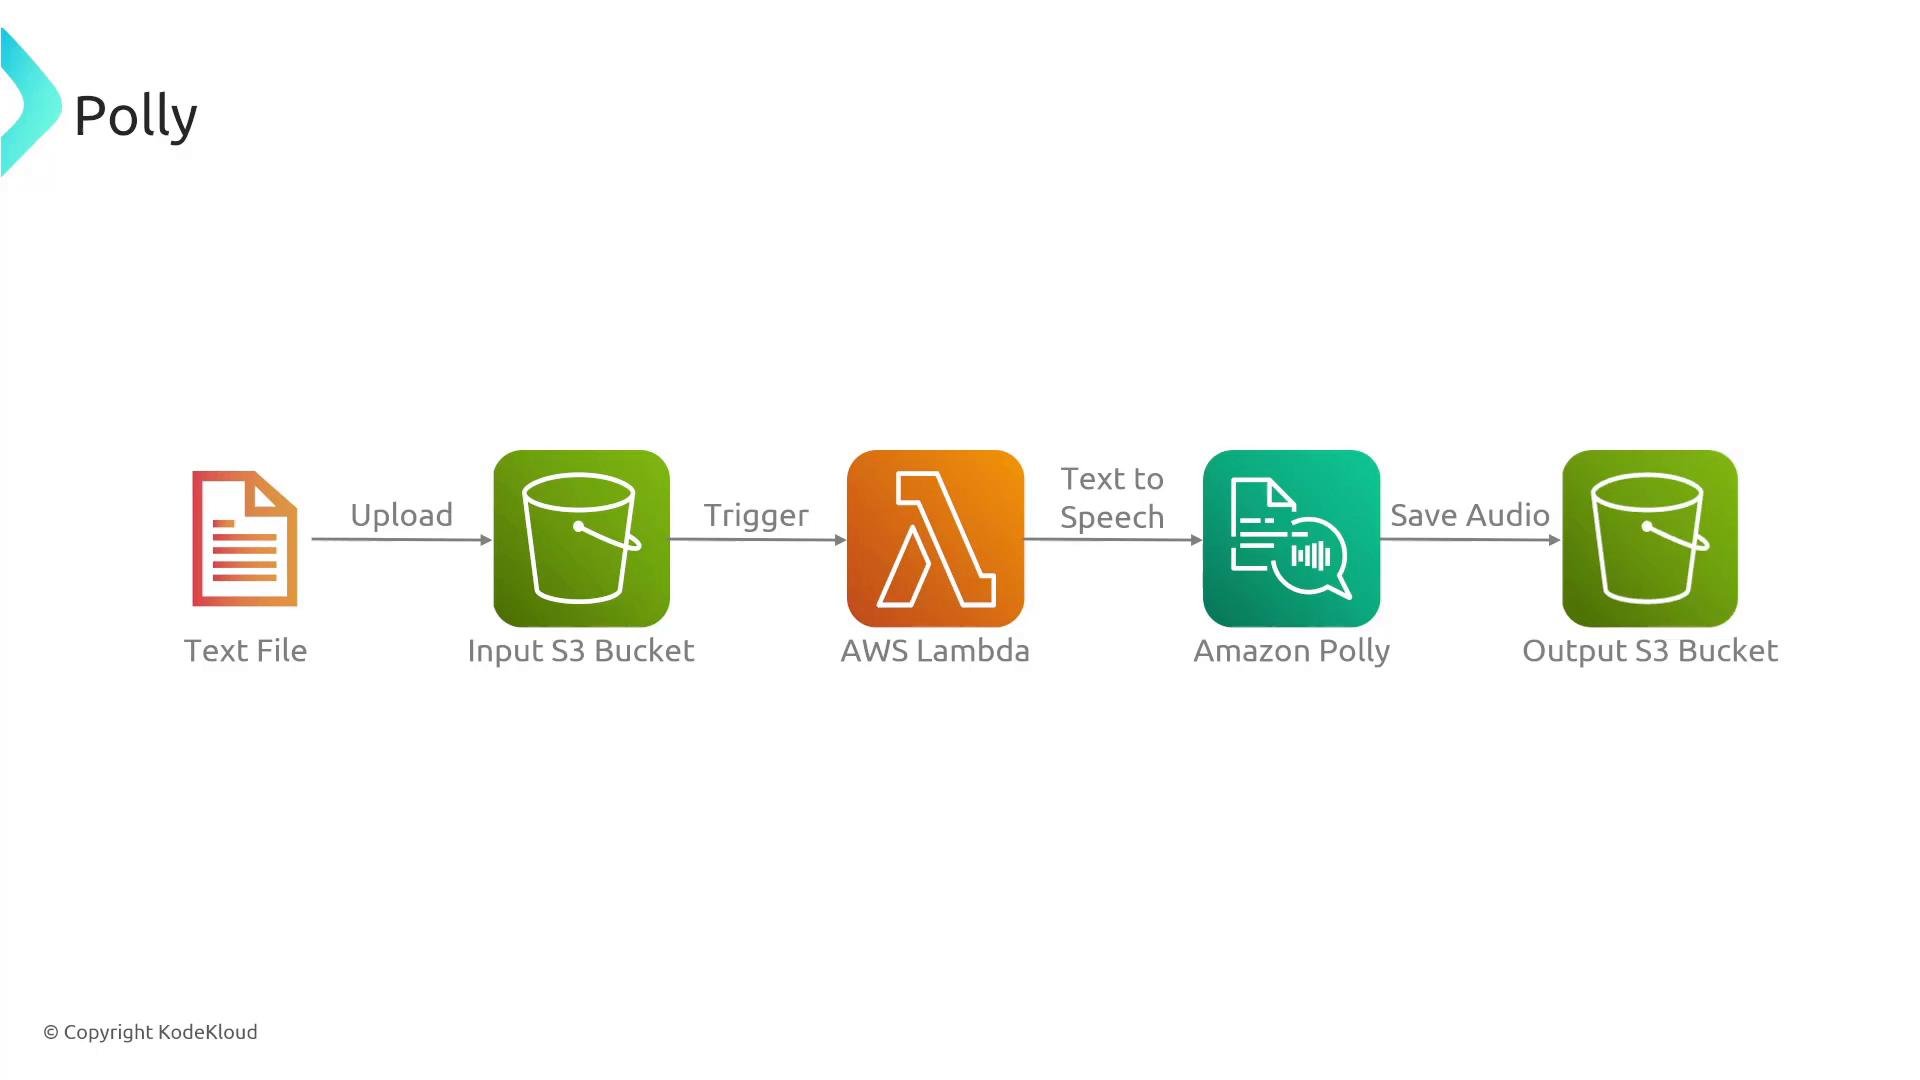
Typical S3 + Lambda + Polly architecture
A common, production-friendly pattern is:- Upload an input text file or transcript to an input S3 bucket.
- S3 event notifications trigger an AWS Lambda function.
- The Lambda function calls Polly to synthesize speech.
- Lambda writes the generated audio to an output S3 bucket for playback or distribution.
Voice-enabled devices: Transcribe + Lambda + IoT + Polly
For voice-driven devices (smart speakers, thermostats, IVR), Polly typically pairs with Amazon Transcribe. A common conversational workflow:- User speaks to the device.
- Amazon Transcribe performs speech-to-text.
- An AWS Lambda function interprets the text and interacts with device control (for example via AWS IoT Core / MQTT).
- The system composes a textual response (e.g., “The temperature is now set to 22°C”).
- Amazon Polly converts that text response to spoken audio and returns/stores the audio for playback.
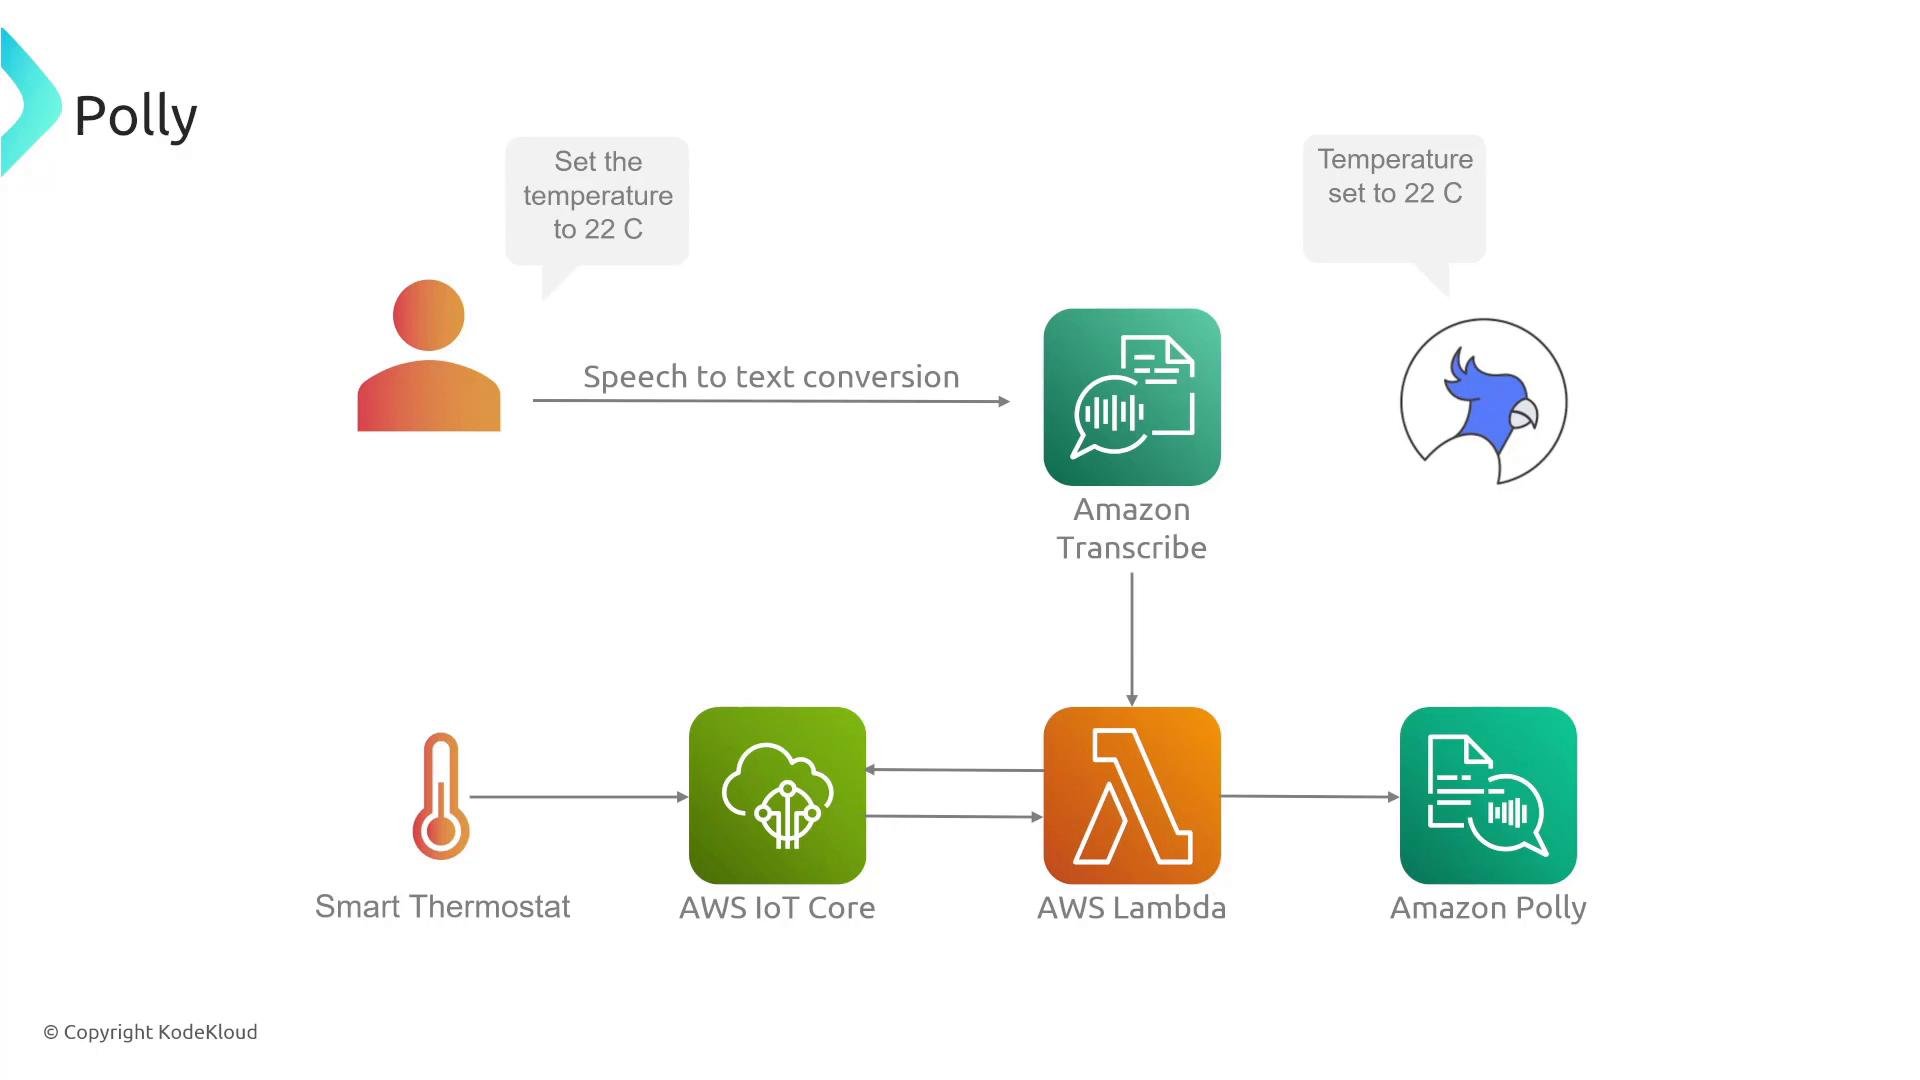
Remember: Amazon Transcribe = voice-to-text. Amazon Polly = text-to-voice. Use both when you need conversational voice interactions that require understanding and spoken responses.
Key features and configuration
Quick examples
AWS CLI — synthesize a short phrase and save as MP3:When to use Amazon Polly
- Interactive voice assistants and chatbots that require spoken responses.
- IVR and telephony systems where synthesized prompts and responses are needed.
- Bulk generation of audio content such as podcasts, audiobooks, or announcements.
- Devices or applications requiring low-latency streaming speech output.
- Scenarios needing precise control over pronunciation using SSML or lexicons.
Example decision table: Polly vs Transcribe
Integration patterns and best practices
- Use S3 + Lambda as a durable, event-driven pipeline for TTS generation.
- Prefer neural voices when naturalness is important — test cost vs quality.
- Use SSML and custom lexicons to improve pronunciation for domain-specific words.
- For interactive devices, stream audio from Polly to minimize end-to-end latency.
- Secure access with IAM roles and apply least privilege for Lambda and S3 actions.
Links and references
- Amazon Polly product page: https://aws.amazon.com/polly/
- SSML reference: https://docs.aws.amazon.com/polly/latest/dg/ssml.html
- Managing lexicons: https://docs.aws.amazon.com/polly/latest/dg/managing-lexicons.html
- AWS Lambda: https://learn.kodekloud.com/user/courses/aws-lambda
- Amazon S3: https://learn.kodekloud.com/user/courses/amazon-simple-storage-service-amazon-s3
- Amazon Transcribe: https://aws.amazon.com/transcribe/
- AWS IoT Core: https://aws.amazon.com/iot-core/