Why this service exists
Maintaining a traditional disaster recovery (DR) site is costly and operationally complex. Typical on‑premises DR requires:- Paying for idle infrastructure that must remain available to run production workloads at any time.
- Ongoing maintenance to ensure the recovery site mirrors the primary site (OS/patching, application configuration, networking).
- Skilled staff to manage, test, and validate the DR environment, plus possible additional colocation or data center contracts.
What AWS Elastic Disaster Recovery provides
AWS Elastic Disaster Recovery (AWS DRS) minimizes downtime and data loss by offering:- Continuous, near real‑time block‑level replication with point‑in‑time recovery.
- Automated recovery drills that validate recoverability without impacting production.
- Fast launch of recovery instances within minutes.
- Simple failback to your primary environment once it’s restored.
Core components and how they work
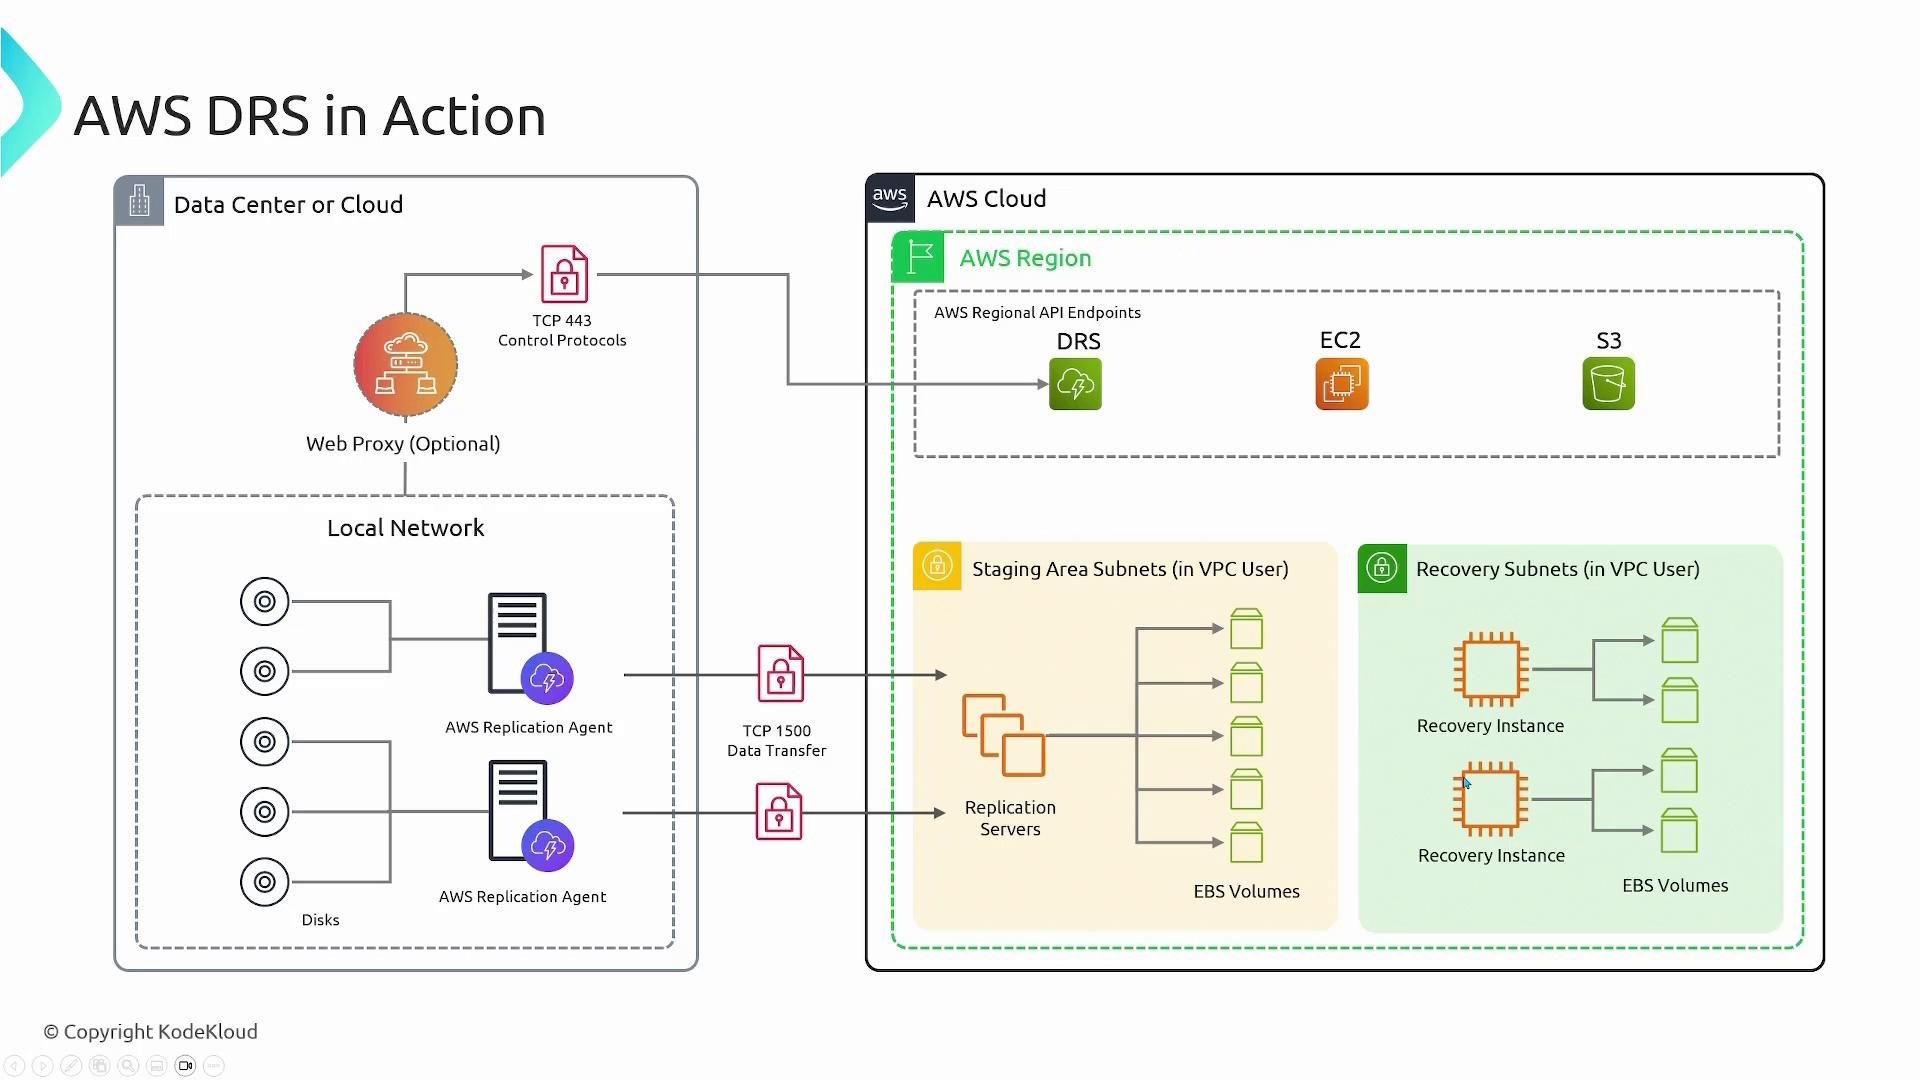
At a high level, AWS DRS relies on three component groups that work together to protect source systems and enable recovery:Step‑by‑step replication and recovery flow
- Install the AWS Replication Agent on each source server and select the disks to protect.
- Each agent registers with the AWS DRS service endpoint and streams block changes to replication servers running in the staging subnet.
- Replication servers ingest the data and persist it to corresponding Amazon EBS volumes; the service maintains near real‑time synchronization.
- For recovery, AWS creates point‑in‑time snapshots from the staging EBS volumes and launches EC2 recovery instances in the recovery subnet (test or failover).
- Recovery instances boot from these snapshots, giving access to the latest replicated data and allowing application startup and verification.
- After primary systems are recovered, you can perform a failback to the original environment.
Key features and benefits
- Continuous block‑level replication for low RPO (Recovery Point Objective).
- Point‑in‑time recovery and snapshot-based boot for accurate restoration.
- Automated, non‑disruptive disaster recovery drills to prove recovery readiness.
- Rapid failover and recovery instance launch to minimize RTO (Recovery Time Objective).
- Simplified failback workflows once primary systems are restored.
When you prepare an Elastic Disaster Recovery plan, include regular DR drills. These validate not only replication health but also networking, IAM, and application startup behavior in the recovery environment.
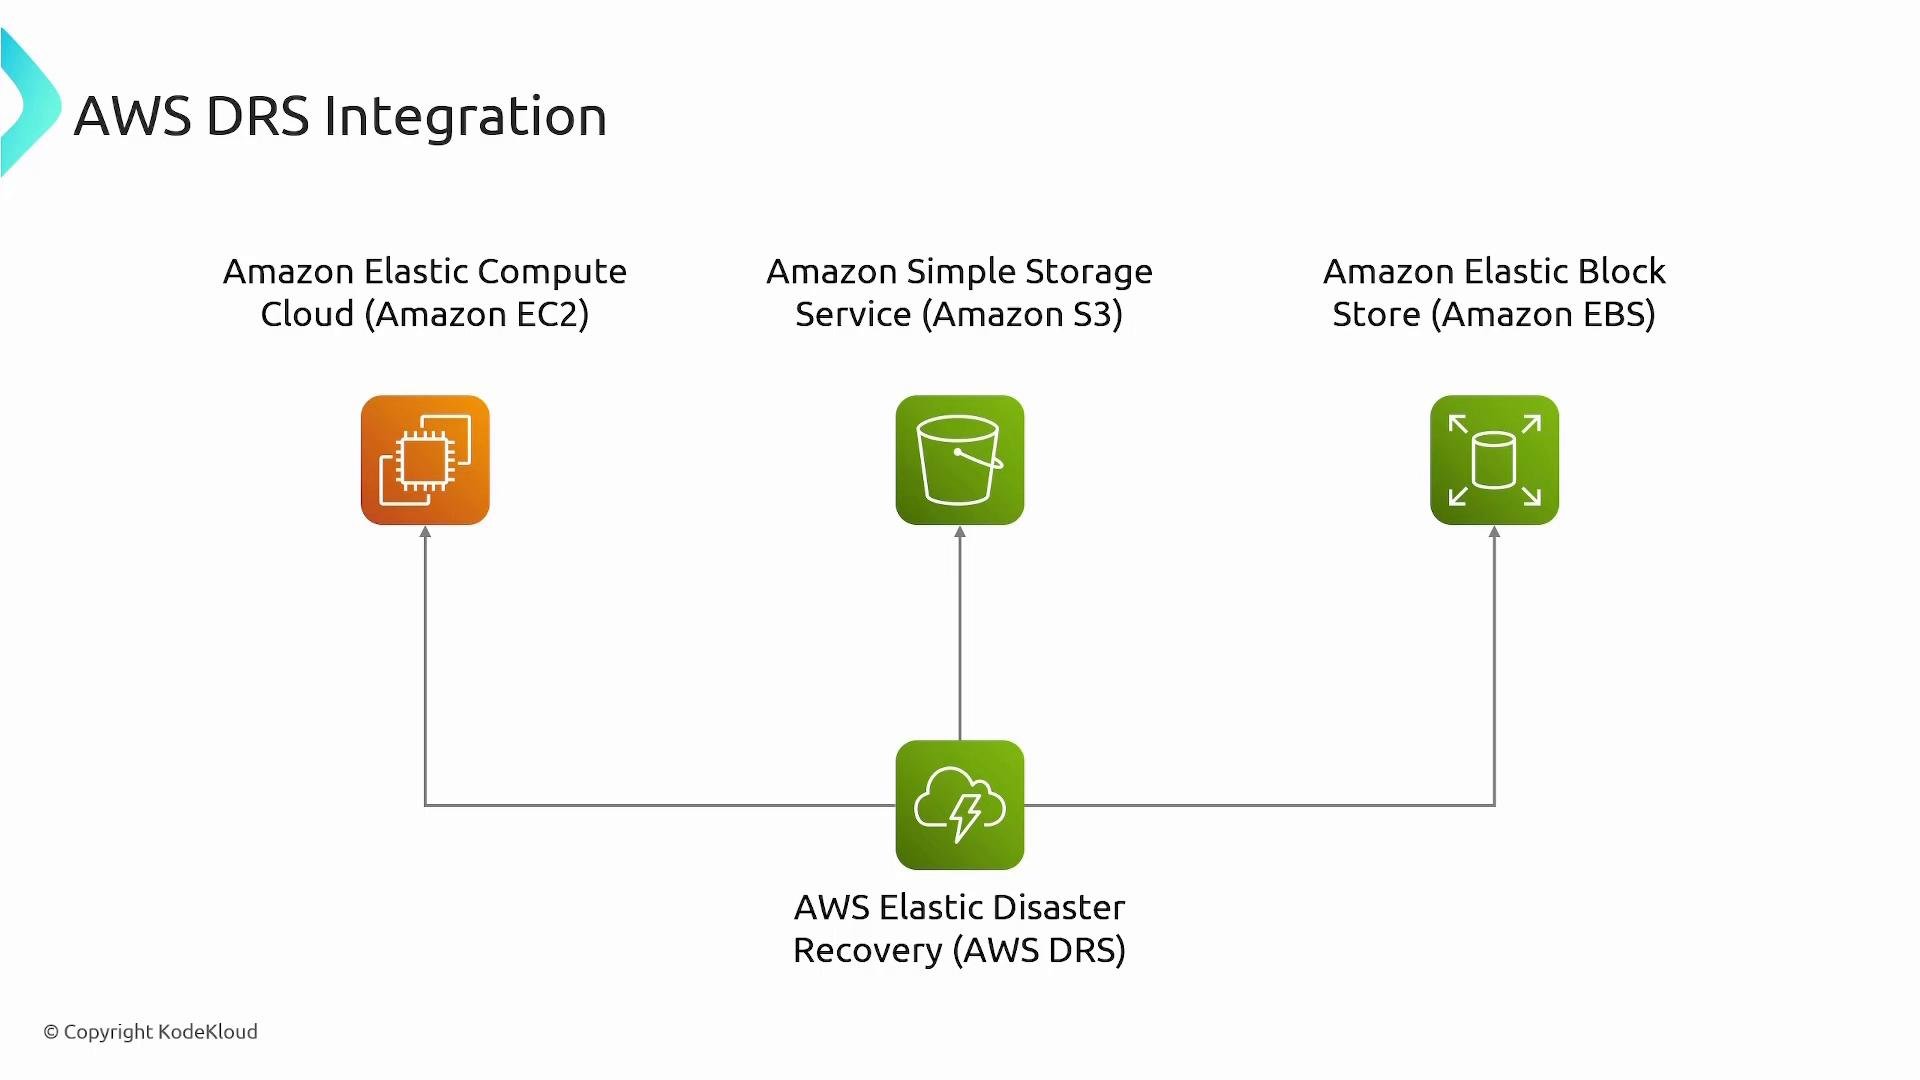
Integration with AWS services
Elastic Disaster Recovery integrates tightly with several core AWS services to provide a complete DR solution:Common use cases
- Rapid recovery for on‑premises applications after software failures, configuration errors, or hardware outages.
- Cross‑cloud or cross‑region failover for workloads running in other clouds or remote datacenters.
- Cost‑effective cloud‑based DR that can be used for tests, audits, or temporary production during migrations.
Summary
AWS Elastic Disaster Recovery reduces the operational overhead and expense of maintaining a traditional DR site by using AWS as the recovery target. With continuous replication, point‑in‑time recovery, automated testing, and fast instance launch, organizations can minimize downtime and data loss while simplifying DR operations. Links and references- AWS Elastic Disaster Recovery documentation: https://aws.amazon.com/drs/
- AWS Disaster Recovery best practices: https://aws.amazon.com/architecture/disaster-recovery/