

- Create a Kinesis Data Stream.
- Create a Kinesis Data Firehose delivery stream that uses the Kinesis stream as its source.
- Configure S3 as the Firehose destination (create a bucket if needed).
- Produce test records into the Kinesis stream using the AWS SDK for JavaScript (v3).
Architecture overview
1) Create the Kinesis Data Stream
When creating a data stream you must choose a capacity mode:- Provisioned — choose explicit shard count when you want fine-grained throughput control and cost predictability.
- On-demand — automatic scaling with no shard management; simpler but can be more expensive for high sustained throughput.
If you expect variable traffic and want minimal operational overhead, start with on-demand. If you need predictable cost and throughput guarantees for steady heavy workloads, choose provisioned and set shards accordingly.
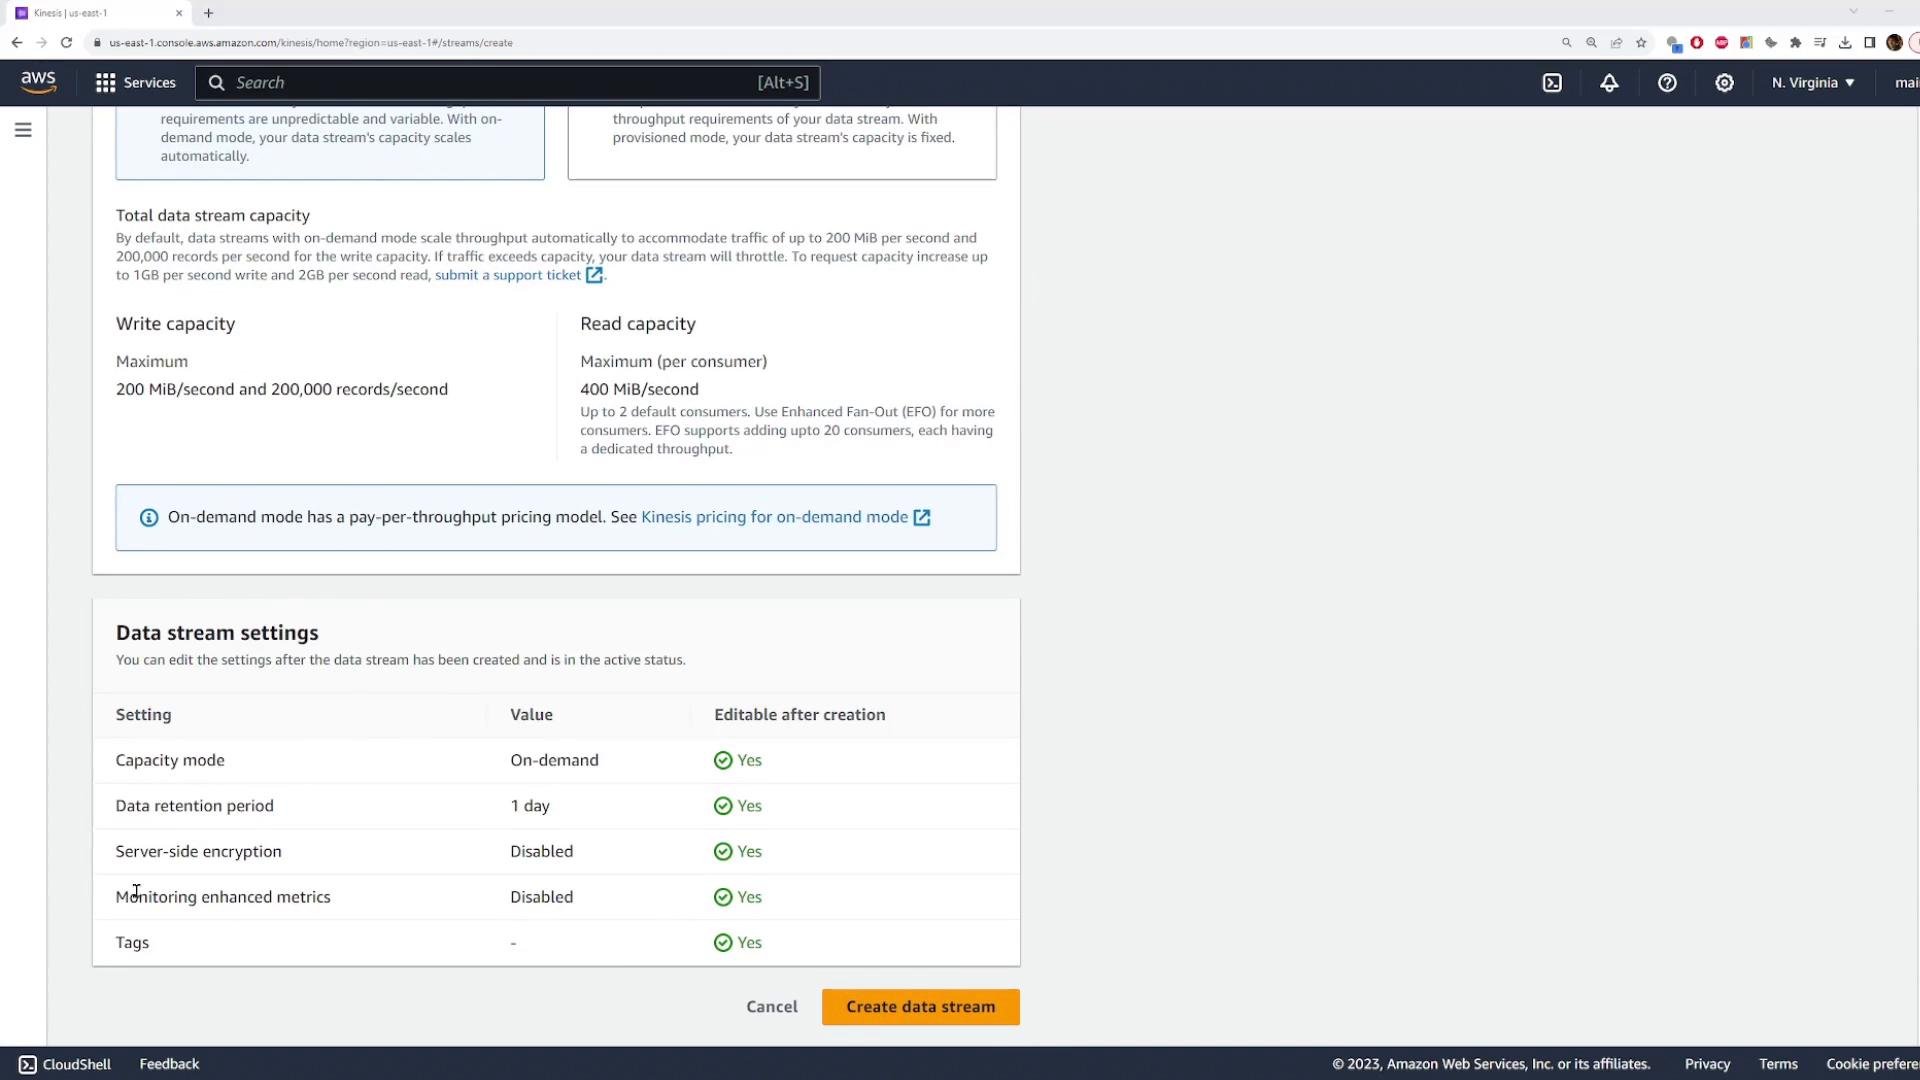
crypto-stock-price.
2) Create the Firehose delivery stream and choose S3 as destination
- In the Firehose creation workflow, choose Kinesis Data Stream as the source and select the stream you created.
- Choose S3 as the destination. Either pick an existing bucket or create a new one during the delivery stream setup.
- Optionally enable buffering, compression, or format conversion (JSON → Parquet/ORC). For this demo we forward raw JSON into S3.
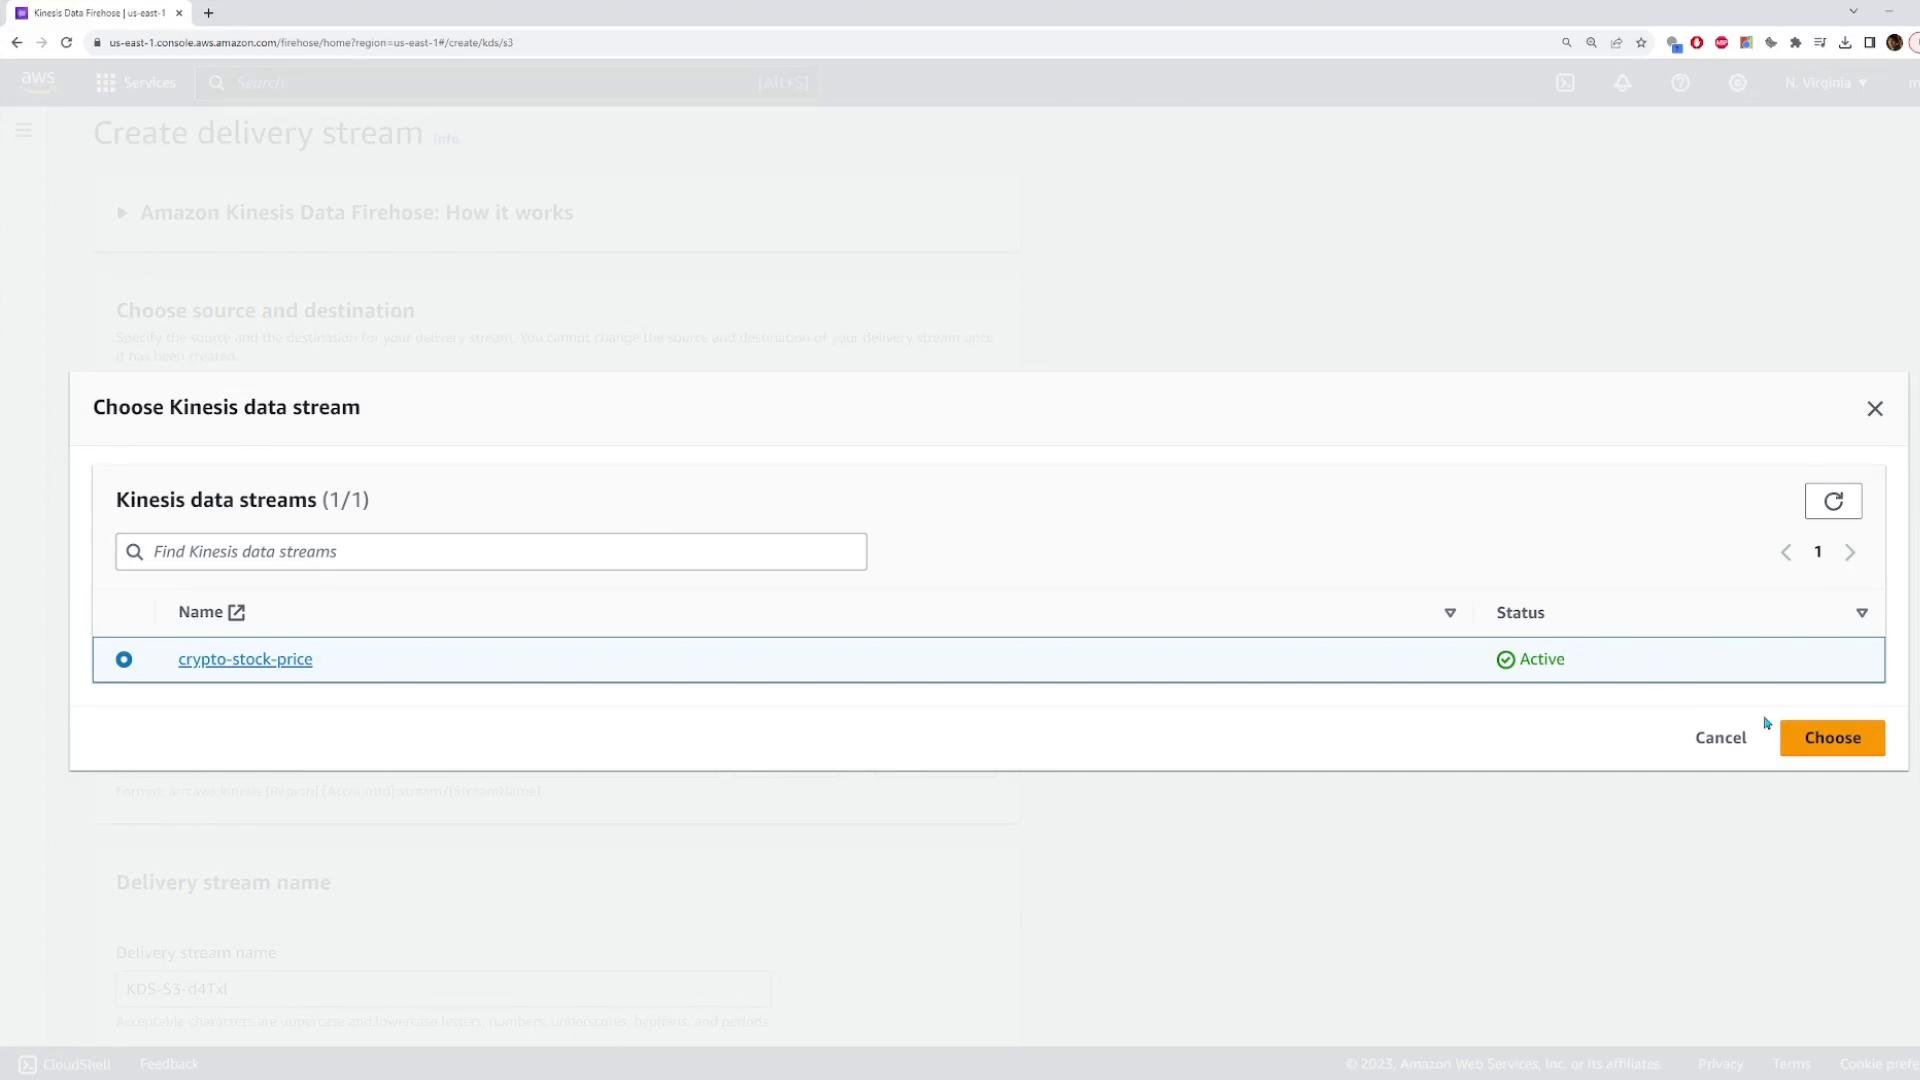
- Buffering settings (size and interval) control how frequently Firehose writes objects to S3. Smaller intervals yield more objects; larger intervals reduce PUT count but increase object size.
- Leaving transformation/format conversion disabled will deliver raw payloads as-is.
3) Confirm S3 delivery and inspect the results
After Firehose becomes active and starts consuming from the Kinesis stream, it will buffer records and periodically write objects to the configured S3 bucket using the prefix and partition scheme you configured. Objects are usually organized by year/month/day/hour in the S3 console.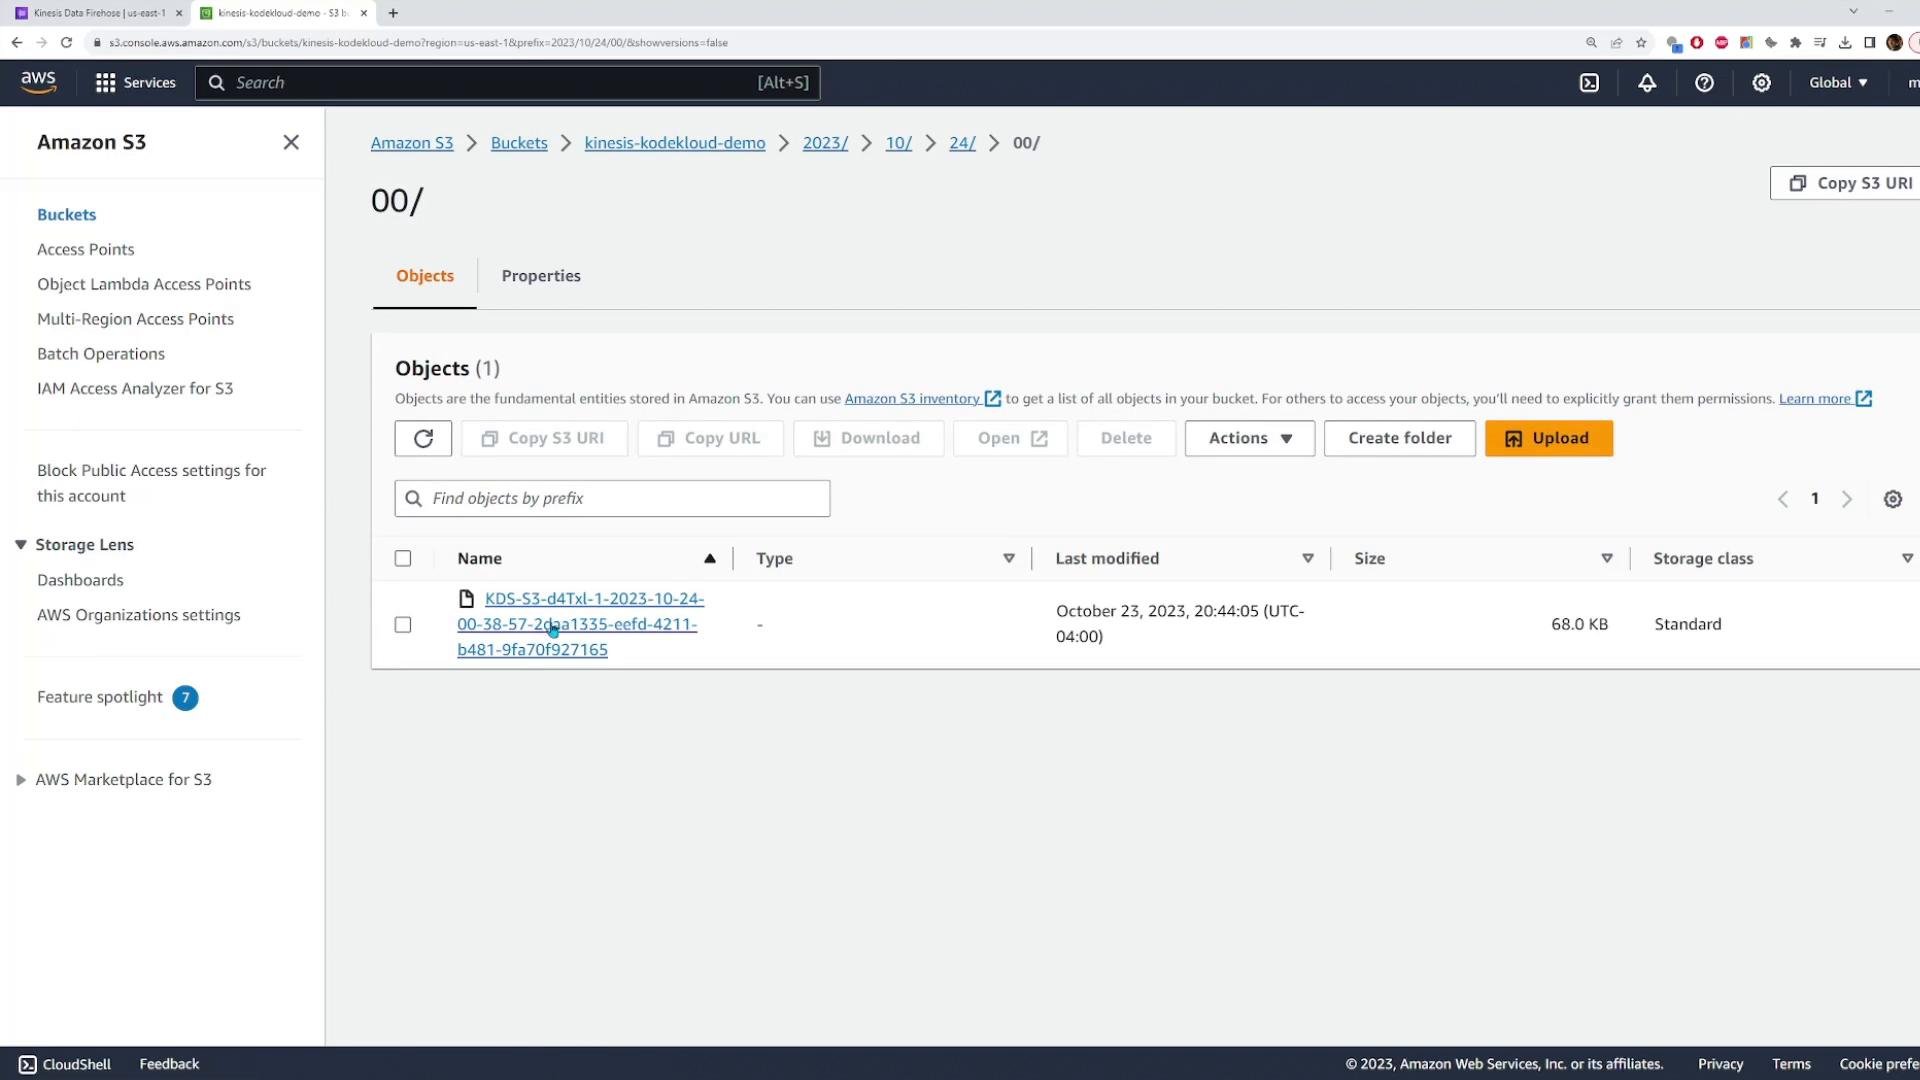
4) Produce test records using AWS SDK for JavaScript (v3)
Prerequisites:- Node.js (v14+ recommended)
- AWS credentials configured (environment variables, shared credentials file, or AWS CLI setup)
- Install the Kinesis client:
npm install @aws-sdk/client-kinesis
"type": "module" in package.json) or convert imports to CommonJS require calls.
Example producer script:
Running a high-frequency producer continuously can generate costs (Kinesis Data Streams, Firehose, S3 PUTs, and storage). Stop the producer when you’re done testing.
Optional: Data transformation and format conversion
If you want to transform or enrich records before they reach S3:- Enable Firehose data transformation and provide a Lambda function to process each batch.
- Enable format conversion to convert newline-delimited JSON to Parquet/ORC — this improves query performance and reduces storage for analytic workloads.
Troubleshooting checklist
- Are AWS credentials and region configured? Use
aws sts get-caller-identityto verify. - Is the Firehose delivery stream in an Active state?
- Are IAM permissions correct for Firehose to write to your S3 bucket and for Kinesis to be used as a source?
- Check CloudWatch logs for Firehose or the transformation Lambda (if enabled).
Links and references
- AWS SDK for JavaScript (v3) — https://docs.aws.amazon.com/sdk-for-javascript/v3/developer-guide/welcome.html
- Kinesis Data Streams documentation — https://docs.aws.amazon.com/kinesis/index.html
- Kinesis Data Firehose documentation — https://docs.aws.amazon.com/firehose/index.html
- Amazon S3 documentation — https://docs.aws.amazon.com/s3/index.html