

Early foundations (1950s–1960s)
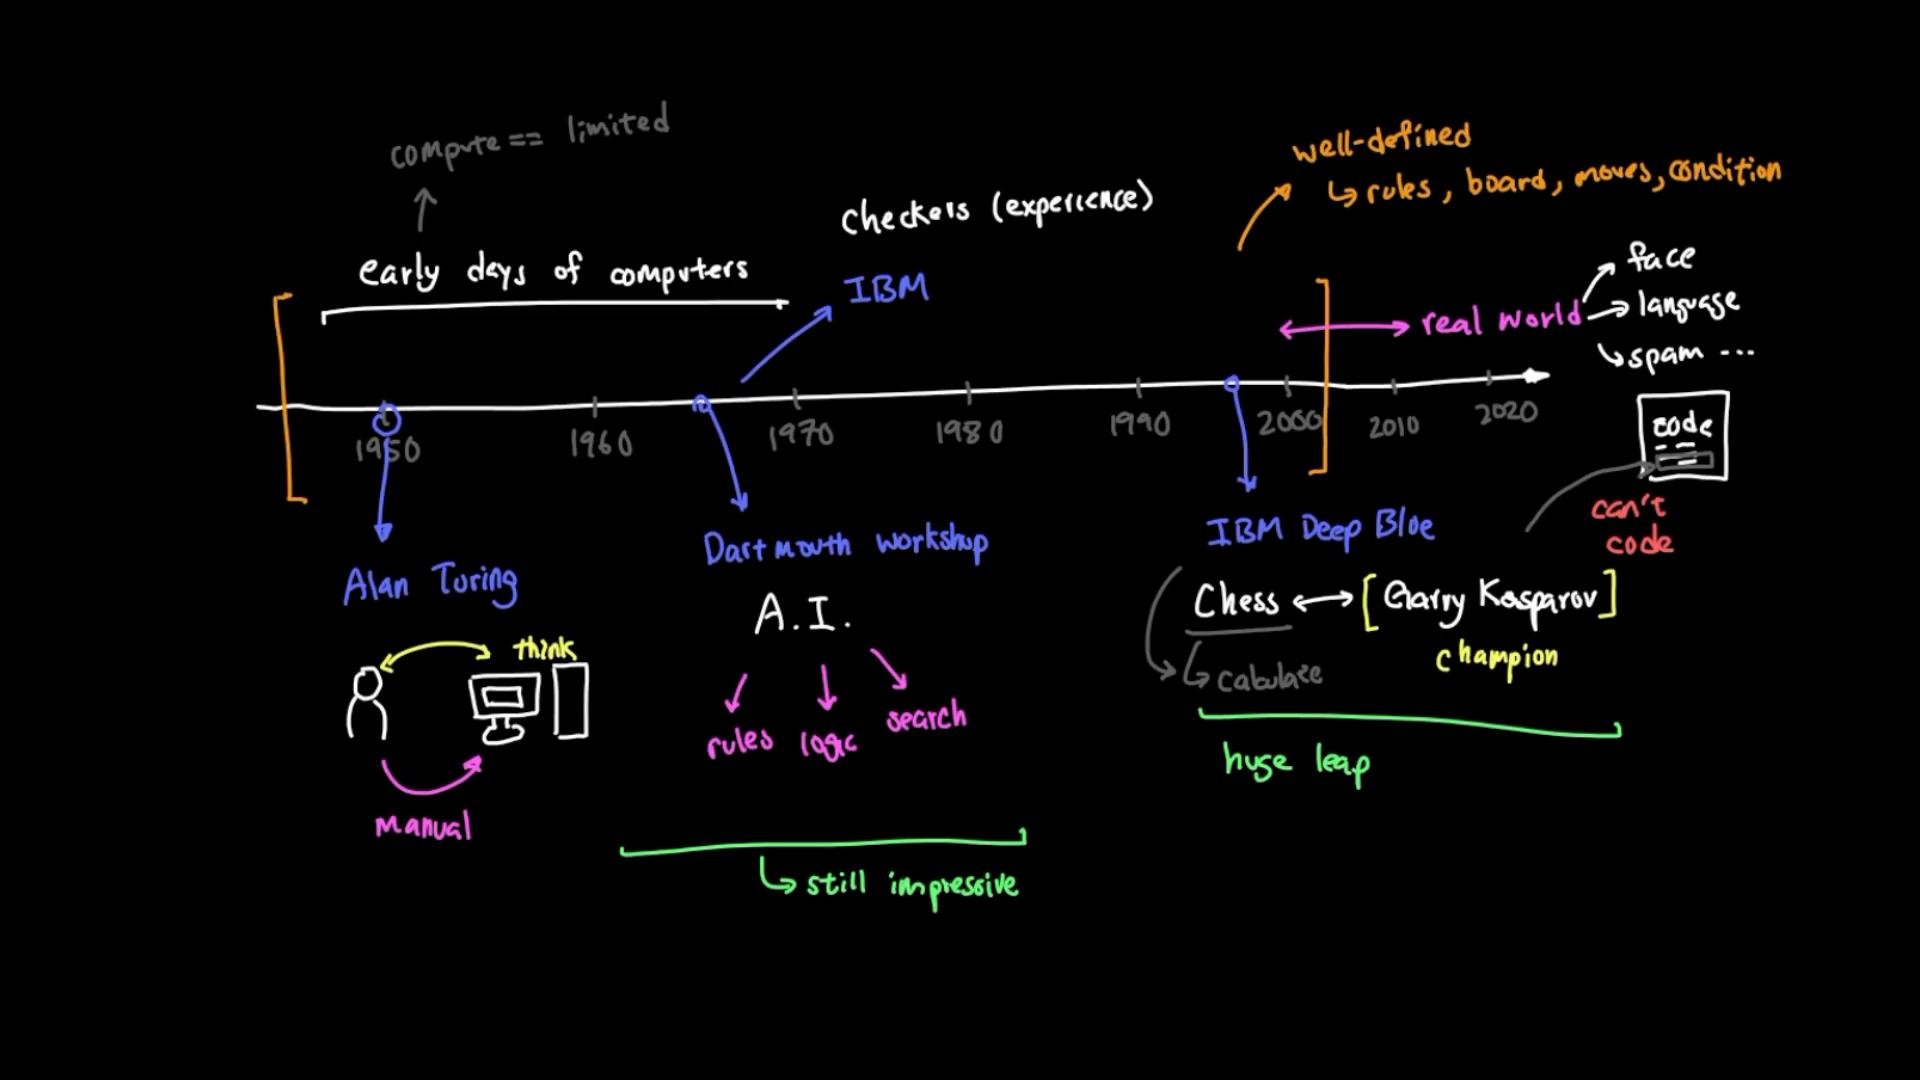
In 1950, Alan Turing posed the question of whether machines could imitate human intelligence. The 1956 Dartmouth workshop formalized artificial intelligence as a research field. Around the same era, Arthur Samuel at IBM developed a checkers-playing program capable of improving through experience — an early practical demonstration of learning from data. At the time, hardware and datasets were extremely limited, so many systems relied on rules, logic, and search. Researchers encoded intelligence manually:- If this condition, then do that.
- If the board looks like this, make this move.
- If the user asks X, return Y.
From rules to examples: the essence of machine learning
Instead of hard-coding every rule, machine learning systems use examples. We supply data and allow algorithms to discover patterns and relationships that generalize to new inputs. In short:- Traditional software = humans write rules.
- Machine learning = humans design systems that learn from examples.
Backpropagation and the practical training of networks
A key technical advance was the adoption of backpropagation in the 1980s. Backpropagation provides a practical algorithm to propagate errors backward through a network and update weights based on those errors.Backpropagation: the model predicts an output, measures the prediction error, and then adjusts internal weights to reduce that error next time. This made multilayer neural networks trainable in practice and enabled deeper architectures as compute and data improved.
Deep learning breakthrough: AlexNet and beyond (2012 onward)
The watershed moment came in 2012 when AlexNet dramatically outperformed previous methods on the ImageNet visual-recognition challenge by leveraging GPUs for training. That result proved that neural networks, when paired with big data and fast hardware, could scale to previously intractable vision tasks. After AlexNet, deep learning quickly advanced across many fields:- Computer vision (object detection, segmentation)
- Speech recognition and synthesis
- Machine translation and NLP
- Recommendation systems
- Reinforcement learning for games and robotics
The transformer era and modern large models
In 2017 the transformer architecture was introduced and changed the landscape of natural language processing. Transformers use attention mechanisms to model relationships across sequences efficiently, enabling much larger and more capable language models. These architectures are the backbone of modern large language models (LLMs) and many state-of-the-art systems across modalities.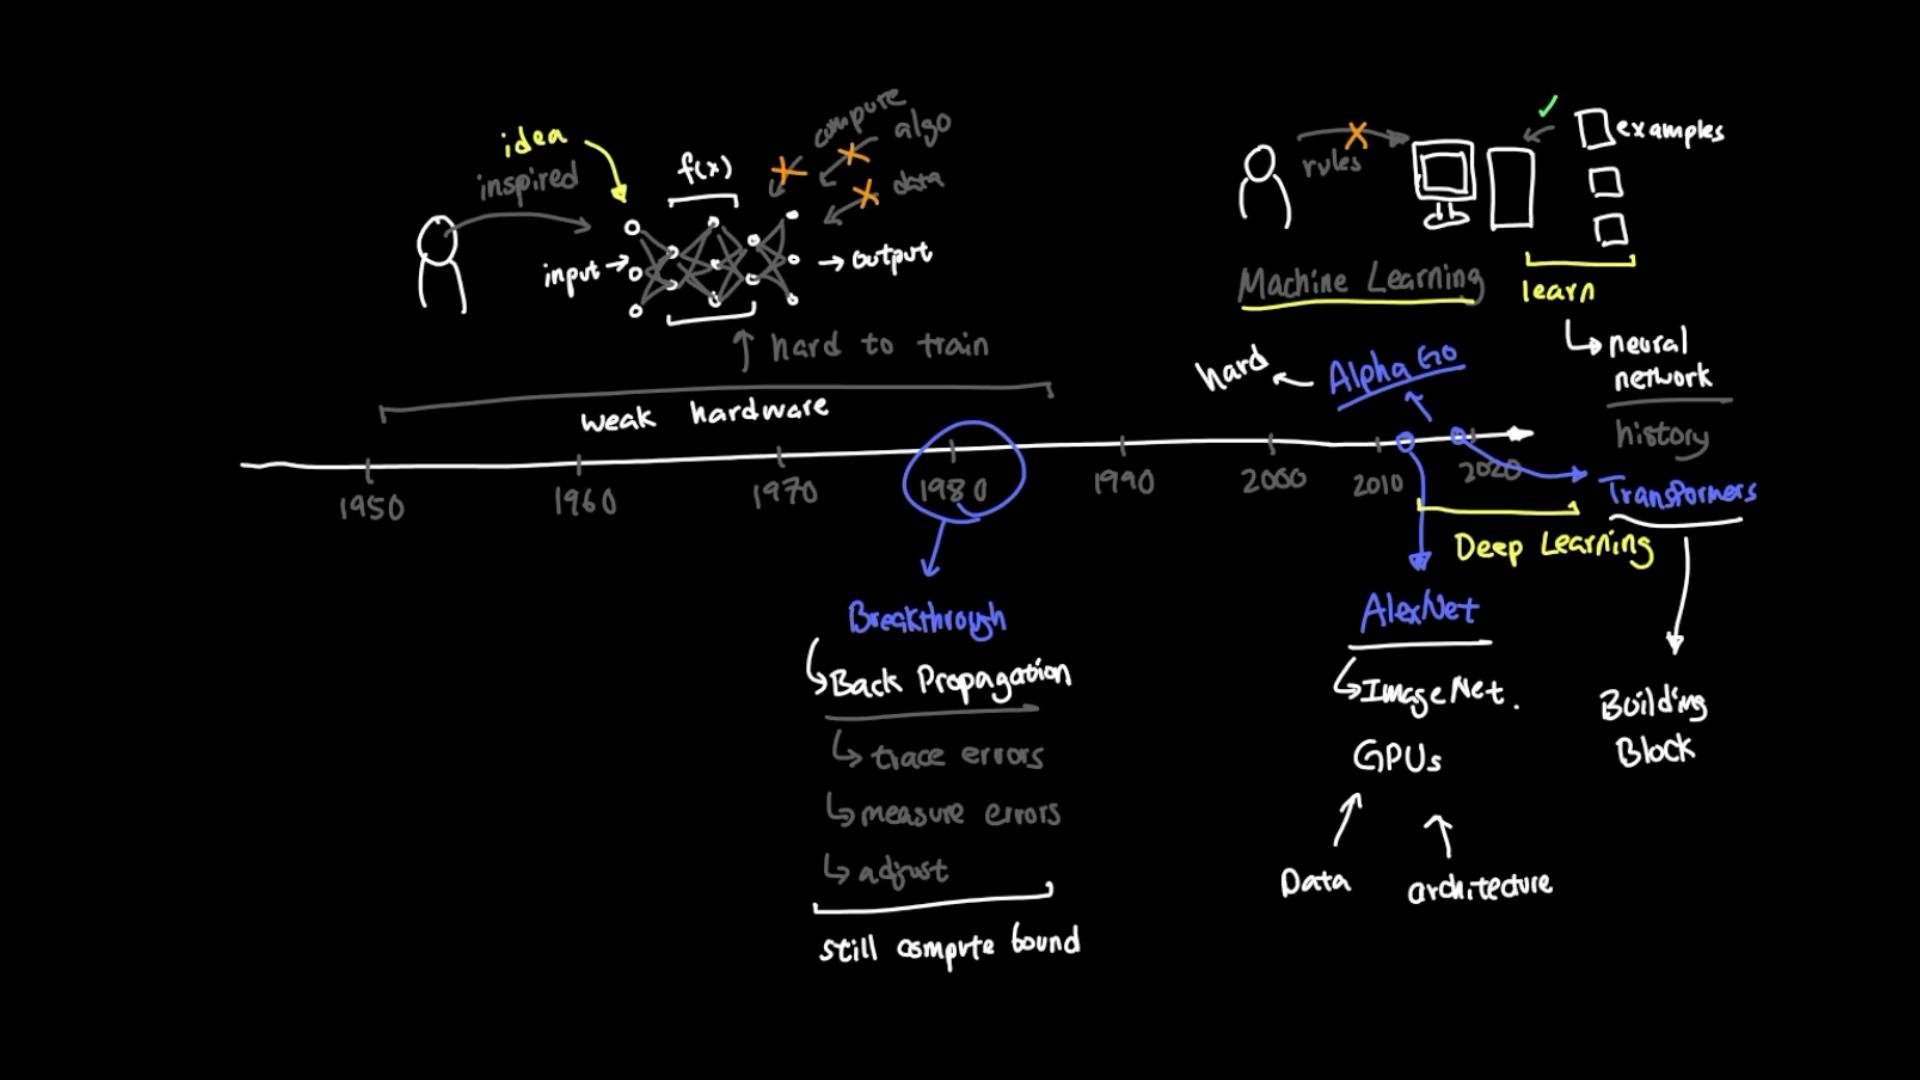
Timeline of major milestones
What it means for a system to “learn”
Learning, in practical terms, means using data to adjust parameters of a model so that the model generalizes well to new, unseen inputs. Designing learning algorithms involves choosing:- A model or architecture (e.g., neural networks, decision trees)
- A loss function that quantifies error
- An optimization algorithm to minimize that loss (e.g., SGD, Adam)
- Appropriate data and preprocessing
- Evaluation metrics and validation strategies
Further reading and references
- Alan Turing — Computing Machinery and Intelligence (1950)
- Dartmouth workshop (1956) — Wikipedia
- Arthur Samuel — Wikipedia
- Deep Blue — Wikipedia
- Backpropagation — Wikipedia
- AlexNet — Wikipedia
- ImageNet — Official site
- AlphaGo — Wikipedia
- Attention Is All You Need (Transformer paper)
If you want a concise takeaway: machine learning evolved from rule-based systems to data-driven models because real-world tasks are noisy and complex. Key enablers were algorithms (e.g., backpropagation), big datasets, and accelerating hardware (GPUs/TPUs), culminating in architectures like transformers that power today’s AI systems.