

Transformers: a change in sequence modeling
In 2017, researchers at Google introduced the Transformer architecture in the paper “Attention Is All You Need.” This work reshaped how models process sequences (like text) by replacing strictly sequential architectures with self-attention mechanisms that consider relationships across many tokens at once. Self-attention answers the question: which parts of the input should influence a given output token? For example, in the sentence “a dog chased a ball because it was excited,” attention helps the model link “it” with “dog.” More generally, attention enables models to capture long-range context efficiently and to parallelize computation across tokens — a key reason transformers scale well with data and compute.Transformers scale better than prior sequential models because self-attention lets the model relate any pair of tokens directly, enabling richer context modeling and parallel training across positions.
Multimodal AI: combining images, audio, text, and more
Historically, models focused on a single modality (text-only, image-only, or audio-only). Modern systems increasingly learn shared representations across multiple modalities, allowing them to understand and generate across data types. A prominent example is OpenAI’s CLIP, which learns a unified representation by training on large sets of image–caption pairs. Rather than learning a fixed set of image labels, CLIP aligns visual and textual concepts in the same embedding space, enabling robust zero-shot classification and flexible image–text retrieval. Generative multimodal models such as DALL·E demonstrated that models can synthesize images from text prompts — for example, producing “an astronaut riding a horse” from a natural-language description. These models show that multimodal training creates flexible mappings between modalities instead of rigid classifiers.Agents and tools: connecting models to actions
A language model alone predicts tokens. When you connect that model to external tools, it can do much more than return text: it can search the web, execute code, call APIs, inspect files, and control external software. These capabilities are the foundation of modern AI agents. An agent repeatedly:- Chooses an action (e.g., run a query, call an API, execute code),
- Uses available tools to perform the action,
- Observes the tool outputs,
- Updates its plan and repeats until it reaches the goal.
Agents extend model capabilities, but they do not guarantee perfect answers. Models can hallucinate, misunderstand instructions, or misuse tools. Always validate critical outputs and use verification (search, test-run code, or human review) for high-stakes tasks.
Why tools matter
Tools compensate for common model limitations:- Stale knowledge — use web search or knowledge bases for up-to-date facts.
- Exact computation — delegate arithmetic or heavy computation to dedicated code execution.
- Data access — read files or query databases instead of relying on memorized facts.
- Grounding and verification — test results or cross-check with external sources.
Quick comparison
Core continuity: learning from data
Underneath these innovations is the same foundation: models learn from data, behavior is defined by parameters, training updates those parameters, and evaluation measures usefulness. Scaling and system-level integration improved capabilities, but the core ML principles remain.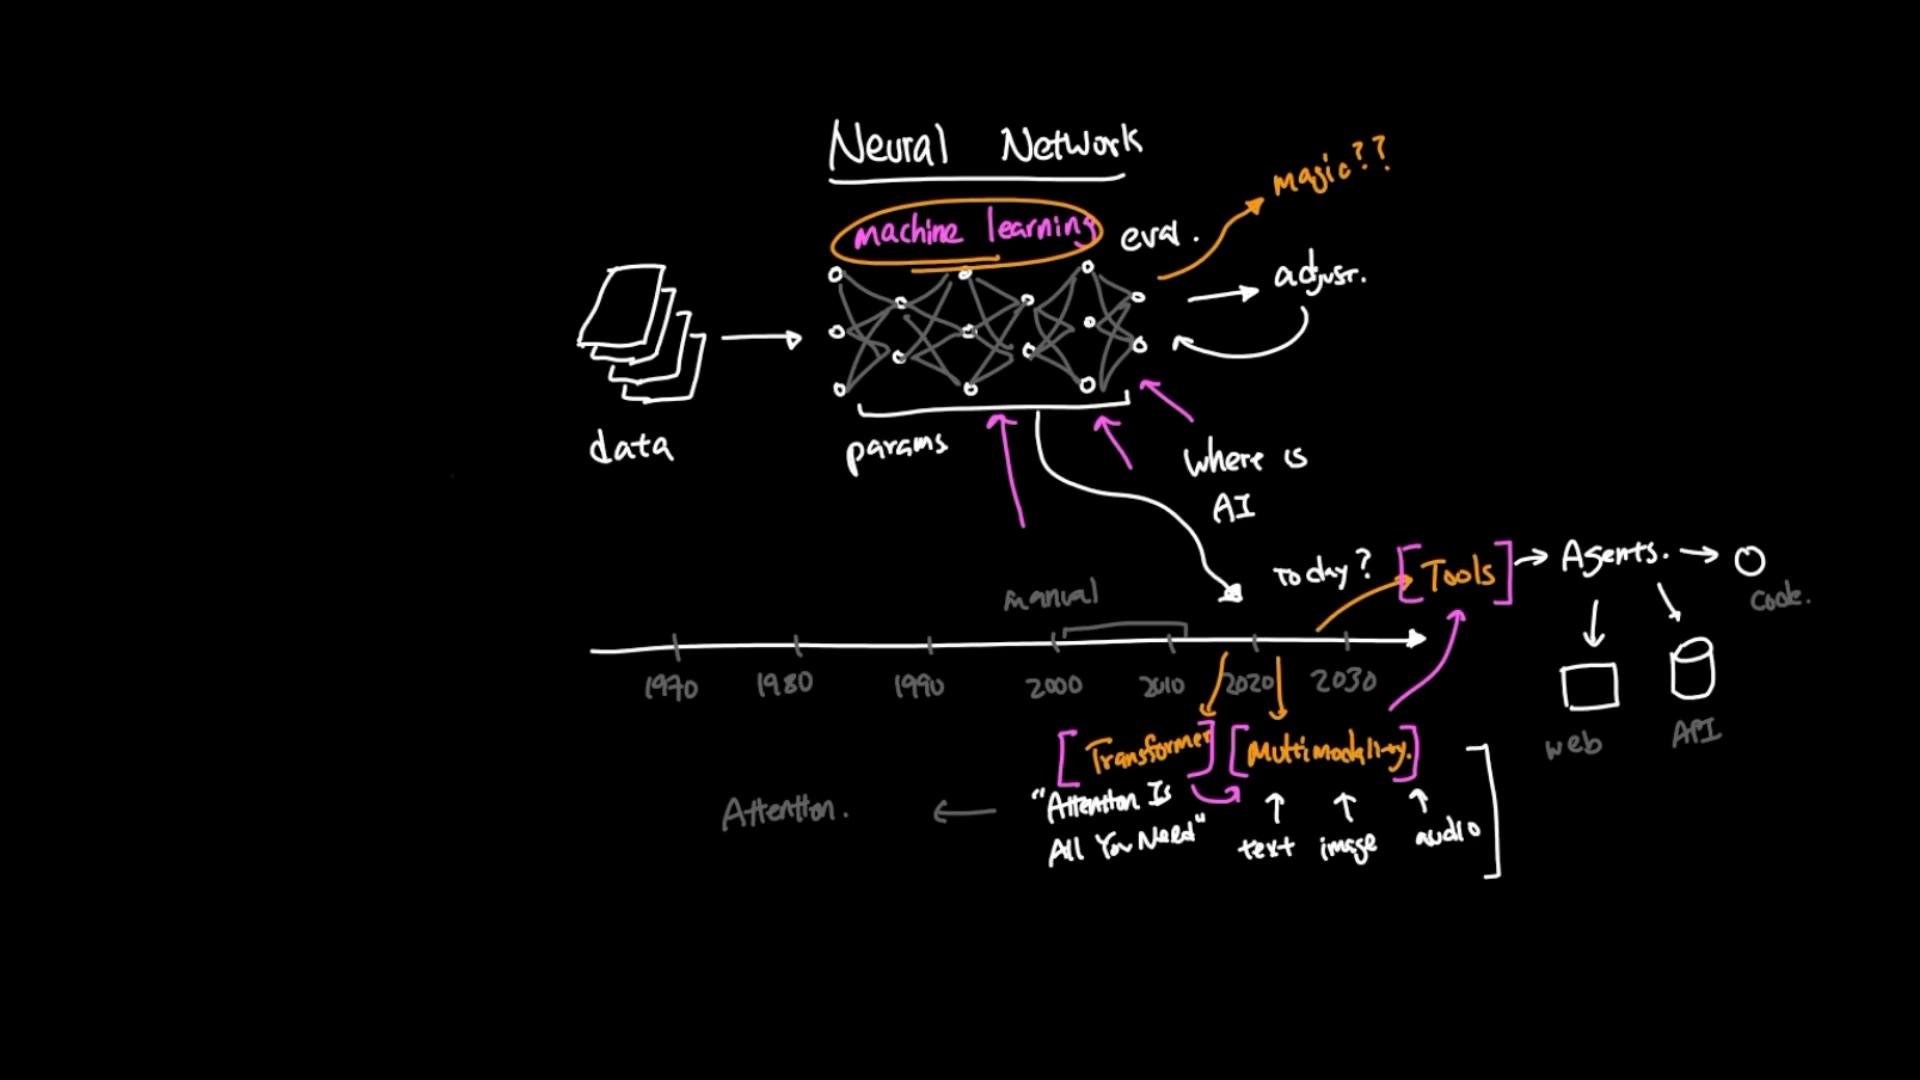
Links and references
- Attention Is All You Need (Transformer paper)
- CLIP — Connecting vision and language (OpenAI)
- DALL·E — Image generation from text (OpenAI)
- Kubernetes Documentation (example resource for system integration concepts)