

- Story-driven concepts: No terminals or clusters. We build ideas step-by-step, starting with a single user asking a chatbot a question. Each new idea is introduced as the solution to a limitation discovered in the previous step, so the resulting architecture emerges naturally.
- Hands-on demos: Real commands executed against a real cluster. Every architectural claim from the story is verified with live metrics, commands, and observable behavior.
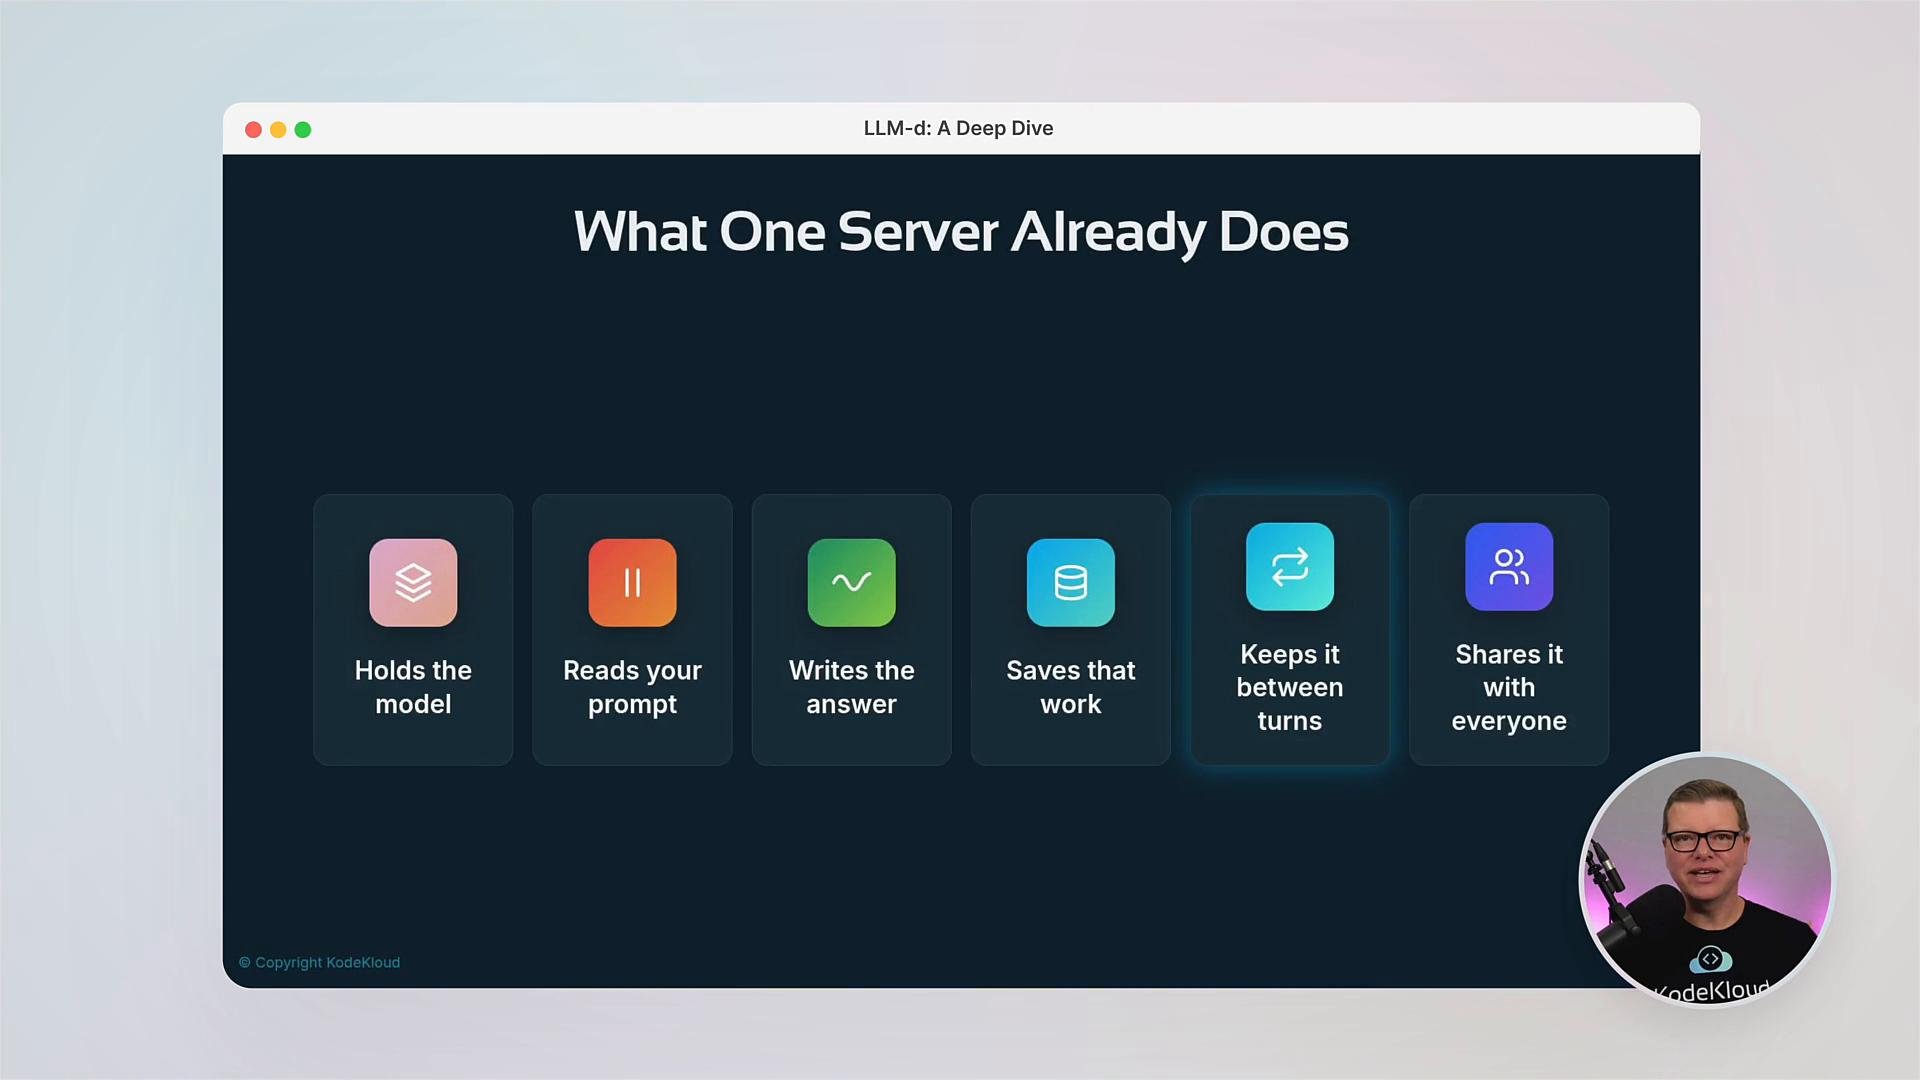
- How far the familiar Kubernetes pattern (containerize → load balance → add replicas) gets you when serving LLMs — and exactly where it fails.
- The failure modes you’ll see in practice: request drops, head-of-line blocking, GPU memory contention, and throughput collapse — plus how those failures show up in real metrics.
- A component-by-component architecture for model serving on Kubernetes, with responsibilities for routing, placement, and worker lifecycles.
- How to validate routing and placement decisions using commands and dashboards rather than slides.
- A safe rollout strategy to update model servers without dropping in-flight requests — turning a demonstration into an operational pattern.
- How to read the dashboards and benchmarks that tell you whether the system is healthy and where to tune for cost, latency, and throughput.
You can follow the demos and reproduce the results without owning a cluster — the lesson provides an environment and the exact commands you’ll run, so you can focus on understanding architecture, behaviors, and observable signals.