

Before designing changes, always measure the current system: latency, queue backlog, cache hit rates, and hot-key access patterns. Optimize based on data rather than assumptions.
Follow-up 1 — A power user follows many celebrities
Scenario: Alan follows 20,000 accounts, 800 of which are celebrities. Each time he opens the app the system must gather recent posts from those 800 celebrity accounts. Should you change the design? Key observations- The size of Alan’s follow list (20k) is not the main issue if the list itself is cached (for example, in Redis).
- The real cost comes from repeatedly querying the database for each celebrity’s recent posts on every read.
- Maintain a small cached list (e.g., a limited list of recent post IDs) per celebrity account. This per-celebrity cache is shared among all followers.
- Instead of 800 DB queries, the feed read fetches 800 small lists from cache.
- Because there are only a few thousand celebrity accounts total, storing these small caches in Redis is feasible.
- This prevents repeated DB hits when many followers request the same celebrity posts.
- Naive fan-out could cause a storm of reads when a celebrity posts. Caching celebrity posts prevents each follower from hitting the database repeatedly.
- For writes, avoid a single blocking fan-out: perform prioritized fan-out (see Follow-up 2) and rate-limit or batch writes to follower lists when appropriate.
- A user who follows 20k accounts will see a feed that churns rapidly as new posts push older ones out of their (capped) feed list. Typical systems cap per-user candidate lists (e.g., 500 post IDs) and only surface the top N (e.g., 50).
- Trade-offs: you can increase per-user cache size or provide persistent per-user storage if you must preserve more history, but that increases cost. Most products prioritize top-of-feed freshness for active reading.
Follow-up 2 — New posts take 8 minutes to reach follower lists
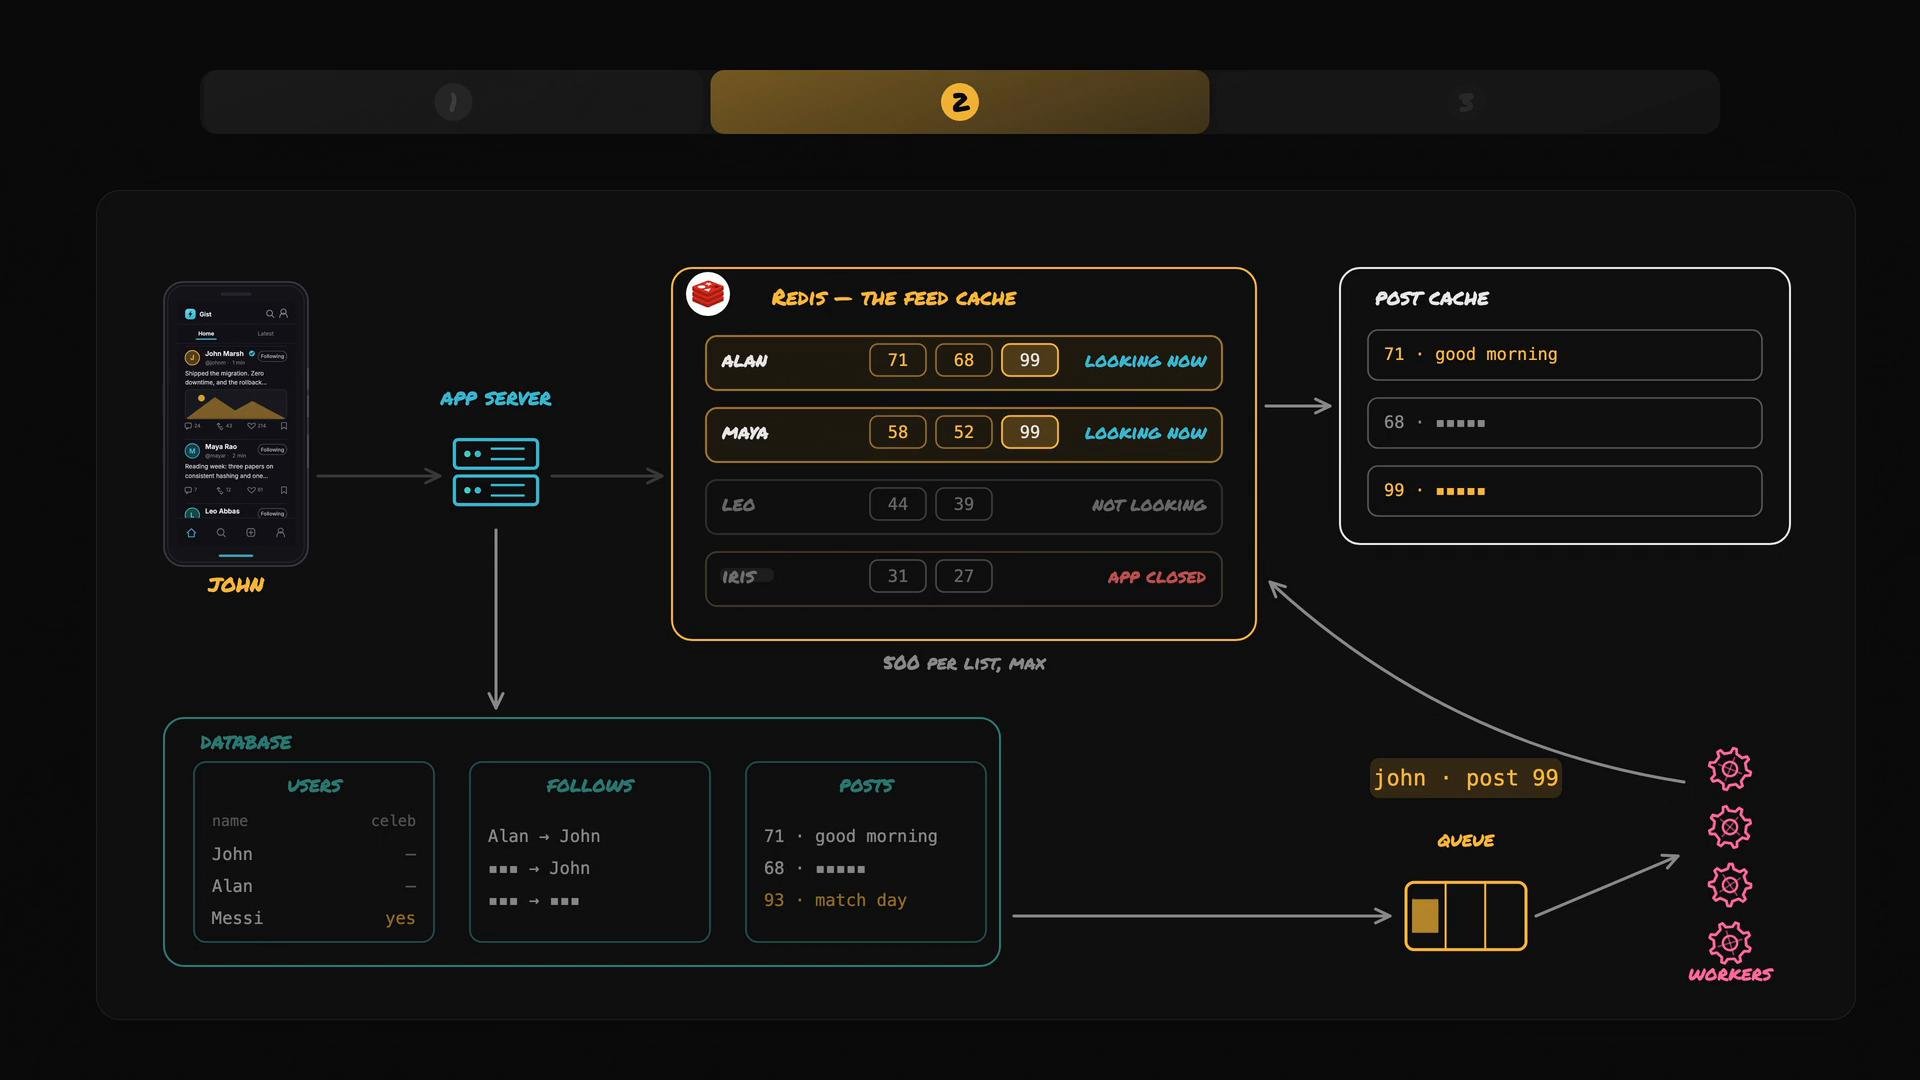
Scenario: New posts are delayed — it takes 8 minutes for a post to appear in all followers’ feeds. How do you fix it? Step 1 — Measure- Measure latency from post creation to the point the last follower list is updated. Identify whether the queue is accumulating tickets and where the bottleneck lies (queue length, worker throughput, DB writes, network IO).
- Increase worker parallelism: add more workers to consume the queue concurrently.
- Be deliberate: adding workers raises cost and operational complexity. Scale where it provides the best latency improvement per dollar.
- Don’t treat all followers equally during fan-out. Prioritize active or recently-active followers first.
- When a worker processes a post, it first pushes the post to lists of followers who are online or were recently active.
- The remaining followers receive the post in a secondary pass.
- Benefits:
- Active users see the post quickly, improving perceived freshness.
- Peak load is reduced because many inactive users won’t notice a small delay.
Follow-up 3 — Product wants a ranked feed (relevance over recency)
Scenario: Product wants relevance-based ranking rather than strictly newest-first ordering. What changes are required? What does not change- Core storage tables, the event queue, worker fan-out, and the post cache can remain as-is.
- We still maintain per-user candidate lists (e.g., newest 500 post IDs) populated by fan-out workers.
- On a feed read, fetch a bounded candidate set (for example, newest 500 post IDs from the user’s list, merged with celebrity caches).
- Send these candidates to a dedicated scoring service that computes a relevance score for each candidate and returns posts sorted by score.
- Return the top N items (e.g., top 50) to the user.
- Ranking depends on dynamic signals that change after publish: likes, comments, recent interactions between the viewer and the author, and time-decayed signals.
- Precomputing scores at write-time becomes stale; computing scores at read-time over a bounded candidate set keeps results relevant.
- Increased per-read CPU and IO because the scoring service must fetch dynamic metrics (likes, comments, user interactions) for each candidate.
- Post ordering can change between reads. If duplicates on refresh are problematic, maintain a per-user “seen” set or deduplication filter.
- Keep the candidate set bounded (a few hundred) to control scoring latency. Use feature caches for common metrics to reduce IO.
When adding ranking, always score a bounded candidate set at read time (e.g., the newest few hundred candidates). This limits latency while allowing dynamic signals to influence ordering.
Final notes
- The news-feed pattern (fan-out, caching, prioritized updates, and read-time ranking) is common across Twitter, Instagram, and Facebook. The right choices balance cost, latency, and user experience.
- In interviews, emphasize measurement first (queue backlogs, cache hit rates), prioritize work that improves user-visible metrics, and clearly state trade-offs for each option.
- Practice explaining how caching, prioritized fan-out, and read-time scoring work together: that combination is a robust approach for scalable, low-latency, and relevant news feeds.