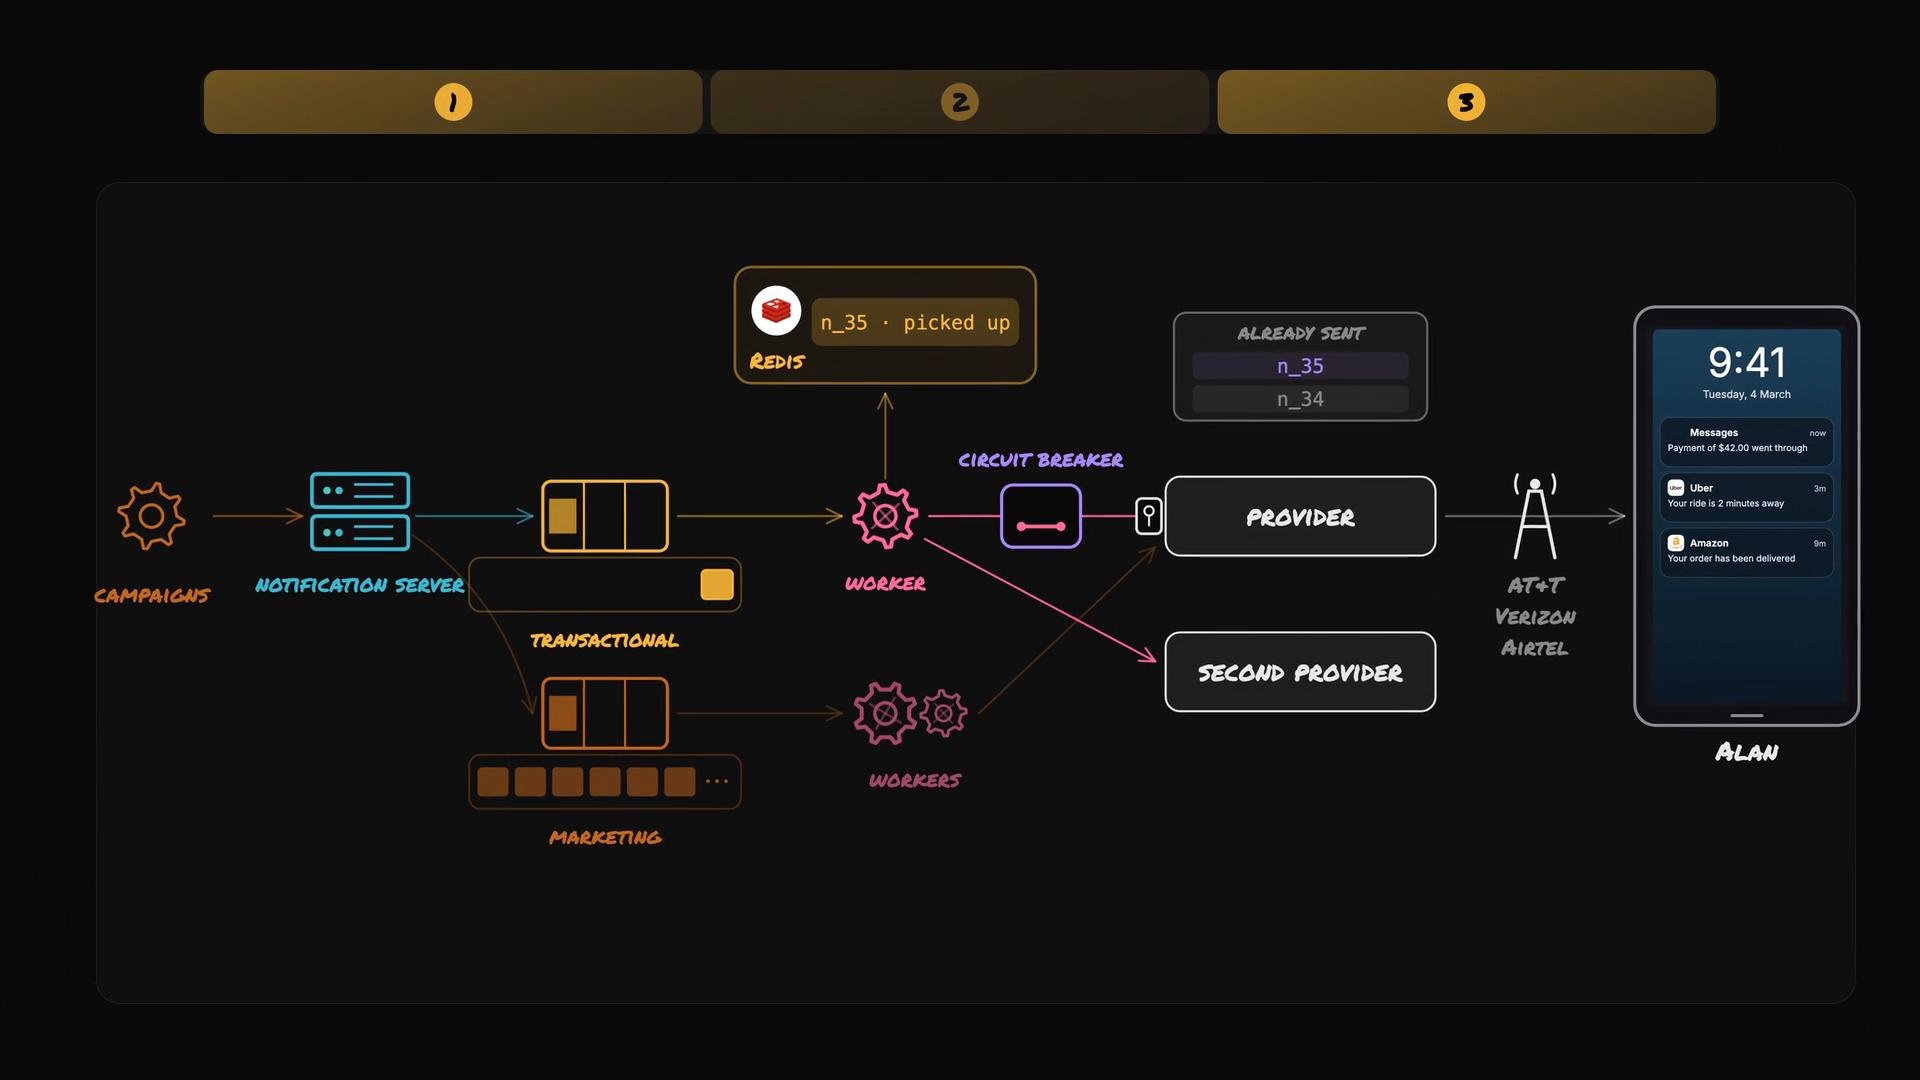
Question 1 — A marketing campaign floods the queue with one million notifications. Alan’s login code is stuck behind that traffic. What do you change?
Problem: transactional messages (login codes, password resets) have strict latency needs (seconds), while marketing campaigns can tolerate much higher delays. A shared queue allows bulk marketing traffic to block critical transactional messages. Solution:- Segregate traffic by priority at enqueue time. Create separate queues per channel:
email.transactional,email.marketingsms.transactional,sms.marketingpush.transactional,push.marketing
- Run dedicated worker pools for each transactional queue. Workers for marketing queues must not be allowed to steal or borrow transactional workers.
- Optionally apply more granular priority buckets (e.g., high/medium/low) for complex workloads and SLA differentiation.
- Transactional messages stay low-latency even during large marketing campaigns.
- Easier to scale marketing workers independently without affecting transactional SLAs.
Separate queues and dedicated workers for transactional vs. marketing traffic preserve low latency for critical notifications.
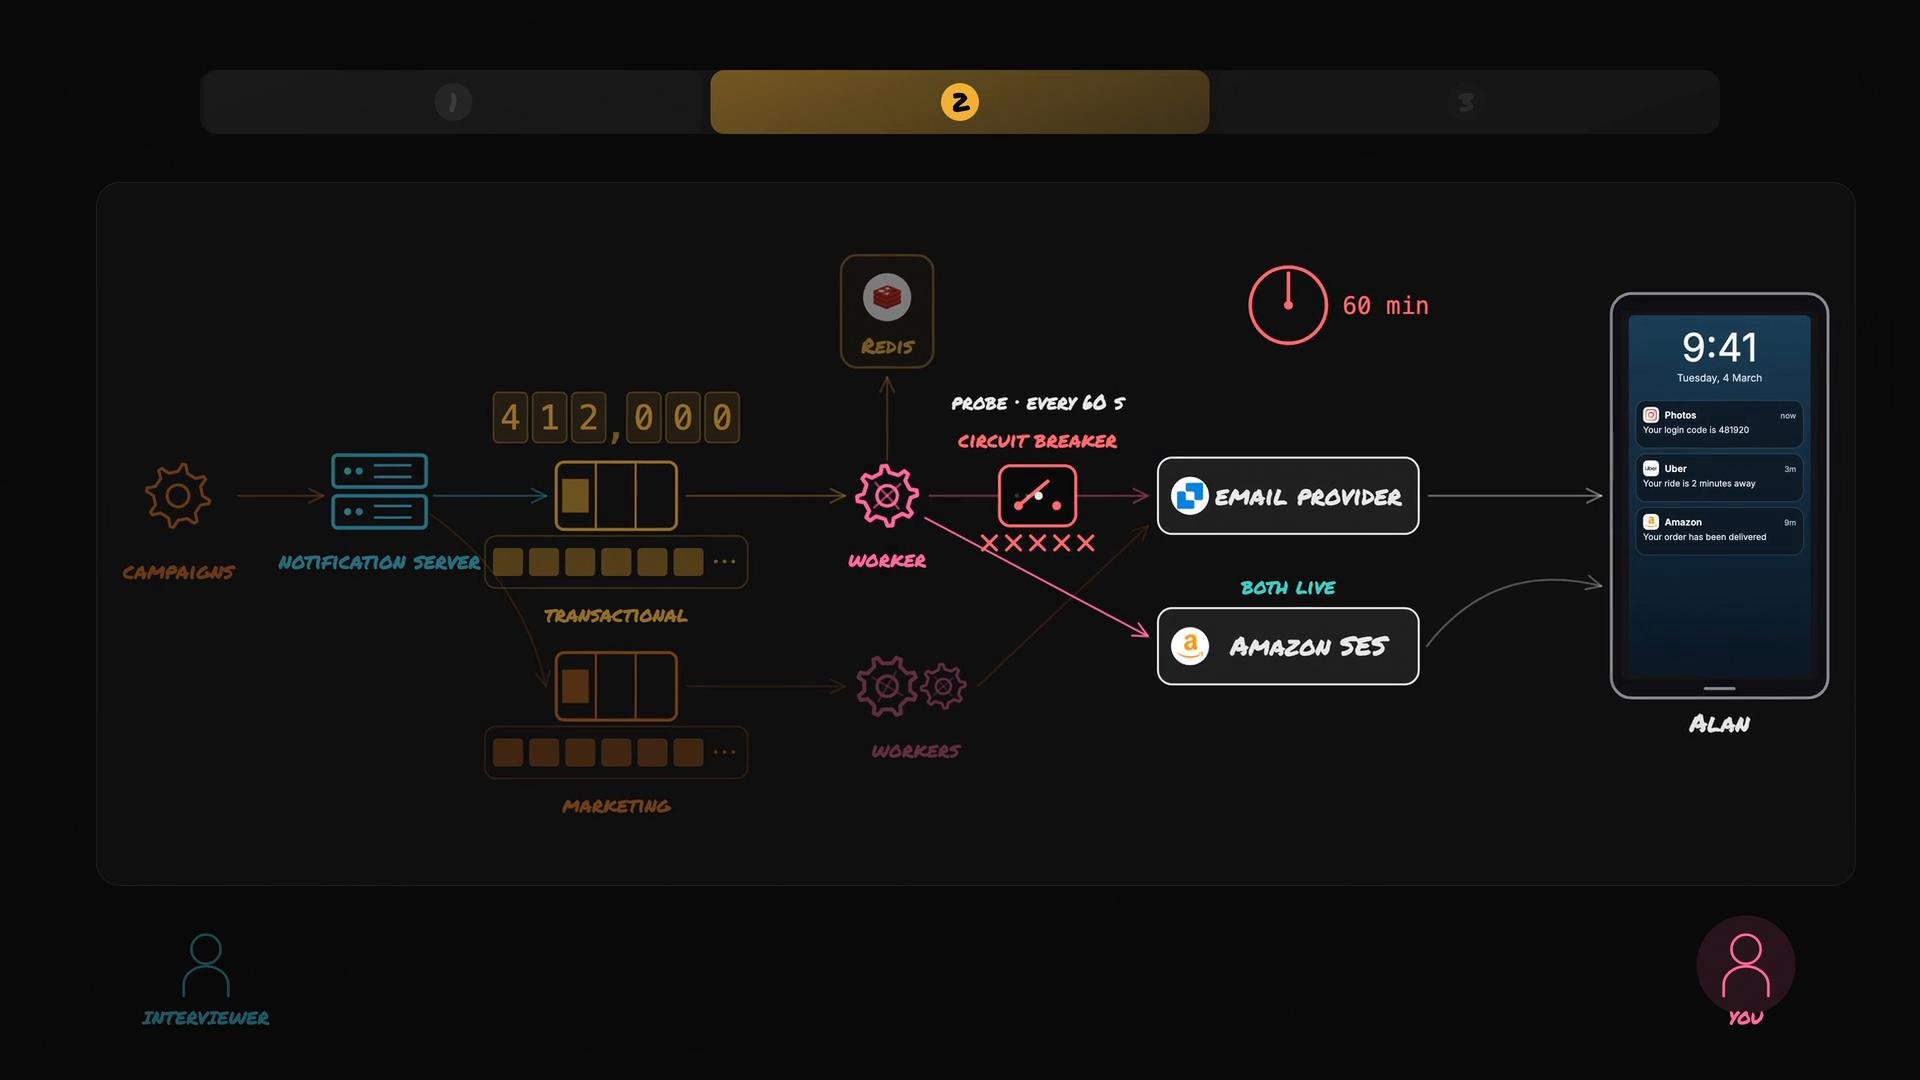
Question 2 — The email provider is down for one hour. What does the system do during that hour?
Key behaviours to describe:- Durable accumulation: email messages remain safely in the queue (persistent/durable storage) and are not lost.
- Backoff + circuit breaker: workers should stop hammering a failing provider after a configurable number of consecutive failures. Use an exponential backoff and open a circuit that prevents delivery attempts until a periodic probe detects recovery.
- Periodic probe for recovery: a single lightweight probe (for example, once per minute) can be used to test provider health and close the circuit when the provider is healthy again.
- Multi-provider failover: support a secondary (or active-active) provider and route traffic there if the primary is down.
- Respect expiry: short-lived notifications (e.g., OTPs) should carry an expiry timestamp; expired messages should be discarded rather than retried.
- Idempotency + audit: keep delivery logs and dedupe attempts where possible.
- Queue retains messages (no data loss).
- Workers hit the circuit breaker after N failures and switch to periodic probes.
- If a secondary provider exists, traffic is routed there automatically or via configurable failover rules.
- Expired messages are dropped at dequeue time.
- Circuit breaker pattern: https://martinfowler.com/bliki/CircuitBreaker.html
- Exponential backoff: commonly used for transient network failures
Question 3 — You say exactly-once delivery is impossible. Show exactly when the system could still send the notification twice and why an idempotency key might fail.
Explain the critical race that causes uncertainty: Scenario (step-by-step):- A worker dequeues message
notif-1234and checks Redis (or a sent-log) for whethernotif-1234was delivered. - Redis indicates it has not been sent. The worker marks
notif-1234as “in-progress” and calls the SMS provider. - The request to the provider times out before the worker receives a response.
- Provider never received the request → safe to retry.
- Provider received and sent the message, but the response was lost → retry will cause duplicate delivery.
- Provider received and is still processing → retry may or may not duplicate delivery.
- Idempotency keys: include the notification ID in the provider request. Many providers will deduplicate on server-side if the same idempotency key is presented.
- Delivery acknowledgements + durable audit log: only mark as delivered after a confirmed acknowledgement; but timeouts and provider semantics still leave ambiguity.
- User-level design: ensure the user experience tolerates rare duplicates (e.g., short-lived codes, clear messaging).
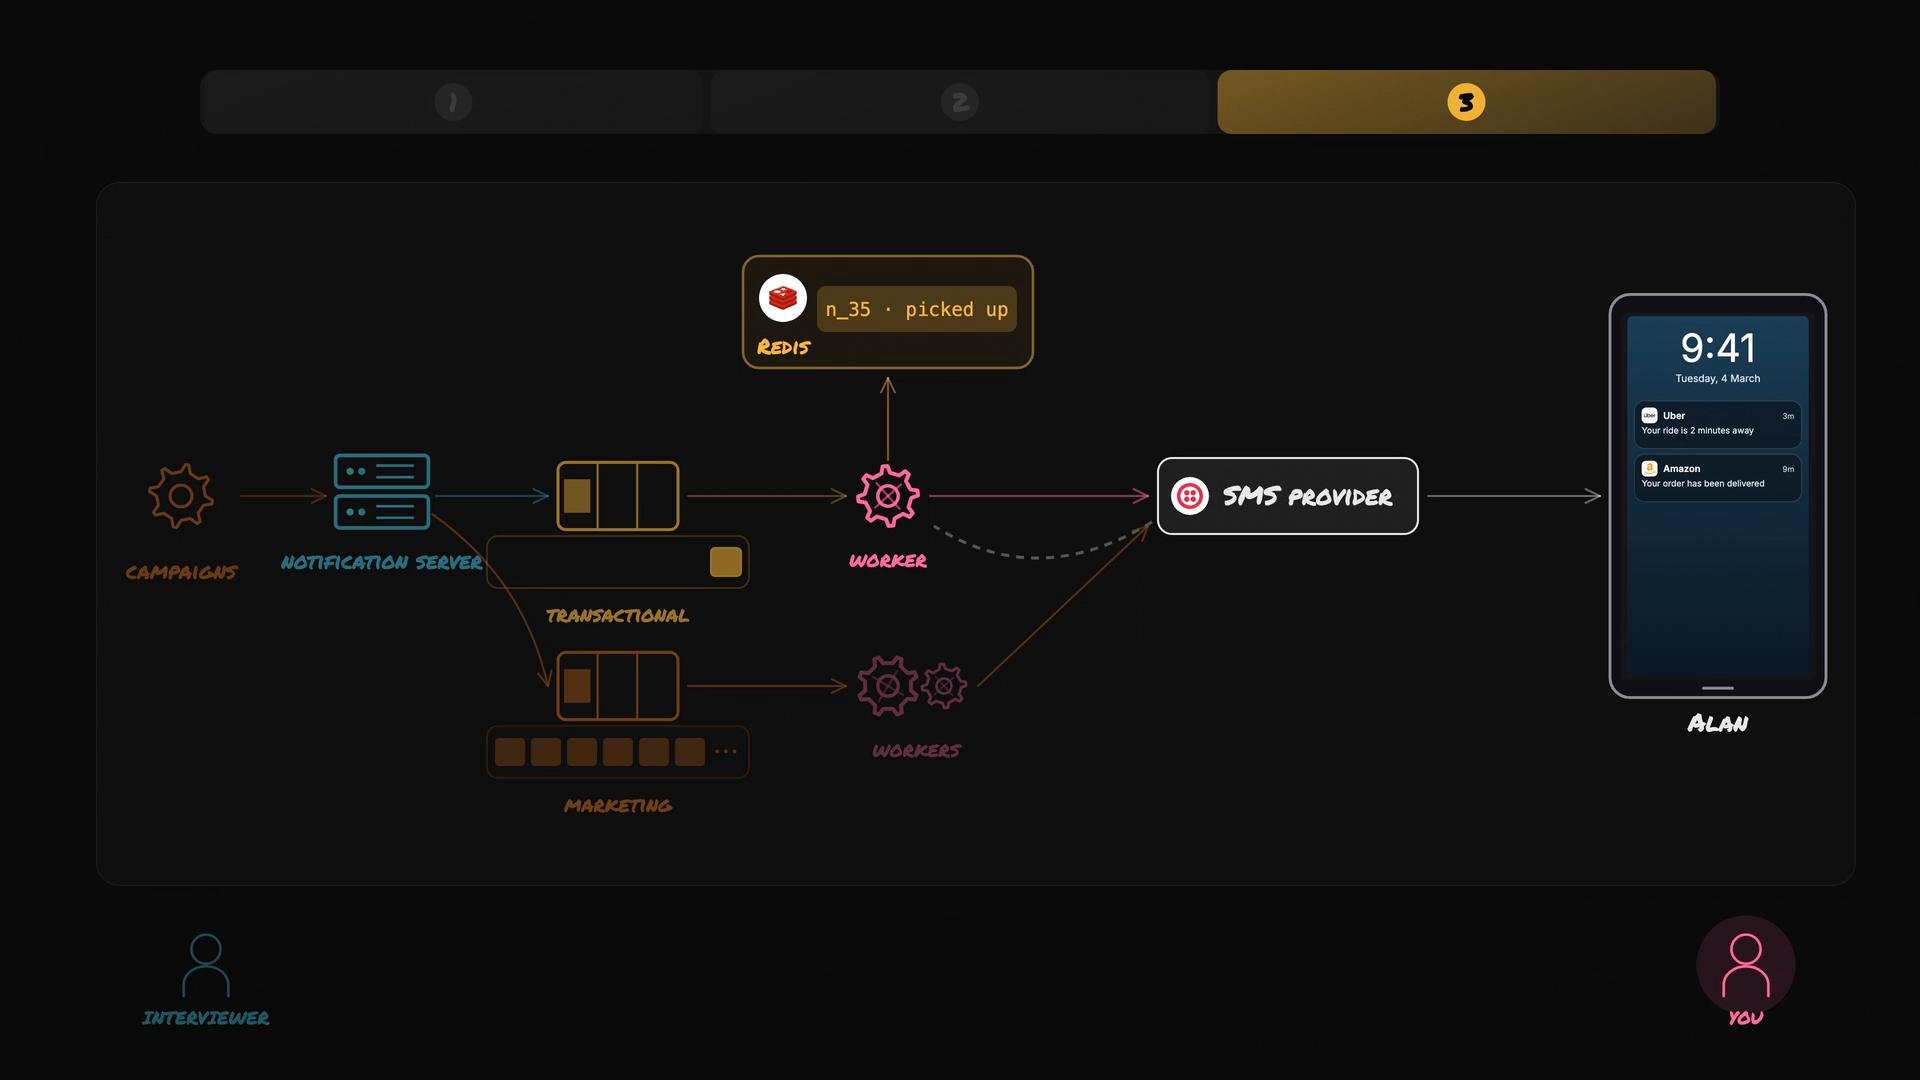
Idempotency keys reduce provider-level duplicates, but network/carrier-level behavior can still cause duplicate deliveries. Exactly-once semantics cannot be fully guaranteed end-to-end.
- Emphasize that idempotency greatly reduces duplicates but doesn’t eliminate them across the full delivery chain (carrier/operator behaviors).
- Describe measurable SLAs and monitoring (duplicate-rate alerts, delivery latency histograms).
- Propose compensating UX or business rules for duplicates (e.g., ignore duplicate OTPs within a small time window).
Summary — What to say in an interview
- Separate priorities: use dedicated queues and worker pools for transactional vs. marketing notifications to guarantee low latency for critical messages.
- Design for outages: durable queues, circuit breakers, periodic probes, and multi-provider failover keep the system resilient to provider outages.
- Respect expiry: attach expiry timestamps to short-lived notifications so workers discard stale messages.
- Mitigate duplicates: use idempotency keys and provider-side deduplication, but acknowledge end-to-end exactly-once delivery is infeasible; design the UX to tolerate rare duplicates.