

notify endpoint. This notification system is a normal application running on servers — not a black box — and its primary goals are reliability, scalability, and clear visibility into notification state.
High-level behavior
- When the notification API receives a request, it persists the complete notification record in PostgreSQL and marks its status as
pending. - At that point we must decide who performs the actual sending work: the API process itself (synchronous) or separate worker processes (asynchronous with a queue).
Simplest approach — synchronous sending
- After saving the notification to the database, the server calls external providers directly:
- Apple Push Notification Service (APNs) for push
- An SMS gateway for text messages
- An email provider for email
- The API waits for each provider’s acceptance/acknowledgement. When providers respond, the server updates the notification status from
pendingtosent.
Synchronous sending ties API capacity to external provider latency. A single slow provider or a crash while sending can produce ambiguous notification states and message loss.
Failure scenarios with synchronous design
- If the notification server crashes mid-send (say, processing notification #2000), some providers may have accepted the payload while others have not. The server cannot reliably know the final outcome for that notification.
- Blocking on provider responses makes the system fragile to spikes and slow downstreams, and reduces overall throughput and resiliency.
Why a queue is the right component
A message queue decouples acceptance (persisting a notification) from delivery (sending to external providers). Benefits:- Durable storage of the full notification remains in the database (PostgreSQL).
- The queue stores a small, transient ticket per notification (typically just the notification ID).
- Workers pull tickets and perform sending, allowing horizontal scaling and retries.
What the queue provides (detailed)
- Database: the source of truth. Stores full notification body, channels, status, timestamps, retry history.
- Queue: stores lightweight tickets (e.g.,
{ "notification_id": 35 }) that represent pending work. - Workers: read tickets, retrieve the notification from the DB, check contacts and preferences, and then send to external providers.
- Visibility timeout and retries: if a worker crashes before acknowledging a ticket, the queue detects the lack of acknowledgement and re-queues the ticket (or assigns it to another worker), preventing message loss.
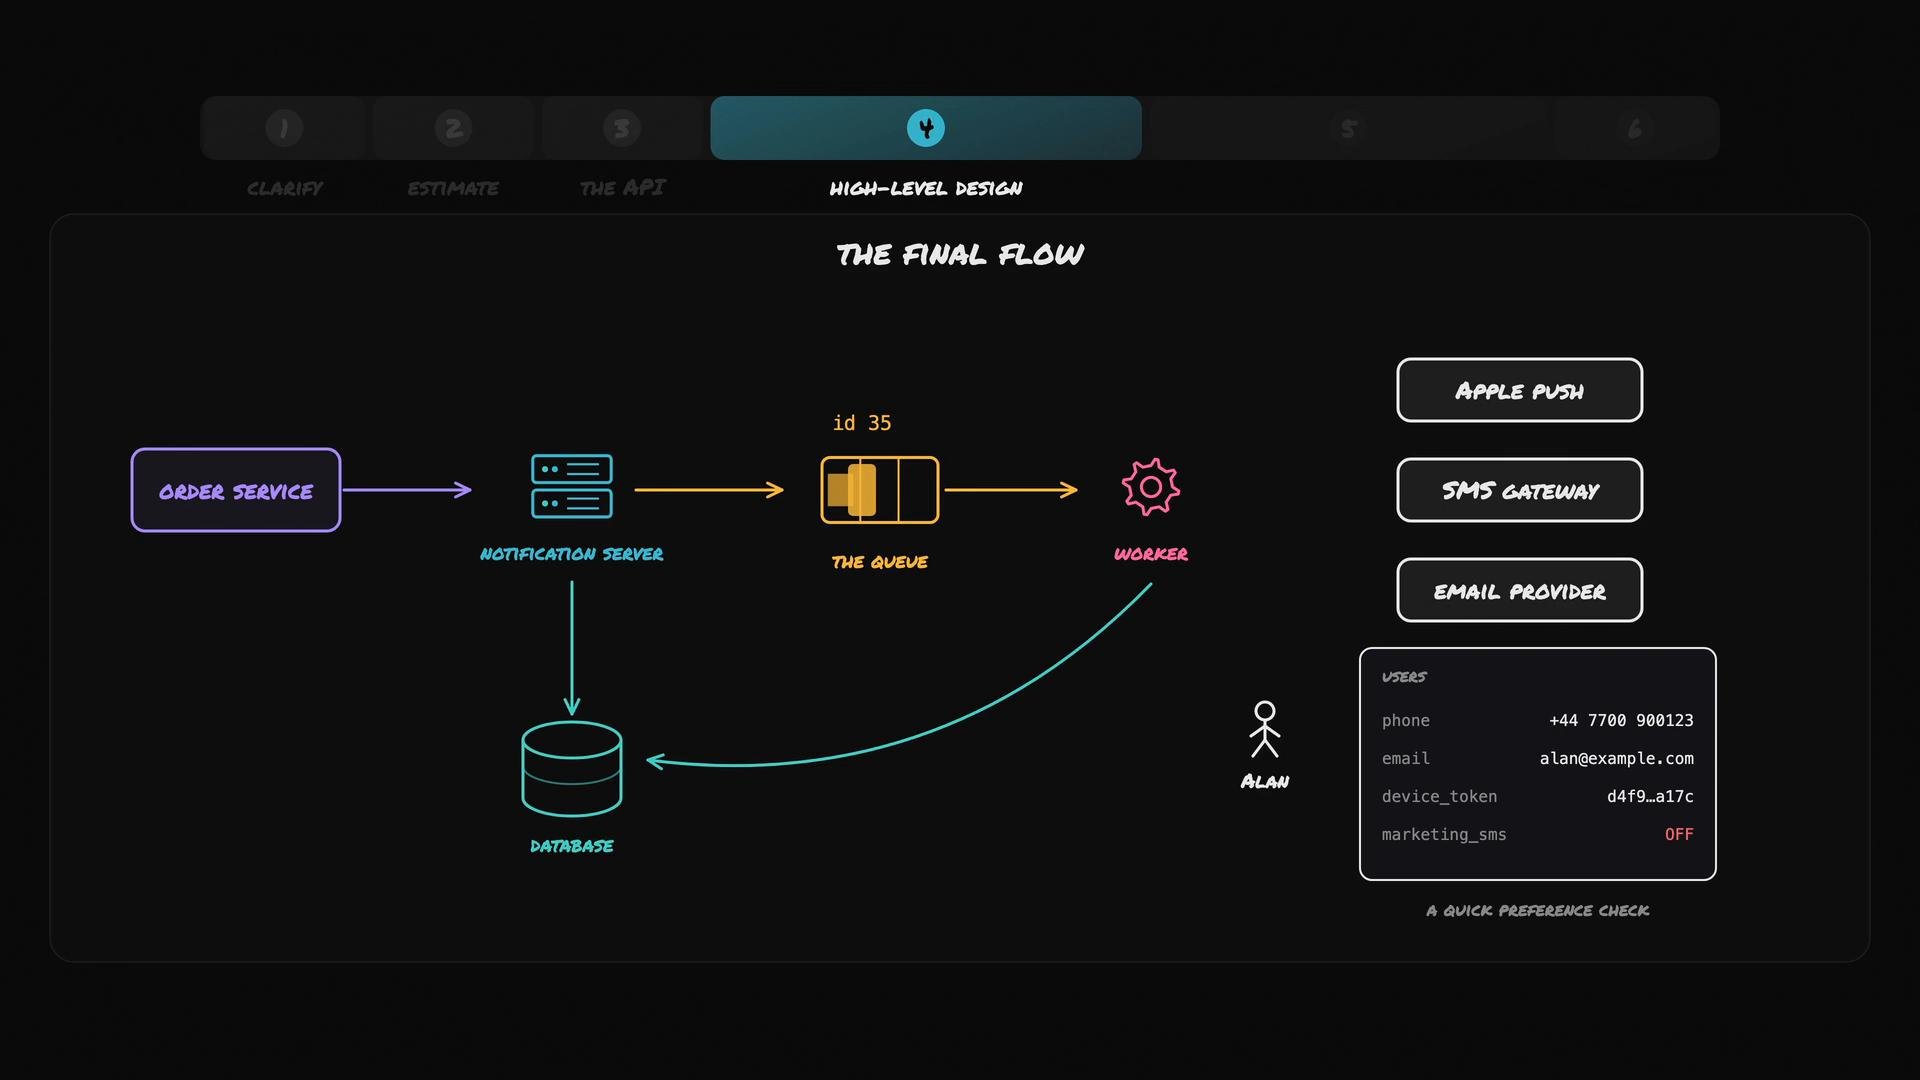
Final flow (with workers)
- API receives notification request and persists the full record in PostgreSQL with status
pending. - API enqueues a small ticket into the message queue (usually only the notification ID and metadata).
- Worker processes consume tickets in parallel:
- Read the
notification_idfrom the ticket. - Fetch the full notification record from the database.
- Load the recipient’s contact details (device token, phone, email) and notification preferences.
- Decide which channels to use based on preferences (drop or skip channels if the user opted out).
- Send to chosen providers (APNs, SMS gateway, email provider).
- When provider acknowledgements arrive, update the notification status in the database and acknowledge the ticket in the queue so it’s removed.
- Read the
- If a worker crashes before acknowledging, the queue’s visibility timeout ensures the ticket becomes available again so another worker can retry.
Concrete example
- A worker pulls a ticket referencing notification ID
35. - It loads notification
35from PostgreSQL and finds it is addressed to Alan. - The worker fetches Alan’s contact details and preferences from the users table (device token, phone number, email).
- If Alan opted out of marketing SMS and this notification is marketing-related, the worker discards the SMS channel and acknowledges the ticket (no unwanted delivery).
- Otherwise the worker sends through the appropriate providers and updates the notification status to
sent(orfailedwith retry metadata on transient errors).
Comparison: synchronous vs queued (at-a-glance)
Implementation notes & best practices
- Keep the DB as the source of truth; queue tickets should be minimal to reduce queue size and processing overhead.
- Use idempotent worker behavior so retries do not cause duplicate notifications (store unique provider IDs or use deduplication keys).
- Persist retry metadata and error reasons in the database for observability and debugging.
- Respect user preferences and legal requirements (e.g., opt-outs, regional restrictions) in workers before sending.
- Choose a queue system that supports visibility timeouts and dead-letter queues (DLQs) for non-recoverable failures.
Using a message queue decouples acceptance from delivery: the API accepts requests quickly, workers reliably deliver notifications later, and the system gains retries, visibility timeouts, and horizontal scaling without losing messages when workers fail.
Links and references
- PostgreSQL: https://www.postgresql.org/
- Message queue overview: https://en.wikipedia.org/wiki/Message_queue
- AWS SQS visibility timeout: https://docs.aws.amazon.com/AWSSimpleQueueService/latest/SQSDeveloperGuide/sqs-visibility-timeout.html
- Apple Push Notification Service (APNs): https://developer.apple.com/documentation/usernotifications/setting_up_a_remote_notification_server
- SMS gateway: https://en.wikipedia.org/wiki/SMS_gateway
- Email service providers: https://en.wikipedia.org/wiki/Email_service_provider