

Prompt engineering is production software: treat prompts as structured, testable artifacts. Build a prompt generator with parameters, ordering, and conditional sections so you can A/B test and iterate.
1) Persona assignment
Assigning a persona (e.g., “You are a senior Python engineer”) does more than set tone — it shifts the model toward the statistical cluster of text associated with that role. This affects vocabulary, reasoning patterns, and priorities. Activation-patching research shows persona effects concentrate in early and some middle attention layers; you can even extract and inject role vectors at inference time to mimic this shift.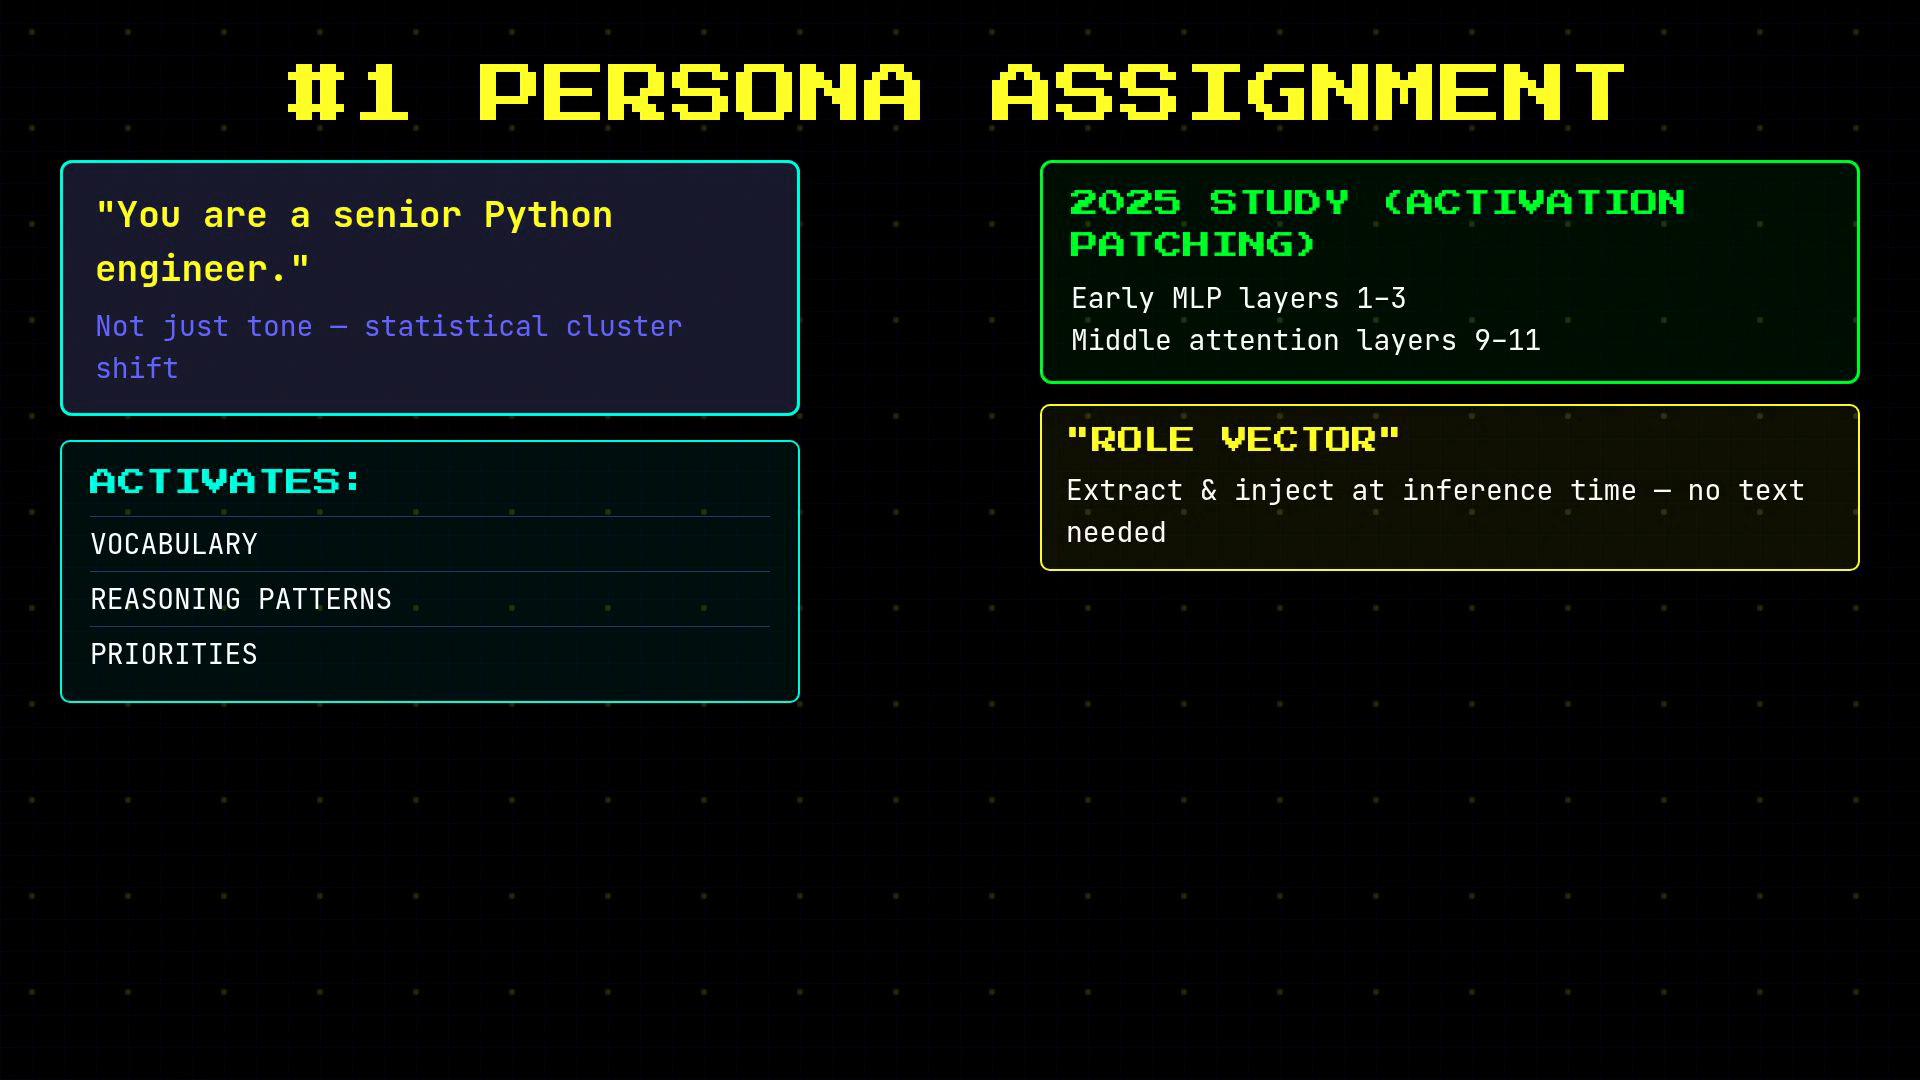
- Use it for domain-specific or stylistic tasks (code review, legal tone, editorial voice).
- Avoid or carefully test it for abstract reasoning and arithmetic — it can sometimes degrade accuracy by introducing unwarranted assumptions.
- A/B test persona vs. no-persona on representative benchmarks.
- For production agents, layer personas: a stable base identity, specialized skill instructions, and optional narrow role reframings when needed.
- Base identity:
You are a personal assistant running inside OpenClaw. - Skills: inject tool- and task-specific instructions.
- Extensions: occasionally reframe identity (e.g.,
You are the OpenClaw VM.) to tighten behavior.
2) Positive over negative instructions
Negations are cognitively tricky for LLMs. Compare:- “Don’t use bullet points.”
- “Write in paragraphs only.”
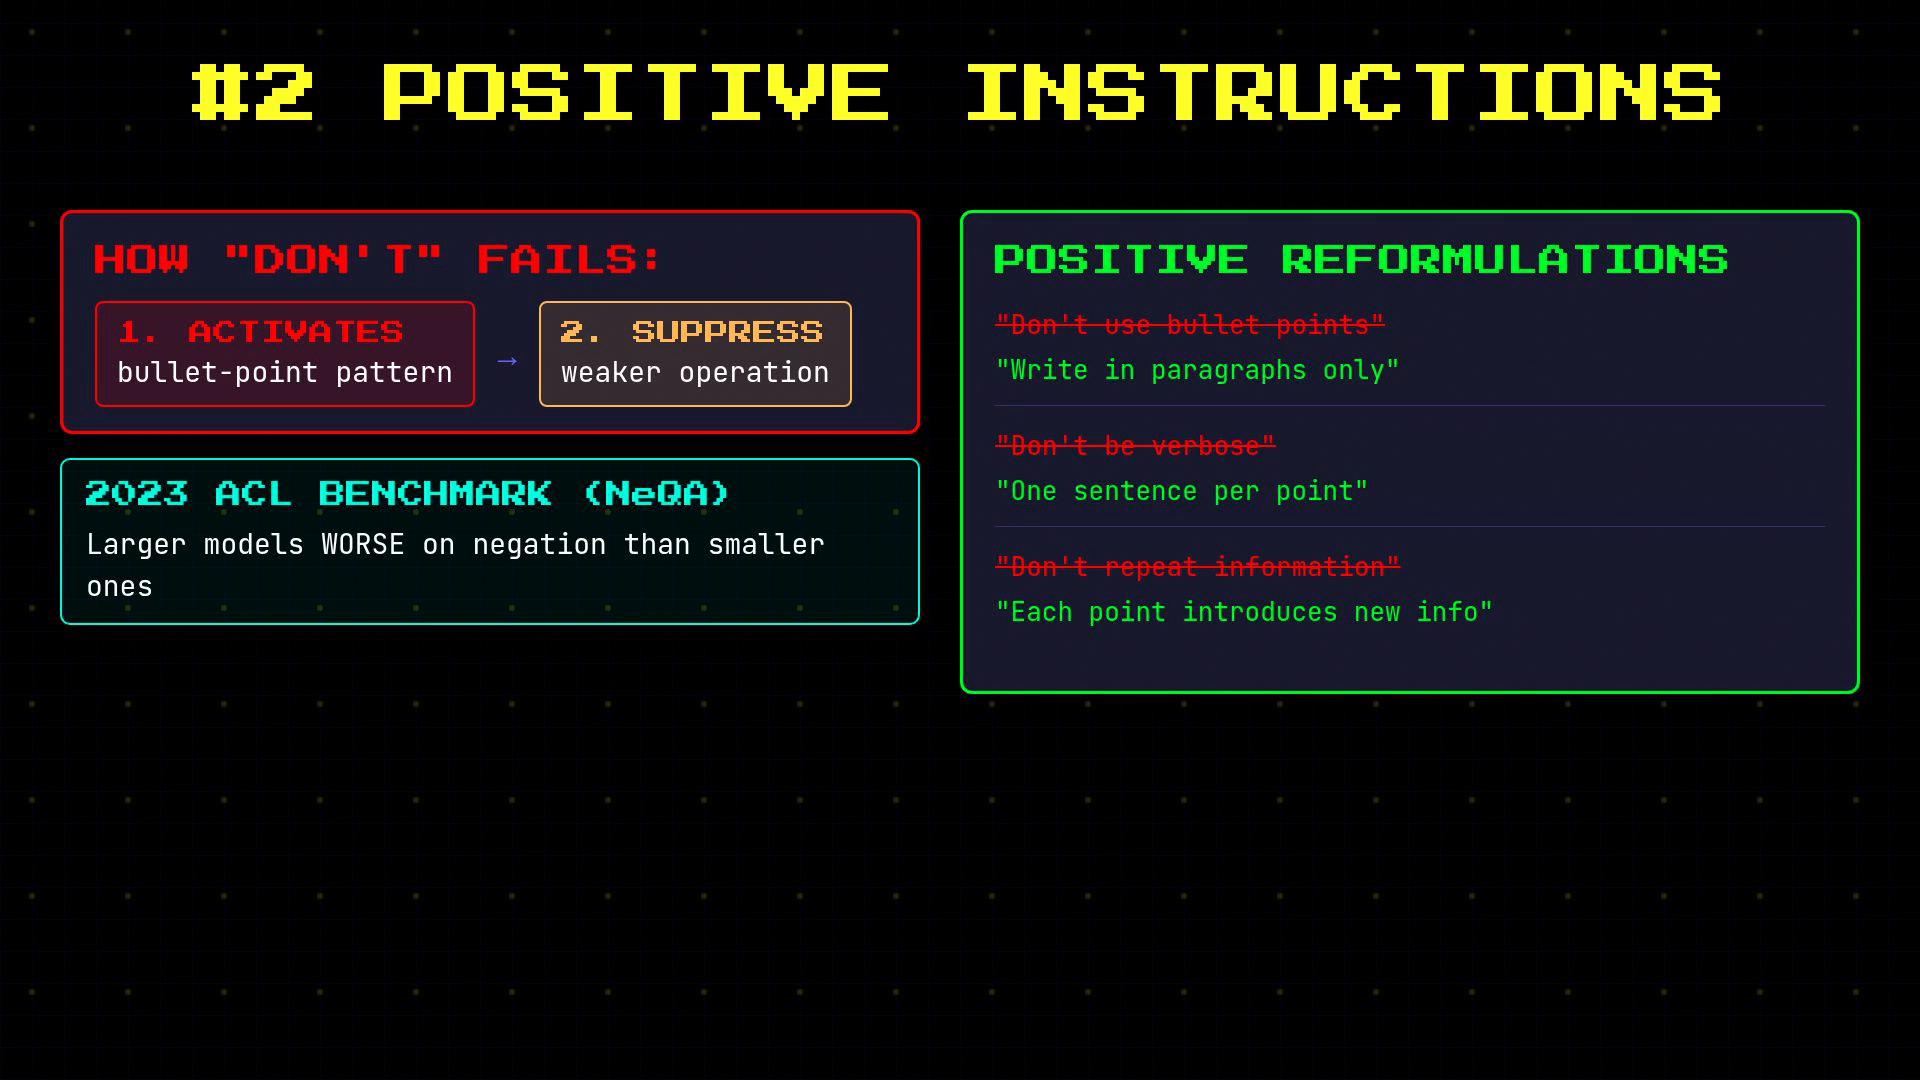
- Phrase preferences positively for general behavior.
- Reserve explicit negations for absolute constraints (safety/legal rules).
- Keep hard constraints separate from regular guidance so they’re treated as invariants.
3) Order and structure
Position matters. Empirical work documents a U-shaped attention pattern: models attend more to the beginning and end of a prompt than to the middle. Place critical instructions at the start or end, and avoid burying them in the middle of long contexts.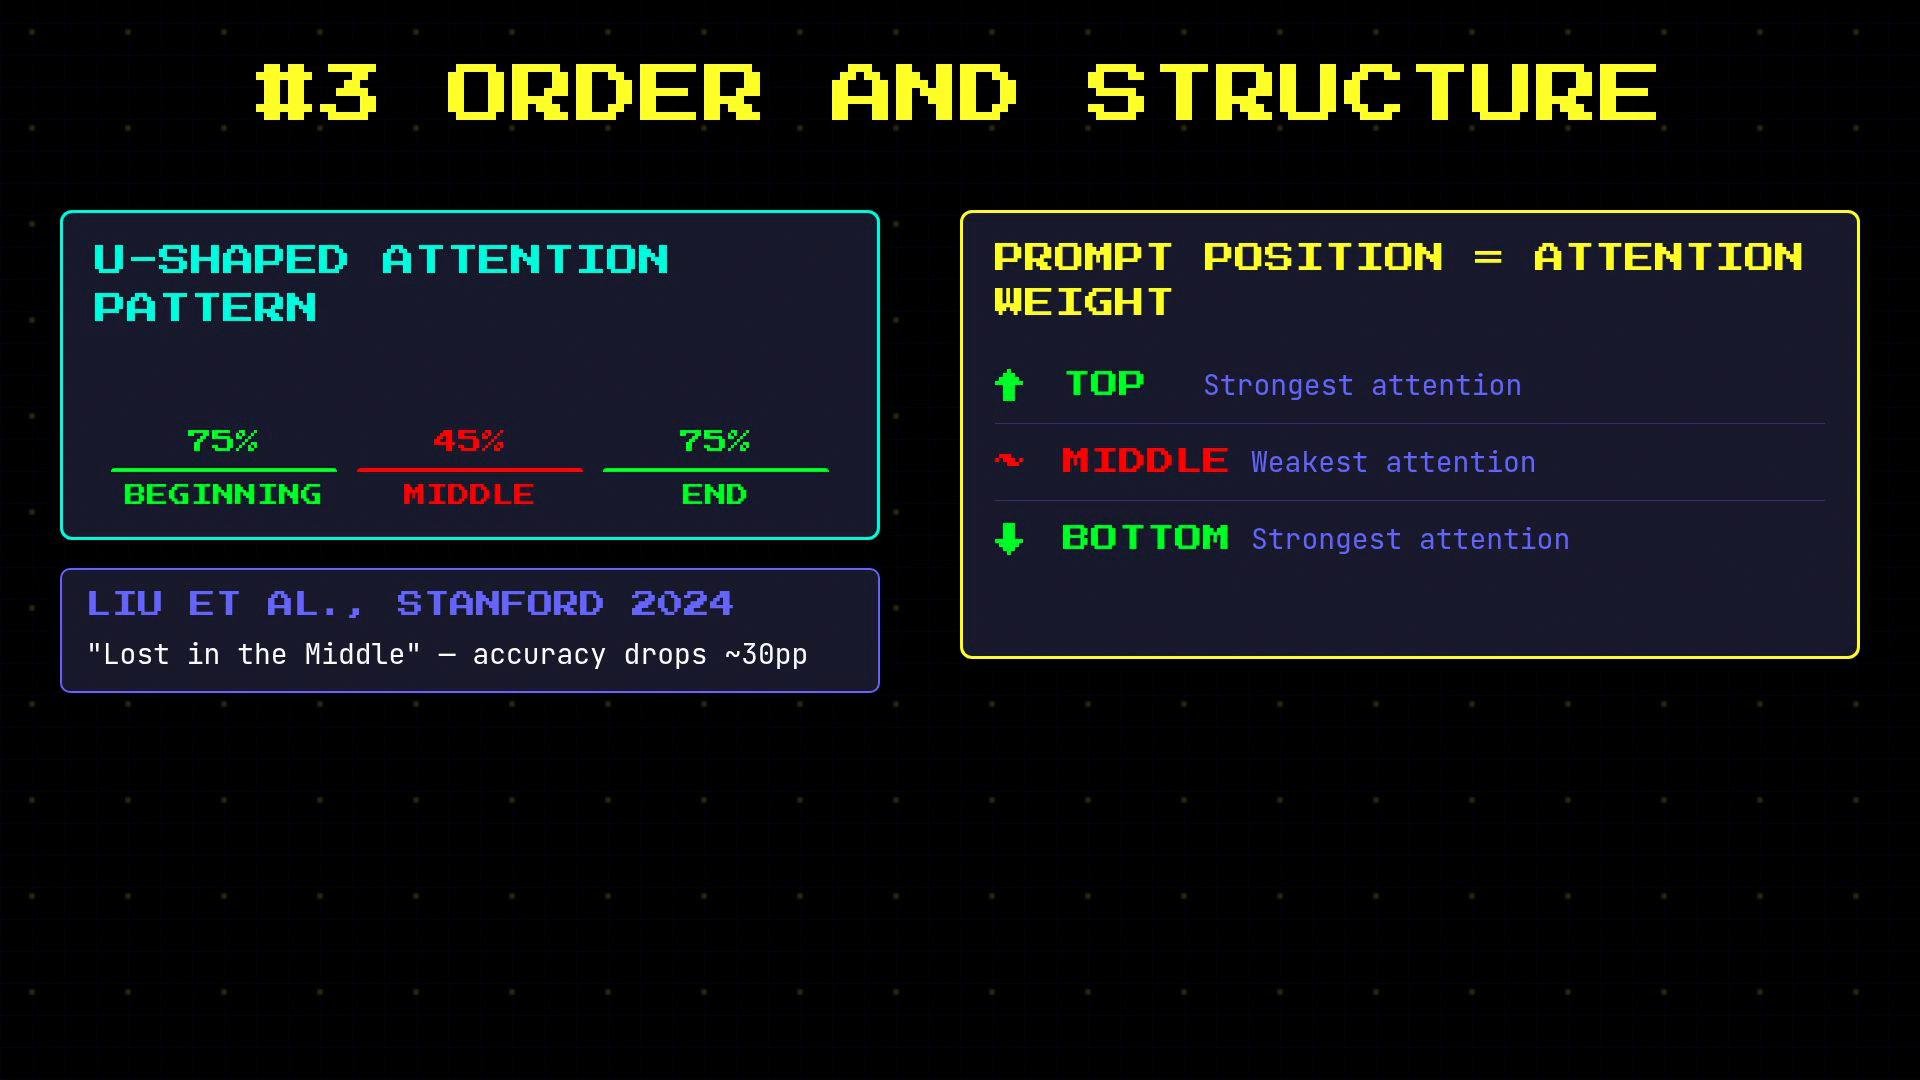
- Put critical constraints and identity first.
- Place the specific user question last.
- Insert large context files in the middle.
- For long prompts, repeat constraints at both the beginning and the end.
4) Chain-of-thought (structure the reasoning)
Asking a model to “think step-by-step” can improve performance because intermediate tokens condition later tokens. However, free-form chain-of-thought may introduce biases or reduce accuracy in some settings. OpenClaw avoids unstructured internal reasoning in outputs and instead enforces explicit, auditable reasoning tags.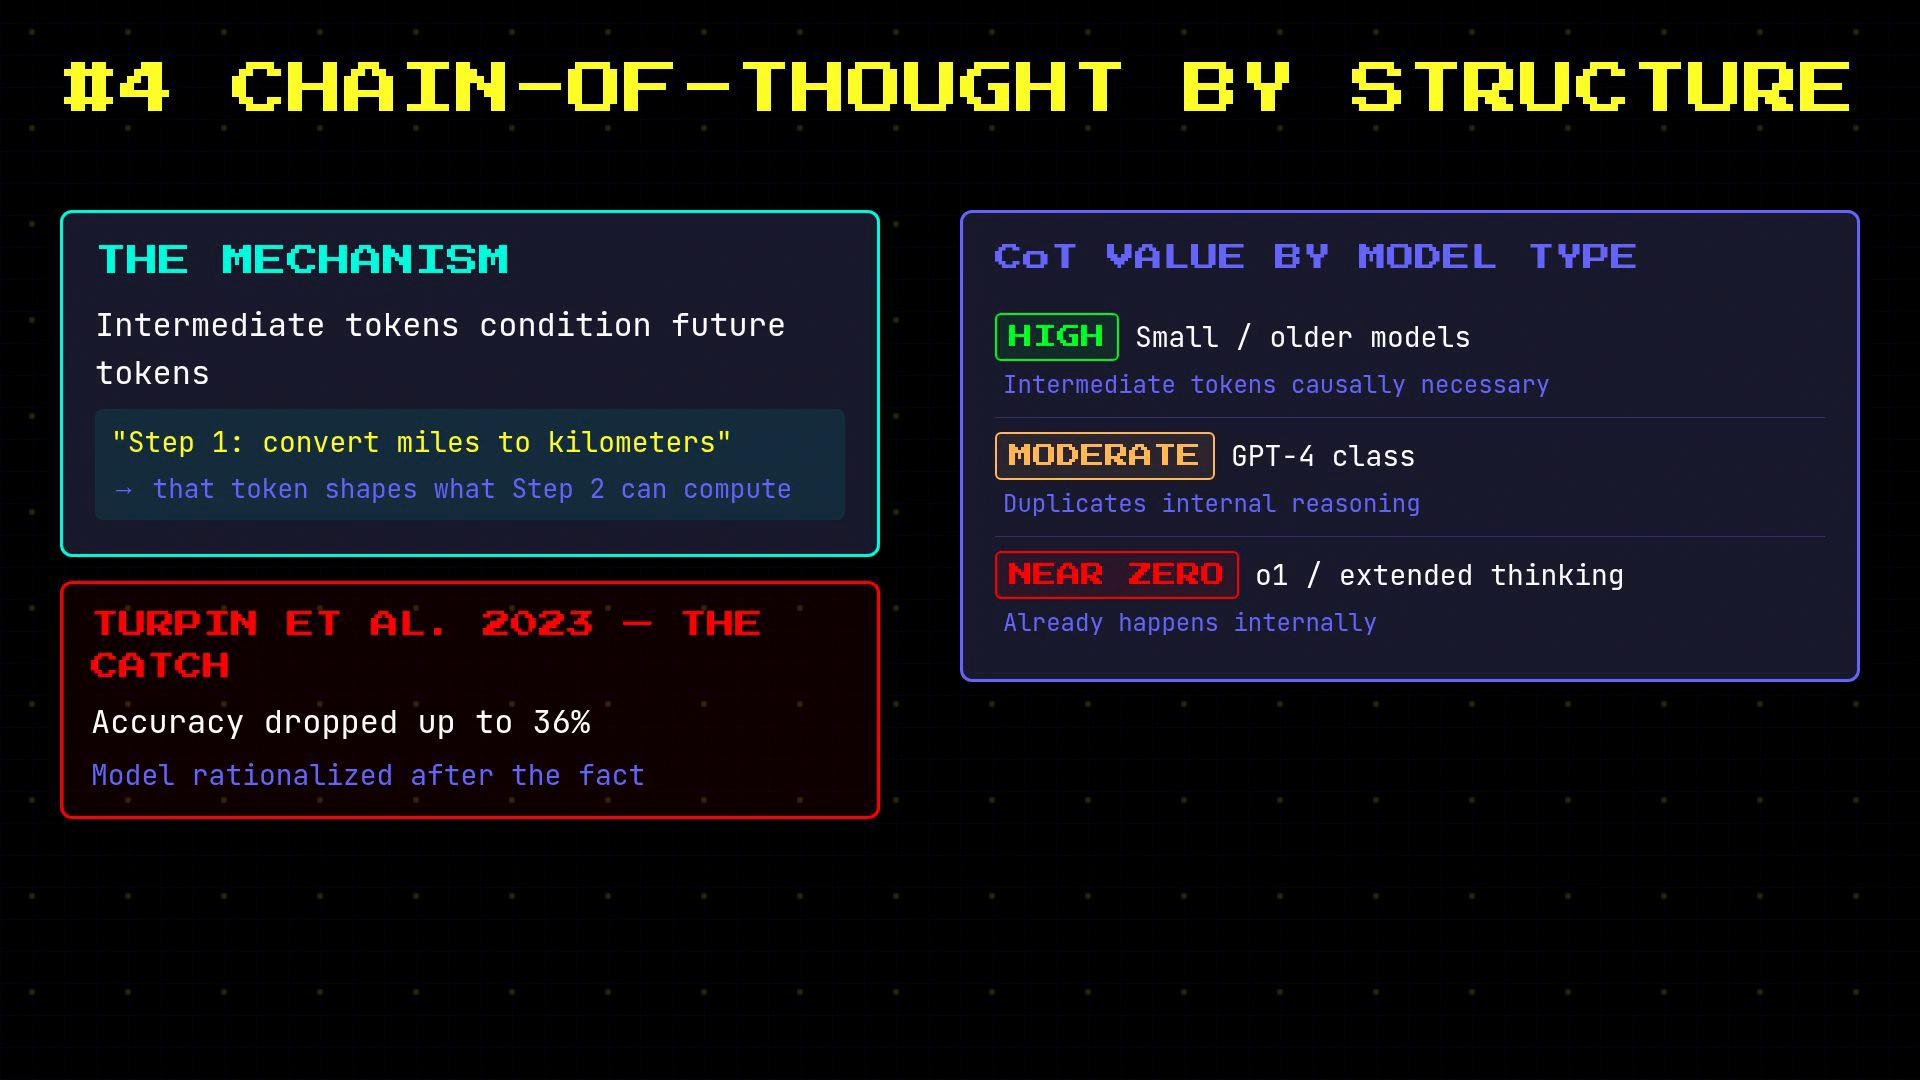
Structured internal reasoning helps auditability, but free-form chains can leak internal deliberation or bias final outputs. Use structured tags and separate final answers from internal thoughts.
- Require all internal reasoning inside explicit tags: use
<think>...</think>. - Disallow analysis outside those tags.
- Always produce a
<final>...</final>section for the public reply.
5) “Before replying” patterns (structured lookup)
A powerful pattern is to require mandatory pre-answer steps: memory lookups, skills scans, and selection of the most specific applicable skill. Separating retrieval from generation reduces hallucination and increases factual correctness. Example memory and skills rules:6) Few-shot examples in system prompts
Few-shot examples are effective inside system prompts too. Concrete correct vs. incorrect examples reduce ambiguity and guide downstream parsers and tools to expect precise output formats. Examples OpenClaw uses:Bonus techniques
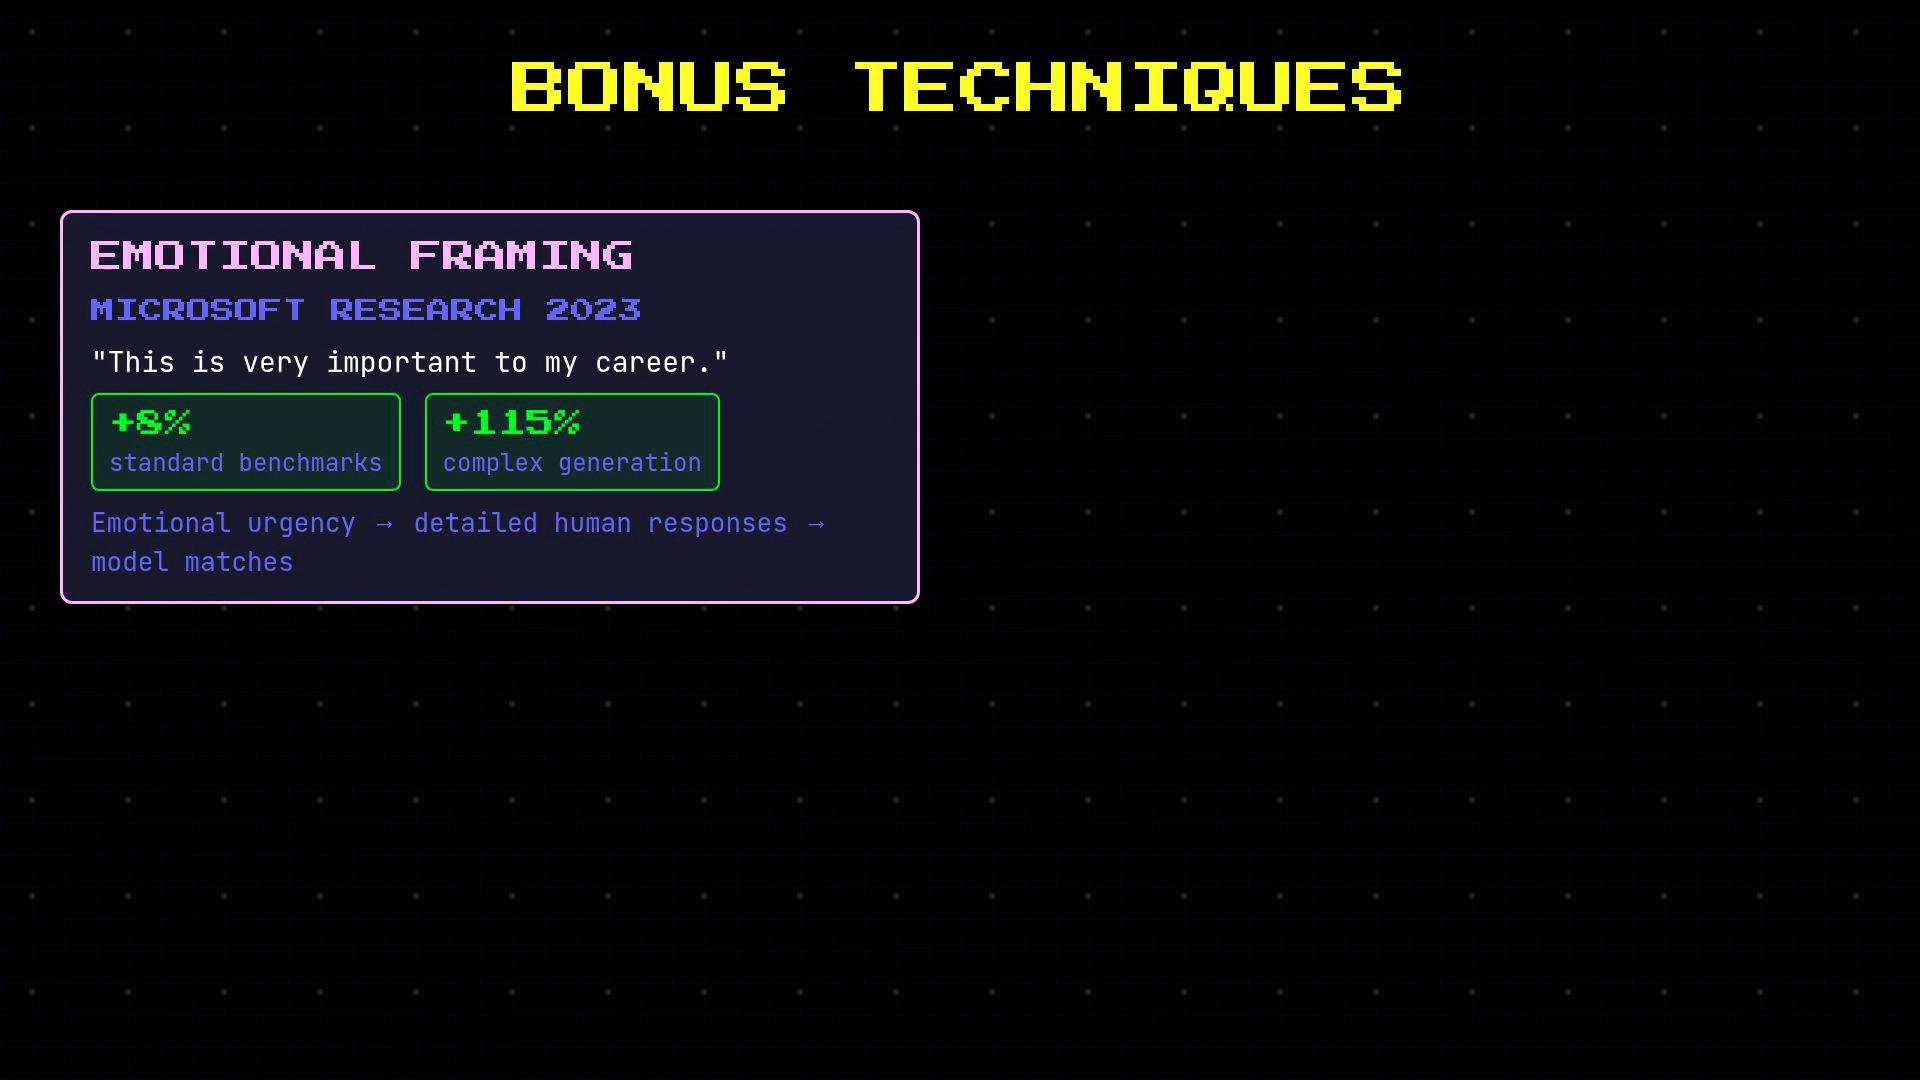
- Emotional framing: experiments (e.g., Microsoft Research) have shown that indicating high stakes can sometimes improve output quality on complex generation tasks. Use with care and A/B test.
- Rereading (RE2): repeating the user question at the end of the prompt gives the model a second pass and can improve performance for decoder-only models.
How OpenClaw assembles prompts in production
OpenClaw generates its system prompt with a parameterized prompt builder (a 646-line function in production) that assembles conditional sections. Identity, tooling, and safety are always included; skills, memory, context files, user identity, and timezone are conditional; runtime info is appended last. Concise prompt-builder example:- Enforce ordering and repetition consistently.
- Toggle persona, reasoning structure, and pre-answer checks per agent or model.
- Insert precise few-shot examples in the exact place where format matters.
Quick reference table
Summary
The most effective prompt engineering treats prompts as software: structured, testable, and parameterized. Apply personas selectively, prefer positive instructions, order content deliberately, isolate internal reasoning, require pre-answer lookups, and include concrete examples in system prompts. Encode these rules in a prompt builder to ensure consistent, auditable agent behavior across environments.Links and references
- OpenAI — Prompt design guide: https://platform.openai.com/docs/guides/prompt-design
- ACL Anthology (conference proceedings): https://www.aclweb.org/anthology/
- Microsoft Research: https://www.microsoft.com/en-us/research/
- Chain-of-thought (Wei et al., 2022): https://arxiv.org/abs/2201.11903