

Why move beyond frequency counts?
Statistical analysis (counts and co-occurrences) is useful, but limited. Frequency alone cannot explain meaning or relationships between words. Example: the words dog, puppy, cat, and kitten might have different frequency counts — e.g., dog 100, cat 80, puppy 20 — but frequency does not reveal that a puppy is a young dog or that a kitten is a young cat. Semantic models aim to capture those relationships so generative AI can produce meaningful responses. If you ask “What is a young dog called?” a model that understands semantics can answer “puppy” by recognizing the relationship between “young” and “dog.”From tokens to numbers: vectorization
Neural networks operate on numbers, so tokens like “dog” must be converted into numeric form. Vectorization maps each token to a numerical vector (an embedding) in a high-dimensional space. During training, models learn embeddings that reflect usage patterns and semantic relationships.
Why vectors capture meaning
Vectors place tokens in a metric space where distance or angle indicates relatedness. Common similarity metrics include cosine similarity and Euclidean distance. In simple visualizations, related words cluster together (e.g., cat, kitten, puppy, dog), while unrelated words (e.g., tree) lie farther away.Common relationship types
Semantic models capture more than synonyms. They learn hierarchical, categorical, and associative relationships.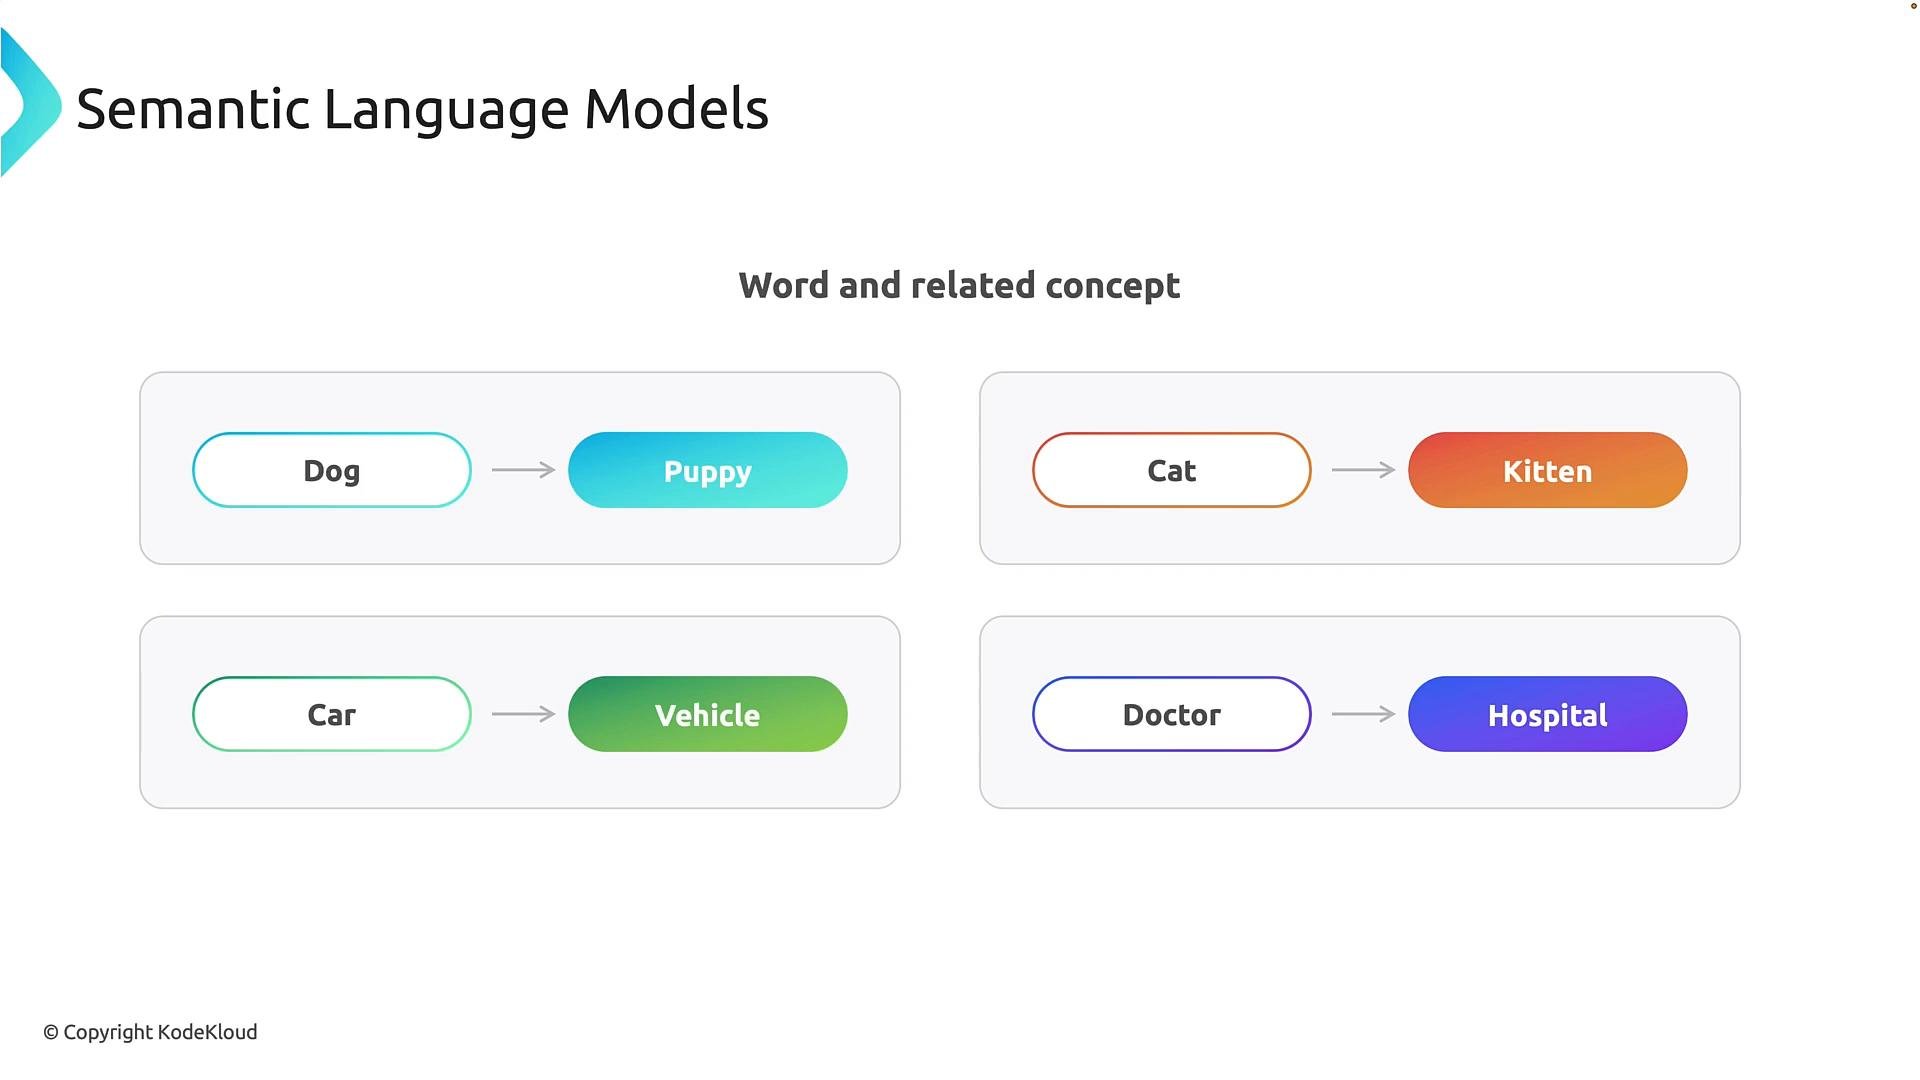
A simple mathematical intuition
Some semantic relationships are approximately reflected by arithmetic on vectors. The following simplified example illustrates this intuition:These arithmetic examples are illustrative and intended to build intuition. Modern transformer-based models learn highly non-linear relationships; they do not rely on simple vector addition to derive meaning.
How embeddings fit into the transformer LLM pipeline
Embeddings are the first numerical representation used by transformers. The end-to-end pipeline in most transformer-based LLMs looks like this:- Tokenization: Split input text into tokens (words or subwords, e.g., byte-pair encoding).
- Embedding: Map tokens to learned vectors; often add positional encodings.
- Transformer processing: Multiple layers use attention to model context and relationships among tokens.
- Decoding / prediction: The model outputs probabilities for the next token(s); repeated decoding generates text.

Inside transformers, attention weights determine how strongly tokens influence each other. For instance, attention helps resolve pronoun references: in “The dog chased the ball because it was excited,” attention helps identify what “it” refers to by weighing token relationships.
Summary
- Frequency counts and co-occurrence statistics are useful baselines but do not capture meaning.
- Semantic language models represent tokens as embeddings (vectors) that encode relationships and context.
- Related concepts cluster in high-dimensional embedding space; relationships include hierarchical, categorical, associative, and contextual types.
- Embeddings feed into transformer-based LLMs, which use attention mechanisms and many layers to generate text token-by-token.
Links and references
- AI-901: Microsoft Azure AI Fundamentals
- Transformer overview: https://arxiv.org/abs/1706.03762
- Introduction to word embeddings and cosine similarity: https://machinelearningmastery.com/what-are-word-embeddings/
If you want to experiment with embeddings, try producing small vector visualizations (e.g., via PCA or t-SNE) from pre-trained models to see how similar words cluster in practice.