

Single-pass vs. multi-step tasks
The simple flow most people are familiar with is a single prompt → single response:- Prompt: “What’s a good flight to New York City?”
- Model: returns a single answer.
- “Find me a flight to New York City for under $300 and book it.”
Core idea: start with a goal
An agent workflow starts with a goal (e.g., “flight < $300 and booked”). There is no single-model response that accomplishes this goal automatically. Instead the system must plan and coordinate actions over time. High-level agent cycle:- Decide (model produces a textual instruction about the next action).
- Act (a tooling/executor layer performs the action).
- Observe (results are returned to the model).
- Repeat (model uses the observation and goal to decide the next step).
How the loop works in practice
-
Decide
- The model generates a textual instruction (for example, “Search flights for 2026-12-15 to 2026-12-20, return lowest fares”).
- Remember: pretrained LLMs are token-prediction engines — they output text. They do not by themselves perform network requests or invoke APIs.
-
Act (tooling/executor)
- A separate software component parses the model’s decision and executes it: API calls, web searches, database queries, booking APIs, etc.
- This component bridges the model’s text and the real-world operation.
-
Observe
- The executor returns structured results (observations) to the system (e.g., “cheapest flight found: $340”).
- The model receives the observation and the original goal, then decides the next action (try different dates, another airline, or conclude).
-
Repeat
- This cycle continues until the model determines the goal is met or a stopping condition is reached.
Common decision patterns from models
Models often emit outputs in a structured form to make parsing reliable. Example formats include short natural-language steps, JSON objects describing an action, or pseudo-API calls. System designers should constrain and validate these outputs before executing them.Termination and stopping conditions
- The model will typically output an instruction that indicates completion (e.g., “Done: booked flight under 300”).
- Stopping conditions are often determined by the model’s judgment rather than an externally hard-coded counter like “stop after 3 tries.” This grants flexibility, but systems should still enforce external limits:
- maximum iterations
- timeouts
- rate limits
- safety filters
Agent components at a glance
Why this distinction matters
- An agent is not a distinct model type — it’s a pattern: model decisions + external tool executions + returned observations in a loop.
- Any LLM can be part of an agent if it participates in this Decide → Act → Observe cycle.
- Because models can suggest actions with real-world effects, you must design safety controls:
- validate model outputs before execution
- sandbox or simulate risky actions
- require human approval for critical operations
- log actions and decisions for auditing
Practical guidance for building safe agent executors
- Validate and sanitize every decision output before mapping to an API call.
- Limit the scope of actions the executor can perform.
- Implement role-based permissions and explicit human-in-the-loop checkpoints for sensitive tasks (payments, sensitive data access).
- Use timeouts and iteration caps to prevent runaway loops.
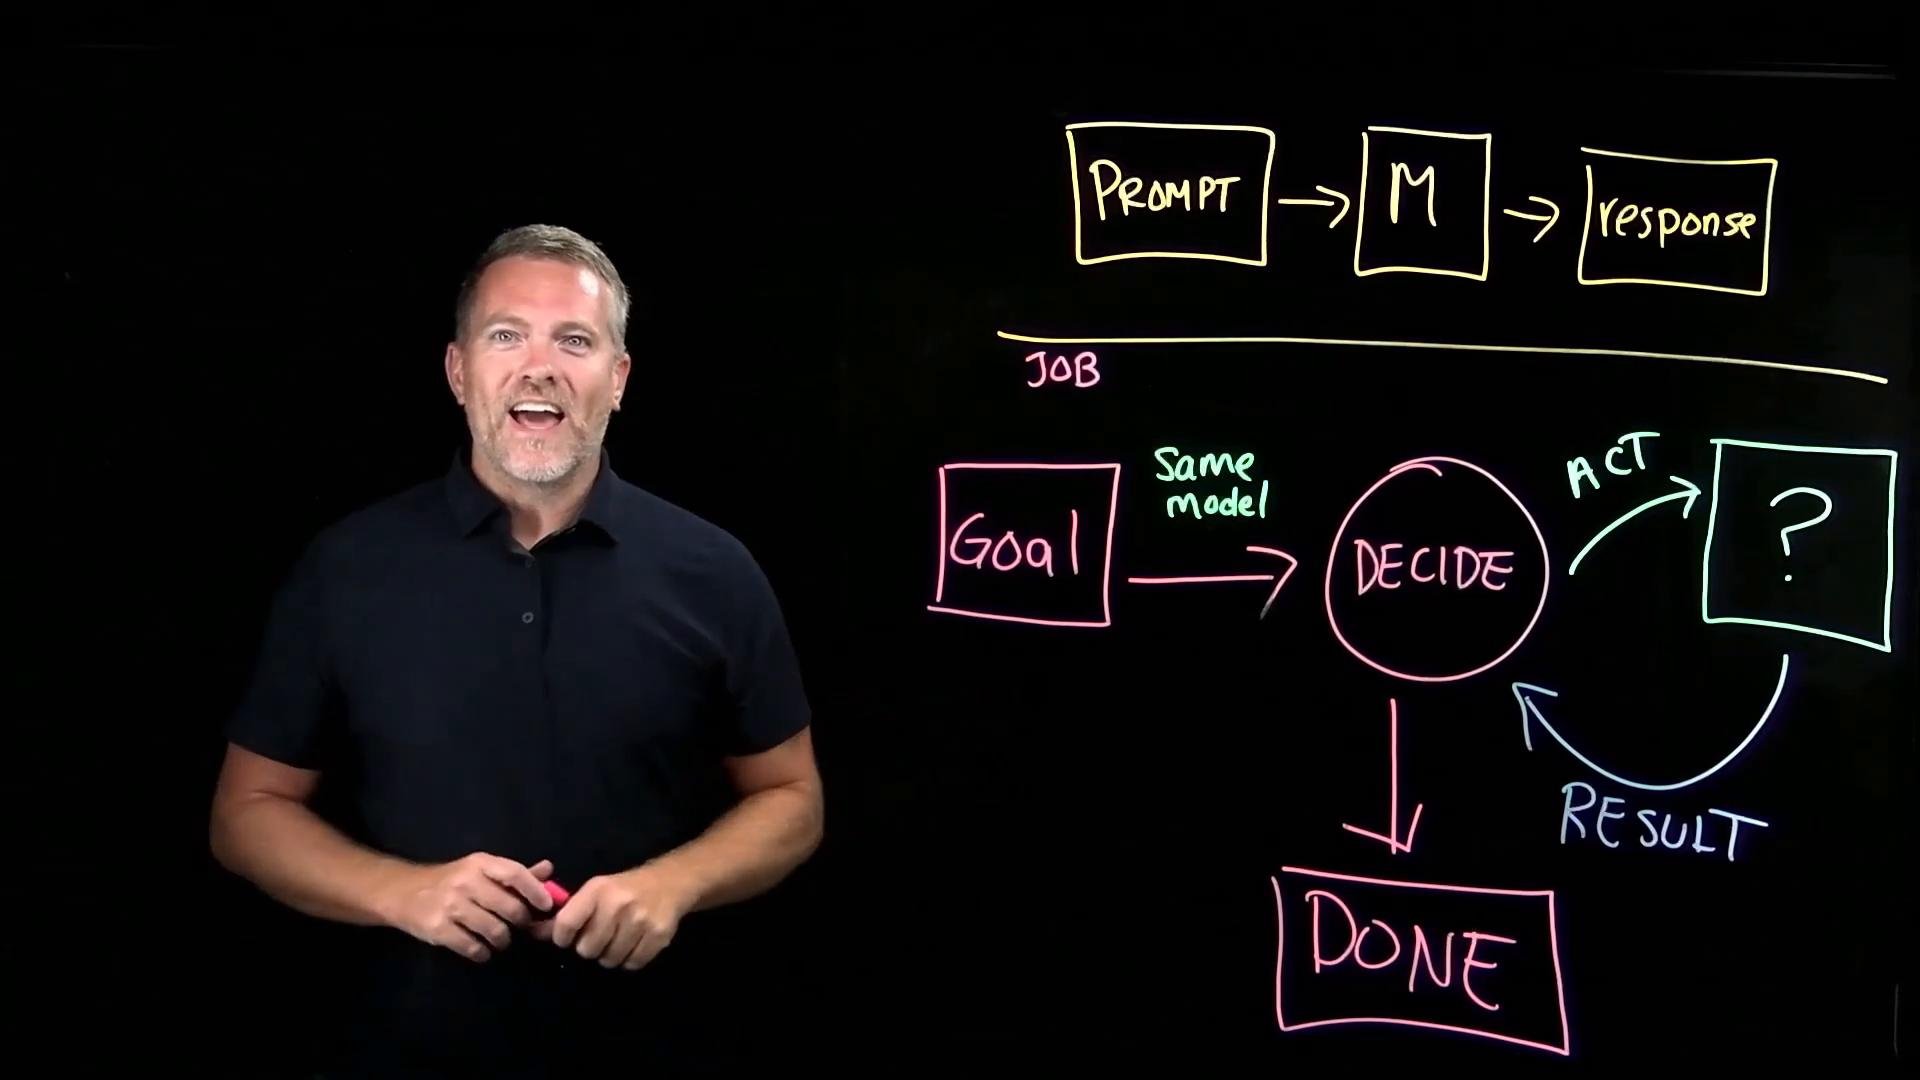
An agent is the repeated cycle of
decide → act → observe. The model supplies decisions (text); a tooling layer executes those decisions and returns observations. The interaction of these components, not a special model, is what creates an agent.Because the model’s decisions can trigger real-world effects, always design agent executors with safety constraints and consider a human-in-the-loop for critical actions.
Links and references
- ReAct: Synergizing Reasoning and Acting in Language Models
- LangChain — tools and orchestration patterns for LLM agents: https://langchain.com/
- Best practices for safe API design and auditing — apply standard security hygiene to agent executors.