

How these models work (high level)
- A pretrained language model is a frozen set of learned parameters (weights) captured when training ended. It does not contain a live database, search index, or an internal table of facts.
- Its fundamental mechanism is next-token prediction: given a prompt, it repeatedly predicts the most likely next token to generate text.
- That prediction loop has no built-in truth-checker or “no results found” gate. The base model generates continuations that look plausible based on patterns seen during training.
- Many deployments add retrieval, tool use, or verification layers which alter behavior, but those are external systems built around the model — not part of the core prediction loop.
- Common question:
- Prompt: “Who wrote Romeo and Juliet?”
- This appears frequently across books and guides, so the model reliably outputs: Shakespeare.
- Niche question:
- Prompt: “Is there a flag to disable telemetry in
internal-tool?” - Training data likely contains little or nothing about this private tool. The model has seen many examples of command-line flags and will finish the pattern with something plausible (e.g.,
--no-telemetry) — formatted and confident but possibly fabricated.
- Prompt: “Is there a flag to disable telemetry in
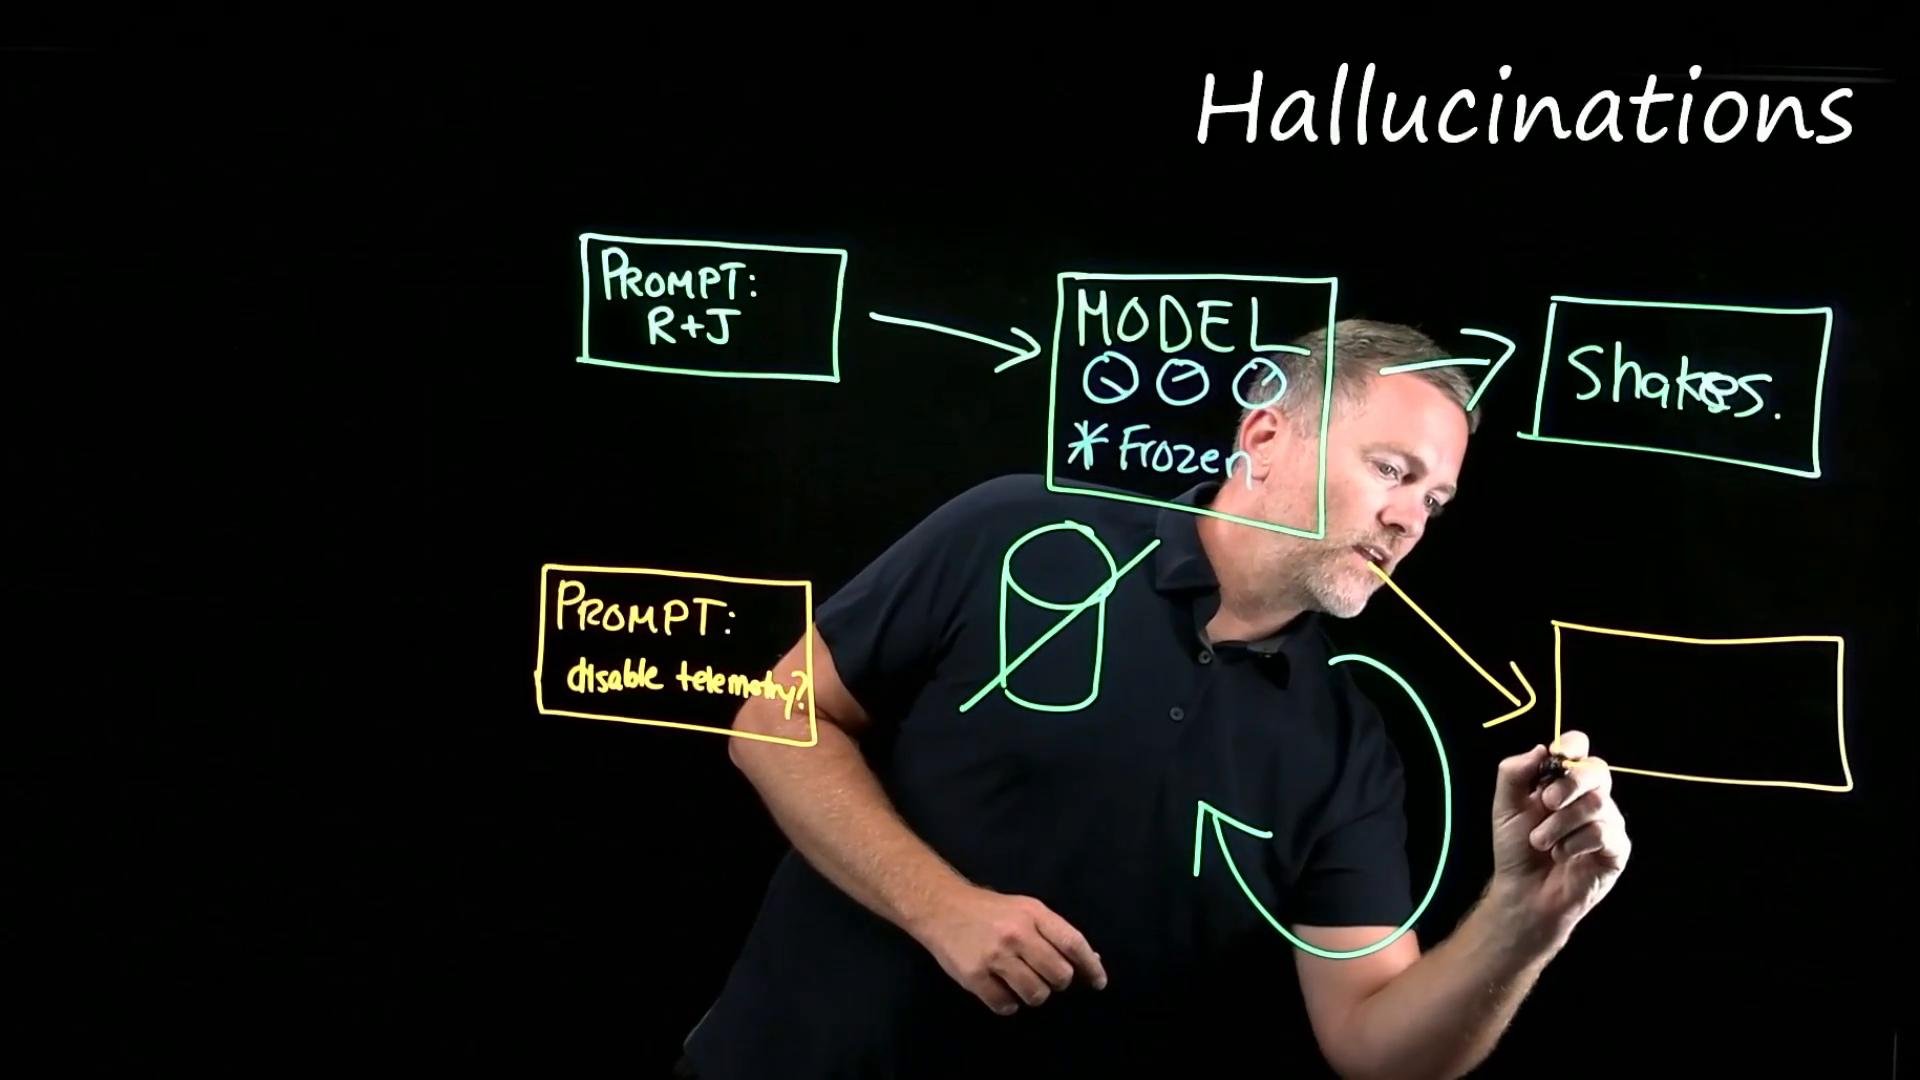
Key takeaways about hallucinations
- The model is a plausibility machine: it predicts what comes next based on learned patterns, not by looking up facts.
- Plausible does not equal true — fluent and confident text can still be incorrect.
- Hallucinations are more likely for:
- Niche or internal facts (private tools, internal APIs),
- Specifics such as URLs, citations, quotes, and version numbers,
- Information created after the model’s training cutoff.
- Confidence or fluent tone is not a reliable indicator of correctness.
Can we eliminate hallucinations?
- You can reduce hallucinations but you cannot remove them completely.
- Newer and better models tend to hallucinate less, but they are still error-prone.
- Adding retrieval, grounding, or verification systems reduces risk: these components supply up-to-date, authoritative evidence that the model can cite.
- There is no single “hallucination module” you can unplug — the same model that handles common facts will invent details on thin topics unless supported by external verification.
Practical mitigations — checklist and techniques
Practical tips:
- Validate any high-risk outputs (citations, URLs, legal/medical facts, software flags) with authoritative sources.
- Prefer direct verification for things after the model’s cutoff date.
- Treat model-generated specifics as drafts that require human validation.
Remember: prediction, not lookup. Most of the time plausible outputs are correct — which is why these models are useful — but the rare incorrect outputs are dangerous because they sound convincing. Always verify critical specifics.
References and further reading
- Fundamentals of RAG — https://learn.kodekloud.com/user/courses/fundamentals-of-rag
- Hallucination (artificial intelligence) — https://en.wikipedia.org/wiki/Hallucination_(artificial_intelligence)