

- Foundations: what system design is, how to capture functional and non-functional requirements, and how to reason about capacity limits. You’ll learn when a single server becomes a bottleneck and how load balancers and horizontal scaling address that.
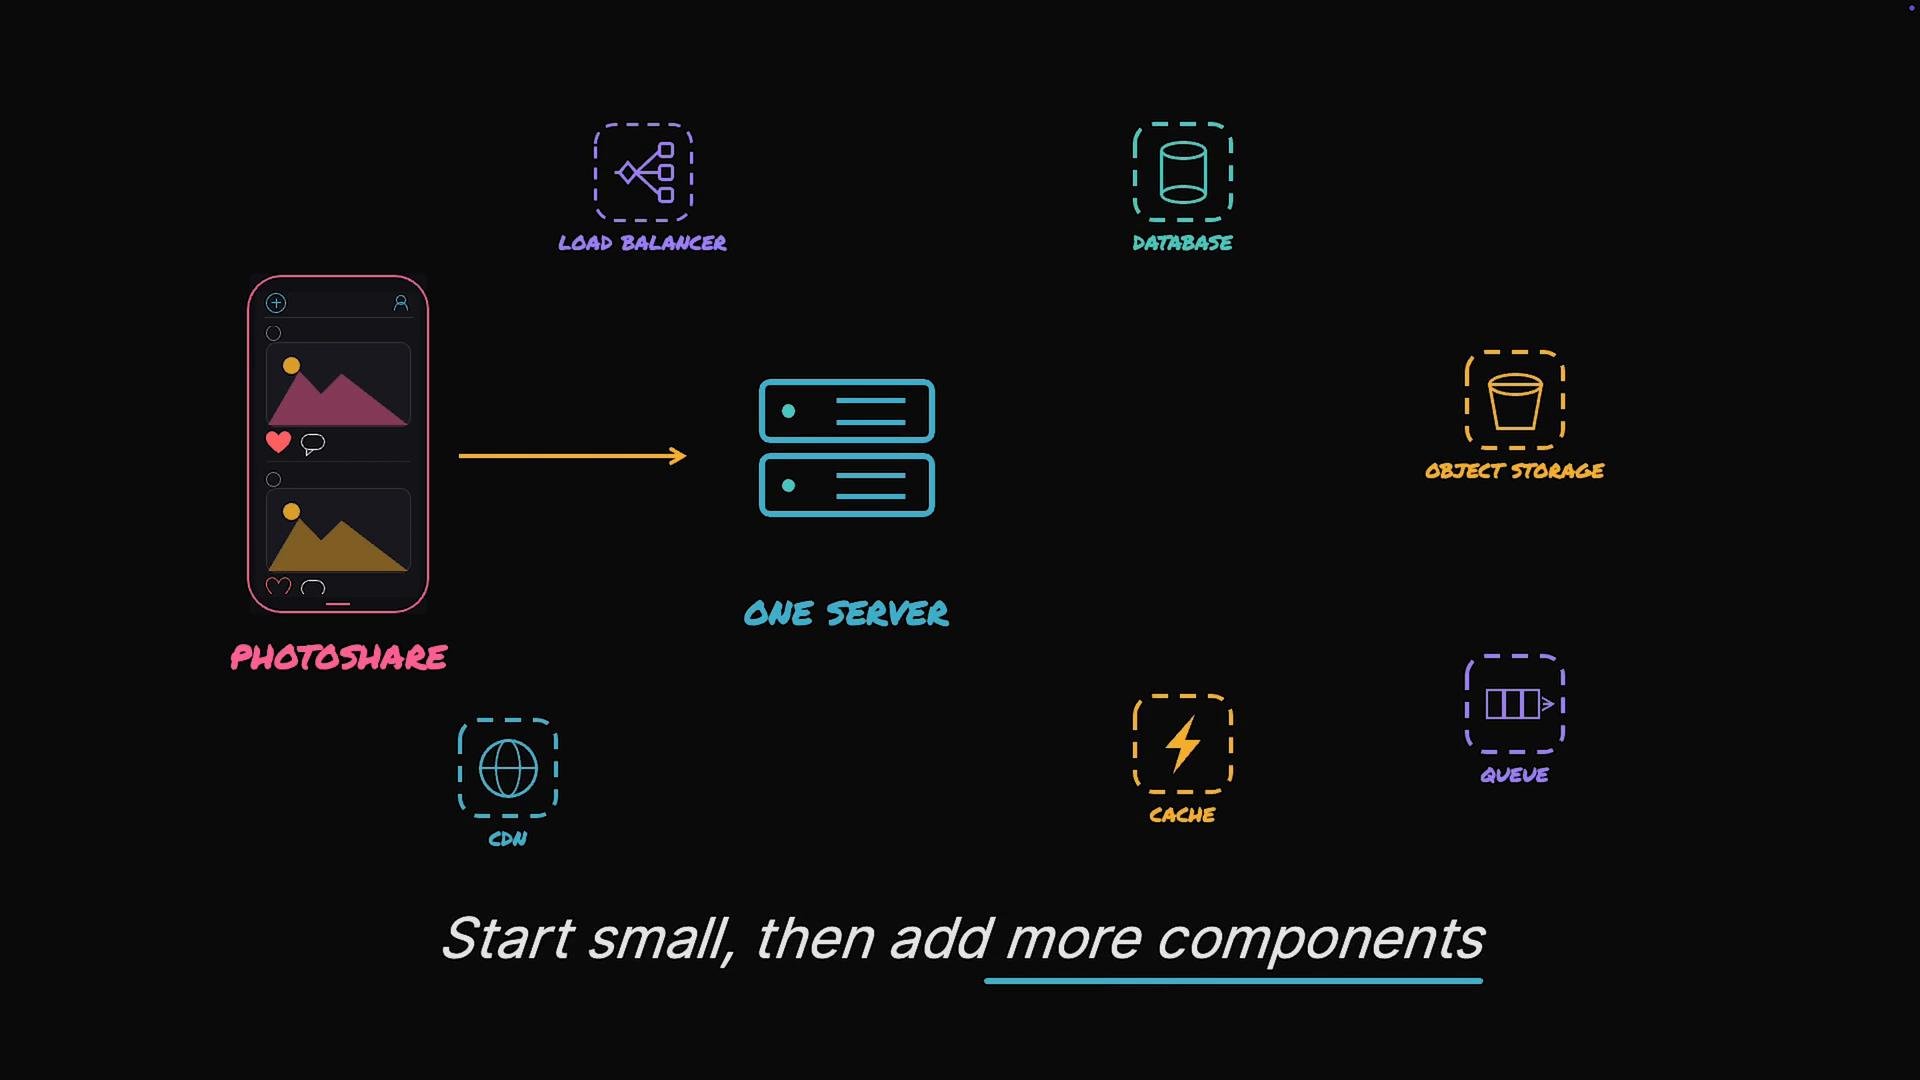
- Data: modeling data for typical access patterns, choosing between SQL and NoSQL, and applying indexes, caching, replication, and sharding to keep databases performant as traffic grows.
- Storage and Delivery: where uploaded images live, how object storage and CDNs cache and deliver media worldwide, and how background processing and message queues offload slow or CPU-bound work.
- Reliability and Operability: designing for inevitable failures by identifying single points of failure, implementing timeouts and retries, applying rate limiting, and instrumenting monitoring and alerting so you detect and resolve incidents quickly.
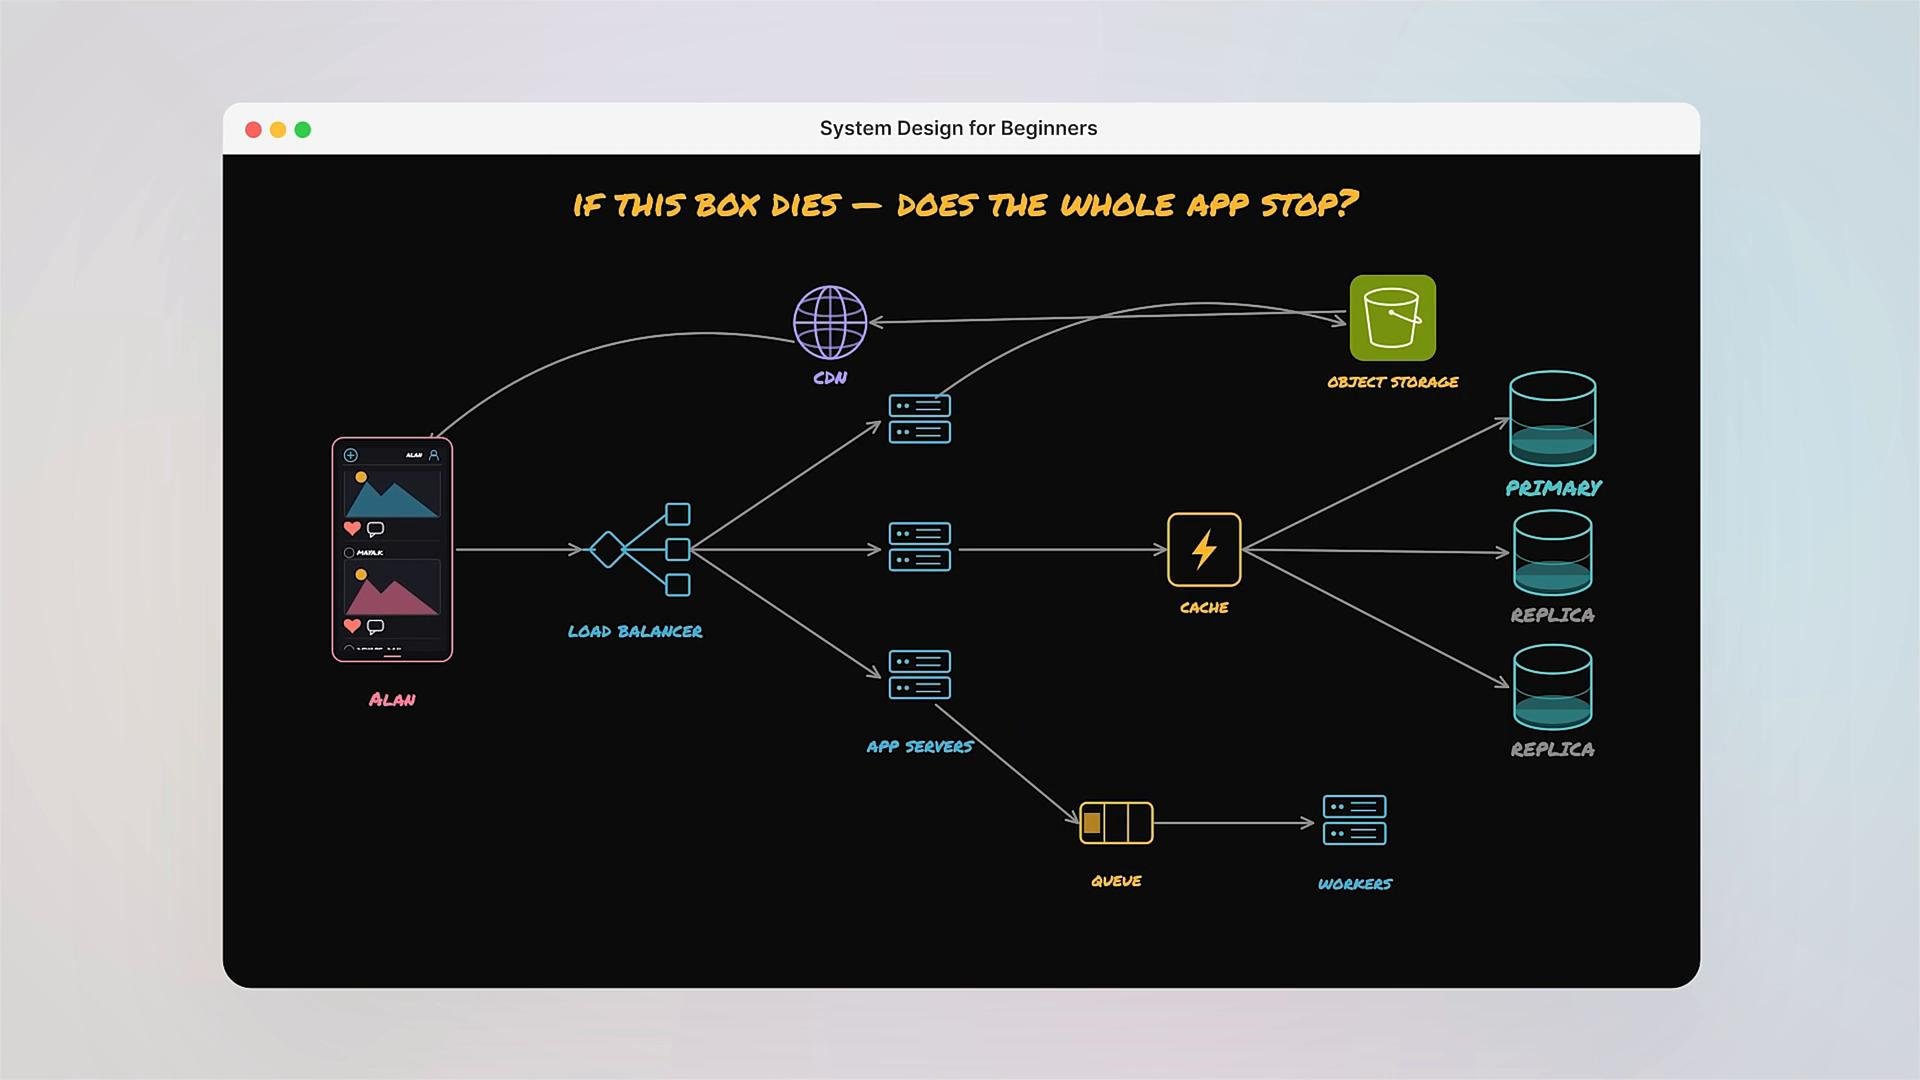
- Conceptual learning tied to a single, evolving application architecture so you can see how pieces interact.
- Practical labs where you intentionally break parts of the system and observe how the system responds.
- Reusable patterns and trade-offs for performance, cost, reliability, and operability.
Hands-on labs
This course includes seven labs that reinforce theory with practical experiments. Labs are intentionally fault-injecting so you can learn how components behave under failure — for example, stopping a container to watch how services restart and background workers process queued jobs.
Example lab output (uploader + thumbnail worker):
- Observe end-to-end behavior when parts fail (e.g., DB or worker outages).
- Validate that load balancers and replicas route traffic correctly.
- Inspect logs and metrics to diagnose issues and verify recovery.
If you get stuck, ask questions in the community — instructors and peers are available to help. You’ll progress faster by sharing logs, diagrams, and specific failure symptoms.