Congratulations on completing this lesson on Chaos Engineering with AWS Fault Injection Simulator. You’ve learned how to inject failures safely, observe system behavior, and build continuous resilience into your distributed applications.

Modern Resilience Challenges

Organizations today must navigate:
  • Customer expectations for always-on services
  • Complex, distributed architectures managed by remote teams
  • The need for frequent, reliable releases
By embedding resilience practices into every stage of your development lifecycle, you’ll proactively uncover weaknesses and prevent outages.
For detailed guidance on AWS Fault Injection Simulator, see the AWS FIS User Guide.

Continuous Resilience Lifecycle

This circular flow represents the iterative process that keeps your systems robust:
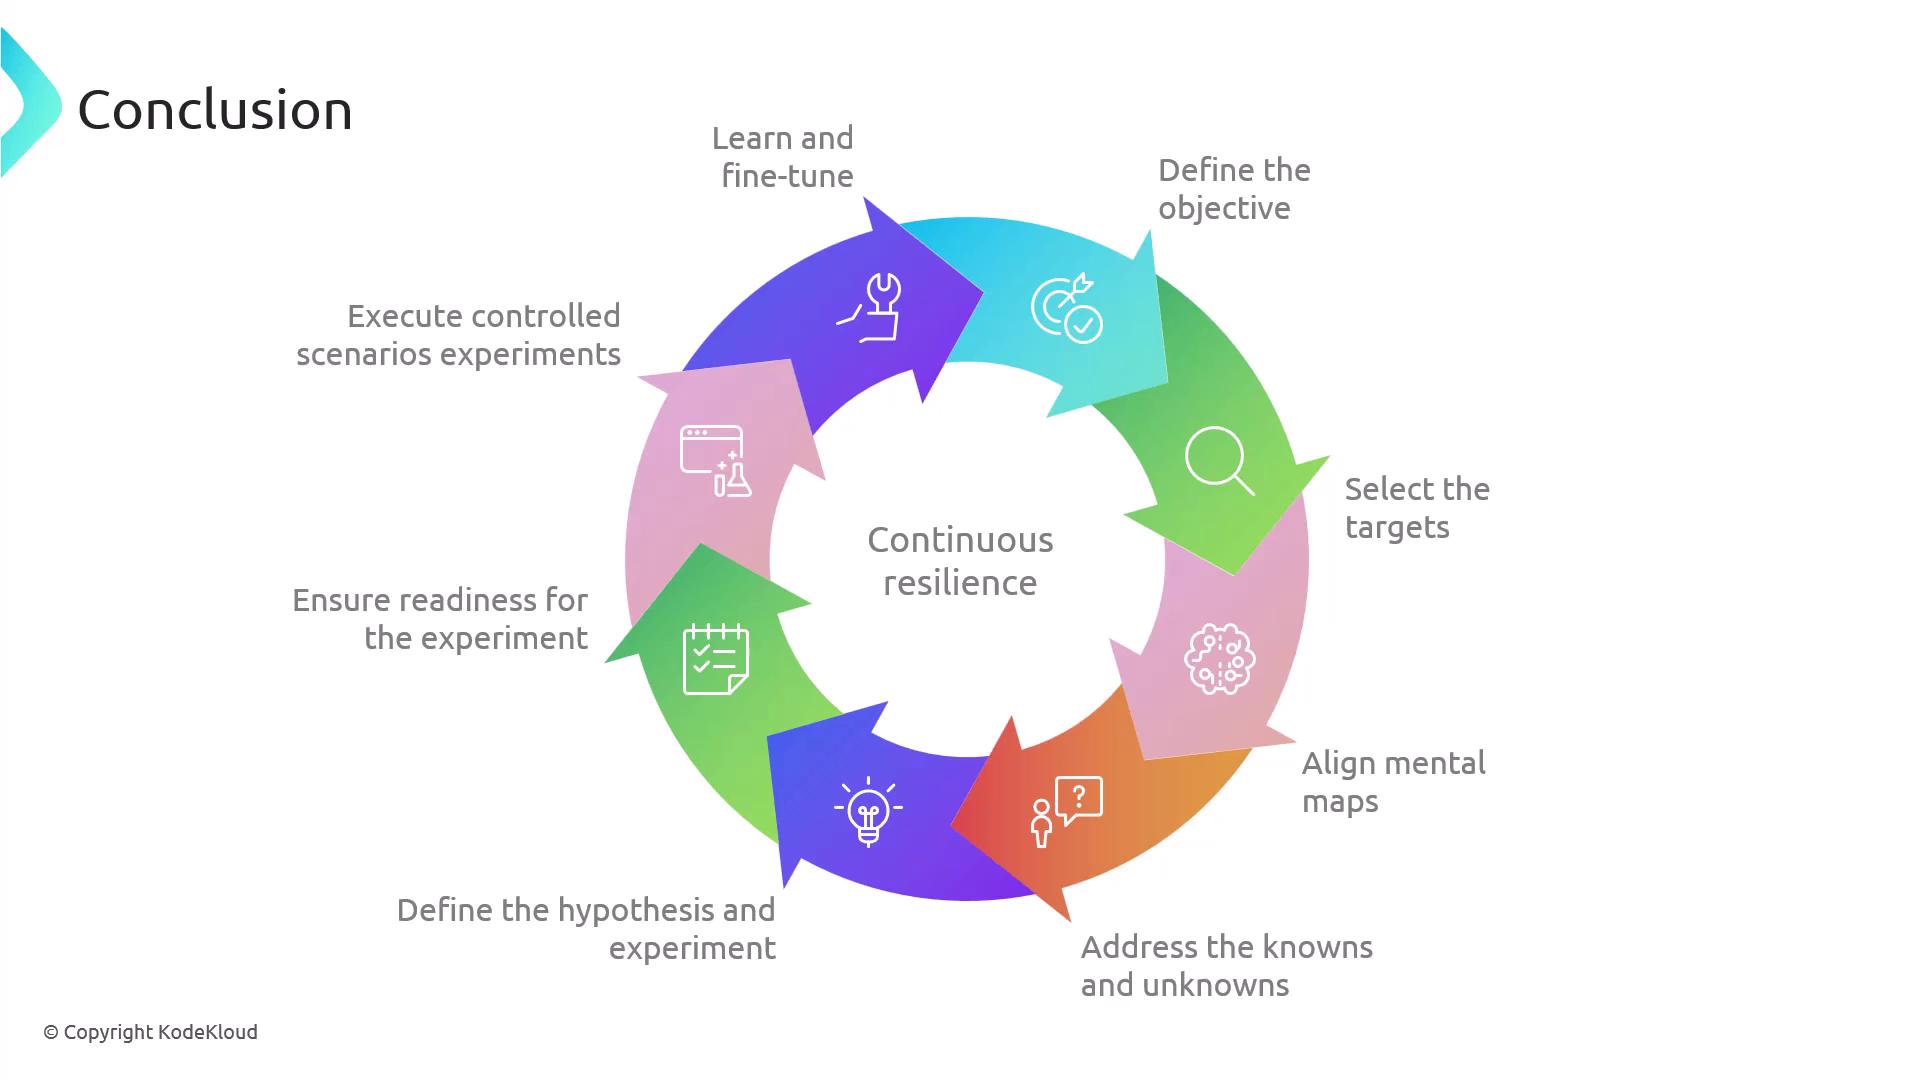
The image is a circular flowchart illustrating a process for "Continuous Resilience," with steps including defining objectives, selecting targets, aligning mental maps, addressing knowns and unknowns, defining hypotheses, ensuring readiness, executing experiments, and learning and fine-tuning.

Step-by-Step Breakdown

Always perform chaos experiments in a staging or non-production environment first. Double-check IAM permissions, backups, and monitoring before injecting faults.
By weaving these steps into your sprint cycles, you’ll continuously validate your system’s ability to withstand disruptions. Thank you for joining this journey—I’m Nasia Ullas, and I look forward to seeing how you apply these practices to build more resilient, reliable applications. Good luck!

Watch Video