

Pipelines as containerized DAGs
With Kubeflow you author ML workflows as pipelines expressed as DAGs. Each pipeline step runs in its isolated container, so steps can fail independently, be retried, and take advantage of caching. That design makes it straightforward to automate end-to-end ML processes and to reason about failures, retries, and where to add observability.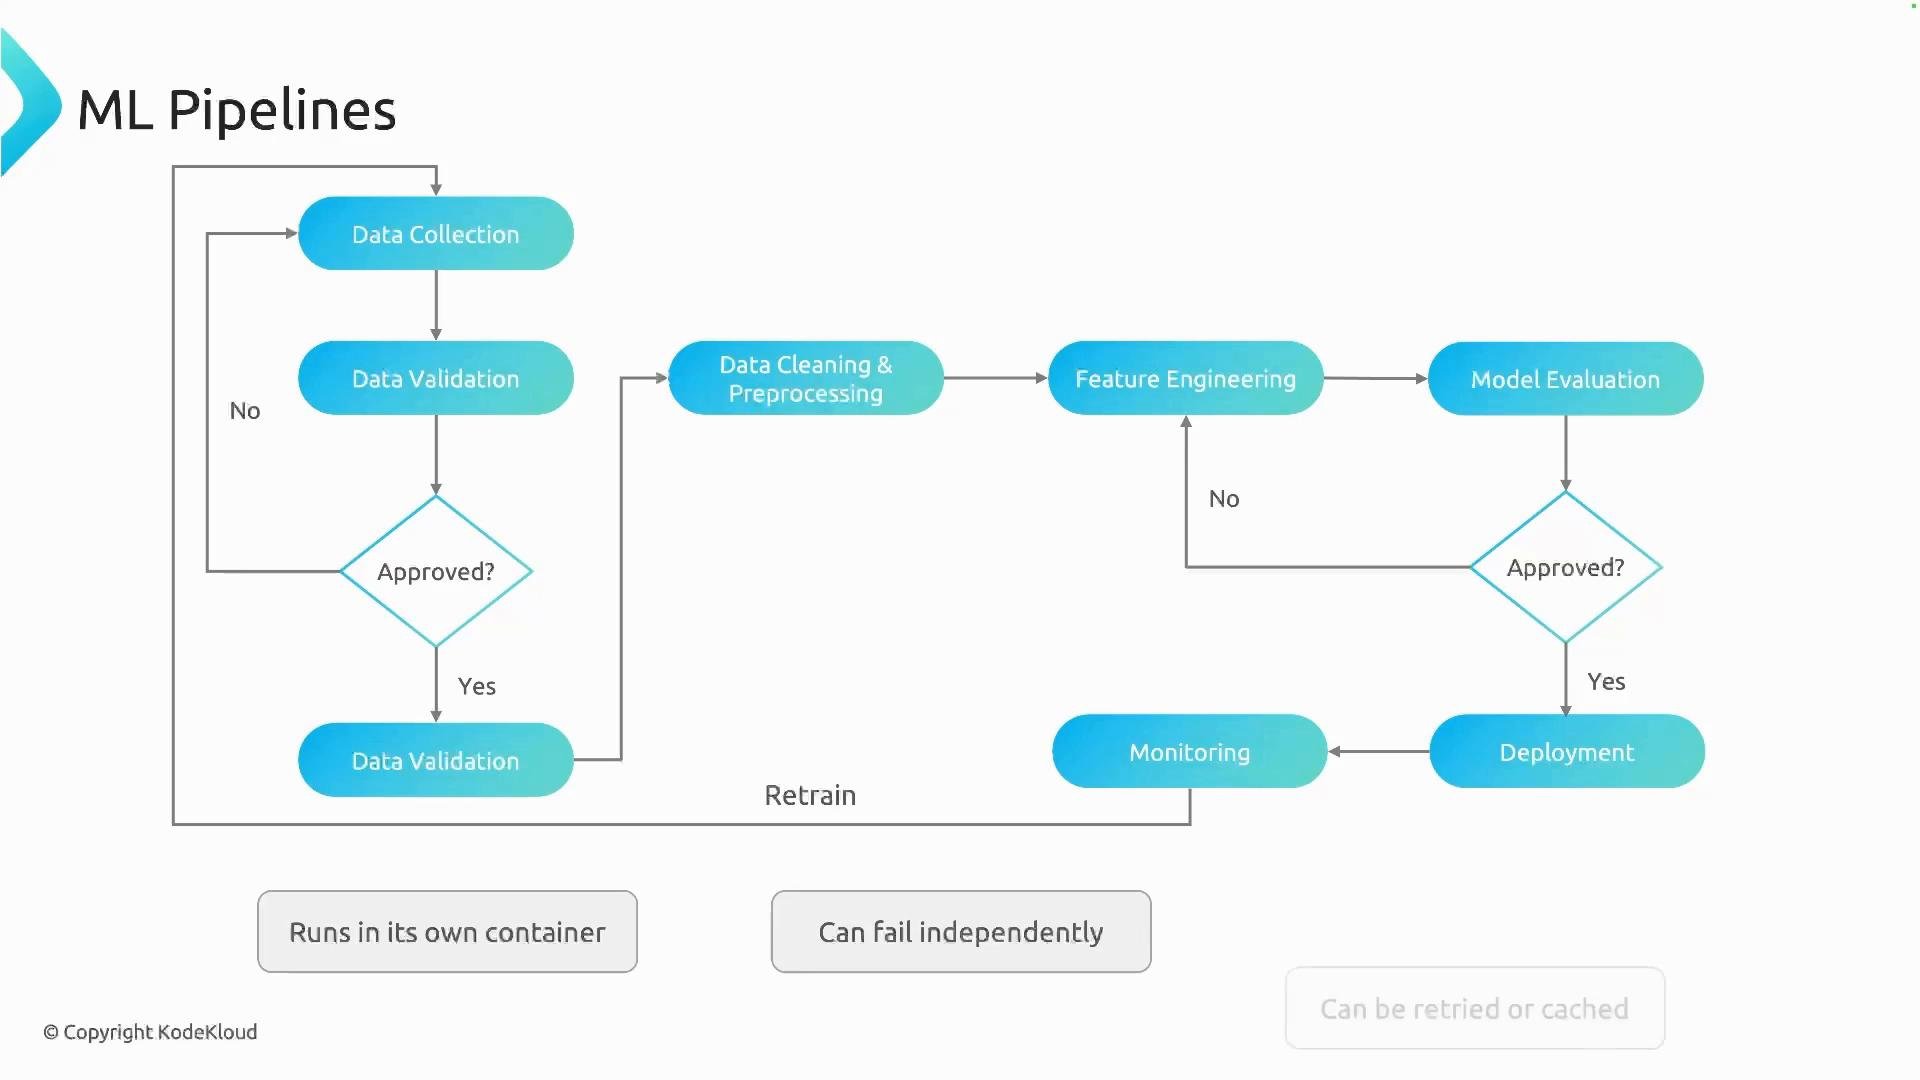
Reproducibility and experiment tracking
Reproducibility is a central benefit. Kubeflow captures pipeline definitions, run metadata, parameters, and environment details (for example, container images and resource requests). Because artifacts and pipeline specs can be versioned or tied to immutable artifacts, experiments can be rerun identically — making results explainable and enabling deterministic debugging so research becomes production-ready.
Track parameters, container image tags, and artifact locations for each run. This metadata is essential for comparing experiments, auditing results, and performing rollback to previous artifacts.
Scalability on Kubernetes
Kubeflow runs on Kubernetes, so training and inference workloads scale from a single GPU to many. Kubernetes schedules resources efficiently and supports multi-tenant isolation via namespaces and admission controls. This removes the need for manual server management, custom autoscaling code, and fragile orchestration logic.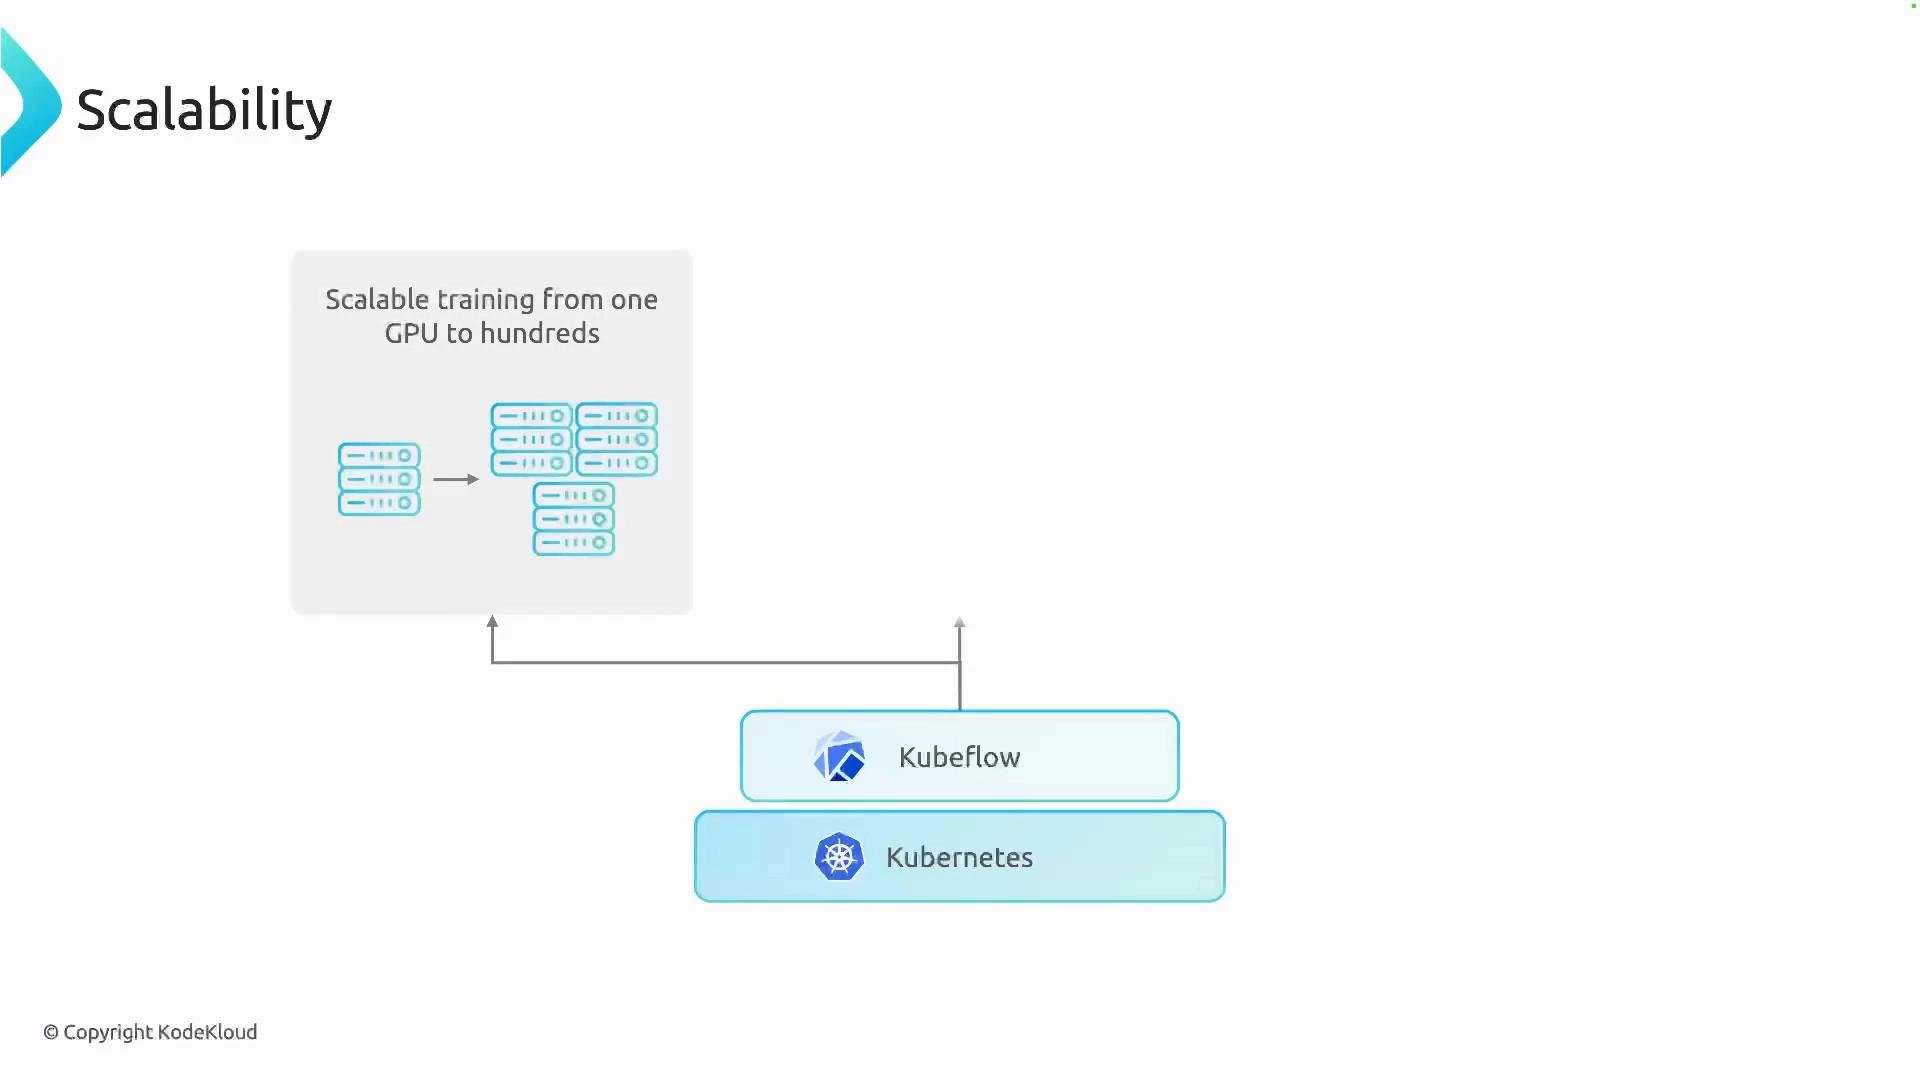
Model registry and metadata management
Kubeflow integrates metadata tracking and model registries so trained models are stored and managed through their lifecycle. Model versioning and metadata let teams correlate models with training data, hyperparameters, and evaluation metrics — similar to how Git tracks code, but for ML artifacts. That correlation is crucial for reproducible deployments and safe rollouts.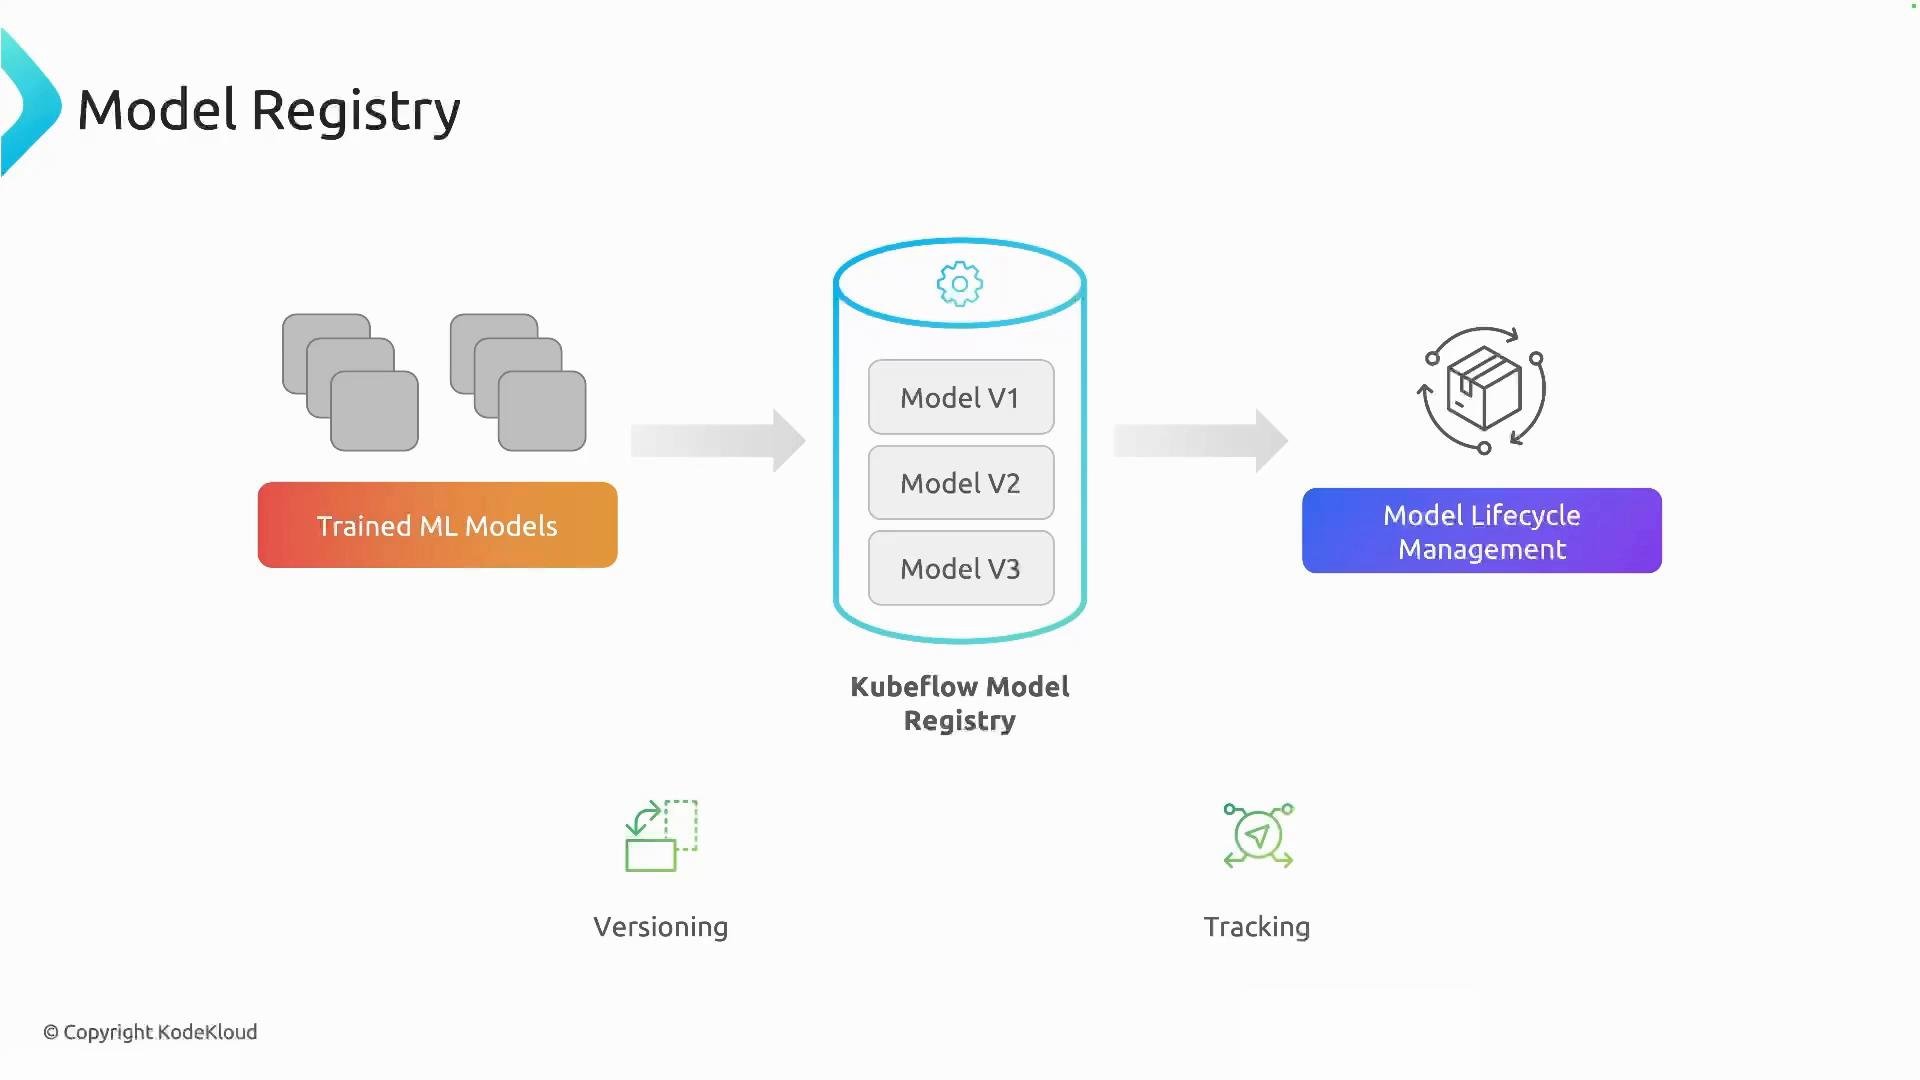
Notebooks and development environments
Data scientists commonly use Jupyter Notebooks for exploration. Kubeflow provides managed notebook servers with GPU access and namespace isolation so teams can run notebooks in consistent, shareable environments without interfering with other projects or resources.Model serving with KServe
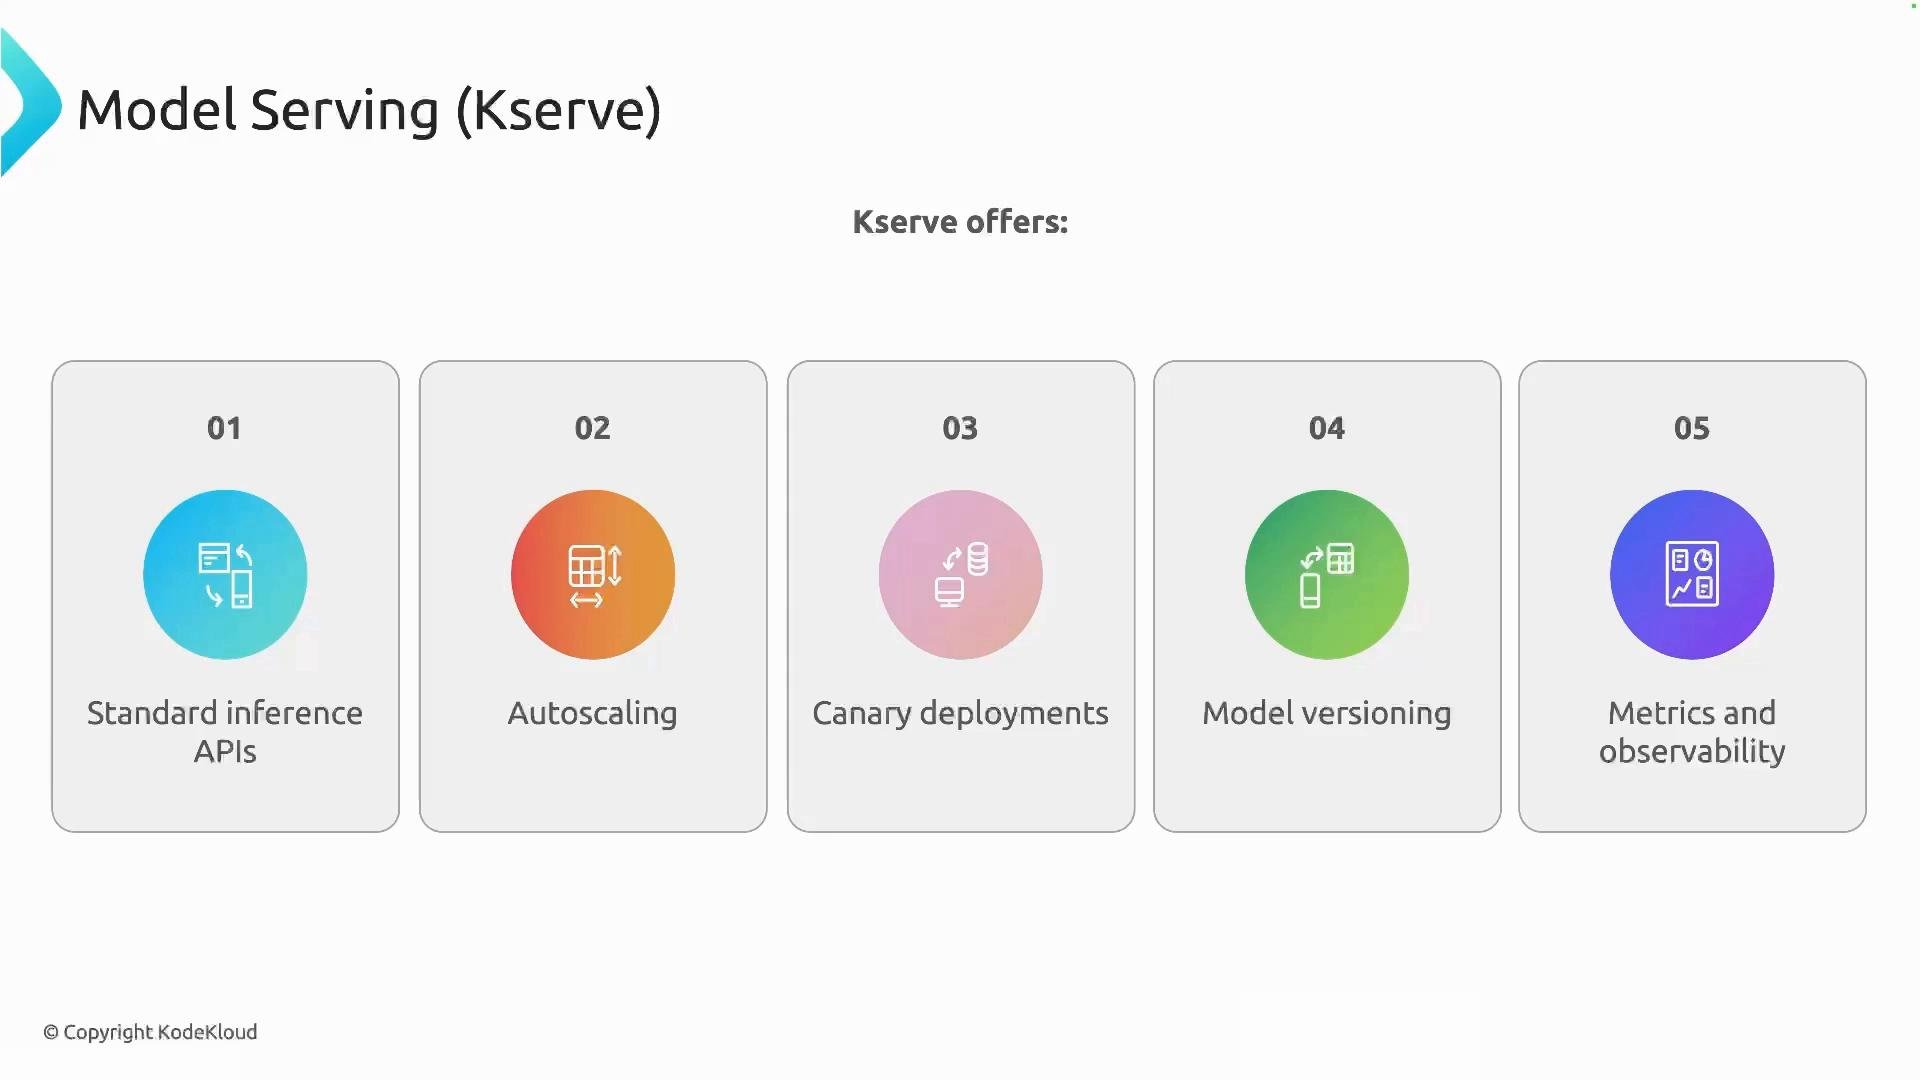
When models are ready for inference, Kubeflow supports serving via KServe. KServe simplifies model deployment and exposes standard inference APIs while providing built-in autoscaling, canary rollouts, model versioning, and observability. These features remove the need to build custom serving stacks (for example, a bespoke FastAPI + autoscaler + deployment pipeline).- Learn more: KServe Fundamentals: Serving ML Models on Kubernetes
- Example lightweight REST framework often paired with custom endpoints: FastAPI
Portability across environments
Because Kubeflow is open source and built on Kubernetes, it is portable across public clouds (AWS, GCP, Azure), on-premises clusters, and hybrid deployments. This portability lets teams standardize their ML platform independently of infrastructure vendors.Quick comparison: Benefits at a glance
Further reading and references
- Kubernetes Basics
- Kubeflow official documentation
- KServe Fundamentals: Serving ML Models on Kubernetes
- FastAPI — high performance web APIs for Python