

train_model— simulates training and accepts hyperparameters.evaluate_model— simulates model evaluation.
Hardcoded pipeline (problem)
In this version theepochs and lr values are fixed inside the component, so every run uses the same hyperparameters.
How pipeline parameters work (overview)
- Declare parameters as arguments to the
@pipelinefunction and give them default values if desired. - Make the component accept the corresponding arguments.
- Forward the pipeline parameters to the component when constructing the pipeline tasks.
Pipeline parameters are ideal for hyperparameters, dataset locations, or any run-specific configuration. Declaring defaults keeps runs reproducible while allowing overrides in the UI or via the API.
Parameterized pipeline (recommended)
Below is the same pipeline updated to acceptepochs and lr as pipeline parameters. When you upload the compiled pipeline, the UI will expose these fields so users can override them for each run.
ml_pipelinedeclaresepochsandlr(defaults:10and0.01).- When creating a run in the Kubeflow Pipelines UI or via API, you can override these defaults.
- The pipeline forwards those values into
train_modelat runtime.
Compile the pipeline
Generate the pipeline package (YAML) with:python pipeline.py
@component decorator. This is informational; see the warning callout below.
You may see a FutureWarning about the default base image changing in a future SDK release. To avoid surprises, specify an explicit
base_image when using @component, or ensure your component is compatible with the newer Python version.Upload the compiled pipeline to Kubeflow
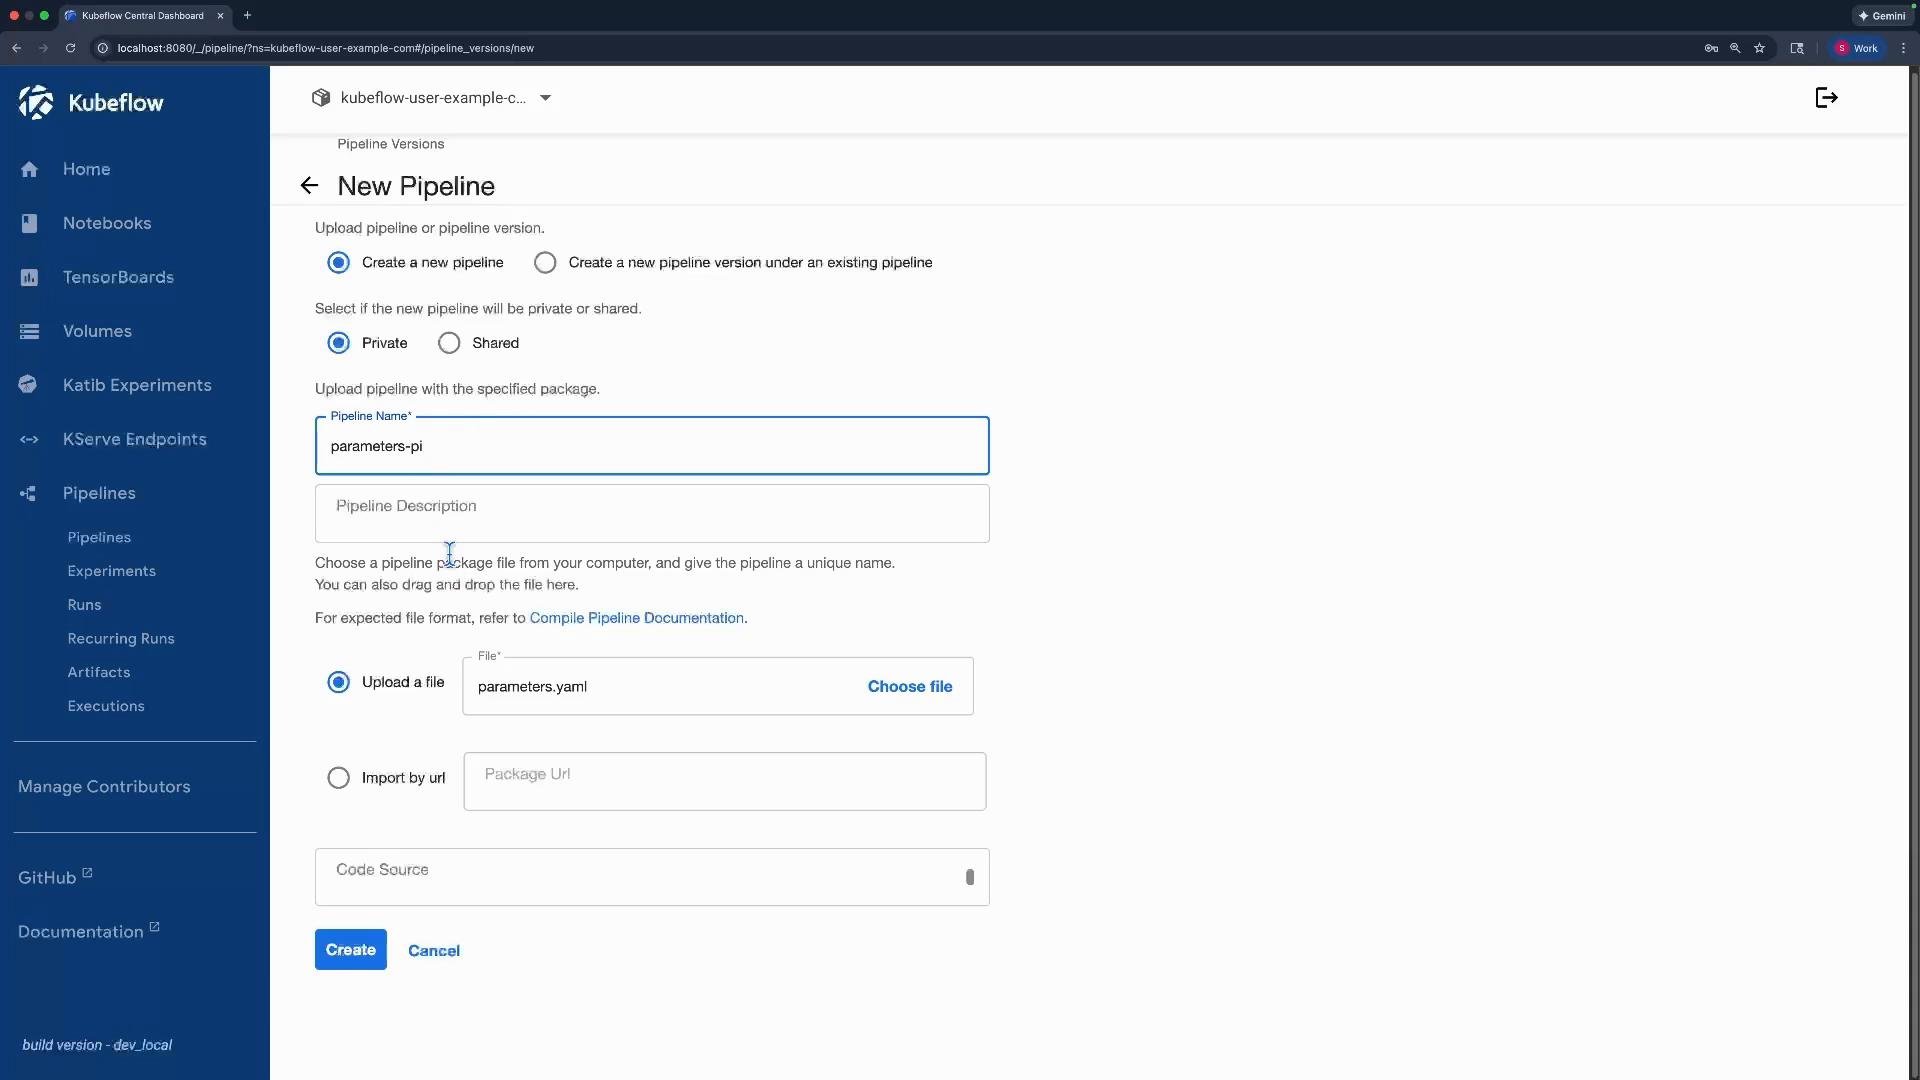
- In the Kubeflow Pipelines UI, upload the generated
parameters.yamland create a new pipeline.
Start a run and supply parameter values
- Click “Create run” (select an experiment if needed).
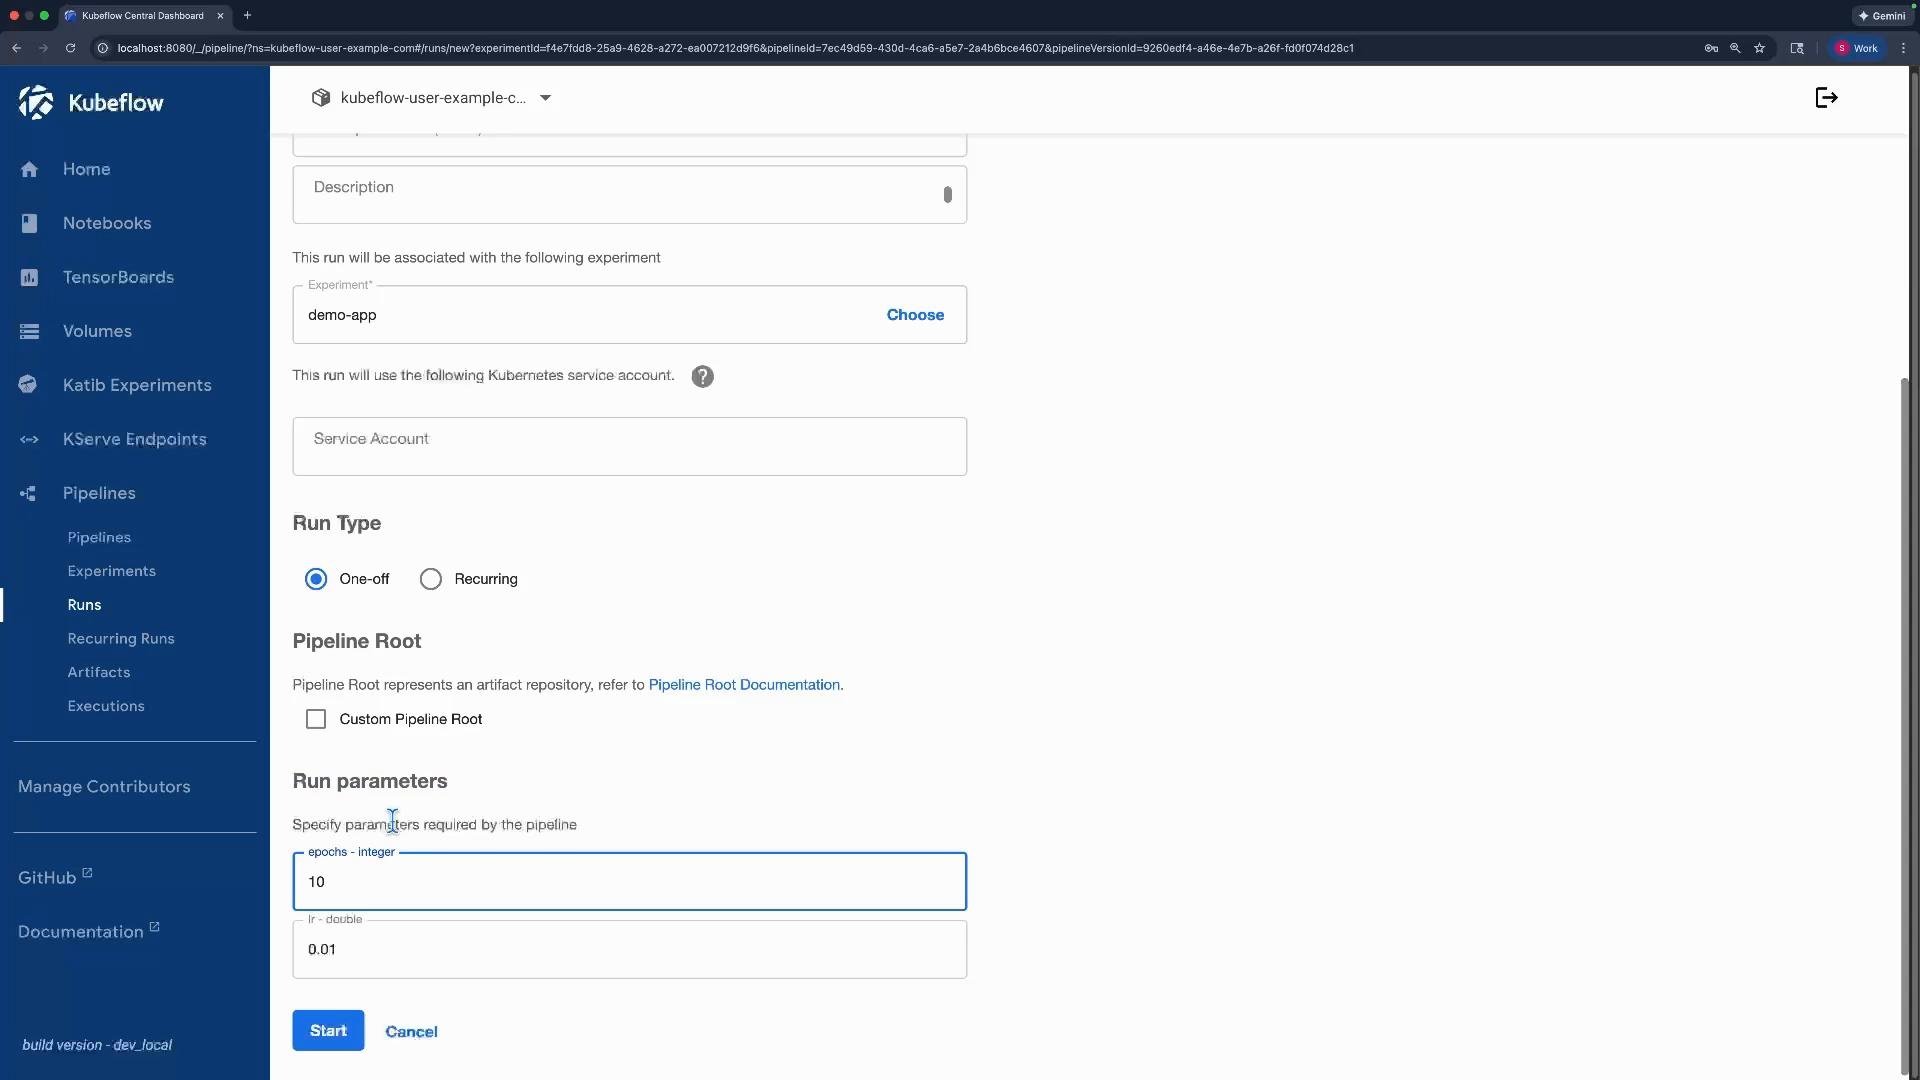
- The run form exposes the pipeline parameters (
epochs,lr). Enter values to override the defaults (for example:epochs = 20,lr = 0.02) and start the run.
Verify the run and inspect inputs
- After the run completes, open the
Train Modelstep to inspect input parameters and logs. - The run inputs will show the parameter values you supplied:
- The executor logs should include the component printout confirming the passed-in values:
Quick reference
Summary
- Define pipeline parameters as inputs to the
@pipelinefunction (with optional defaults). - Accept corresponding arguments in the component that needs them.
- Pass the pipeline parameters into the component call inside the pipeline.
- Users can override defaults in the Kubeflow UI or via the API for flexible experimentation without changing code.
- Kubeflow Pipelines Documentation
- KFP SDK component docs and examples for advanced parameter types and component packaging.