

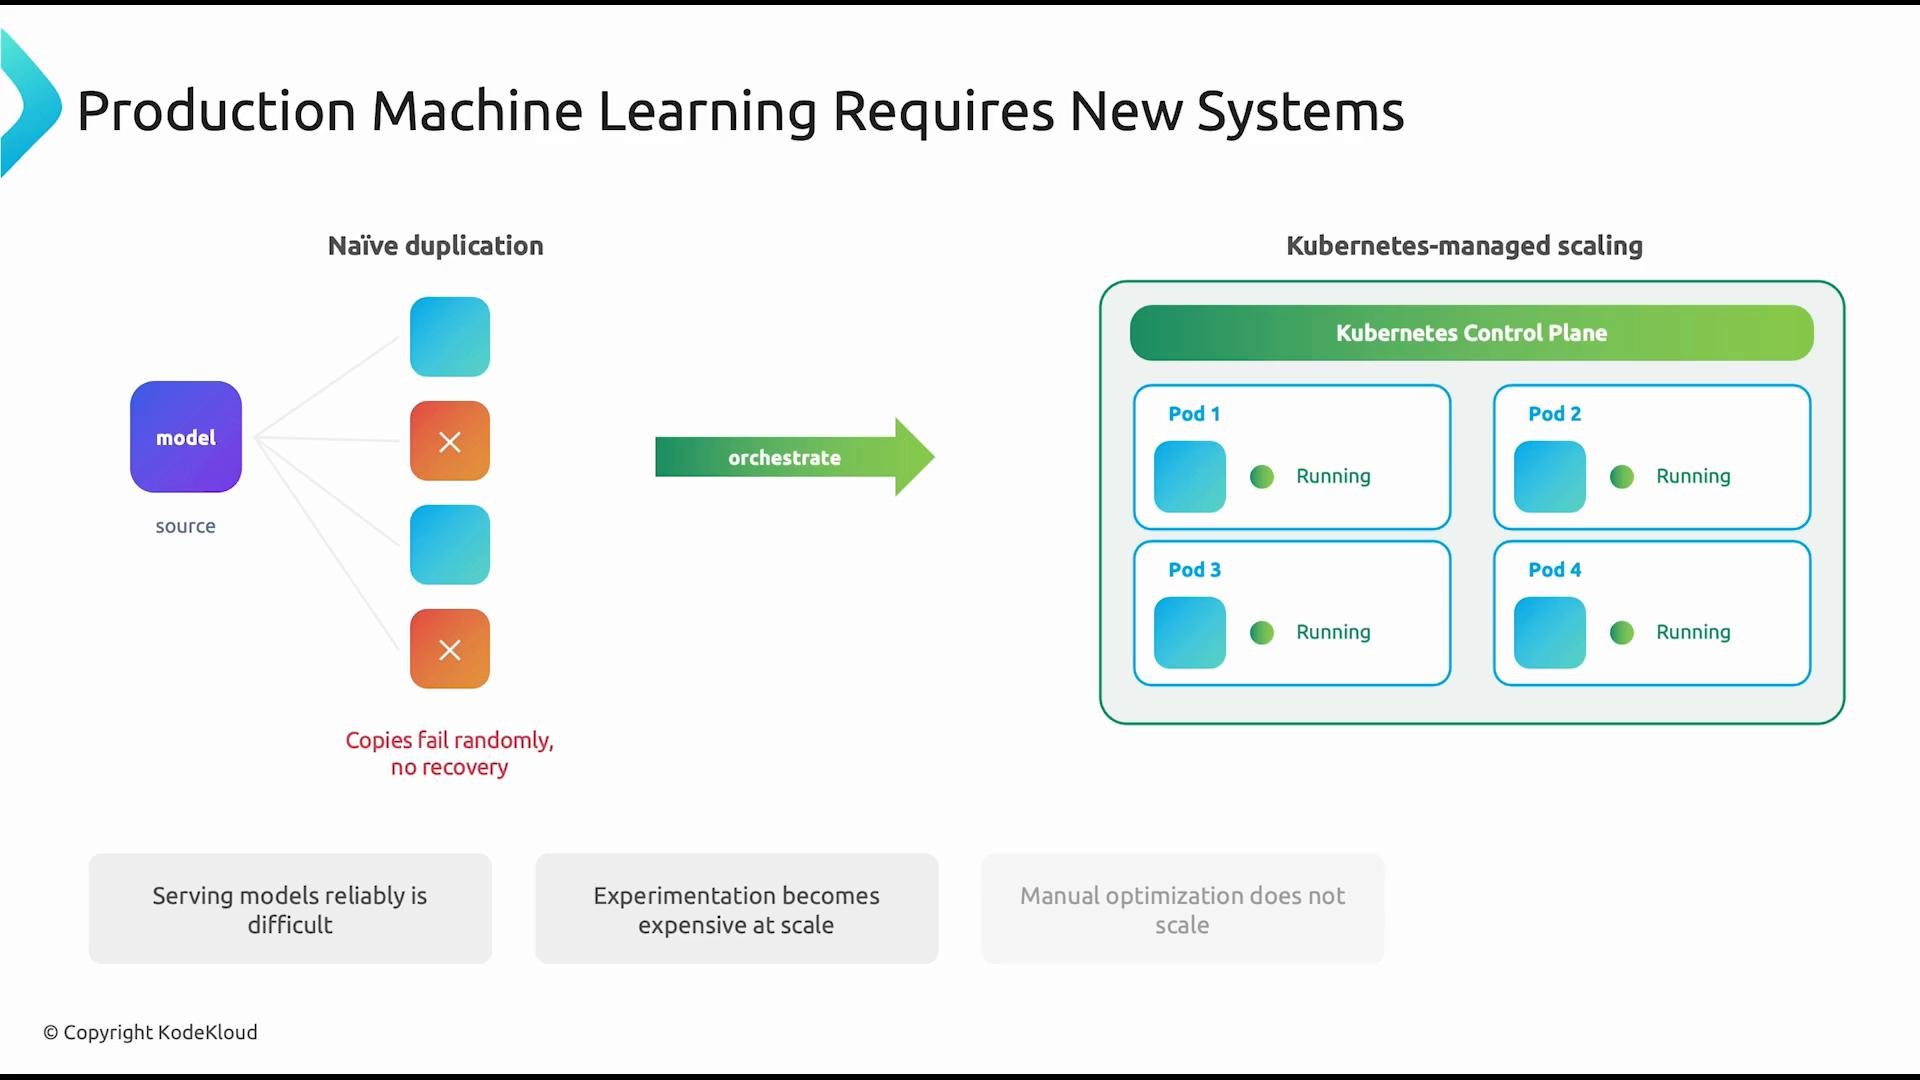
- How do we expose models reliably through APIs?
- How do we scale inference for steady, bursty, or unpredictable traffic patterns?
- How do we monitor and continuously improve model performance in production?
- How do we automate experimentation (hyperparameter search) instead of manually tuning parameters?
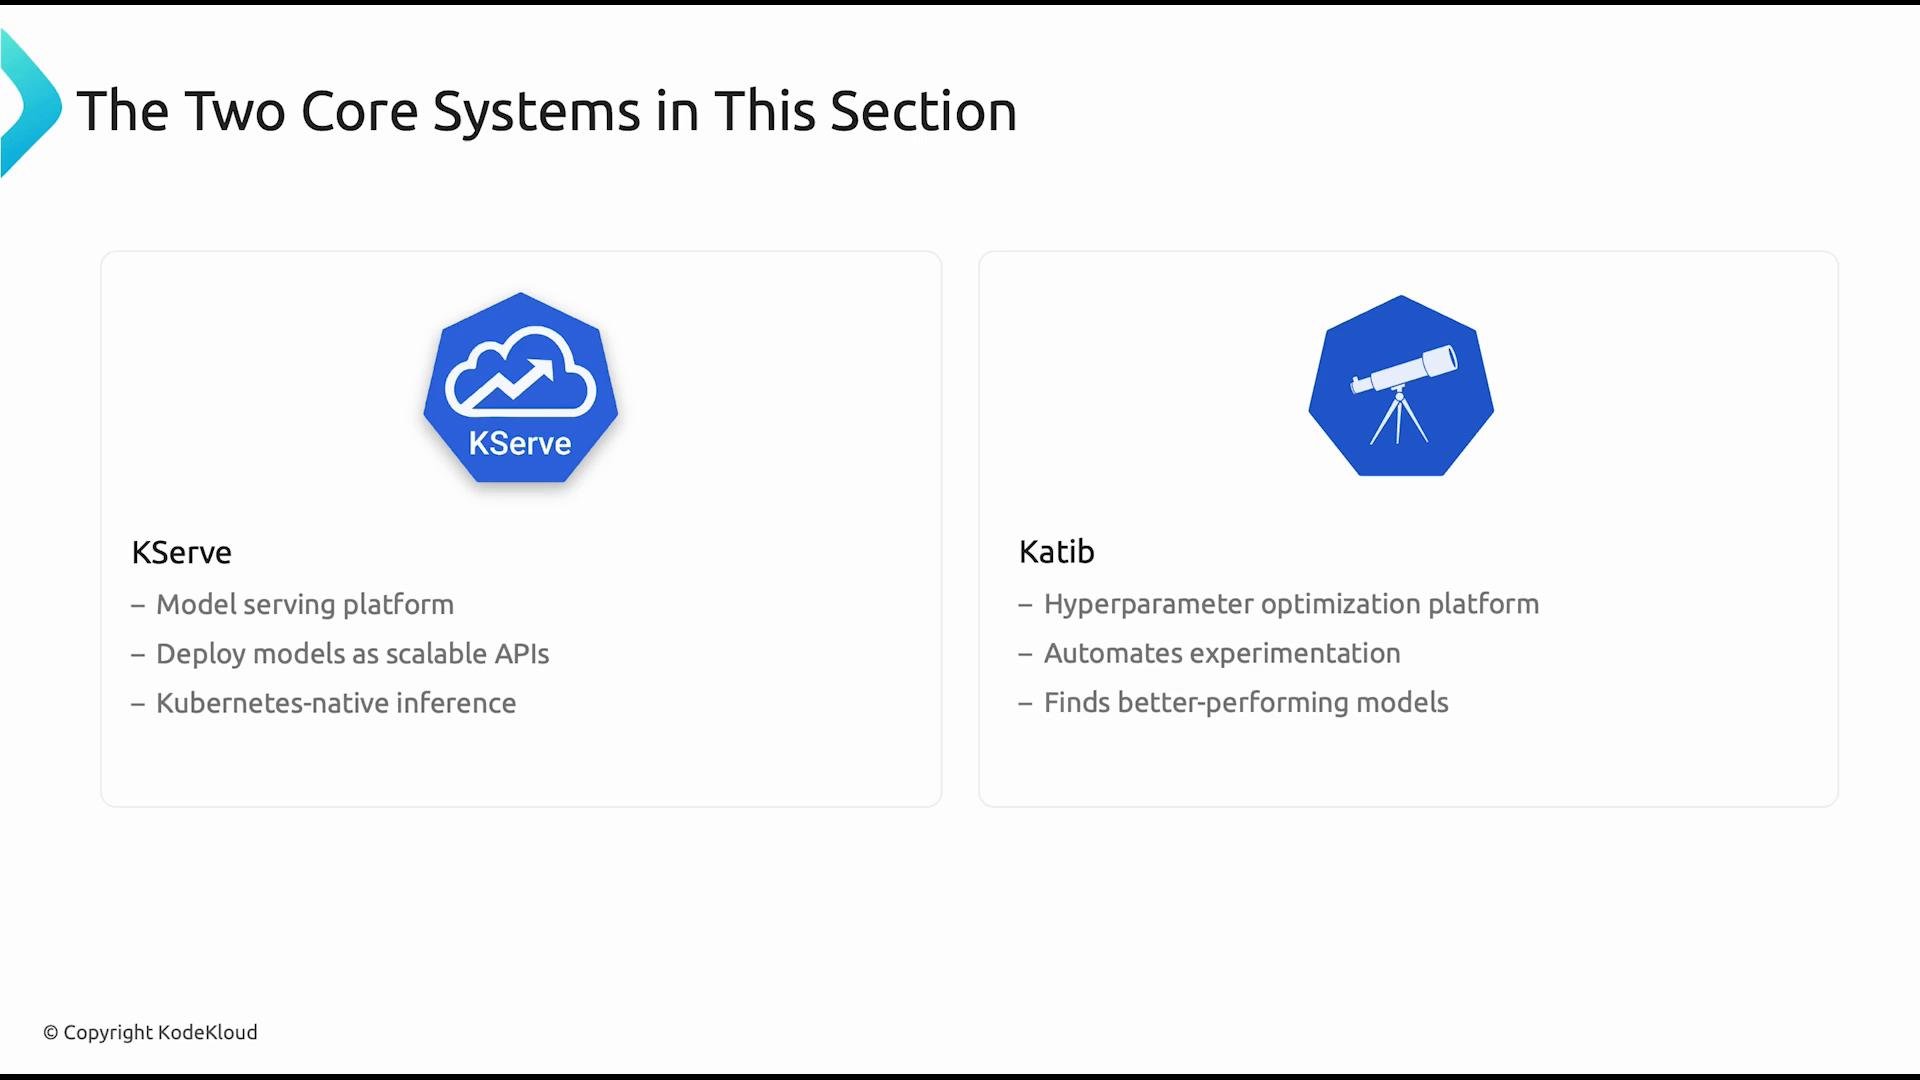
- KServe simplifies deploying models as scalable, production-ready inference services on Kubernetes.
- Knative provides serverless primitives for autoscaling and event-driven workloads.
- KServe — a Kubernetes-native model serving platform that exposes models as scalable HTTP/gRPC inference APIs and integrates with autoscaling and Kubernetes networking.
- Katib — an automated hyperparameter optimization framework that runs experiments to discover better-performing model configurations.
- A practical end-to-end example using the Iris dataset.
- Training a Random Forest model and evaluating how hyperparameters affect performance.
- Using Katib to automate hyperparameter search and run reproducible experiments.
- Deploying the optimized model with KServe and exposing it as a live inference API on Kubernetes.
Before you begin: ensure you have access to a Kubernetes cluster and a working
kubectl context. Installing KServe and Katib requires cluster admin privileges. For guided installs and permissions, see the linked course pages above.- Why ML in production is primarily an infrastructure problem.
- How Kubernetes enables reliable, scalable model serving.
- How Katib automates experimentation so teams can find better model configurations faster.
- How to combine these tools into repeatable, production-ready MLOps workflows.
- Kubernetes Basics
- KServe course (KodeKloud)
- Katib / Kubeflow course (KodeKloud)
- Knative (serverless on Kubernetes)
- Fundamentals of MLOps (KodeKloud)