

Problem type: classification
The Iris dataset is a multiclass classification problem: given numerical measurements of a flower, predict its species. A model learns patterns from the numeric input features and outputs one of the target species. This is a canonical example for teaching supervised classification pipelines.
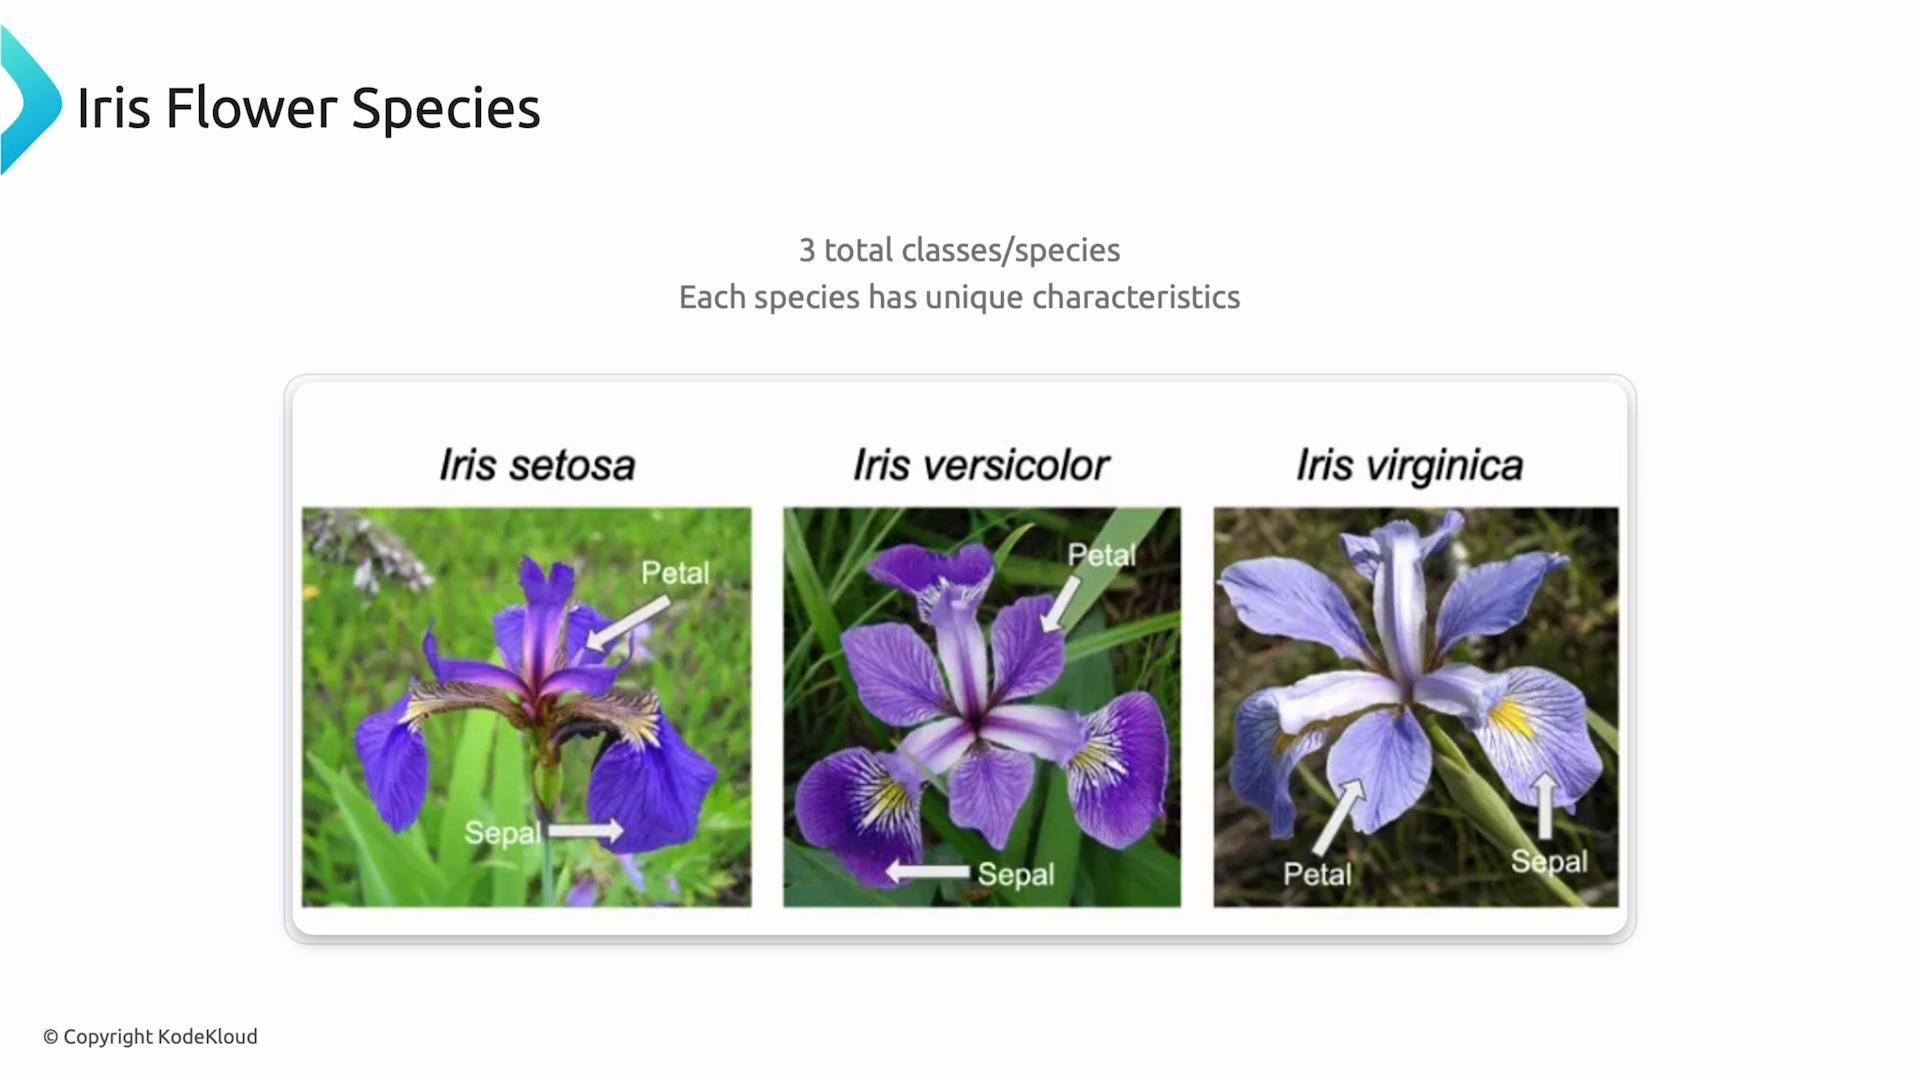
Target classes: three species
There are three labeled species in the dataset:- Iris setosa
- Iris versicolor
- Iris virginica
Features: four numeric measurements
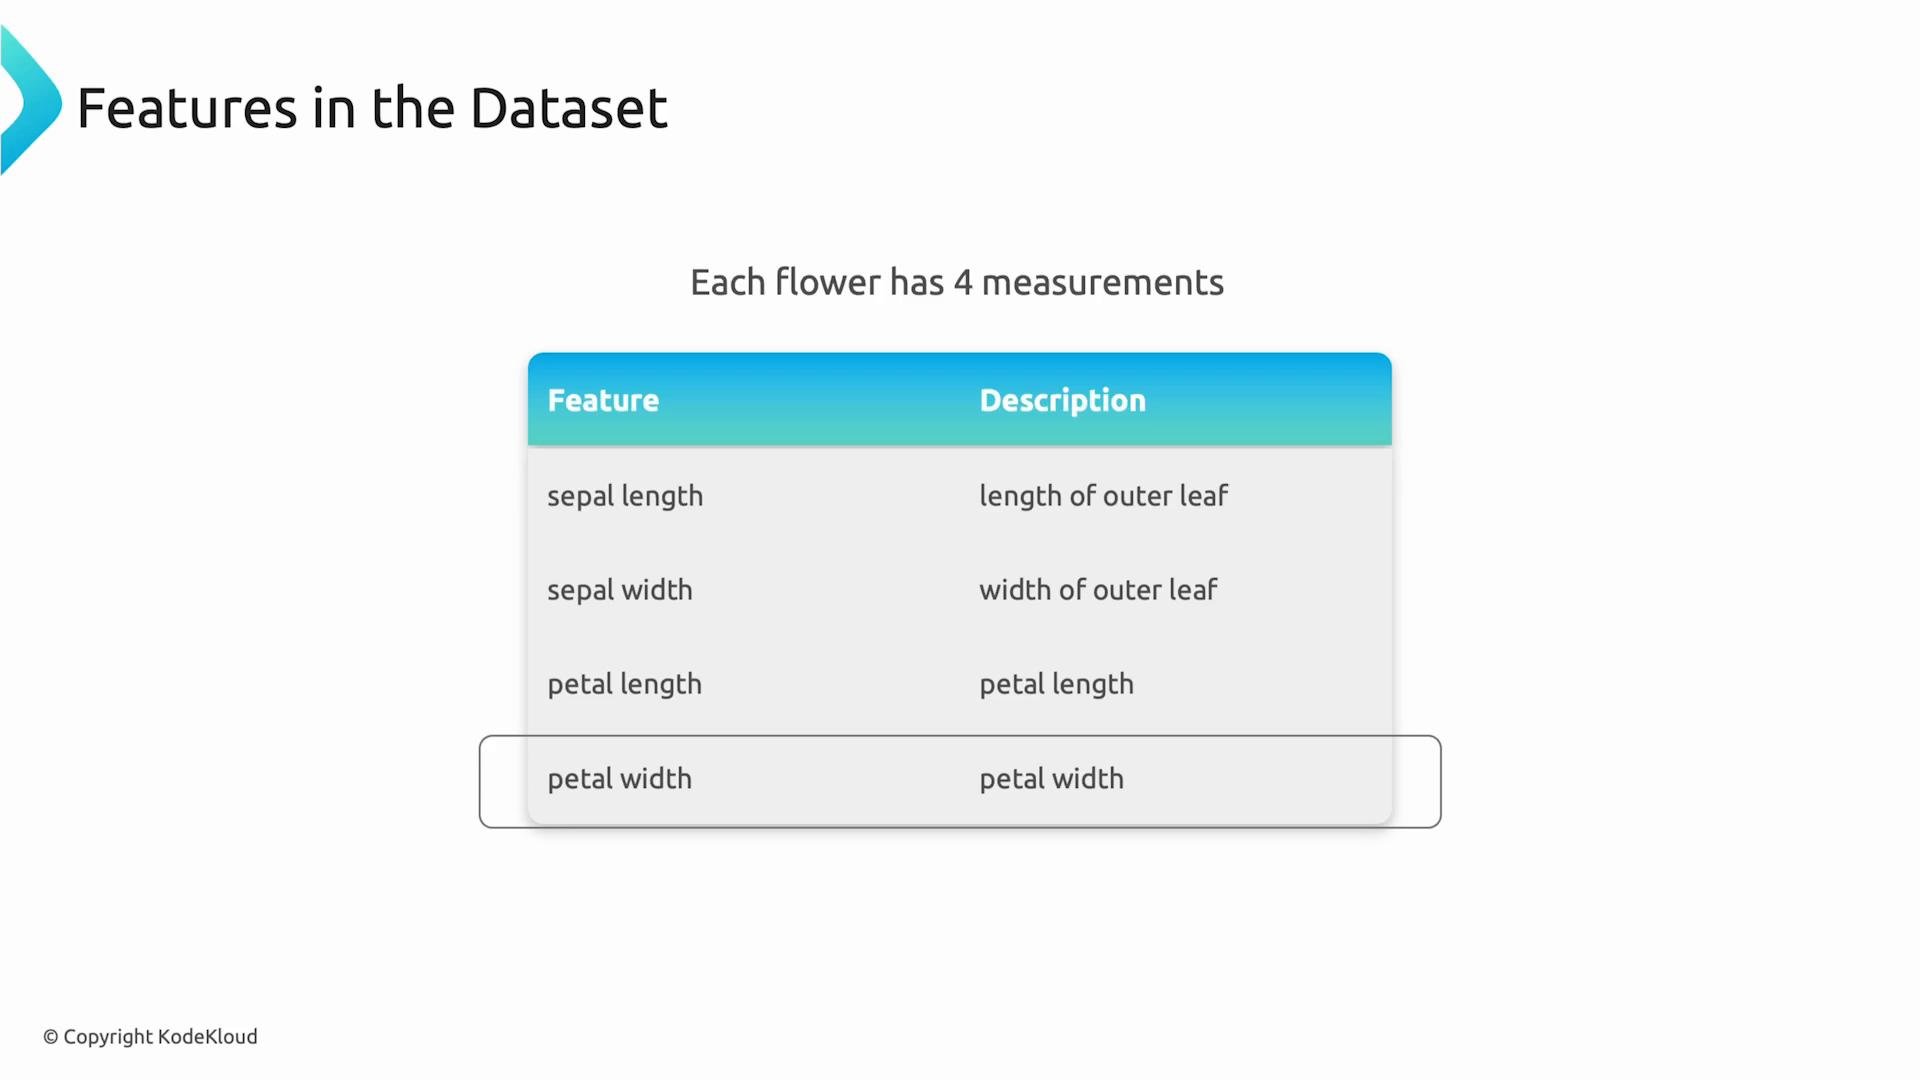
Each observation contains four numeric features:- sepal length (cm)
- sepal width (cm)
- petal length (cm)
- petal width (cm)
Why the Iris dataset is so popular
The Iris dataset is widely used because it strikes a balance between simplicity and pedagogical value:- Easy to understand and visualize
- Clean and balanced classes
- Small enough to train quickly
- Great for demonstrating full ML workflows (inspect → split → preprocess → train → evaluate)
Where to get the dataset
The Iris dataset is bundled with several ML libraries and is also available from classic repositories:- scikit-learn: load with a single function call
- UCI Machine Learning Repository: canonical dataset source
- Many tutorials and teaching resources include ready-to-use copies
Quick dataset facts
A typical workflow is: load the dataset, inspect features and labels, split into training and test sets (use
stratify to preserve class balance), apply preprocessing (e.g., scaling), train a model, and evaluate on held-out data.Example: load, inspect, split, and train
Below is a compact scikit-learn example that demonstrates the essential steps. Comments explain each step. Run this in a Python environment with scikit-learn and pandas installed.stratify=y to keep class proportions similar between splits.
Summary
This article covered:- What the Iris dataset is and why it’s important for ML education
- The classification problem and the three species involved
- The four numeric features used by models
- Where to find the dataset and a quick scikit-learn example showing loading, splitting, preprocessing, and training
Links and references
- scikit-learn: load_iris — https://scikit-learn.org/stable/modules/generated/sklearn.datasets.load_iris.html
- UCI Machine Learning Repository: Iris Data Set — https://archive.ics.uci.edu/ml/datasets/iris