

What a histogram exposes
A histogram metric in Prometheus is represented by three related time series:- The
_countseries — the total number of observations. - The
_sumseries — the sum of all observed values. - The
_bucketseries — cumulative bucket counts with anlelabel (less-or-equal).
/articles path:
- Each
request_latency_seconds_bucket{le="X"}value is the cumulative count of observations with value <= X. - Buckets are cumulative: the count at
le="0.03"includes counts fromle="0.01"andle="0.02", plus any observations between0.02and0.03. - The
le="+Inf"bucket contains all observations (equal to_count).
request_latency_seconds_bucket{le="0.05", path="/articles"} 50means 50 requests took <= 0.05 seconds.request_latency_seconds_bucket{le="0.04", path="/articles"} 44means 44 requests took <= 0.04 seconds.
When working with counters like
_count and _sum, use rate() (or irate() for instant rates) over an appropriate lookback window. This converts counters into per-second rates suitable for further math and charting.Common PromQL patterns with histograms
- Rate of incoming requests per second (1m window):
- Rate for every bucket (to visualize distribution over time):
- Total observed value (e.g., sum of latencies or bytes):
- Rate of increase for that sum:
- Average latency over the past 5 minutes (sum rate divided by count rate):
- Fraction (percentage) of requests that fell into a specific bucket
le="0.06"over 5 minutes:
- Number of observations that fell between two bucket boundaries (approximate):
Histogram quantiles
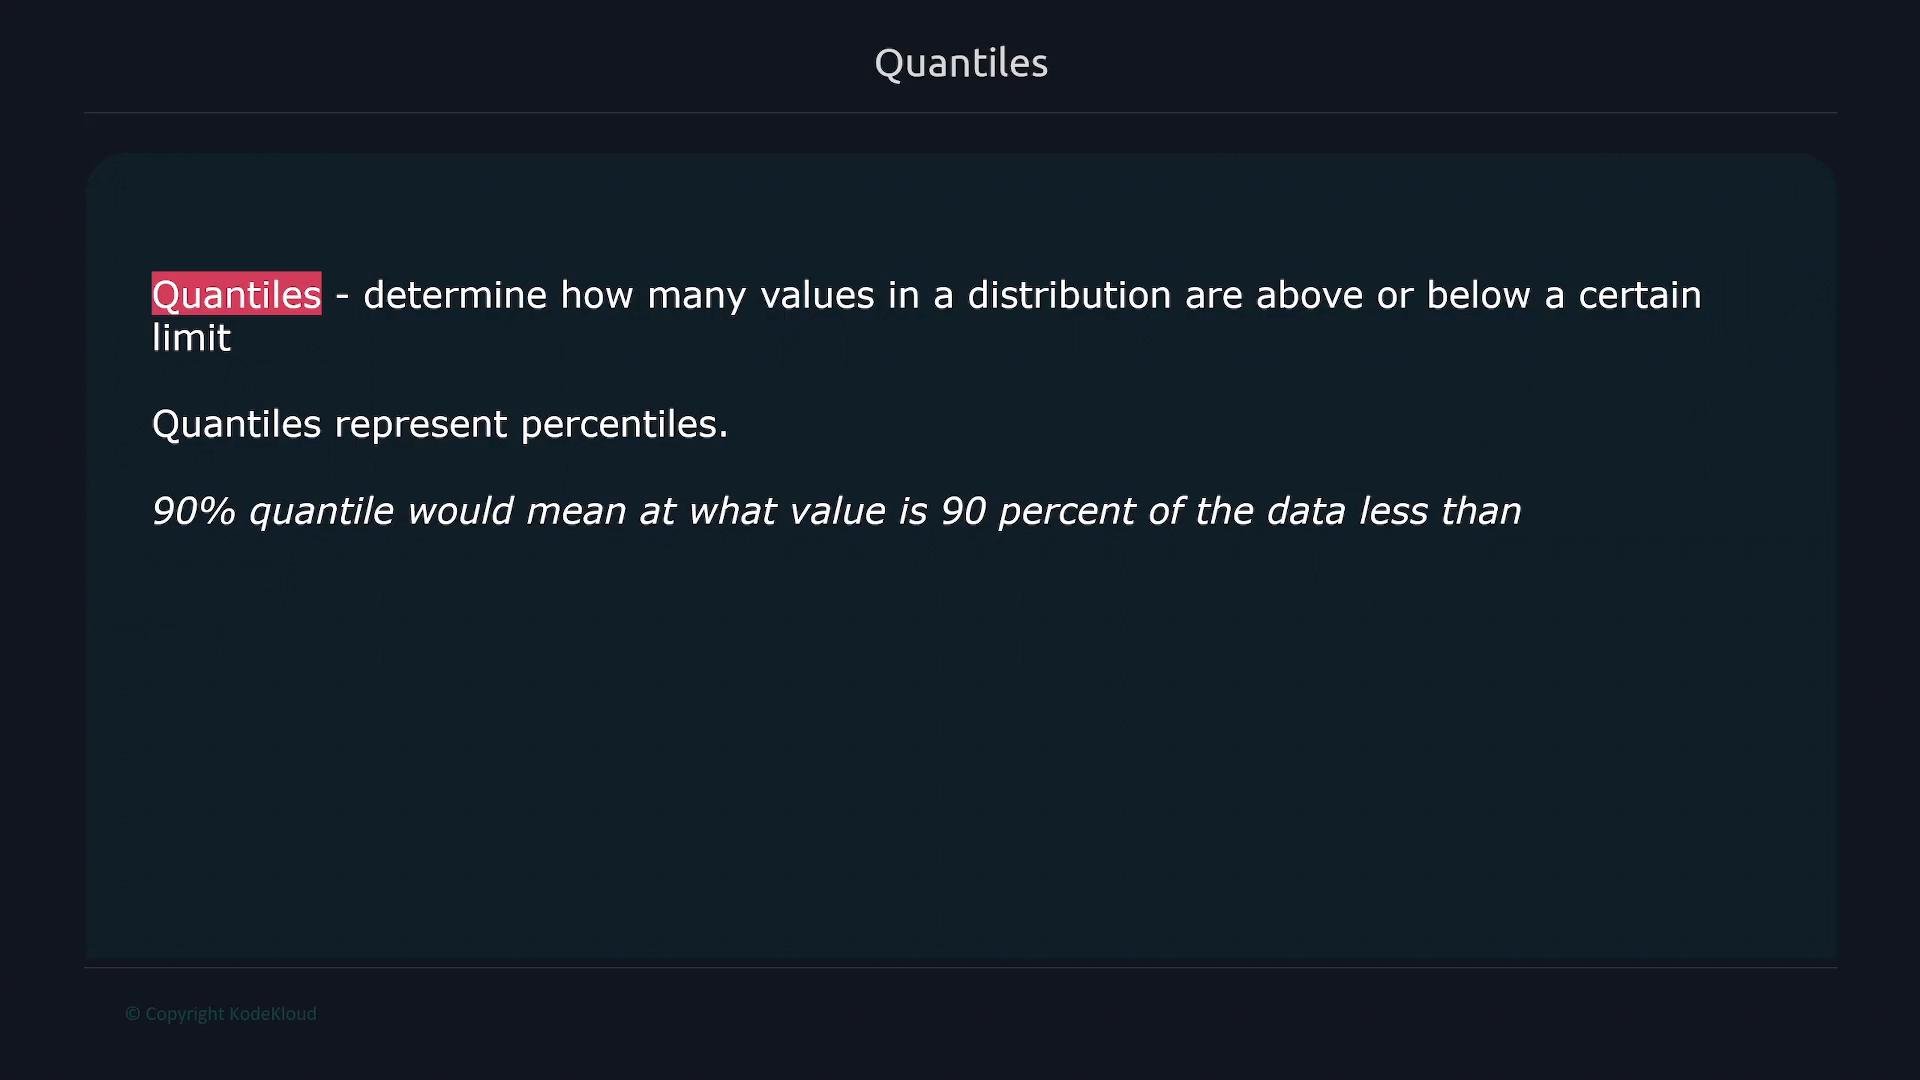
Quantiles (percentiles) tell you the value below which a given percentage of observations fall. Prometheus computes approximate quantiles from histogram buckets usinghistogram_quantile().
Accuracy and bucket placement
histogram_quantile()is an approximation derived by linear interpolation between bucket boundaries.- To improve accuracy around a specific SLO, include a bucket whose
leequals the SLO threshold. For example, if your SLO is 95% of requests <= 0.5s, ensure you have a bucket withle="0.5". - If you require higher precision near an SLO boundary, add more buckets there — but do so sparingly because each bucket creates an additional time series.
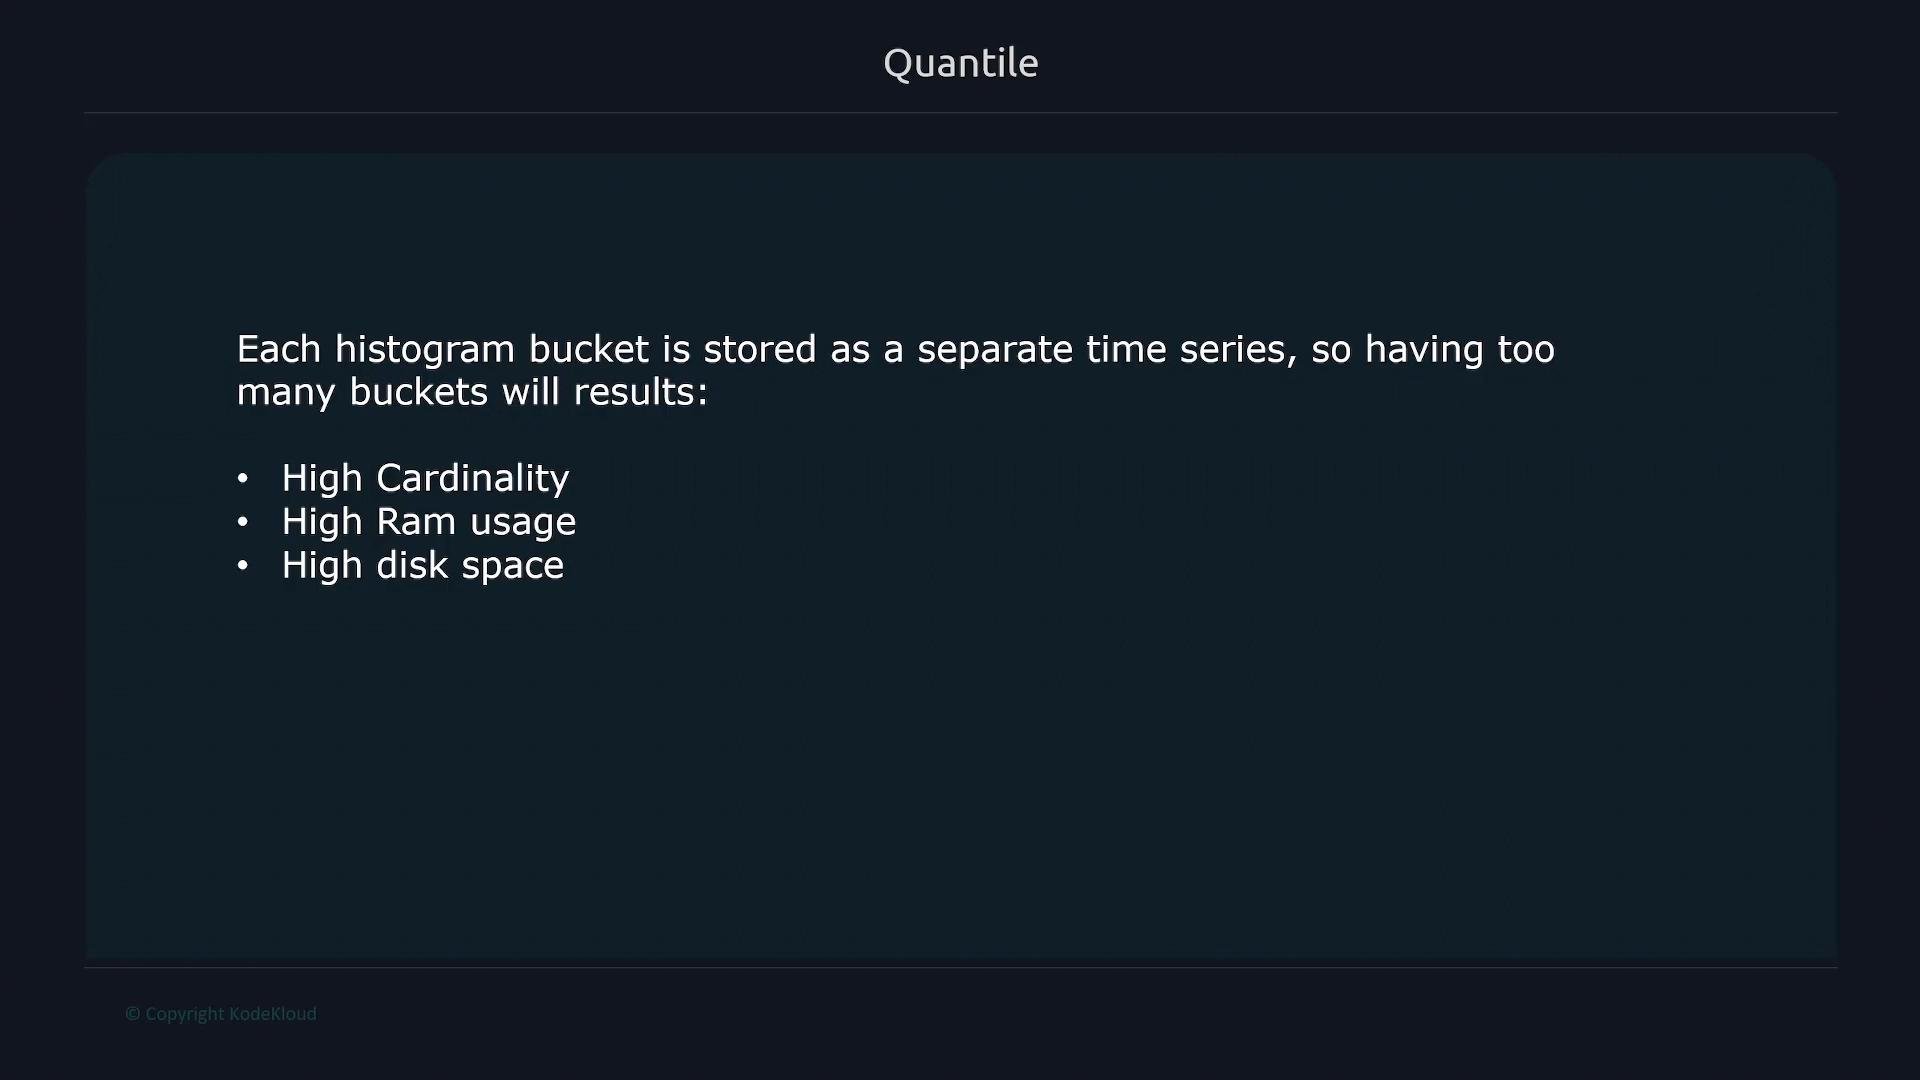
Adding many buckets increases cardinality: more time series, higher memory and disk usage, and slower insert performance. Add buckets only where you need precision.
Practical histogram example
Another histogram dump for the/cars endpoint:
le="0.02"has a count of 3 → three requests <= 0.02s.le="0.05"has a count of 10 → ten requests <= 0.05s (this includes smaller buckets).
Summary metrics (Summaries)
Summaries are an alternative to histograms. They expose quantiles directly (computed on the client) instead of storing bucketed counts. A summary typically contains:- The count (
_count) — total number of observations. - The sum (
_sum) — sum of all observed values. - Quantile timeseries — with a
quantile="<q>"label showing the observed value at that quantile.
request_latency_seconds{quantile="0.7"} 0.0365means the 70th percentile is 0.0365s — 70% of observations are <= 0.0365s.
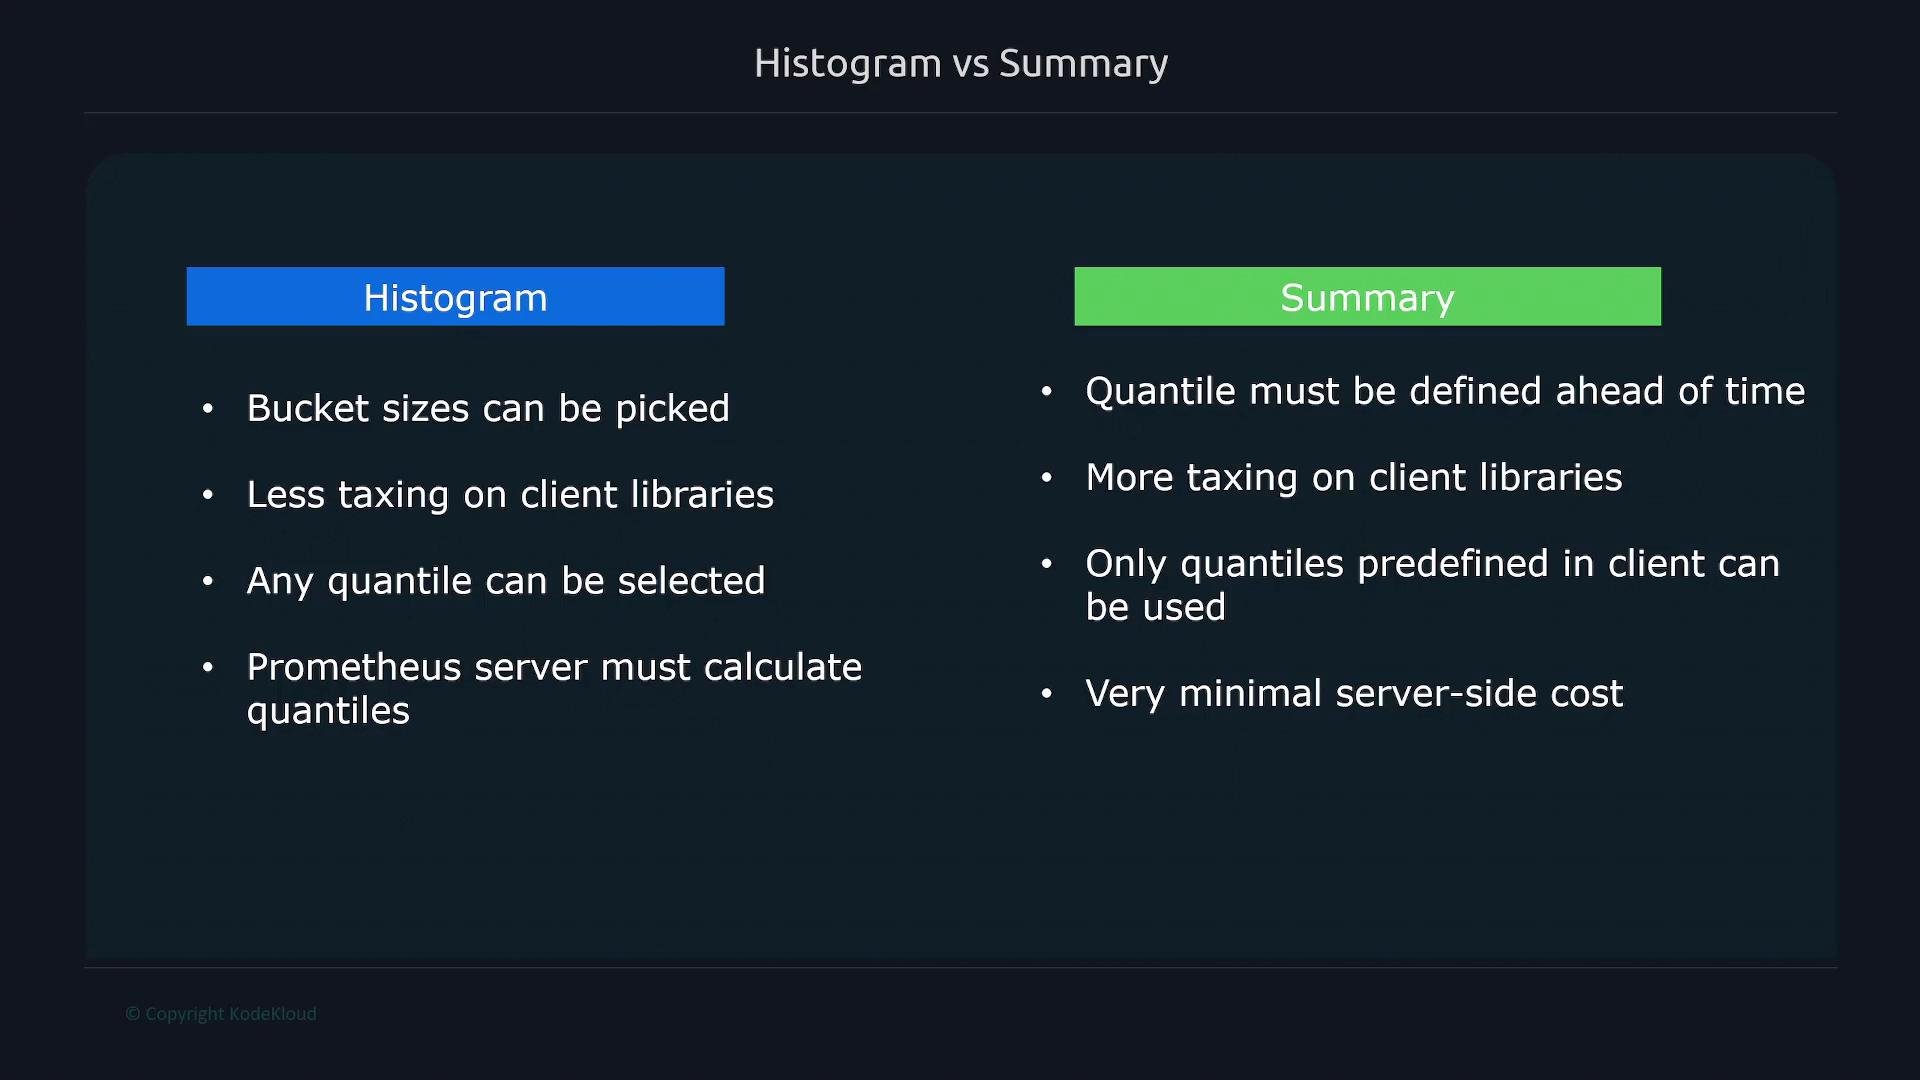
Histogram vs Summary — key differences
Reference: Prometheus documentation for histograms and summaries — https://prometheus.io/docs/practices/histograms/
Takeaways
- Use histograms when you need flexible, server-side quantile estimation and are willing to manage bucket boundaries.
- Use summaries when the client can compute and expose the specific quantiles you need.
- Always consider cardinality: each bucket or quantile creates additional time series. Add resolution only where it matters to your SLOs.
- Prometheus histograms & summaries: https://prometheus.io/docs/practices/histograms/
- PromQL function reference (including
histogram_quantile()andrate()): https://prometheus.io/docs/prometheus/latest/querying/functions/