

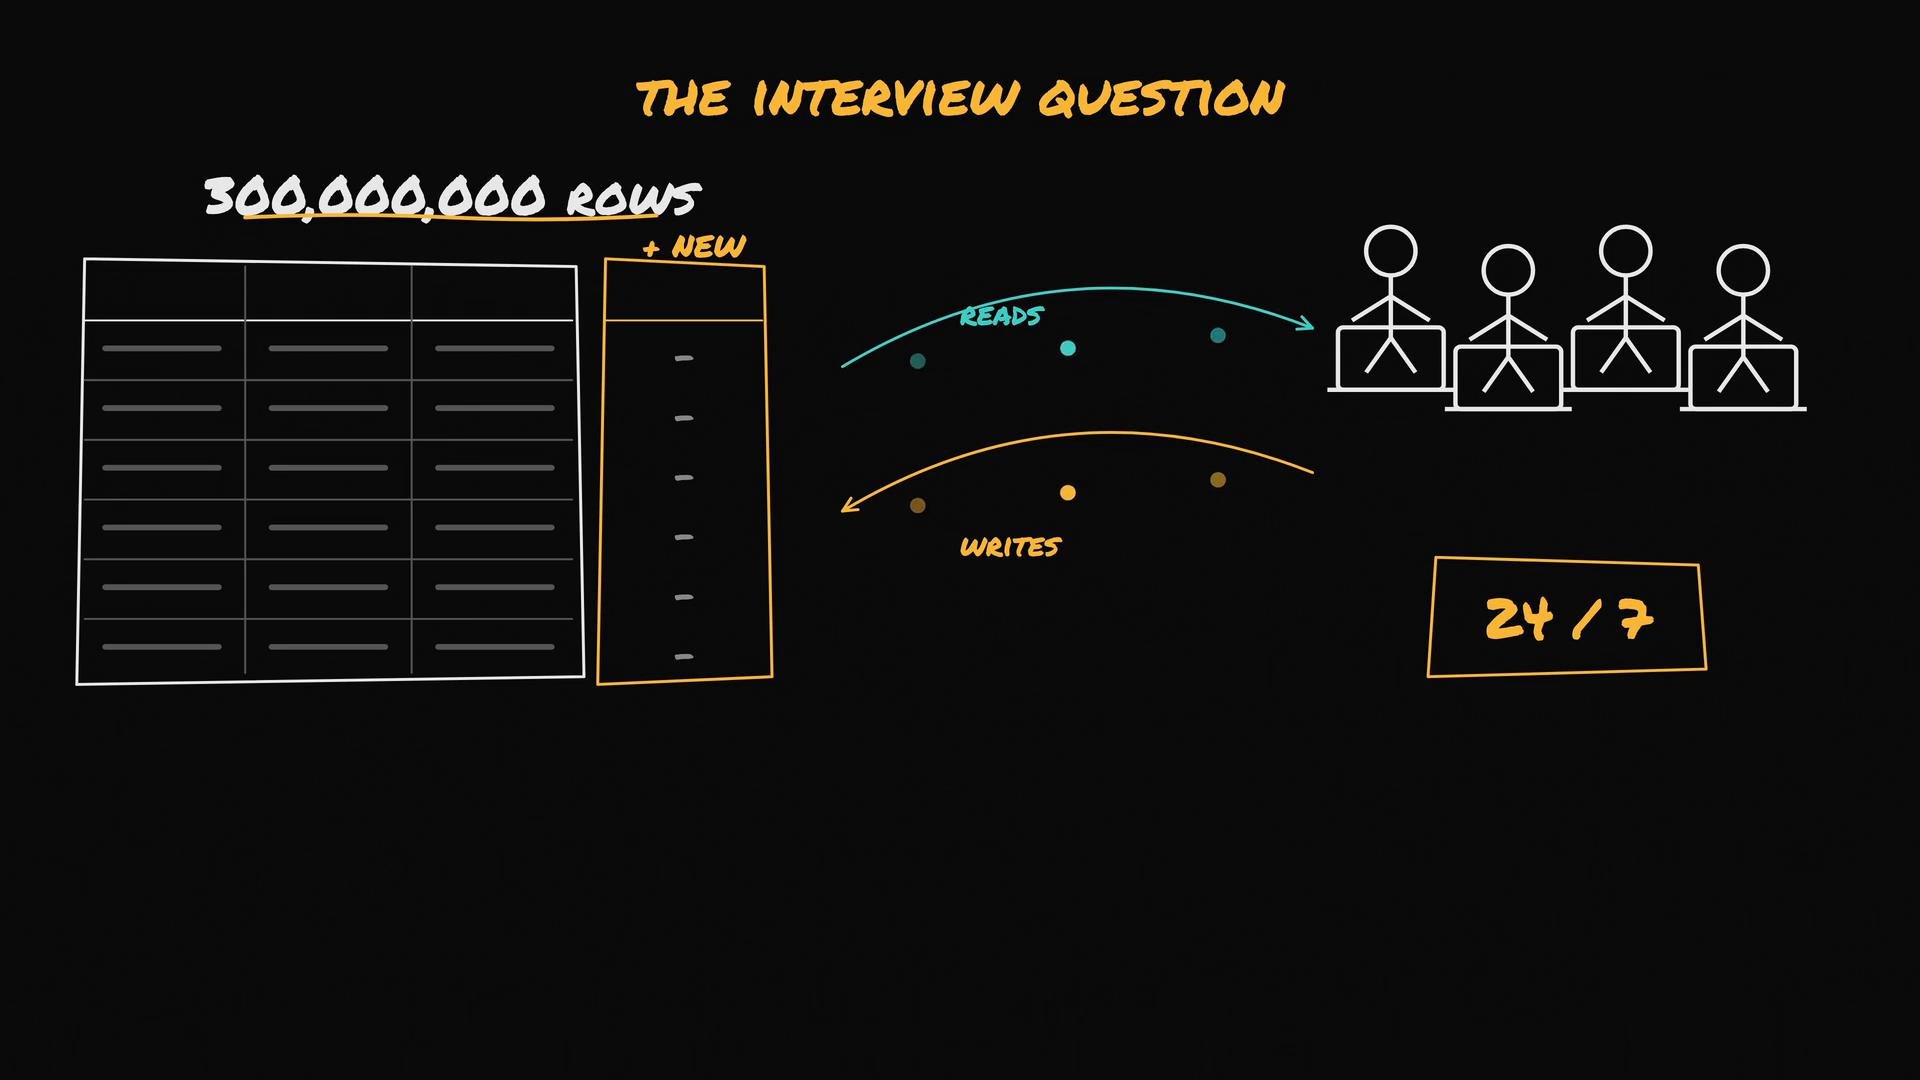
Common—but dangerous—naive approach
A naive migration that adds the column and immediately updates every row will try to modify 300M rows in one transaction. That will either lock large portions of the table or consume so many resources the database becomes unresponsive:Do not run a single UPDATE that touches every row in a hot production table. That will create long locks and resource spikes that can cause downtime.
Safe, staged migration
Follow these incremental stages to add a column without downtime:Stage 1 — Add the column as nullable with no default
Add the new column as nullable and without a default. In many databases (for example, PostgreSQL), a nullable column without a default is a metadata-only change and completes quickly without rewriting the table.NULL for that column.
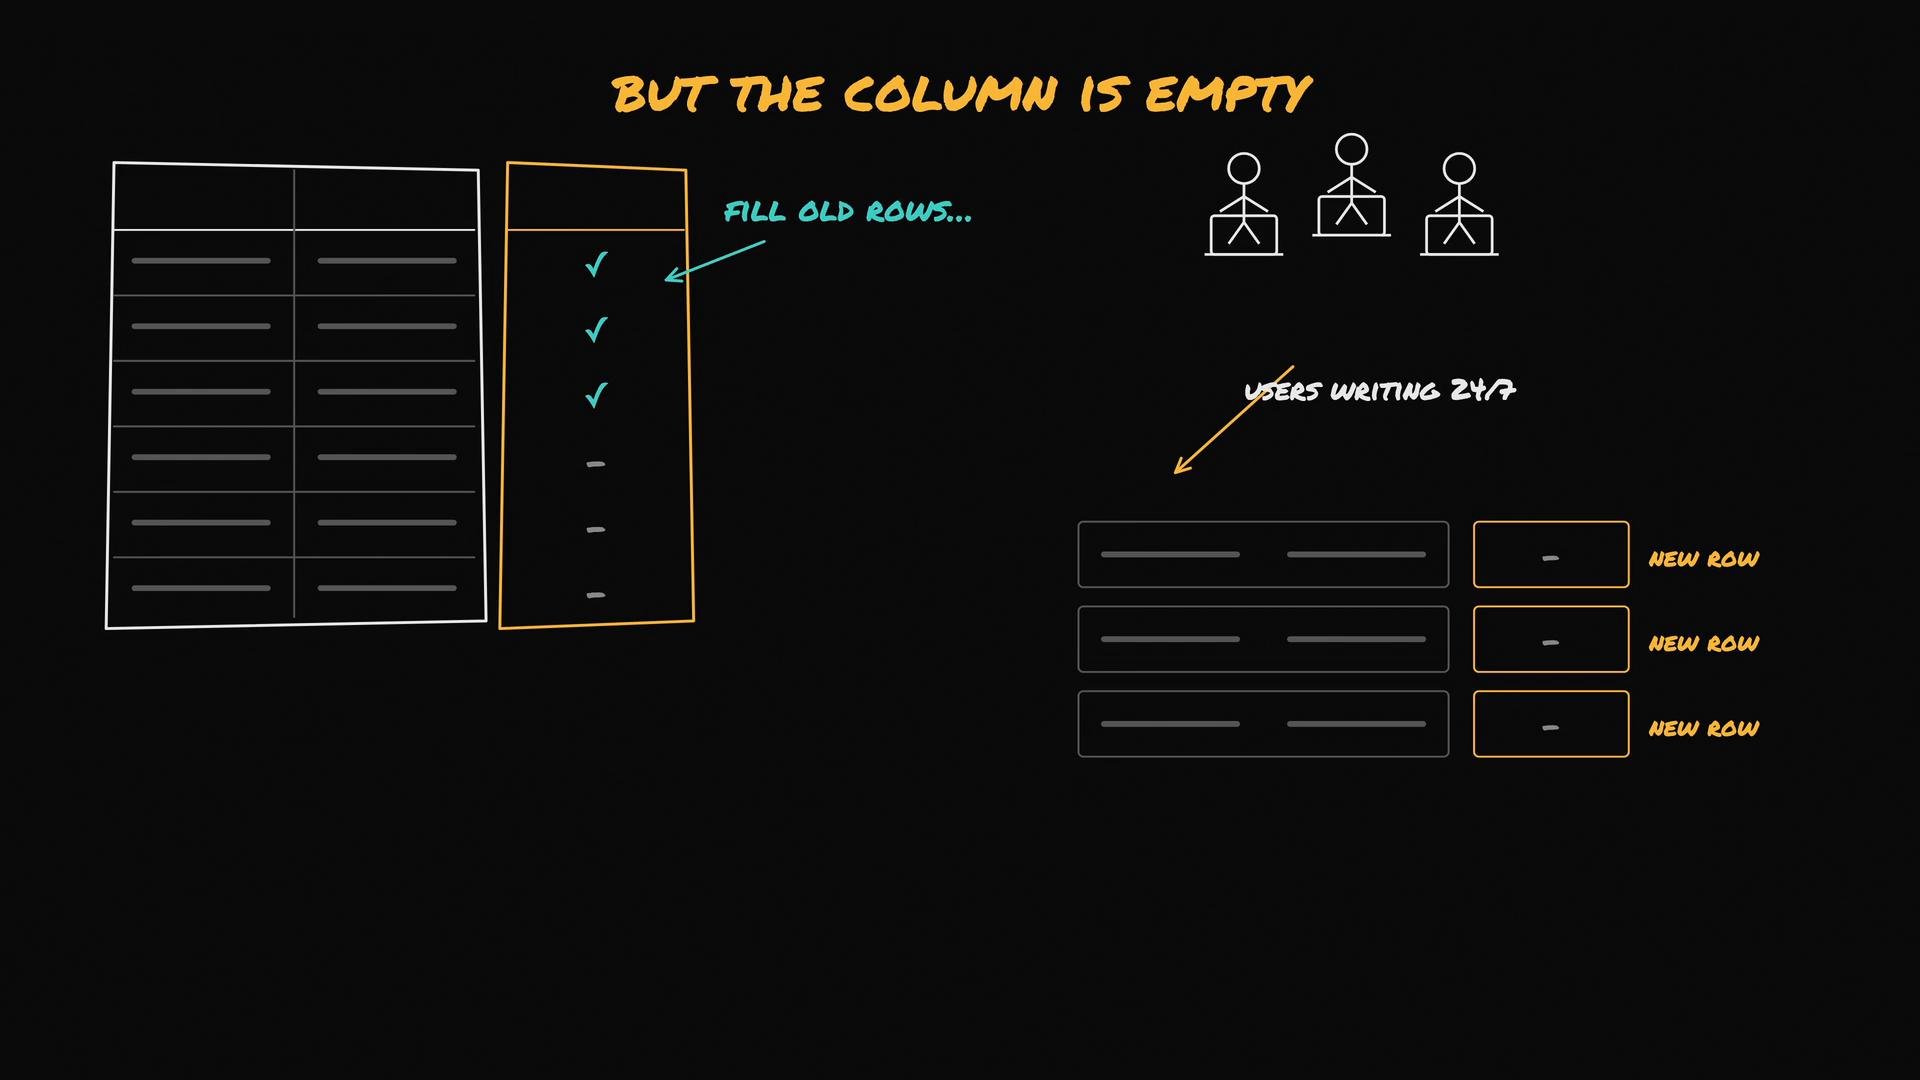
Stage 2 — Update application code so all new writes populate the column
Before backfilling old rows, ensure every new write includes the new column; otherwise you’ll be chasing a moving target.- Modify the application/service layer to collect and send the
planvalue on INSERT (and on any UPDATEs that should set it). - Deploy the updated application so that from this point forward new rows have
planpopulated.
Stage 3 — Backfill existing rows in small batches
Backfill existing rows using a background job that updates a small, bounded number of rows per transaction (for example, 5k rows). Pause between batches and monitor database metrics (CPU, I/O, lock waits). If load rises, increase the pause or reduce the batch size. PostgreSQL-safe batching pattern (CTE with LIMIT):ctid for very short-running batches (remember ctid is a physical row locator and not a stable identifier):
- CPU, IO, and disk latency
- Active queries and lock contention (
pg_stat_activity,pg_locks) - Replication lag if you have replicas
Notes about defaults and NOT NULL
- Avoid adding the column with a non-null default in the first step: on some DB versions this triggers a full-table rewrite (long-running).
- PostgreSQL historically rewrote the table when adding a column with a default; recent versions may optimize this. Always verify the behavior for your database version.
- After the backfill:
- Add a server-side default for future inserts:
ALTER TABLE ... ALTER COLUMN SET DEFAULT ...(often metadata-only). - Add the NOT NULL constraint:
ALTER TABLE ... ALTER COLUMN SET NOT NULL(this requires a scan to verify no NULLs exist but typically doesn’t rewrite the table).
- Add a server-side default for future inserts:
Adding a nullable column and backfilling in batches is the safe, incremental approach. But database-specific behaviors vary — always verify how your DB version handles ALTER TABLE with defaults and NOT NULL changes before performing production migrations.
Quick reference: recommended sequence
Tools and further reading
- For MySQL: pt-online-schema-change, gh-ost (online schema change tools)
- PostgreSQL ALTER docs: https://www.postgresql.org/docs/current/sql-altertable.html
- PostgreSQL system columns (
ctid): https://www.postgresql.org/docs/current/ddl-system-columns.html