

Structured logs (JSON or schema-backed formats) are strongly recommended: they make logs easier to query, filter, and analyze across your observability stack.
What is a log?
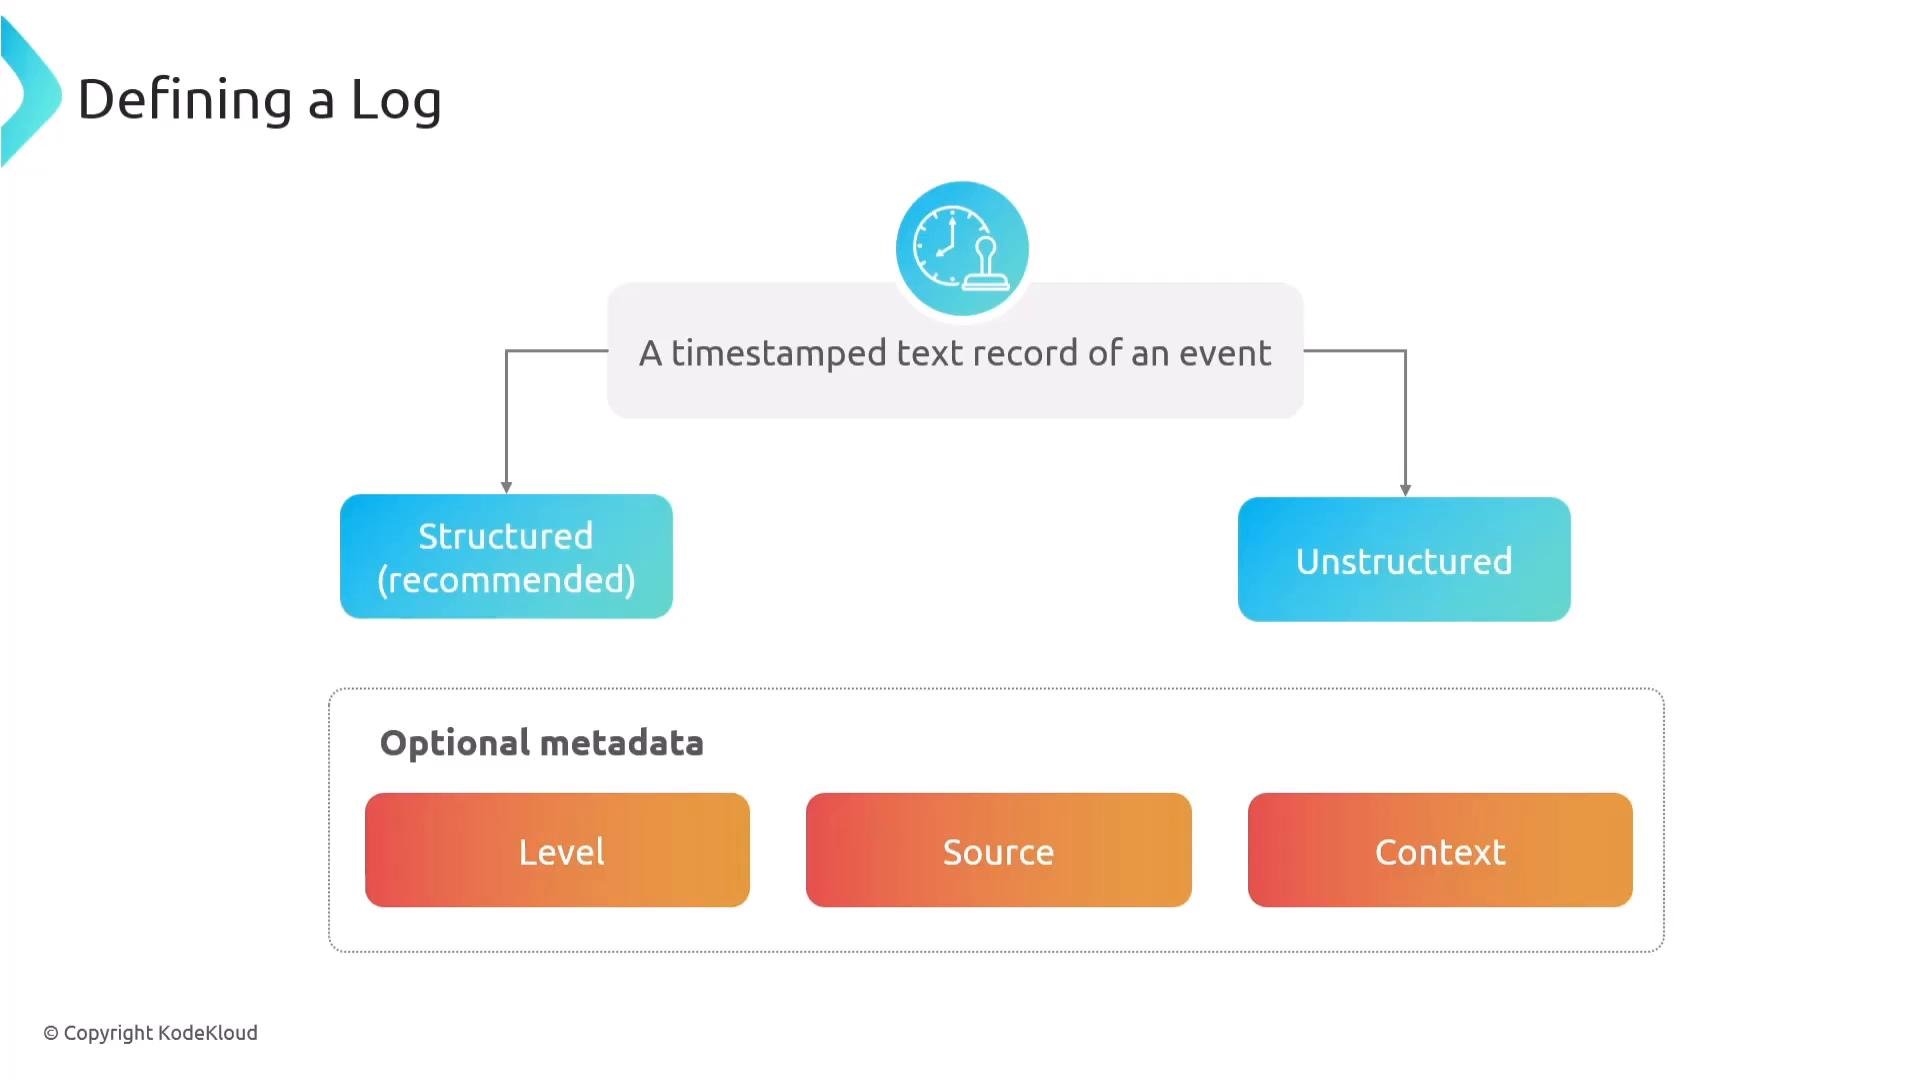
A log is a timestamped text record of an event — something that happened in your system at a specific point in time. Logs may be:- Structured — follow a consistent schema (JSON is common). Predictable and machine-readable.
- Unstructured — free text and stack traces. Easy for humans, but harder for programmatic analysis.
- Semi-structured — key-value tokens or delimited fields (a compromise between the two).
- Level (debug, info, warn, error)
- Source (service or component)
- Context (trace_id, span_id, user identifiers, etc.)
Logging libraries and OpenTelemetry integration
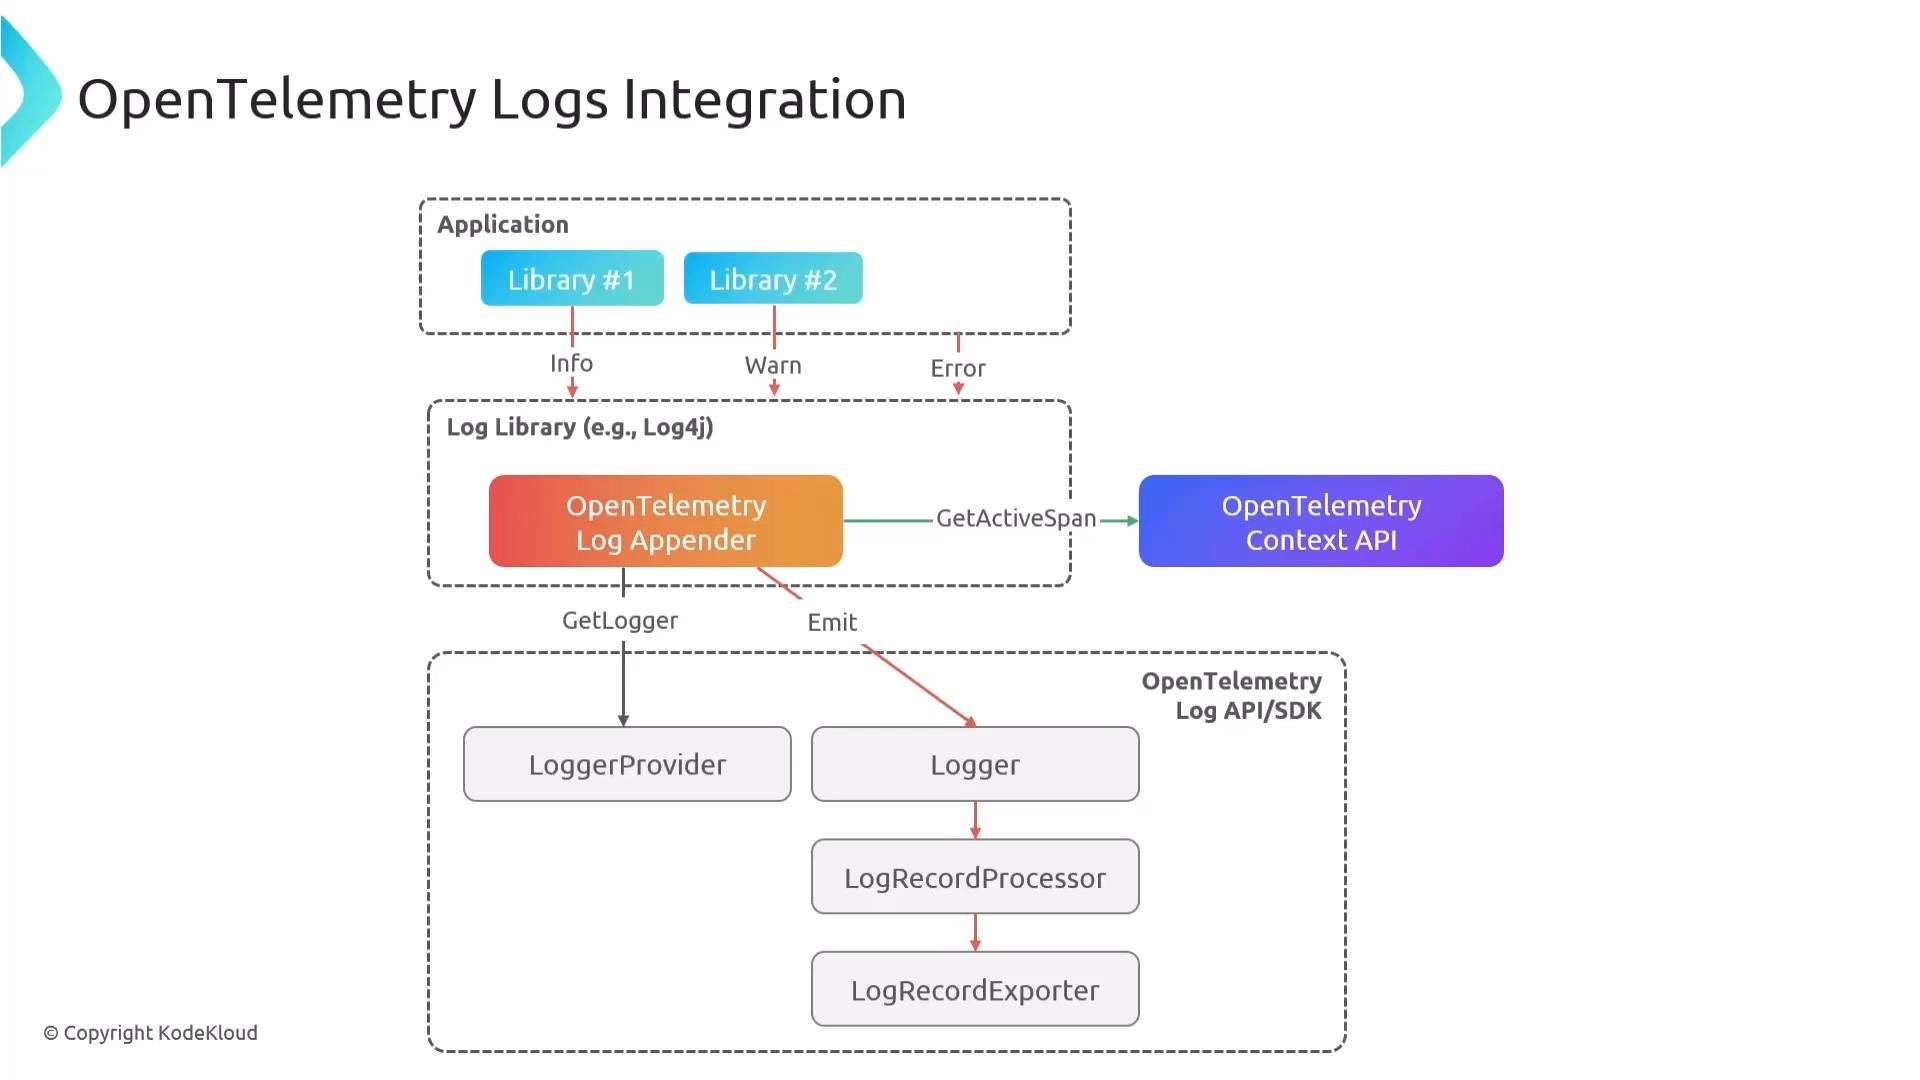
OpenTelemetry does not replace your existing logging libraries or formats; it augments them. Common logging libraries by language include:OpenTelemetry enriches and interoperates with logging frameworks — it does not seek to replace them. Use OTel to add context (trace/span IDs) and to export logs consistently.
- Your application and its libraries emit log messages (info/warn/error) to a logging framework (e.g., Log4j).
- An OpenTelemetry appender/integration captures each log record and queries the OpenTelemetry Context API.
- If a log is produced while a span is active, the integration attaches trace_id and span_id to the log.
- The enriched record passes to the OpenTelemetry Log API/SDK, which uses a LoggerProvider to create logger instances, a LogRecordProcessor to batch/filter/transform, and a LogRecordExporter to convert/export the record (commonly using OTLP).
The OpenTelemetry Collector in the logging pipeline
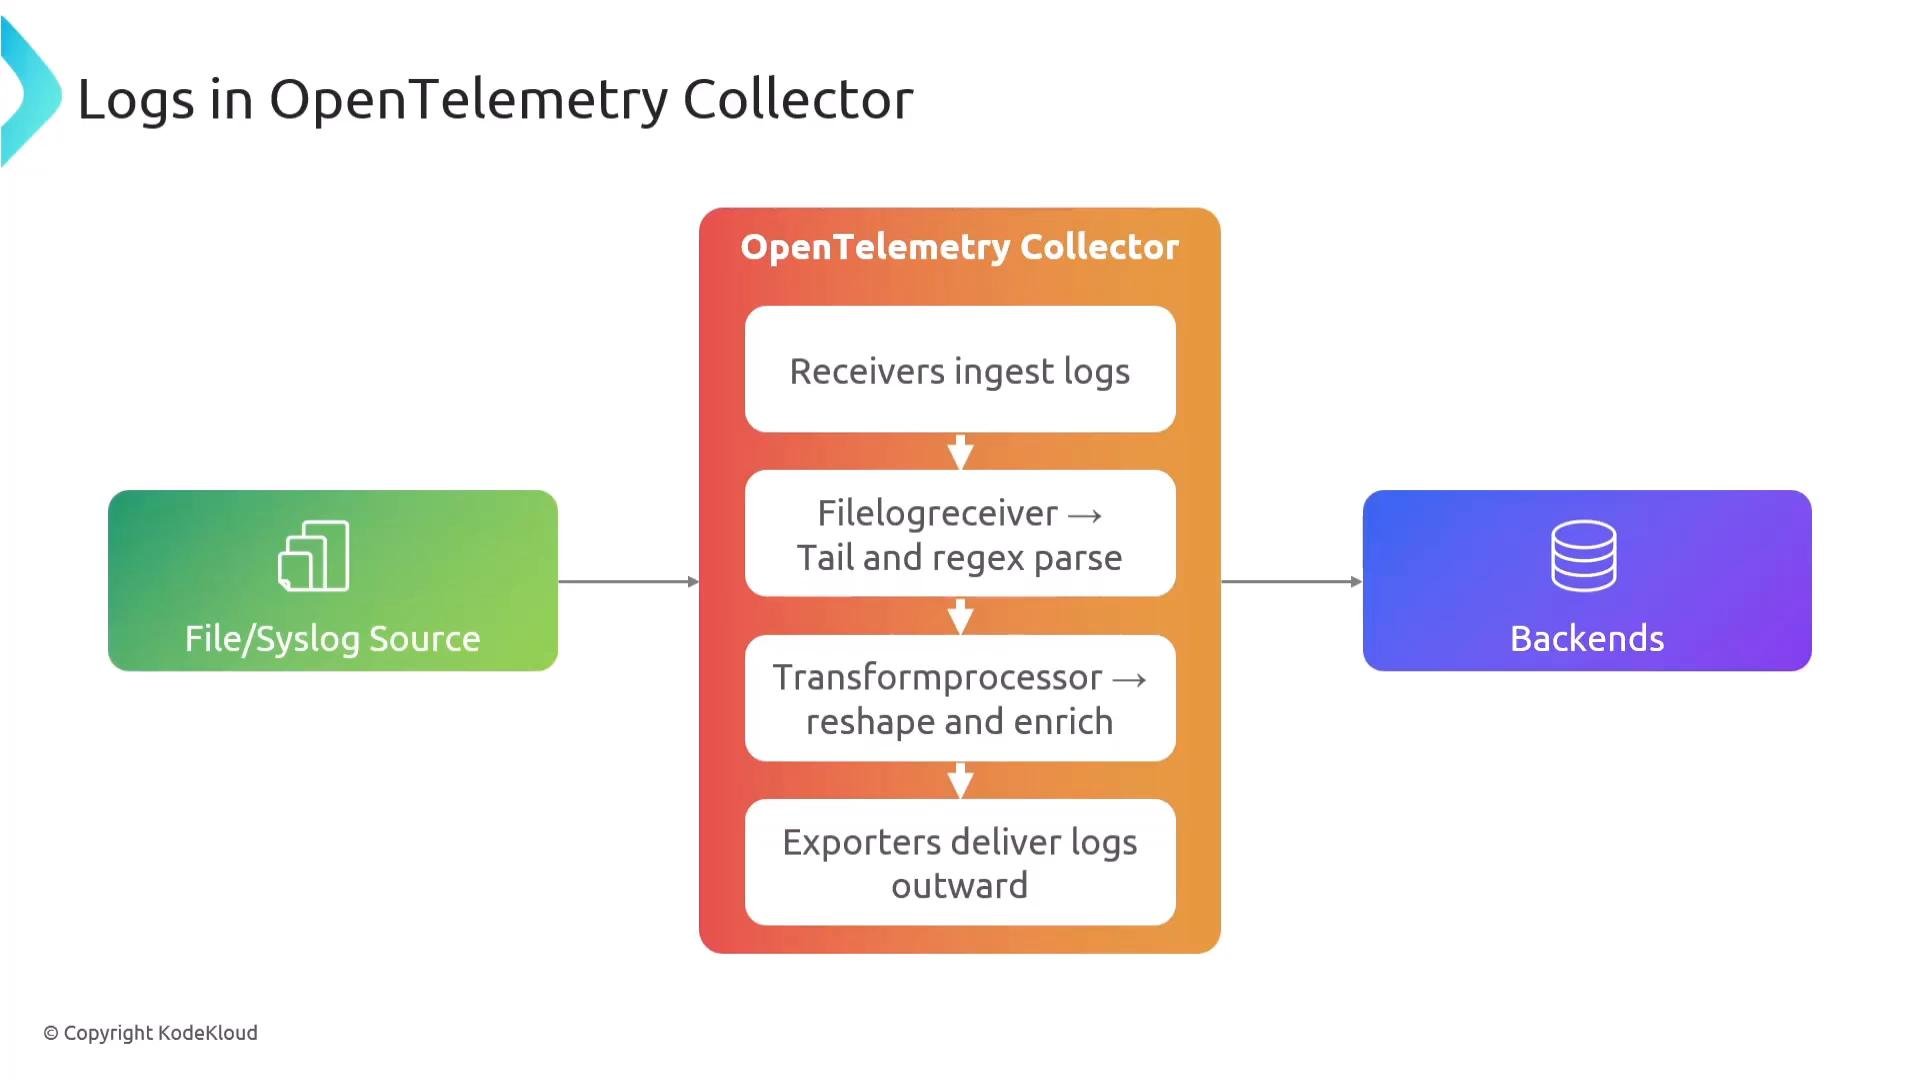
The OpenTelemetry Collector can operate as an agent (sidecar/host) or gateway. It enables you to ingest logs from external sources (file systems, syslog, Fluentd, etc.), apply processing (parsing, transforms, enrichment), and export to your backend(s). Using the Collector lets you centralize processing and reduce per-application complexity. Common Collector pipeline elements for logs:
This separation allows you to send logs to the Collector outside of application SDKs (e.g., tailing files), while still getting unified processing and export.
Correlating logs with traces
When your logging library is instrumented with OpenTelemetry (via SDKs or auto-instrumentation), each log entry can include the currenttrace_id and span_id. This cross-signal correlation enables richer troubleshooting inside observability platforms.
Example log lines enriched with trace/span identifiers:
Common log formats and examples
Broadly, logs follow three styles: structured (preferred), semi-structured, and unstructured. Structured logs (JSON) — predictable and machine-readable:Best practices and recommendations
- Prefer structured logs (JSON) with a consistent schema for services.
- Always include levels and service/host identifiers.
- Attach trace_id and span_id where possible to enable trace-log correlation.
- Use the OpenTelemetry Collector to centralize parsing, enrichment, and export.
- Avoid logging sensitive data (PII, credentials). Filter or redact at source or in Collector processors.
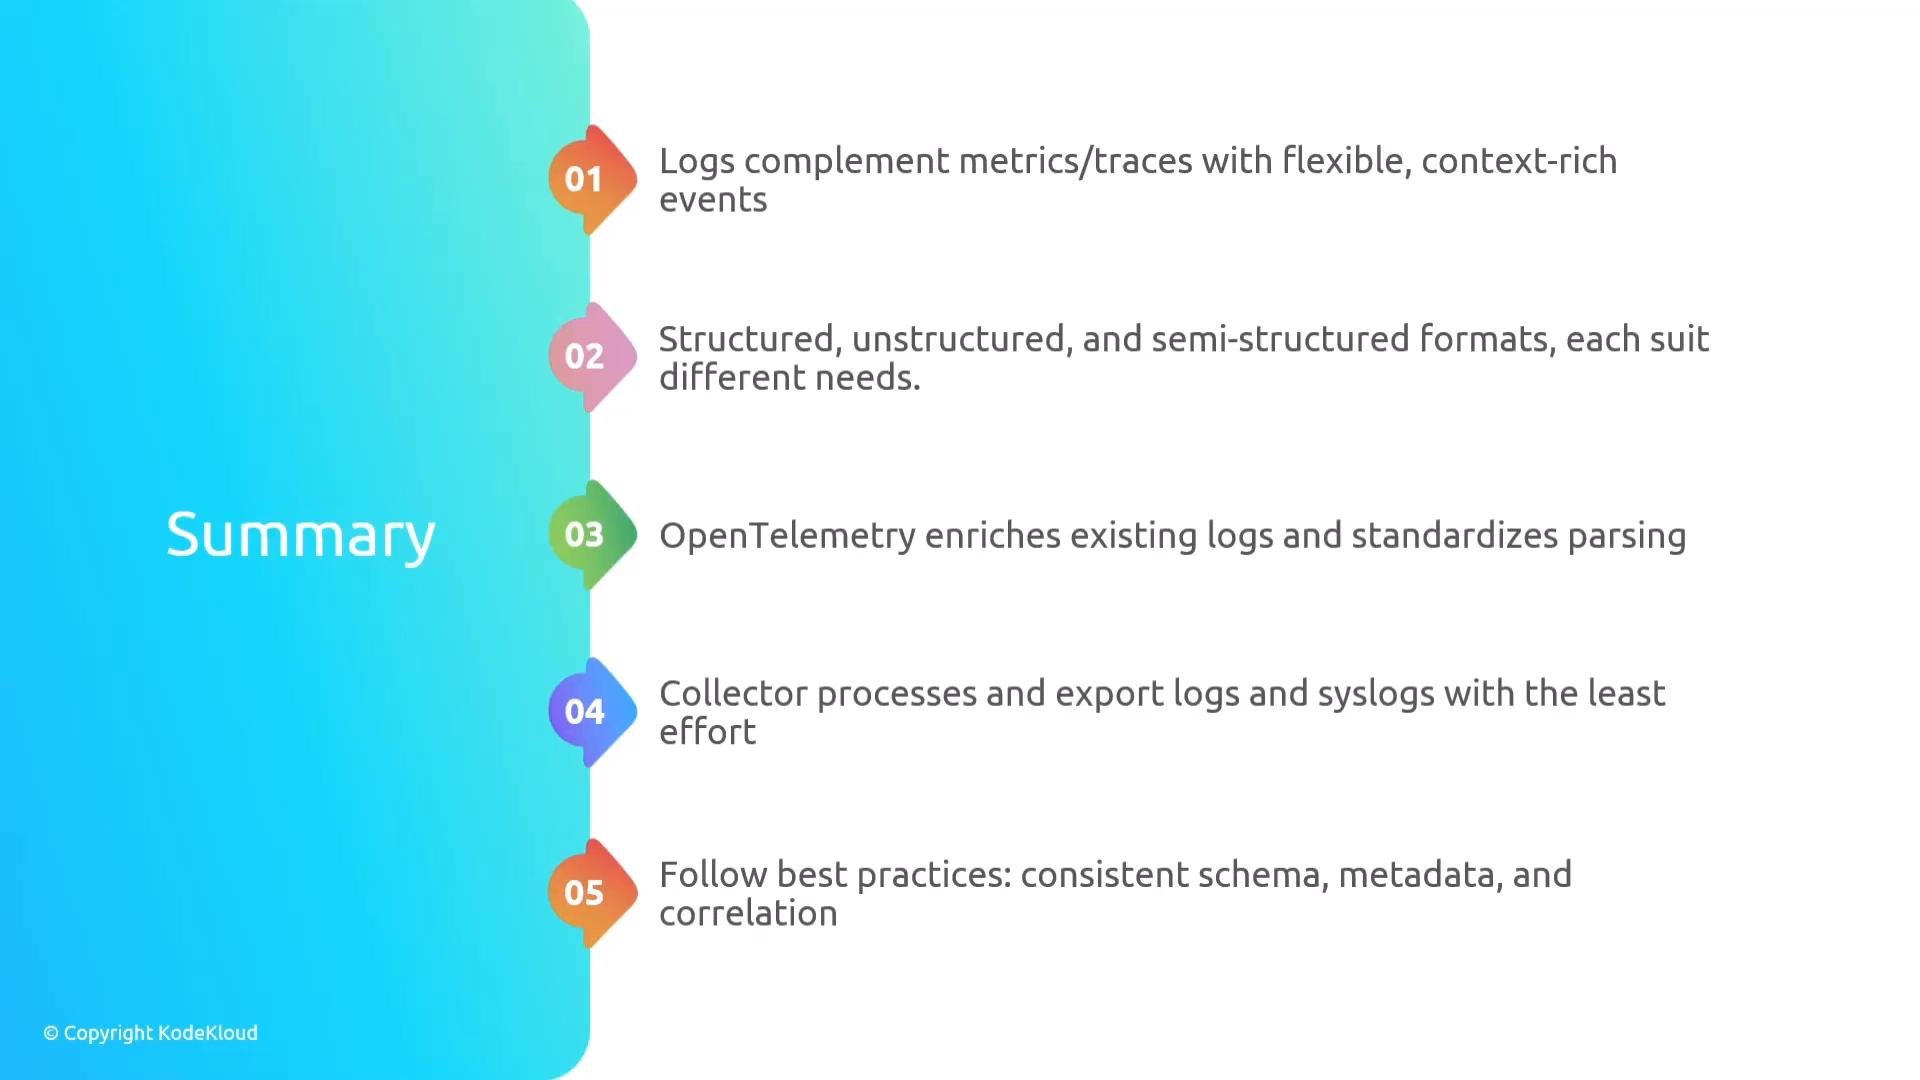
- Logs complement metrics and traces by providing flexible, context-rich events.
- Structured logs improve searchability and analysis; semi-structured logs are a useful compromise.
- OpenTelemetry enriches existing logging frameworks by adding trace/span context and a consistent export pipeline.
- The Collector can ingest logs from files/syslog, transform and enrich them, and export to backends without changing application code.
- Adopt a consistent logging schema and discipline to keep logs actionable and searchable.
Links and references
- OpenTelemetry Logs specification: https://opentelemetry.io/docs/ (see Logging / Logs)
- Common Log Format (CLF): https://en.wikipedia.org/wiki/Common_Log_Format
- OpenTelemetry Collector: https://opentelemetry.io/docs/collector/
- Best practices for structured logging: https://12factor.net/logs