

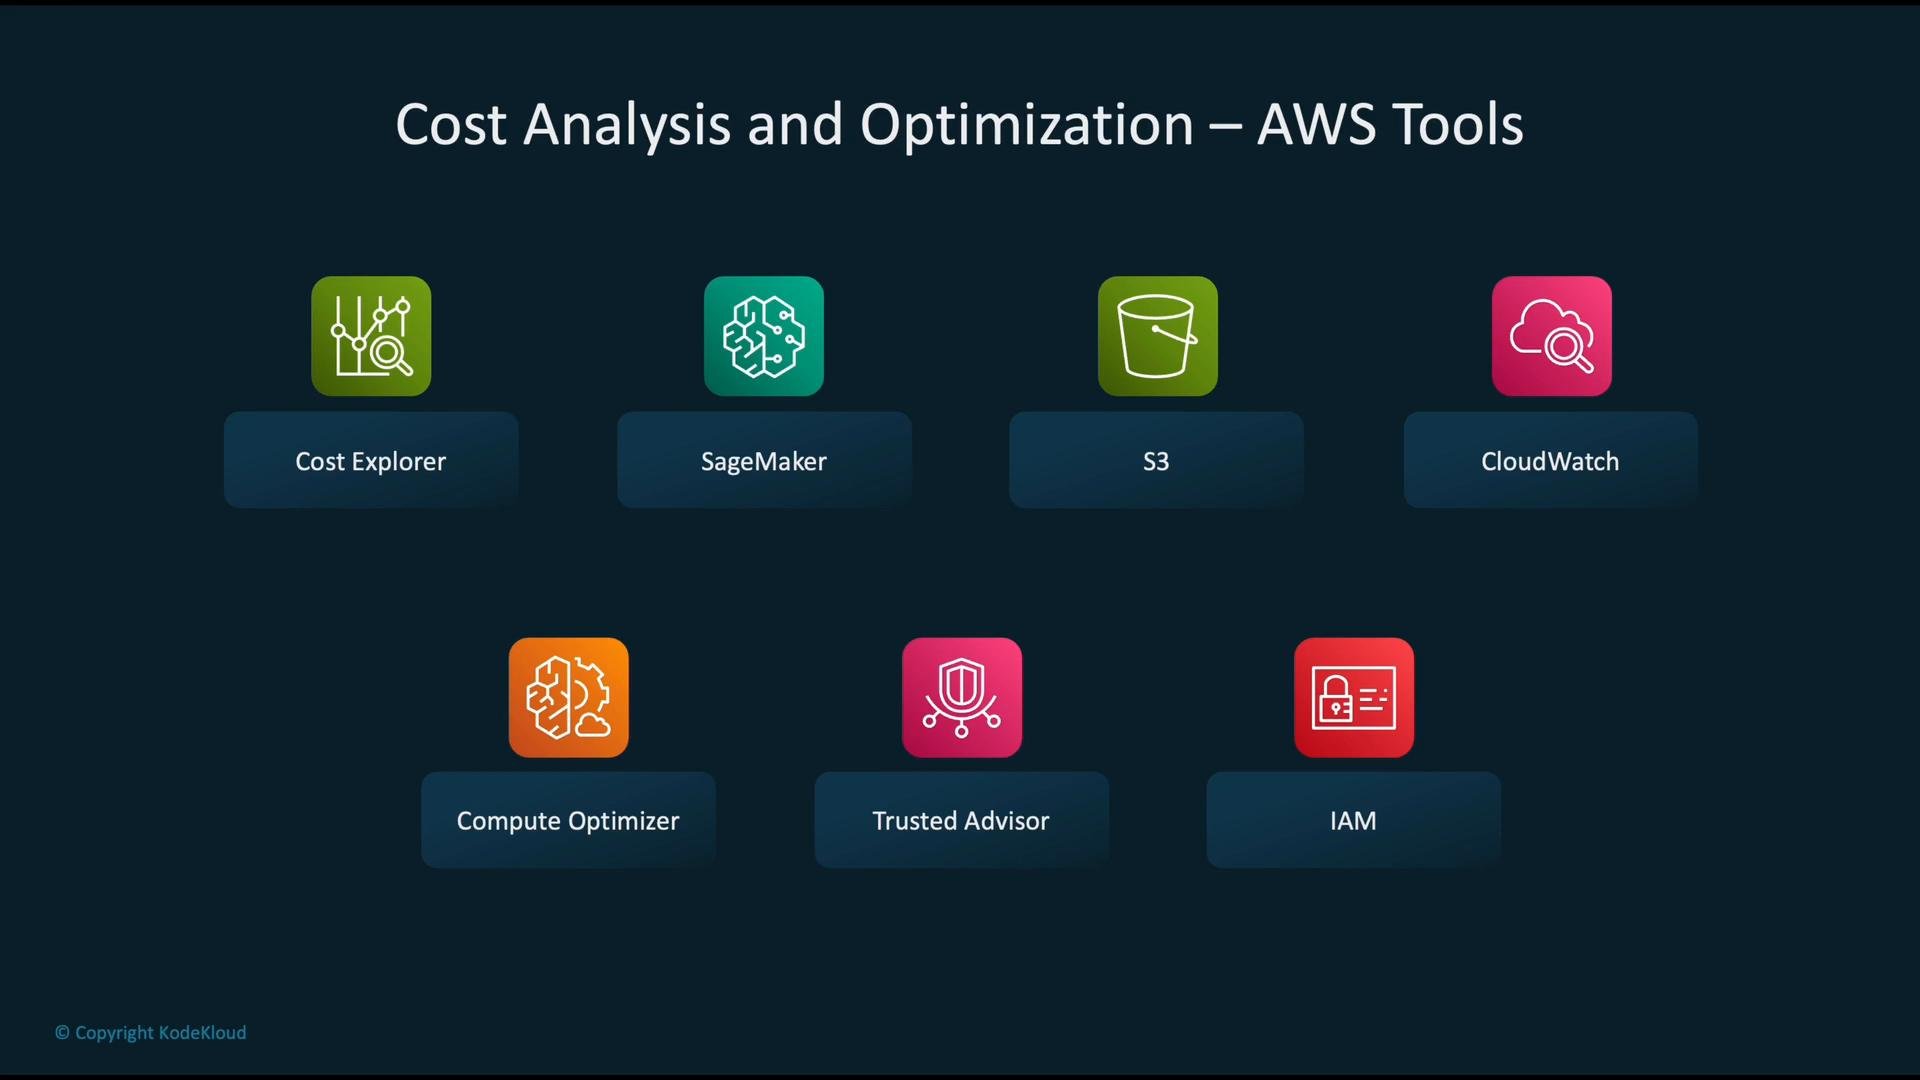
1) Start with cost attribution: tags and Cost Explorer
Begin by collecting and tagging ML resources consistently (for exampleMLWorkload=FraudDetection). Feeding those tags to Cost Explorer enables accurate, workload-level billing analysis and trend detection.
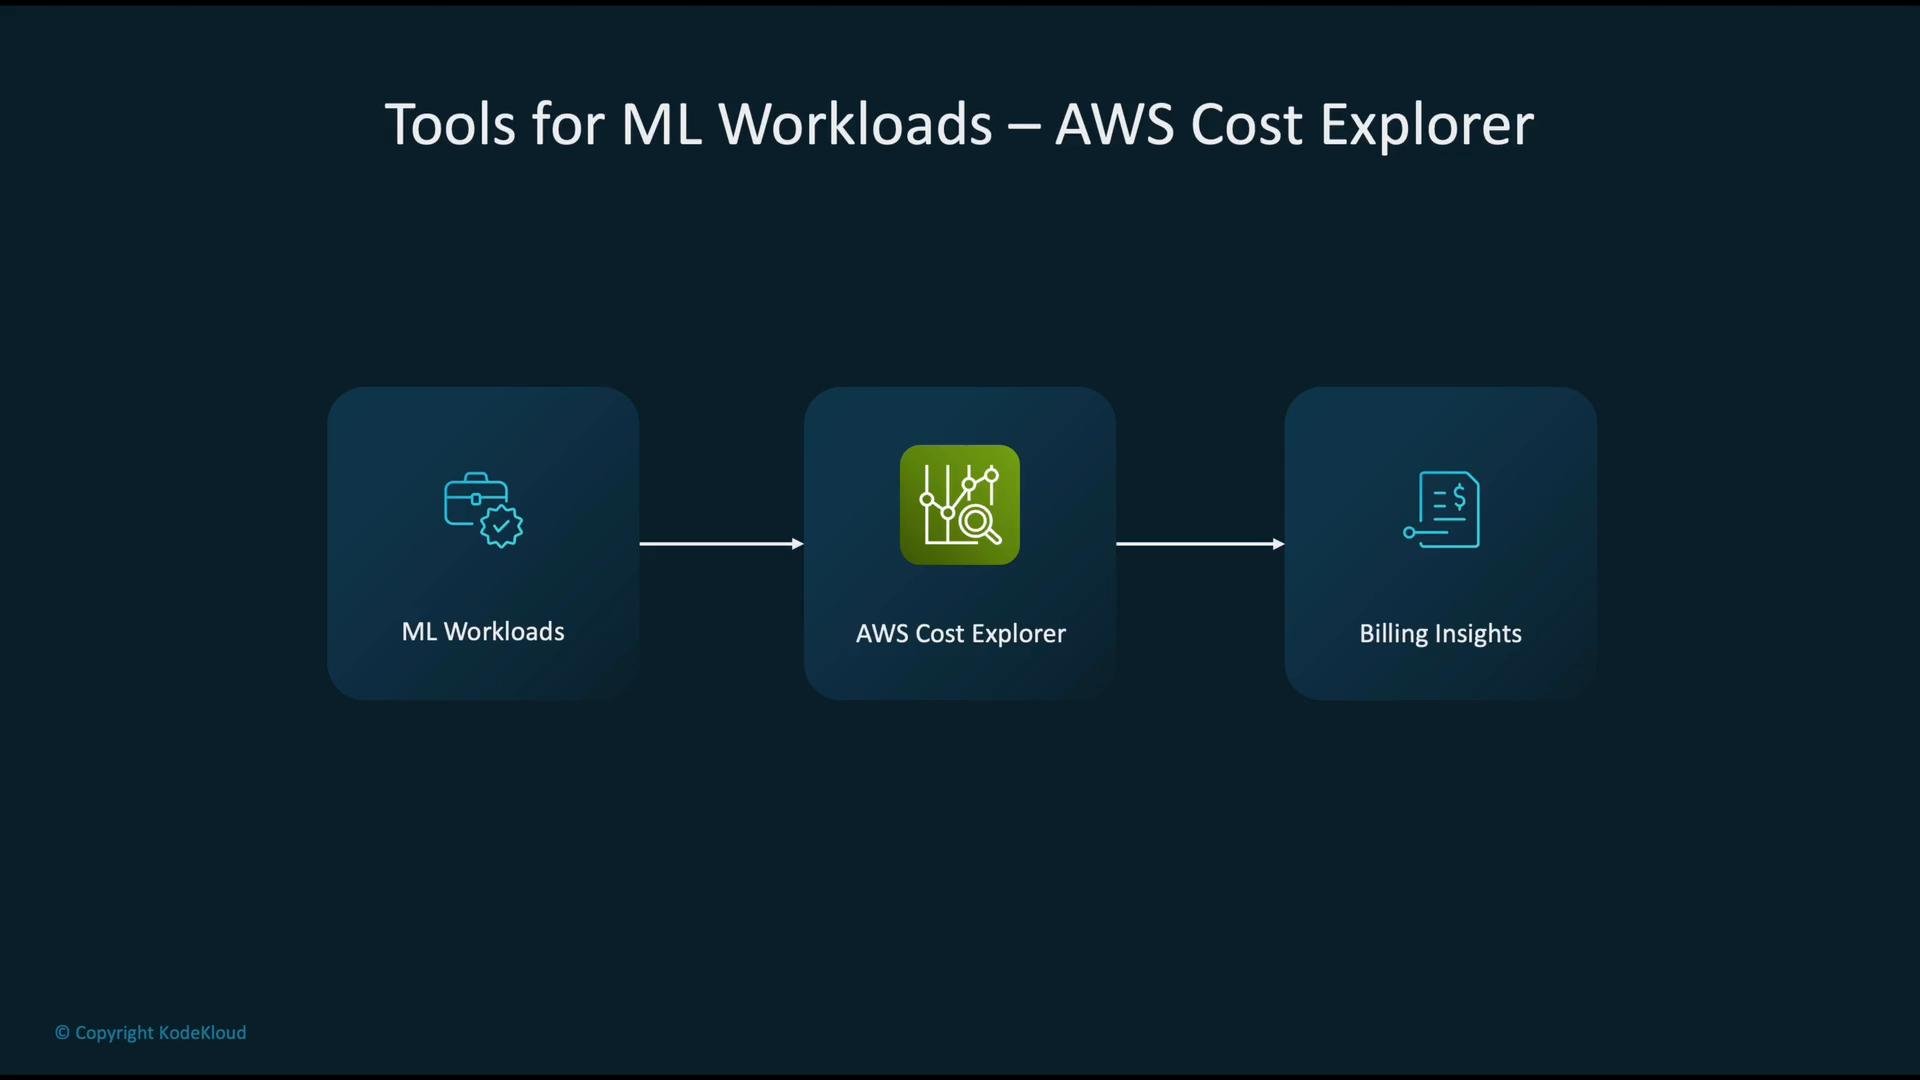
MLWorkload=FraudDetection. Use the ce boto3 client and ensure the account has ce:GetCostAndUsage permission.
Tagging resources consistently (for example
MLWorkload=FraudDetection) is critical for attributing costs correctly across teams and workloads. Make tagging part of CI/CD and provisioning templates.2) Reduce compute costs: SageMaker Spot, managed training, and checkpointing
Compute (training and inference) typically drives most ML cloud spend. Consider these strategies:- Use SageMaker Managed Spot Training to leverage excess EC2 capacity at large discounts.
- Enable checkpointing so interrupted Spot instances resume without losing progress.
- Use multi-instance distributed training only when it lowers wall-clock time sufficiently to justify extra instances.
- Combine Spot with Reserved or Savings Plans for predictable baseline workloads.
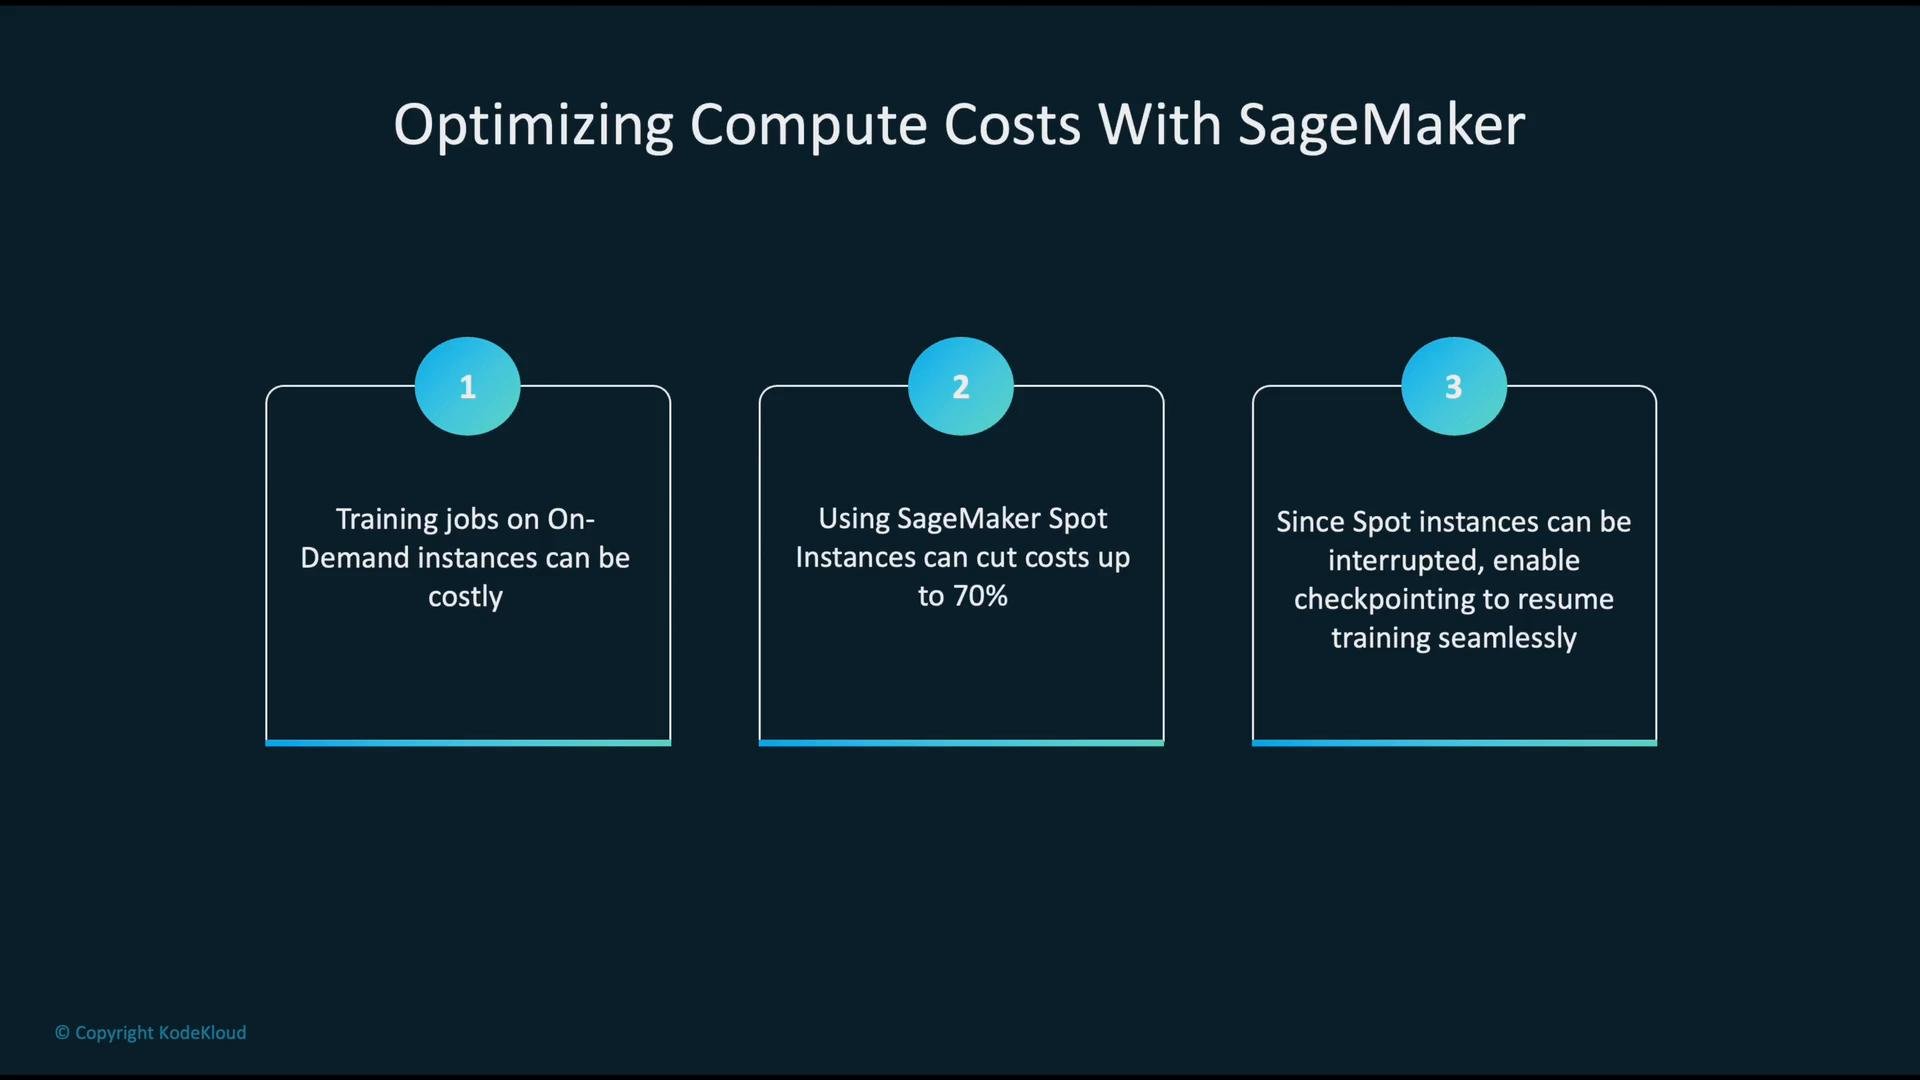
Spot instances can be interrupted with little notice. Always design training jobs to checkpoint model state and resume training to avoid lost progress and wasted resource time.
EnableManagedSpotTraining=True and MaxWaitTimeInSeconds to let the job wait for Spot capacity.
3) Optimize storage costs with S3 lifecycle policies
Storage for training data, intermediate artifacts, and model checkpoints can be expensive if left in hot storage. Apply lifecycle policies that automatically move objects to lower-cost tiers as access patterns age. A common lifecycle progression: S3 Standard → Intelligent‑Tiering → Standard‑IA → Glacier / Glacier Deep Archive.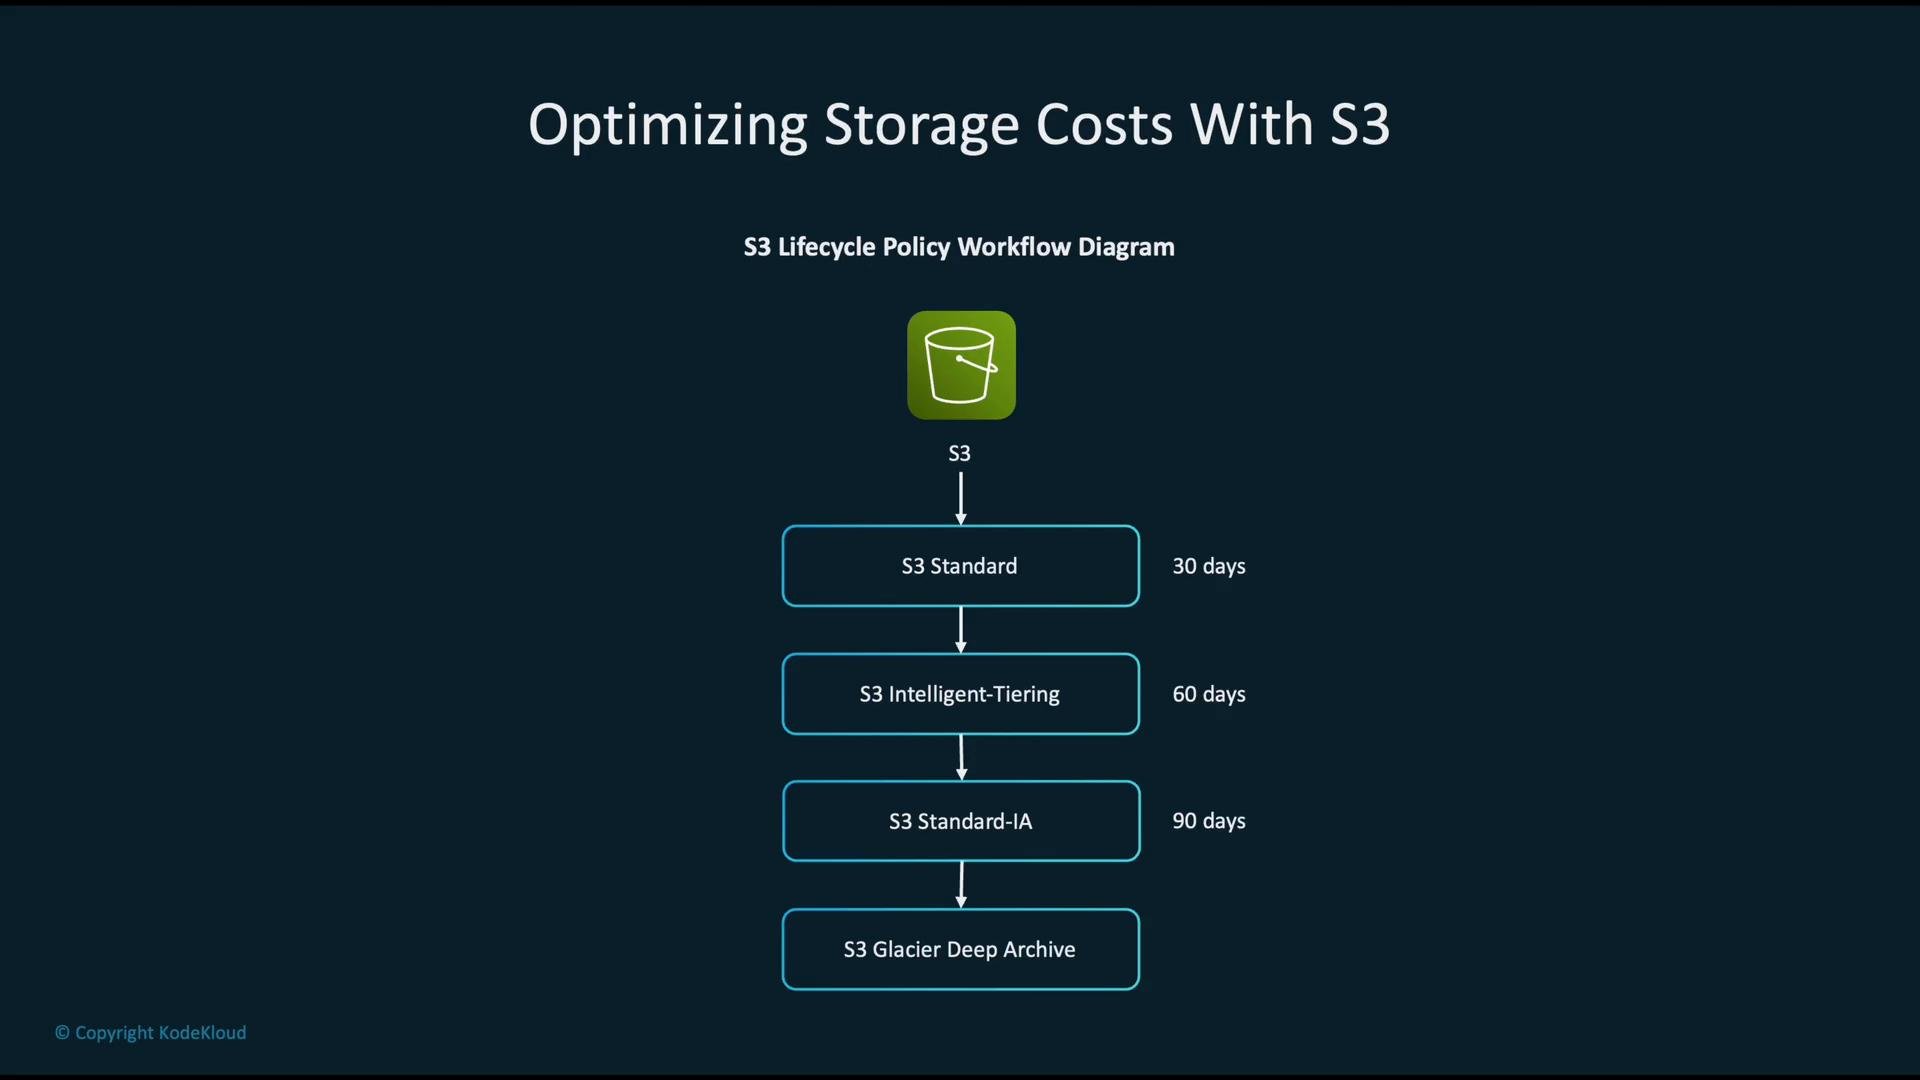
ml-data/ are transitioned to Glacier after 30 days. Adjust StorageClass to DEEP_ARCHIVE if you require Glacier Deep Archive.
- Store frequently used datasets in Standard or Intelligent‑Tiering.
- Use object lifecycle rules on experiment/temporary folders.
- Use S3 object locking/versioning policies when you need retention guarantees but still want to tier storage.
4) Monitor costs and tune monitoring to avoid runaway monitoring spend
Monitoring itself can generate recurring costs (high-cardinality metrics, long retention, noisy alarms). Review CloudWatch usage and optimize:- Reduce retention windows for rarely used metrics.
- Avoid high-cardinality dimensions unless essential.
- Aggregate metrics where possible and tune alarm thresholds to reduce false positives.
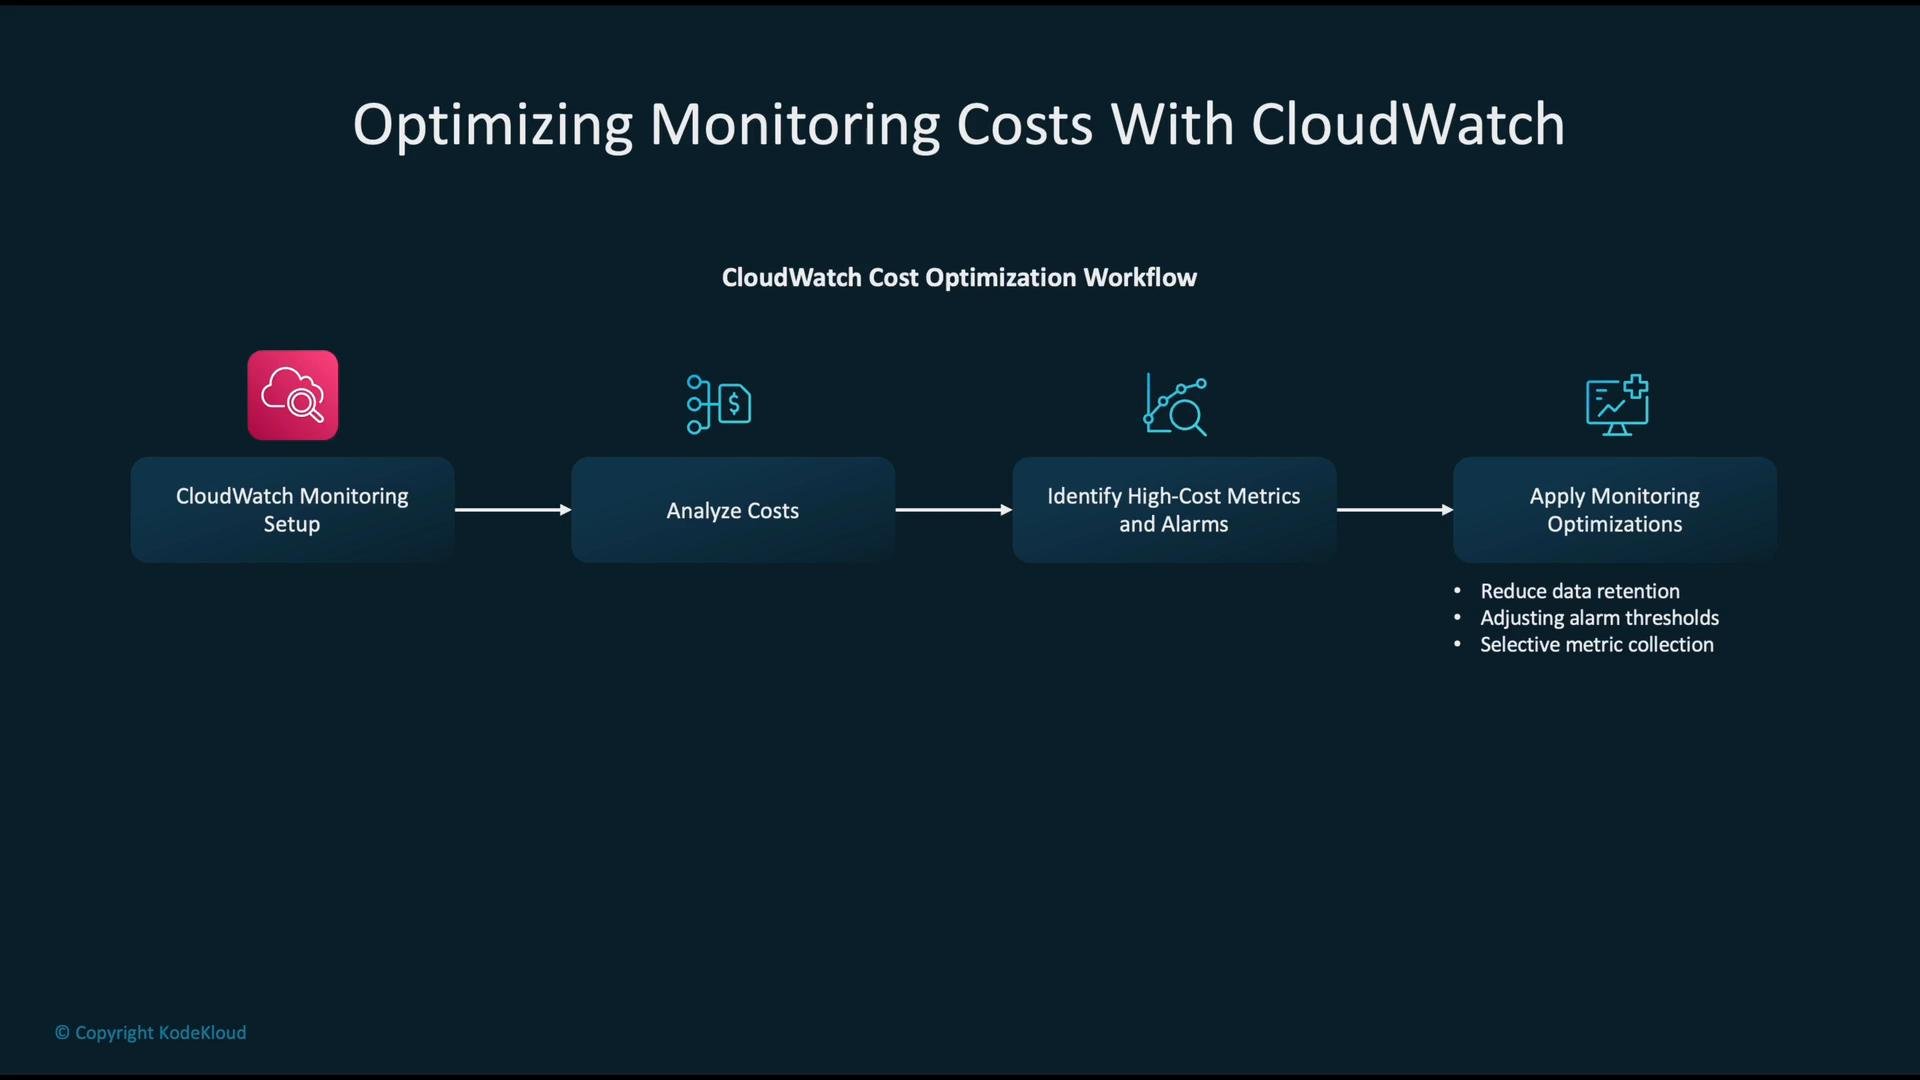
EstimatedCharges metric scoped to the AmazonCloudWatch service and configured to notify an SNS topic.
5) Scale inference efficiently with Auto Scaling
For variable inference traffic, use Auto Scaling (EC2 Auto Scaling groups, ECS/EKS autoscaling, or SageMaker endpoint autoscaling) to match capacity to demand. Scale both horizontally and vertically where appropriate, and use predictive scaling if your traffic has predictable patterns.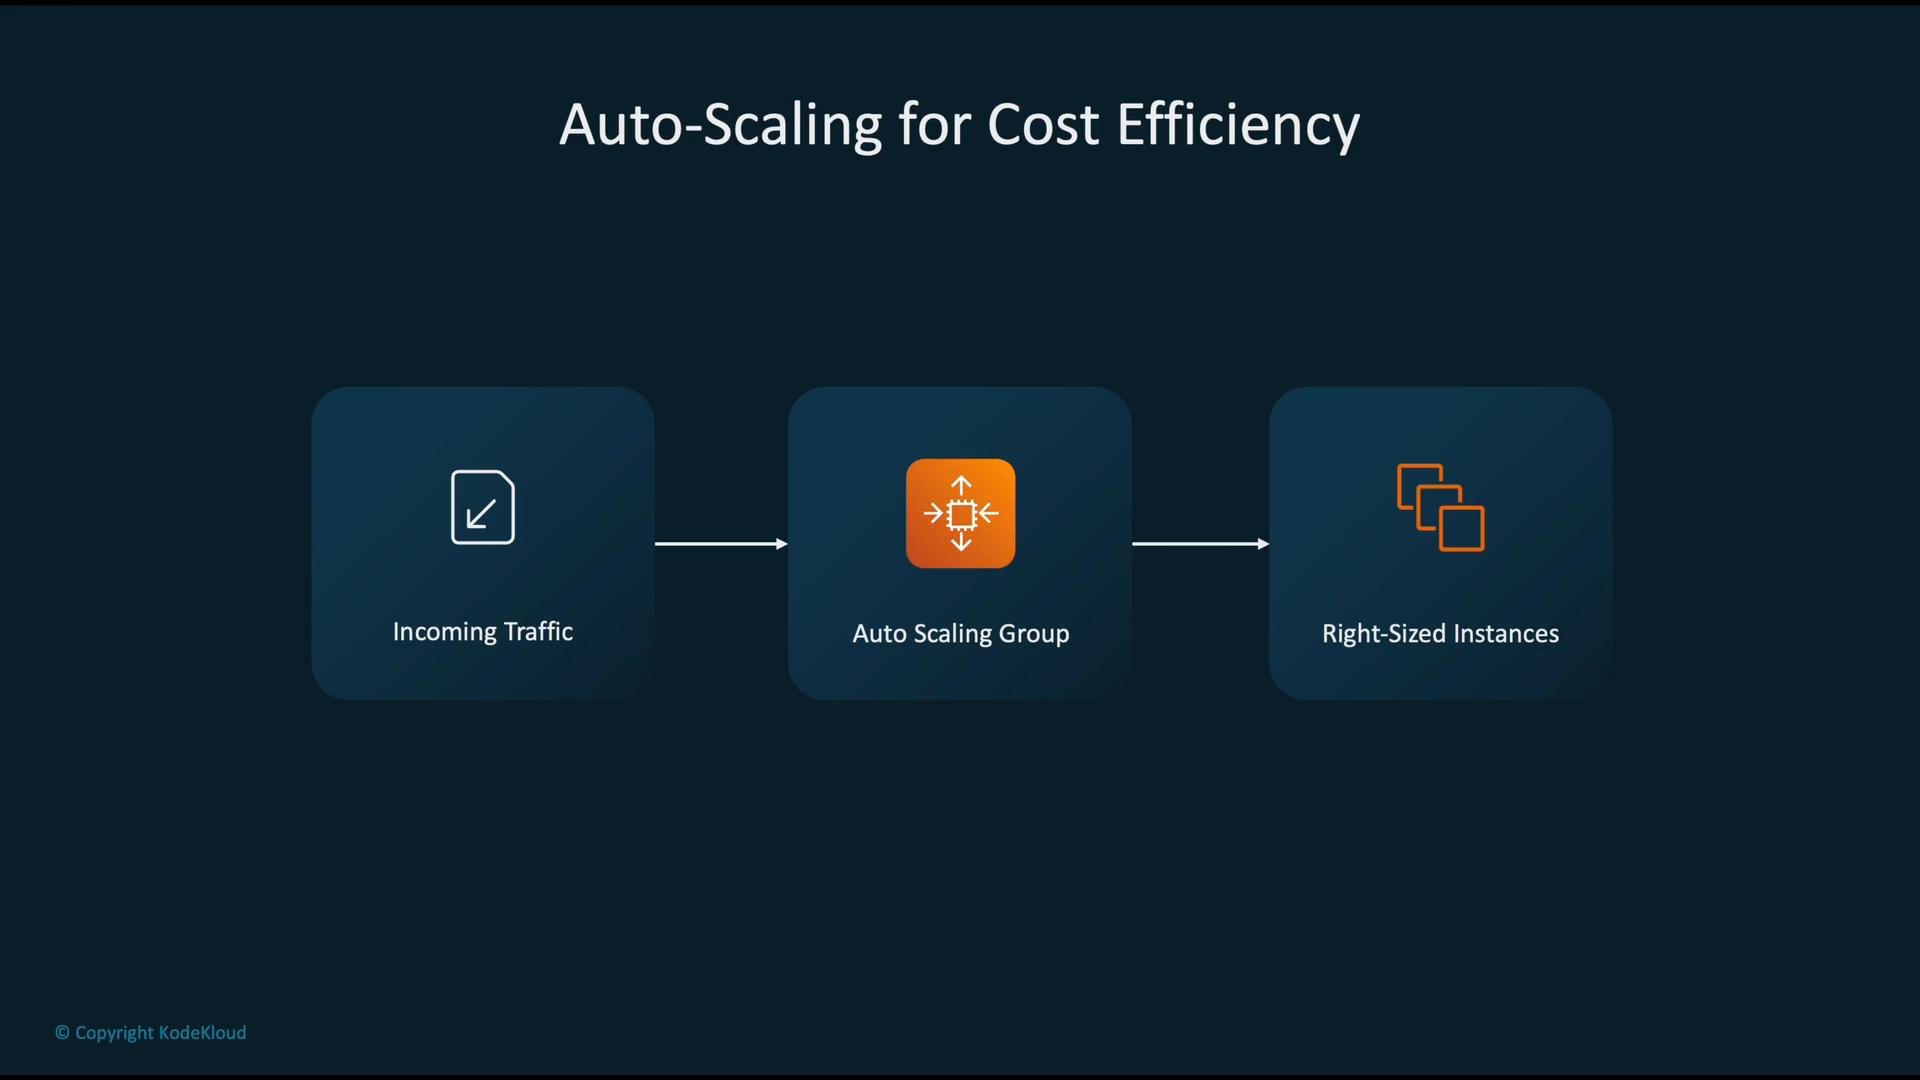
6) Rightsizing and governance
Right-sizing is iterative:- Run representative training and inference workloads.
- Use Compute Optimizer to analyze utilization and recommend instance sizes.
- Review Trusted Advisor for cost-related best practices.
- Apply changes gradually and measure performance vs. cost tradeoffs.
Common anti-patterns that drive unnecessary spend
- Relying only on on-demand pricing (missing Spot, Reserved, or Savings Plan optimizations).
- Not applying S3 lifecycle rules (paying premium for cold data).
- Ignoring billing alarms (delaying detection of overruns).
- Not right-sizing workloads (running idle or overpowered instances).
- Allowing broad IAM permissions that enable accidental resource creation.