

kubectl top to monitor CPU and memory usage for nodes and pods. The lab environment already runs three application pods: elephant, lion, and rabbit.
Verify running pods
Start by listing the pods in the cluster. You should see the three workload pods inRunning state:
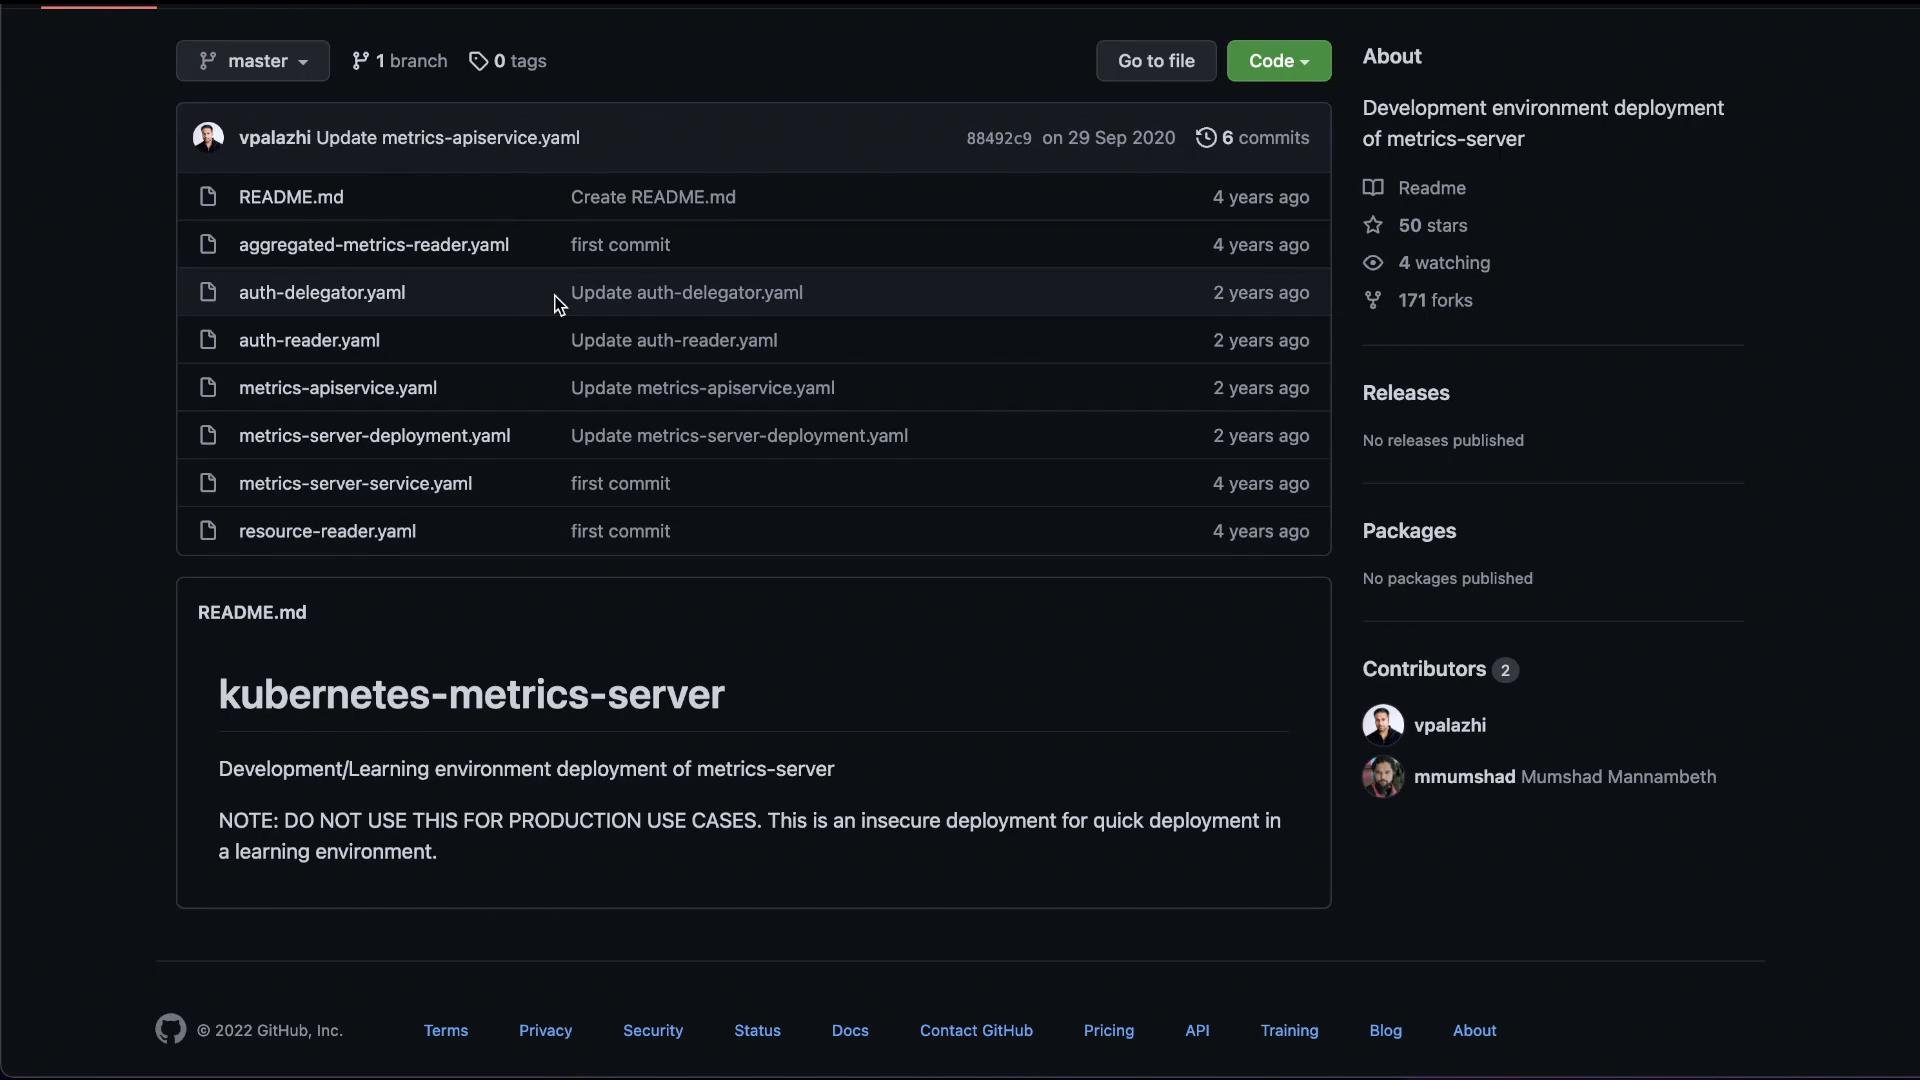
Clone the prepared Metrics Server repository
This lab supplies a test repository with manifests tailored for the exercise. Clone it to the control plane and inspect the files:Do not use the lab repository directly in production. The manifests may be simplified or modified for the lab environment. For production deployments, follow the official Metrics Server documentation: https://github.com/kubernetes-sigs/metrics-server
Deploy the Metrics Server manifests
From the cloned repository directory, create the required resources to install the Metrics Server:The Metrics Server may take a short while to become ready and start publishing metrics to the Metrics API. Wait a minute, then use
kubectl top to query node and pod metrics.Use kubectl top to view resource usage
Once the Metrics Server is collecting metrics,kubectl top reports CPU and memory usage for nodes and pods.
Example output for nodes:
Interpretation — identify heavy resource consumers
Use thekubectl top results to answer common monitoring questions. The primary consumers in this example are:
And the direct answers to the lab questions:
Links and references
- Metrics Server GitHub repository: https://github.com/kubernetes-sigs/metrics-server
- kubectl documentation: https://kubernetes.io/docs/reference/generated/kubectl/kubectl-commands#top
kubectl top to identify nodes and pods that consume the most resources.