

What is a blue-green deployment?
- Maintain two parallel environments: the active production environment (blue) and a staged replacement (green).
- Deploy the new version into green, validate it, then switch user traffic from blue to green.
- Benefits:
- Near-zero downtime
- Fast, reliable rollback (keep blue until green proves stable)
- Strong testability and verification of the production-ready artifact
- Reduced configuration drift by treating environments as immutable
Common AWS approaches for traffic shifting
- More about Route 53: https://docs.aws.amazon.com/Route53/latest/DeveloperGuide/
- More about CodeDeploy: https://docs.aws.amazon.com/codedeploy/latest/userguide/welcome.html
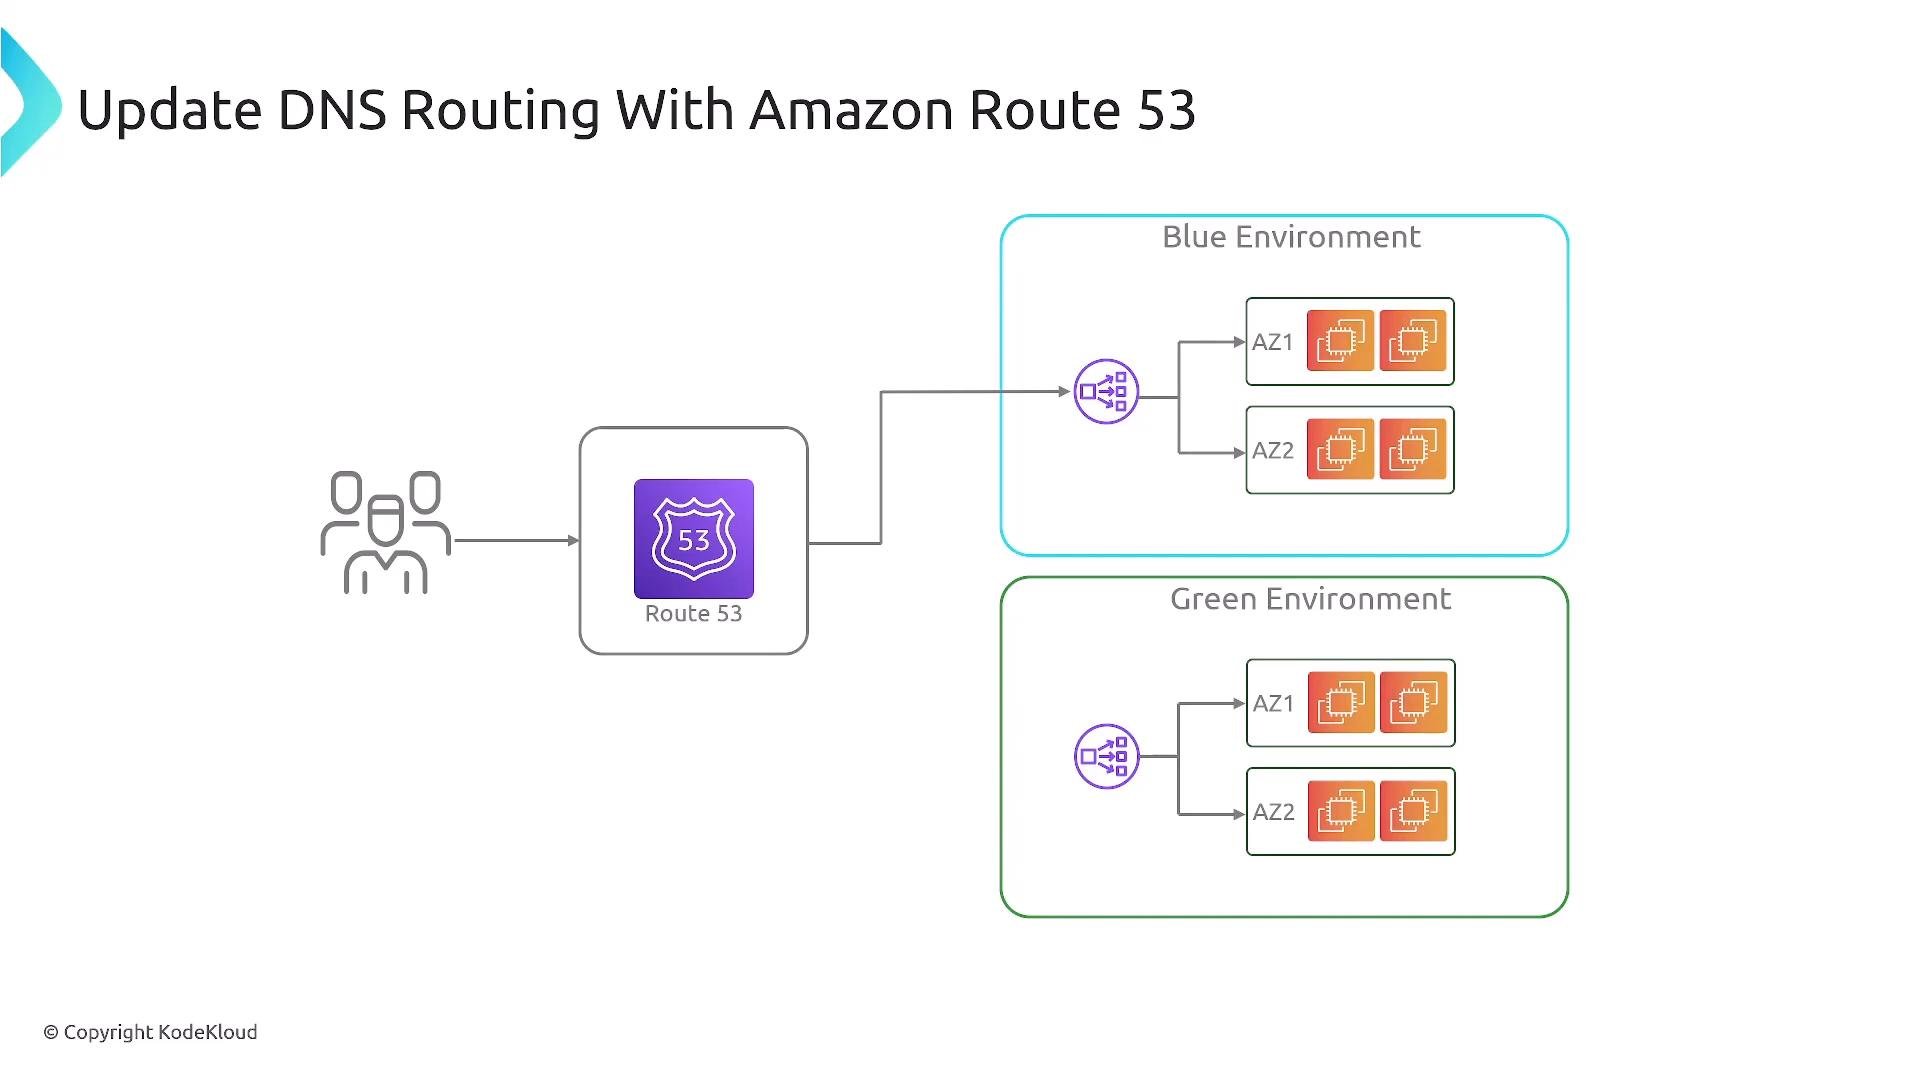
Route 53 traffic shifting
- Route 53 supports weighted record sets so you can migrate traffic progressively (for example 0% → 10% → 25% → 50% → 100%).
- It works for single instances, instance groups, Auto Scaling groups, ECS services, EKS clusters, Elastic Beanstalk, and other resources that Route 53 can resolve.
- Note: DNS TTLs and client DNS caching affect how quickly weight changes take effect.
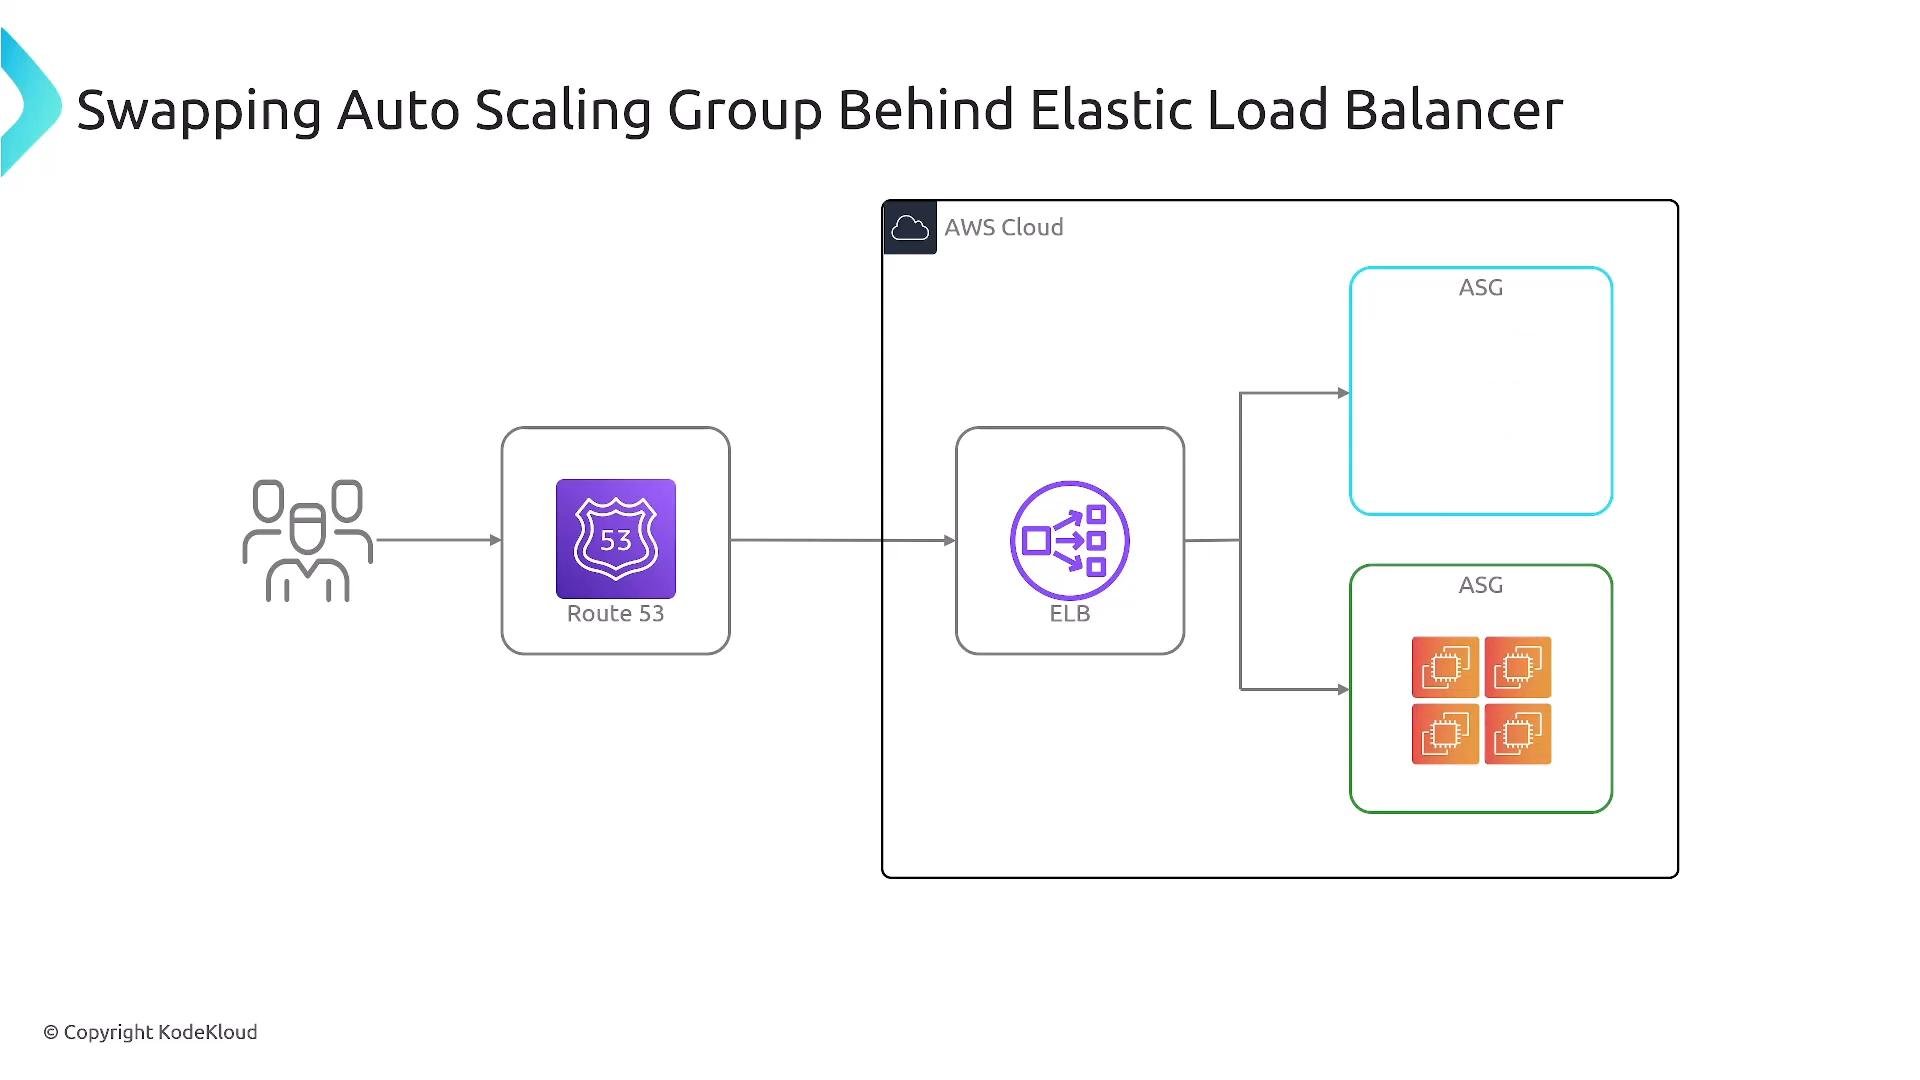
Auto Scaling group swap behind a load balancer
- Create green ASGs and attach them (or their target groups) to the Load Balancer while blue still serves production.
- When green passes validation, change the LB target to green (or set weights on target groups).
- Keep blue available for a quick rollback, or terminate it after you’re confident in green.
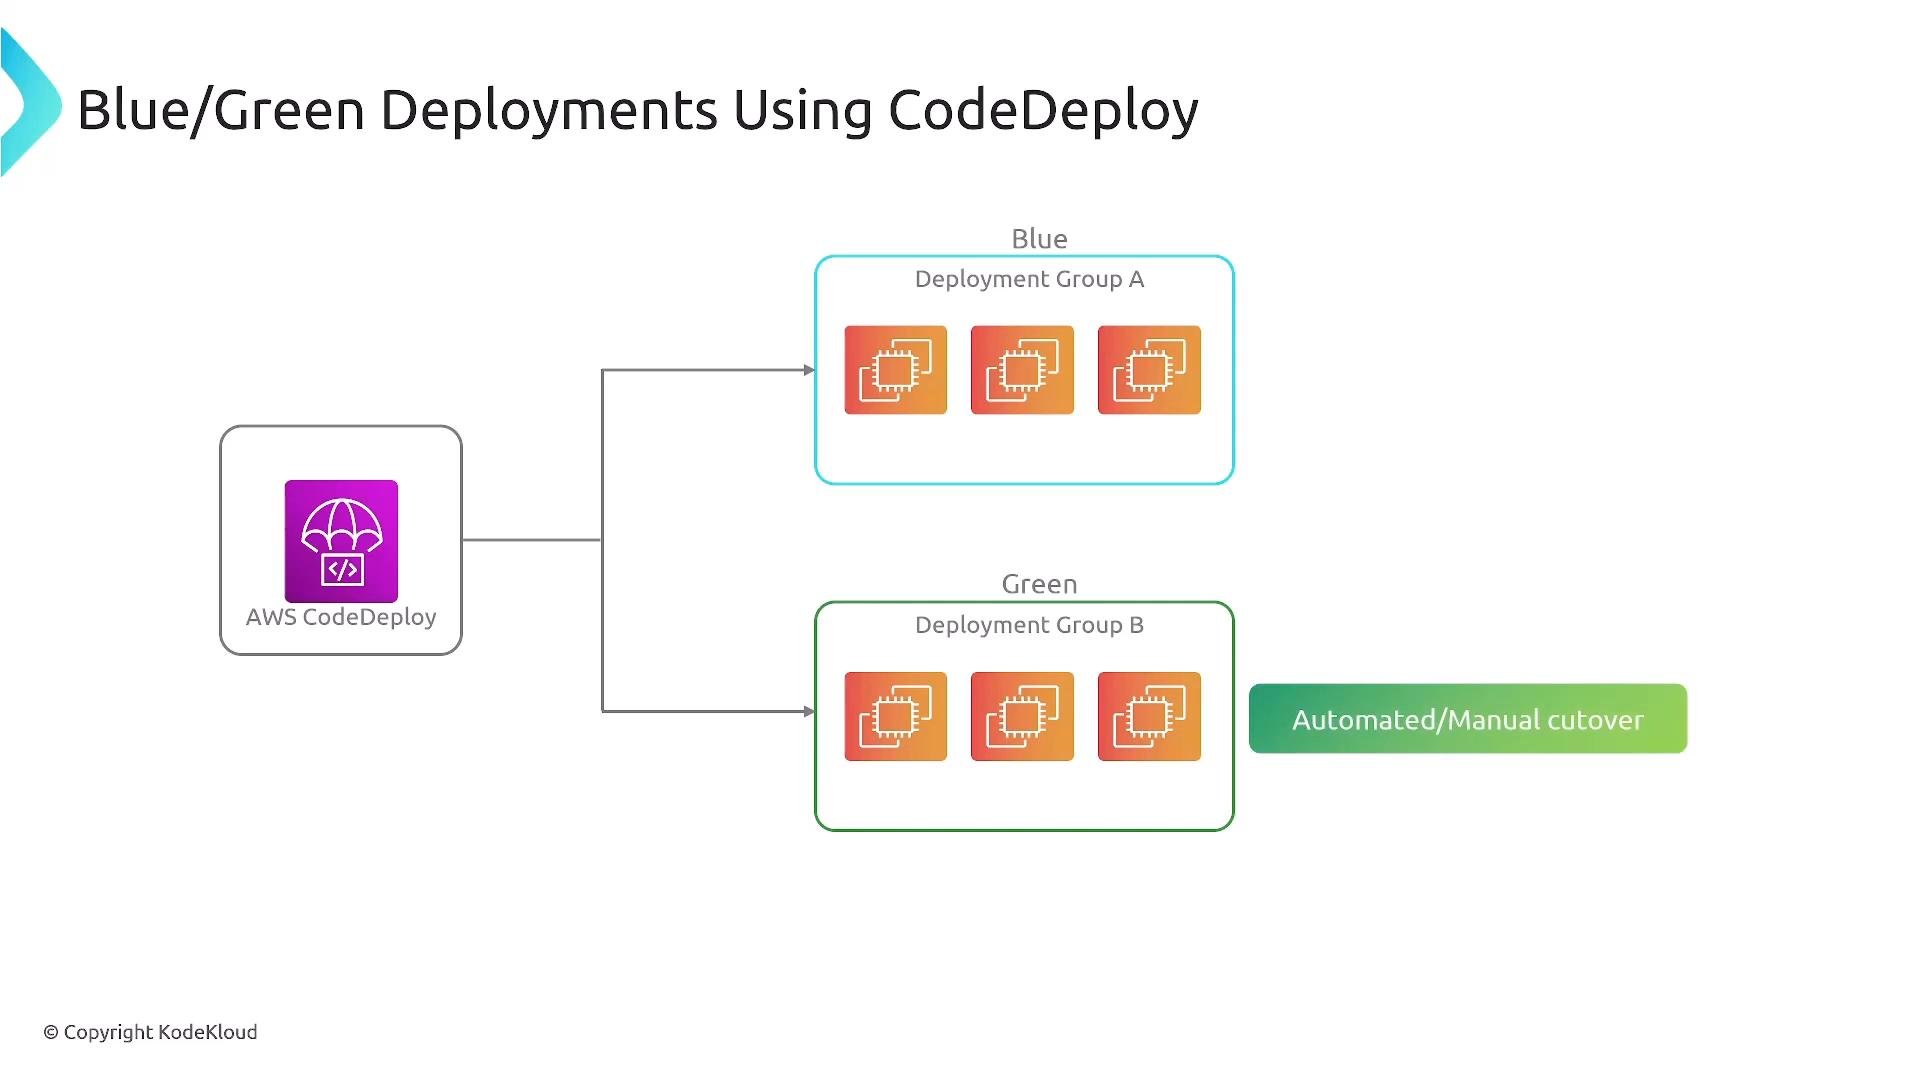
AWS CodeDeploy blue/green deployments
- CodeDeploy automates blue/green workflow, supports traffic shifting strategies, and runs health checks during deployment.
- Integrates with Auto Scaling groups, Amazon ECS, and Lambda alias-based deployments.
- Supports automated or manual cutover and rollback triggers.
Typical pipeline flow (recommended)
- Developer commits code to VCS.
- Build stage (e.g., AWS CodeBuild or equivalent) produces immutable artifacts (images, packages).
- Pipeline deploys artifacts to green (ECS task set, Auto Scaling group, Lambda alias, etc.).
- Health checks and smoke tests validate green (API checks, integration tests, synthetic transactions).
- Shift traffic via Load Balancer (target group swap/weight) or Route 53 (incremental weights).
- Keep blue as a rollback target until green is confirmed stable; then decommission blue as appropriate.
Automate the pipeline and use a consistent health-check mechanism (load balancer, Route 53 health checks, or application-level probes). Configure automated rollback triggers based on health checks and critical metrics to reduce mean time to recovery.
Gradual (canary) rollouts
- Canary rollouts let you route a small percentage of traffic to green initially (for example, 10% every 10 minutes) and increase as confidence grows.
- Monitor key signals (latency, error rate, throughput, logs) before increasing traffic increments.
- Canary strategies pair well with feature flags and observability dashboards.
Monitoring and rollback
- Continuously monitor application metrics (latency, error rates, user-facing KPIs), infrastructure metrics, and logs during each rollout step.
- Define clear automated rollback criteria (e.g., error rate spike > X% or latency above threshold for Y minutes).
- Have a documented manual fallback plan to switch back to blue quickly if automation fails.
Common failure modes and how to avoid them
- Provisioning failures: green environment fails to provision. Mitigation: CI/CD should validate infra provisioning in an isolated stage.
- Permission errors: missing IAM permissions for deployment. Mitigation: least-privilege IAM roles and test role permissions in staging.
- Application start-up failures: environment differences (config, secrets, env vars) break startup. Mitigation: ensure configuration parity and secret management parity between blue and green.
- DNS or load balancer misrouting: incorrect rules or cached DNS entries cause unexpected traffic distribution. Mitigation: validate routing rules and account for DNS TTL/client caching.
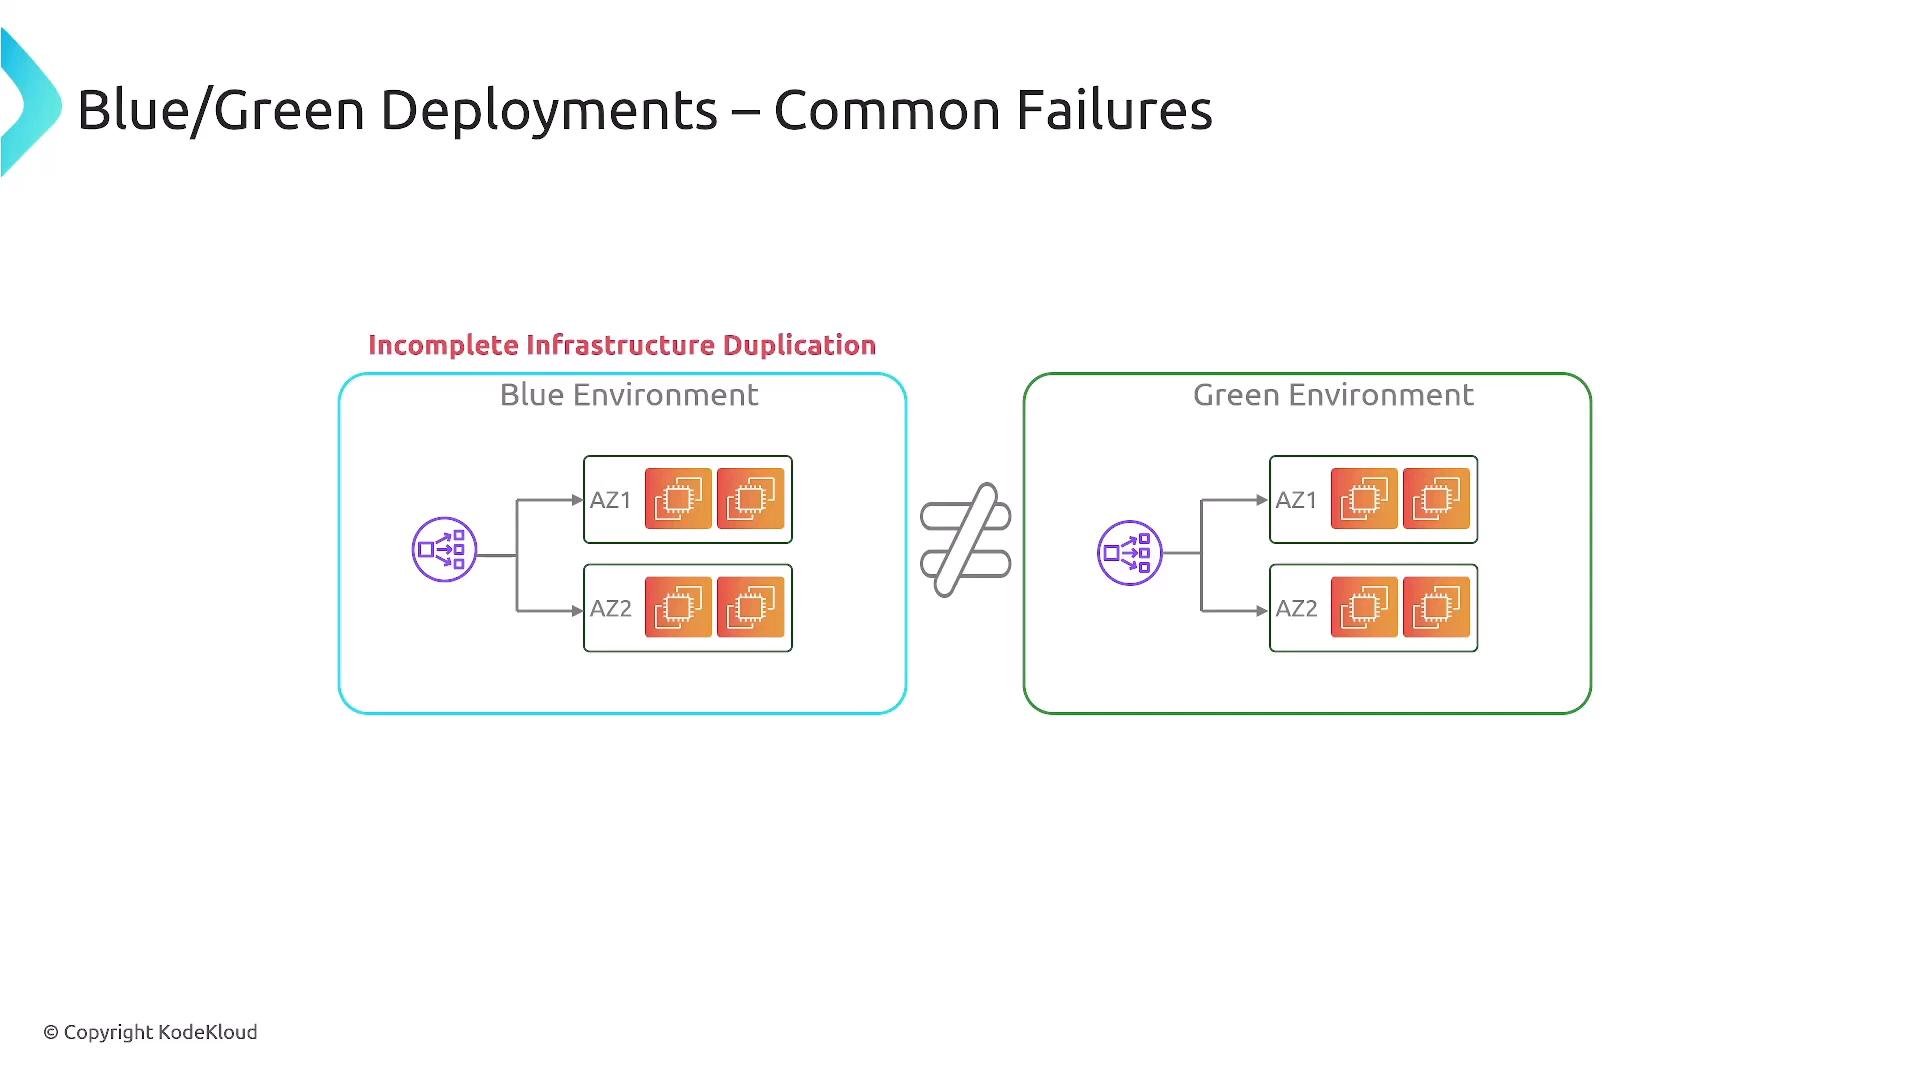
- Incomplete infrastructure duplication: not all resources (databases, caches, or feature flags) were duplicated or toggled correctly. Mitigation: run pre-cutover checks and maintain infrastructure-as-code templates to ensure parity.
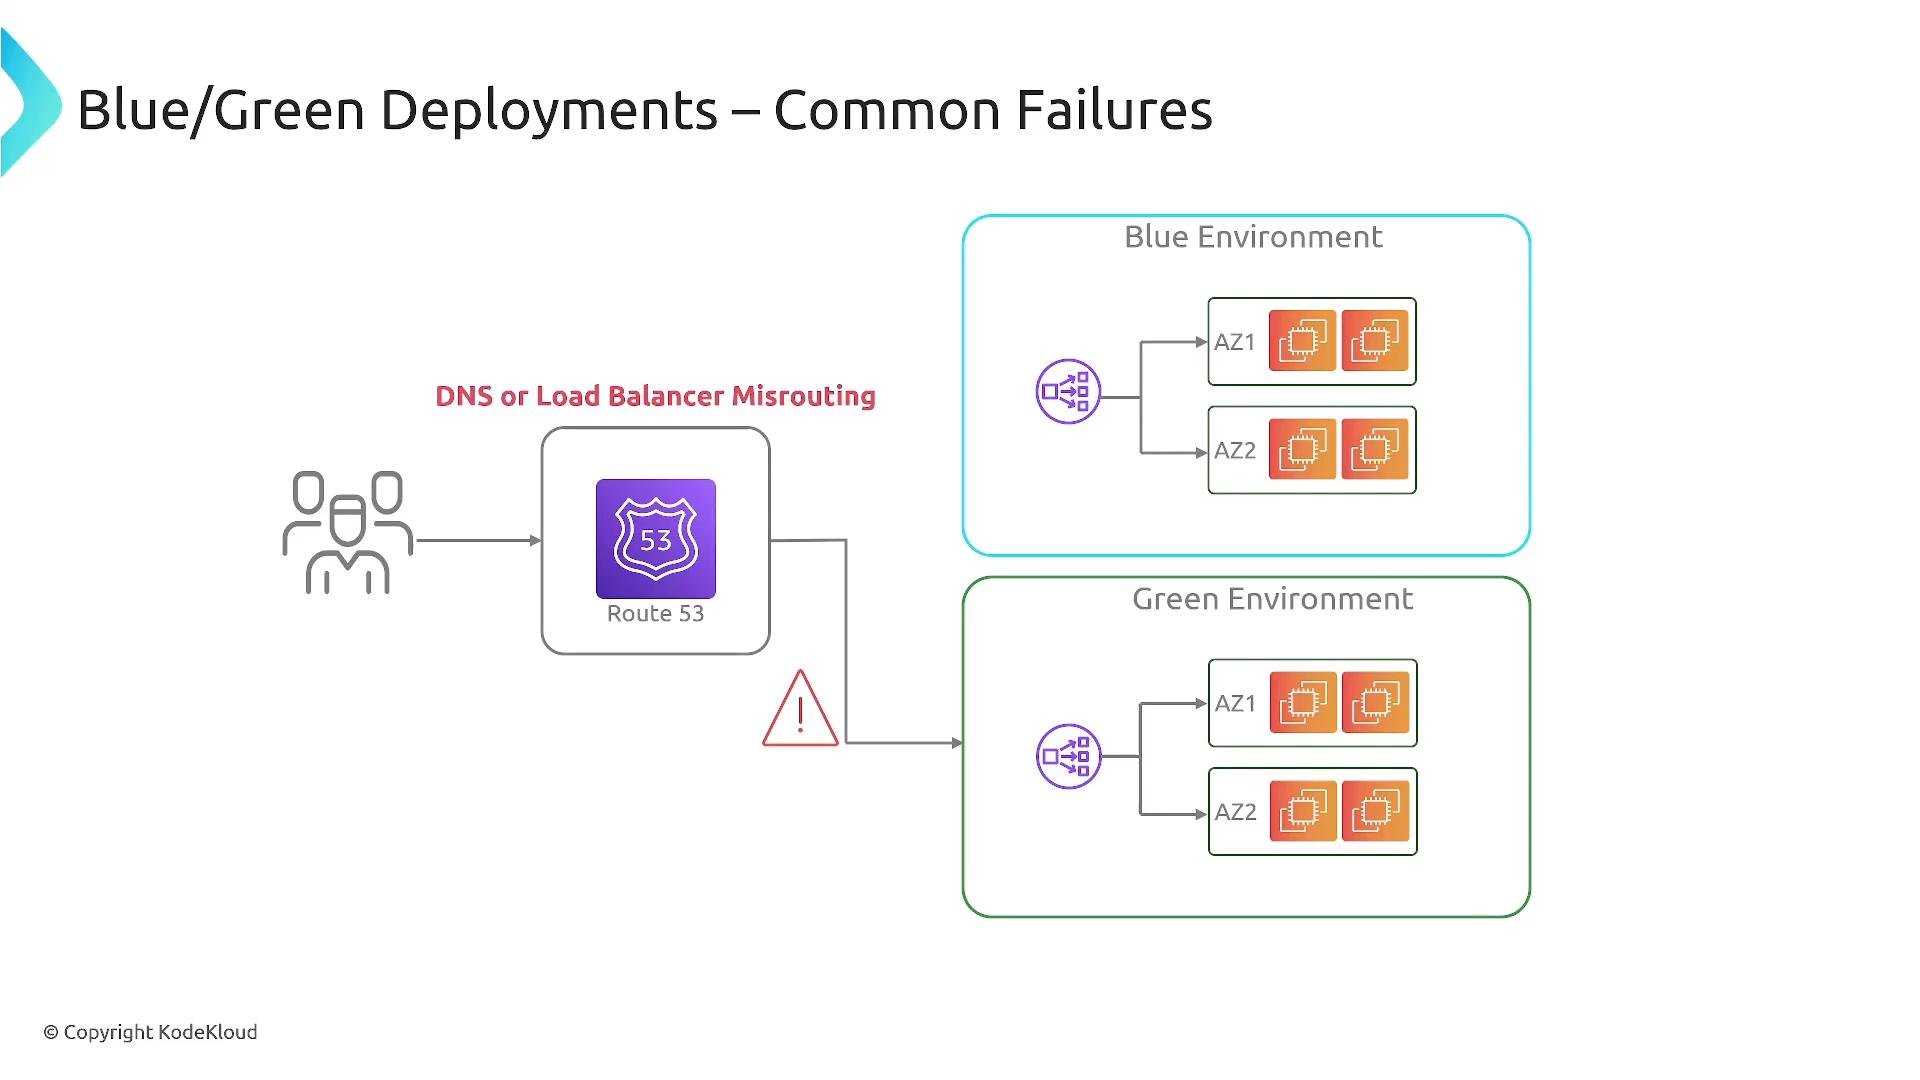
Pay careful attention to infrastructure parity and routing configuration. DNS TTLs, client-side DNS caching, or misconfigured load balancer target groups can cause rollbacks or percentage-based shifts to behave unpredictably. Test rollback procedures regularly.
Applicability and considerations
- Blue-green works across many AWS services:
- Elastic Beanstalk
- Lambda (via aliases)
- Amazon ECS (task set blue/green)
- Amazon EKS (requires explicit traffic-shifting using Kubernetes Services, Ingress controllers, or a service mesh)
- EC2 + Auto Scaling groups
- EKS does not provide native blue/green traffic shifting; you must implement it using Kubernetes primitives or a service mesh (e.g., Istio) or an external load balancer.
Summary and best practices
- Blue-green deployments provide safe, testable rollouts with minimal downtime and fast rollback capability.
- Use automation (CI/CD), immutable artifacts, consistent health checks, and observability to drive deployment decisions.
- Prefer load-balancer–based switching for immediate cutovers; use Route 53 when DNS-level control or cross-region routing is required.
- Always design for environment parity, define rollback criteria, and consider DNS TTL and client caching when planning rollbacks or canary strategies.
- AWS Route 53: https://docs.aws.amazon.com/Route53/latest/DeveloperGuide/
- AWS CodeDeploy: https://docs.aws.amazon.com/codedeploy/latest/userguide/welcome.html
- Kubernetes and blue/green traffic patterns: https://kubernetes.io/docs/concepts/services-networking/service/