

DynamoDB is intended for high-traffic, rapidly changing workloads where predictable low-latency access and minimal operational overhead are required. Use it for user profiles, session stores, leaderboards, real-time analytics metadata, and other internet‑scale applications.
- Fully managed and serverless: no servers to provision or maintain.
- Seamless scaling and automatic sharding for large data sets.
- Low-latency single-digit millisecond reads/writes.
- Durable and highly available with integrated backups, replication, and recovery options.
Core concepts
- Table — the primary container for items.
- Item — a single record (JSON-like document).
- Attribute — a named field in an item (scalar or nested).
Example: People table (schema-less items)
Primary key design
Every DynamoDB table requires a primary key that uniquely identifies each item. Primary keys determine how data is partitioned and organized.
For the People table above,
PersonID is a good partition key. Avoid using non-unique attributes (e.g., FirstName) as a primary key.
DynamoDB uses the partition key value as input to an internal hash function. When using a composite key, the partition key determines the physical partition while the sort key orders and scopes items within that partition.
Primary key selection is critical for performance and scalability. Choose partition keys that distribute traffic evenly (avoid “hot” partition keys) and use sort keys to model access patterns (ranges, time series, or aggregated grouping).
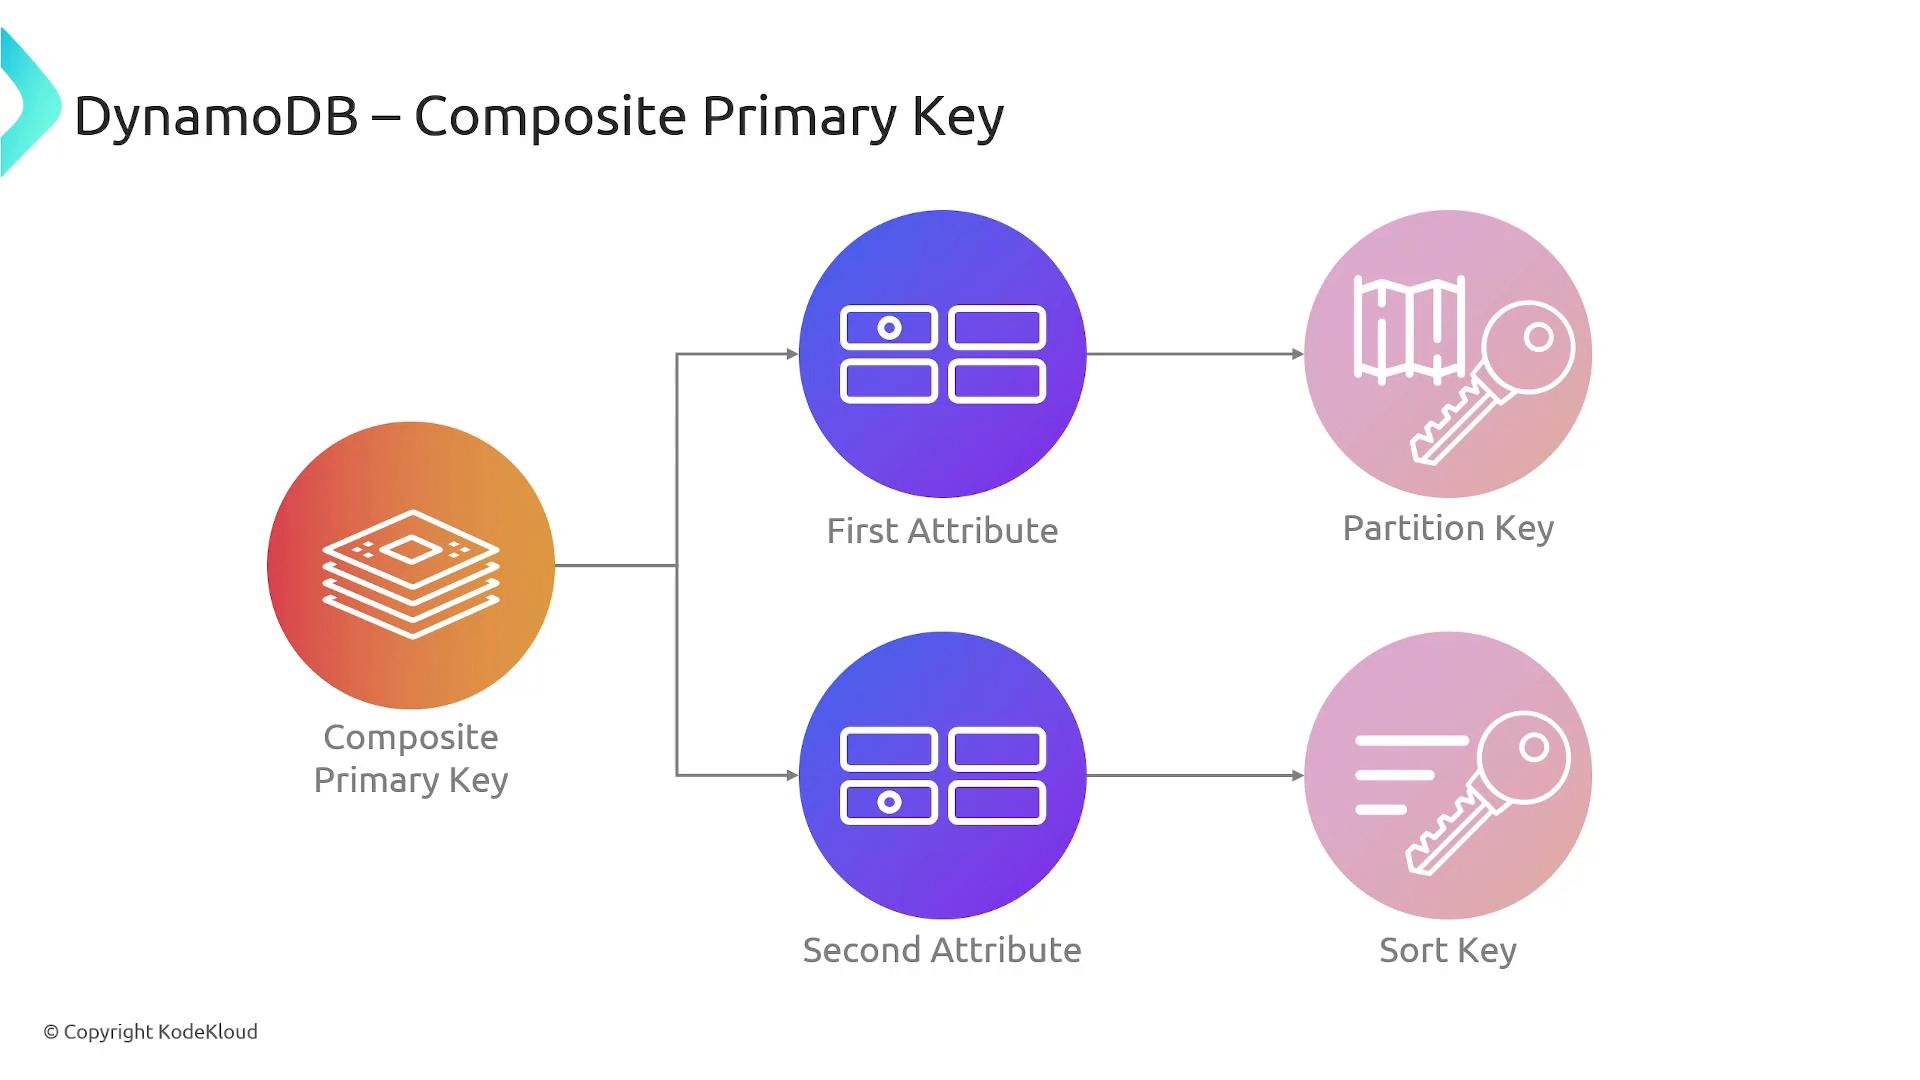
Artist (partition key) + SongTitle (sort key). This lets you fetch all songs by an artist or filter songs within a title range.
- Query all items with a specific
Artist. - Query items for
Artistwith range filters onSongTitle(e.g., between “A” and “M”).
Secondary indexes
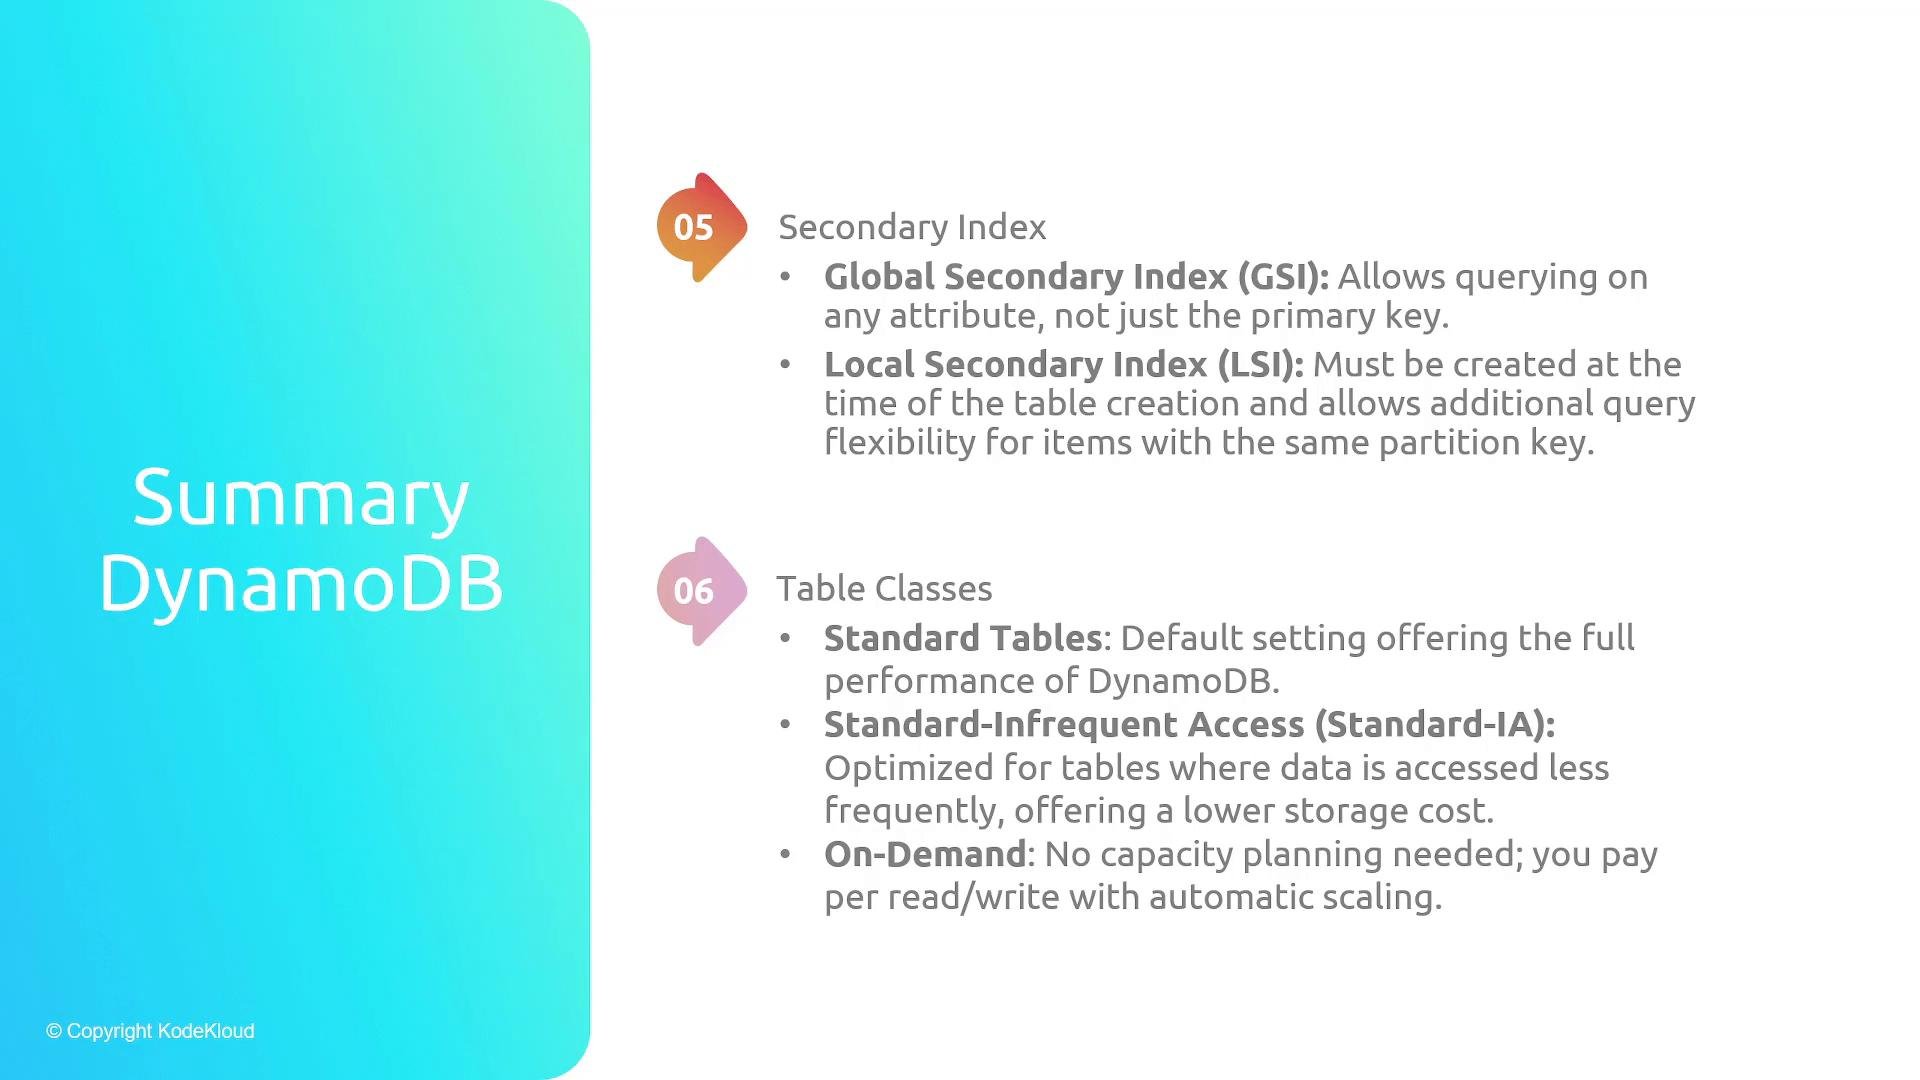
Secondary indexes let you query the table using different keys than the primary key, providing flexible access patterns.
Limits: up to 20 GSIs and 5 LSIs per table.
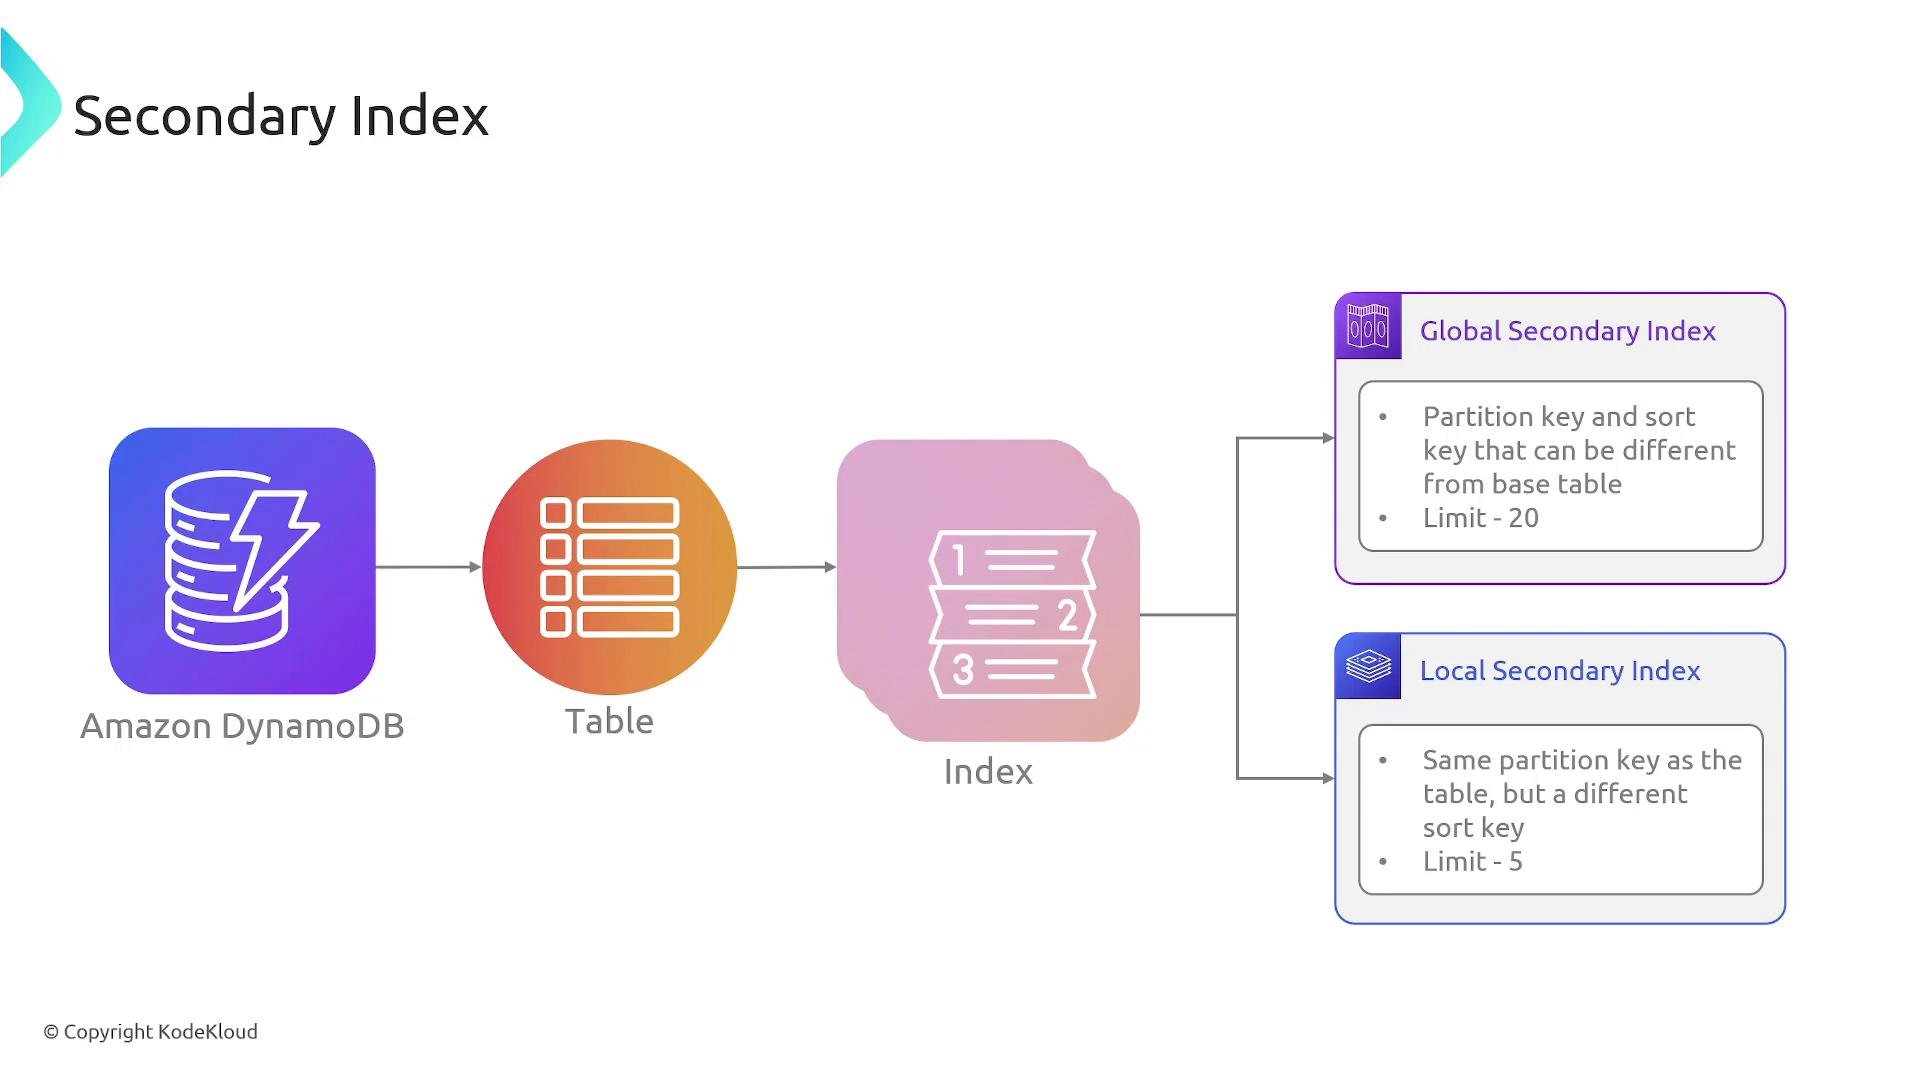
Genre and AlbumTitle. Create a GSI named GenreAlbumTitle:
Genre= partition key for the indexAlbumTitle= sort key for the index
GenreAlbumTitle index:
DynamoDB Streams
DynamoDB Streams capture data modification events (INSERT, MODIFY, REMOVE) and expose them as an ordered stream for up to 24 hours. Each stream record includes metadata and item image(s) depending on the event type. Typical stream record images:- INSERT — the entire new item image.
- MODIFY — the before and after images of the changed item.
- REMOVE — the entire item image before deletion.
EmailAddress).
INSERT example
- Trigger AWS Lambda functions for event-driven workflows.
- Send events to Kinesis Data Streams for complex real-time processing.
Table classes and capacity modes
DynamoDB provides options to balance cost and performance.
All secondary indexes inherit the base table’s table class. You can change table class and capacity mode from the Console, CLI, or SDK.
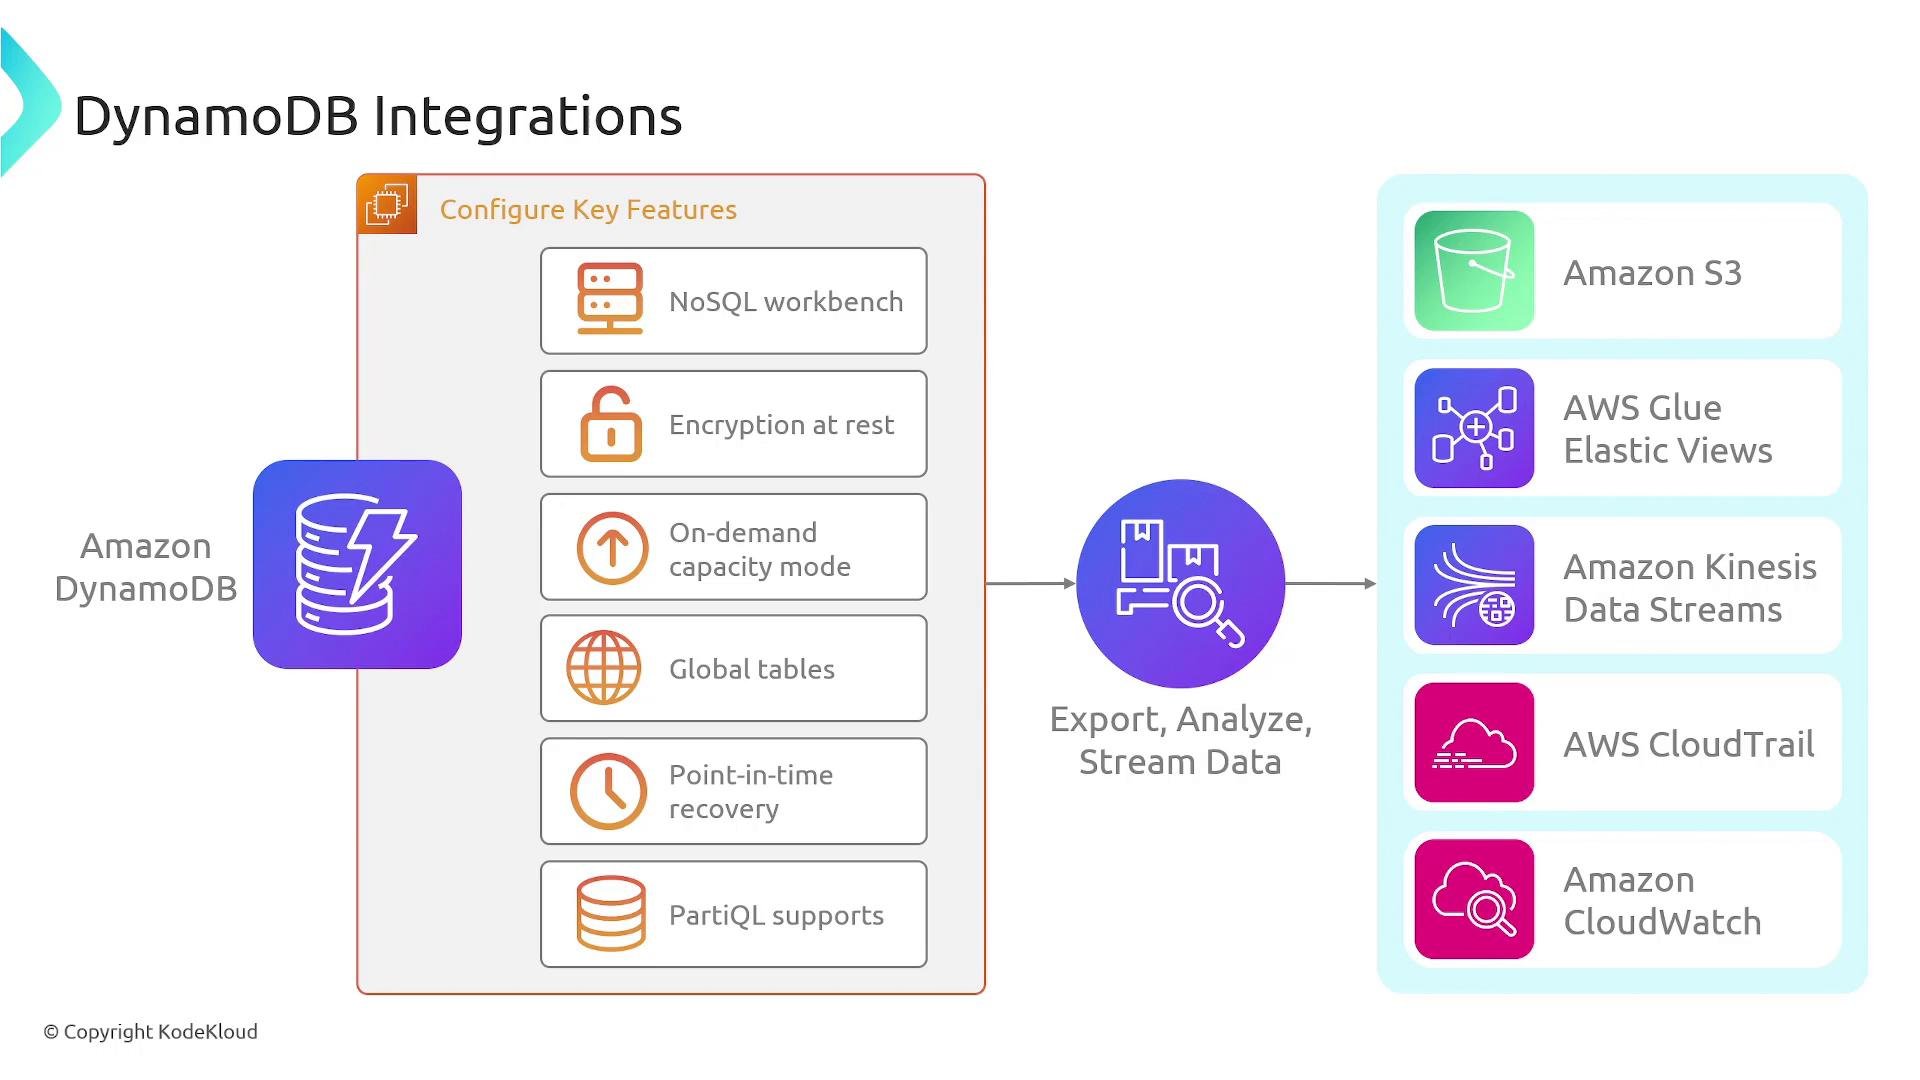
Key features at a glance
- Flexible data models: key-value and document.
- Serverless operation and automatic partitioning.
- On-demand and provisioned capacity modes.
- Secondary indexes (GSI, LSI) for alternate query patterns.
- On-demand backup & restore and point-in-time recovery.
- Global tables for active-active multi‑Region workloads.
- Integration with analytics and streaming services.
Integrations and analytics
DynamoDB works with many AWS services to enable analytics, streaming, and monitoring:- Streams → AWS Lambda for event-driven processing. See: AWS Lambda
- Export to Amazon S3 for archival and downstream analysis. See: Amazon S3
- Use AWS Glue, Amazon Athena, or Amazon Redshift for analytics and ETL.
- Monitor with Amazon CloudWatch and audit with AWS CloudTrail.
- Stream to Amazon Kinesis Data Streams for real-time analytics.
Common use cases
- Internet-scale user profiles, shopping carts, and metadata storage.
- Real-time applications: gaming leaderboards, chat/message metadata, streaming metadata.
- Session stores and caching with consistently low latency.
- Event-driven architectures using Streams + Lambda for near-real-time workflows.
Summary
DynamoDB is a fully managed NoSQL database optimized for performance and scalability. Key takeaways:- Core entities are tables, items, and attributes.
- Choose primary keys carefully:
partition keyorpartition+sort key(composite). - Use GSIs and LSIs to support alternate query patterns.
- DynamoDB Streams enable near real-time processing; stream records are retained for 24 hours.
- Use table classes and capacity modes to optimize cost and performance for your workload.
Links and references
- AWS DynamoDB Documentation
- AWS Lambda
- Amazon S3
- AWS Glue
- Amazon Athena
- Amazon Kinesis Data Streams
- AWS CloudWatch
- AWS CloudTrail