Welcome, Solutions Architects. This lesson—presented by Michael Forrester—explains practical techniques for tuning performance across AWS services. It focuses on the Performance Pillar of the AWS Well-Architected Framework and gives exam-focused guidance and real-world design patterns you can apply to AWS-hosted applications. We concentrate on three high-value strategies that show up frequently in design decisions and exam questions:
  • Auto Scaling (broader than just EC2)
  • Offloading and load distribution (caching, proxies, read replicas, CDNs)
  • Serverless choices that reduce operational overhead and simplify scaling

Auto Scaling — not just for EC2

Auto Scaling is commonly associated with EC2 Auto Scaling groups, but the concept and tooling extend far beyond instances. Many AWS services provide automated scaling (via Application Auto Scaling, service-managed autoscaling, or serverless autoscaling), so you don’t have to manage capacity manually. When comparing manual scaling with Auto Scaling in a design or exam question, prefer AWS-managed or automatic scaling when it meets requirements—especially for hosting platforms and managed databases. Services that support autoscaling patterns include EC2, ECS, Fargate, Lambda, Aurora, DynamoDB, ElastiCache, Keyspaces, Neptune, DocumentDB, and managed Kafka offerings.
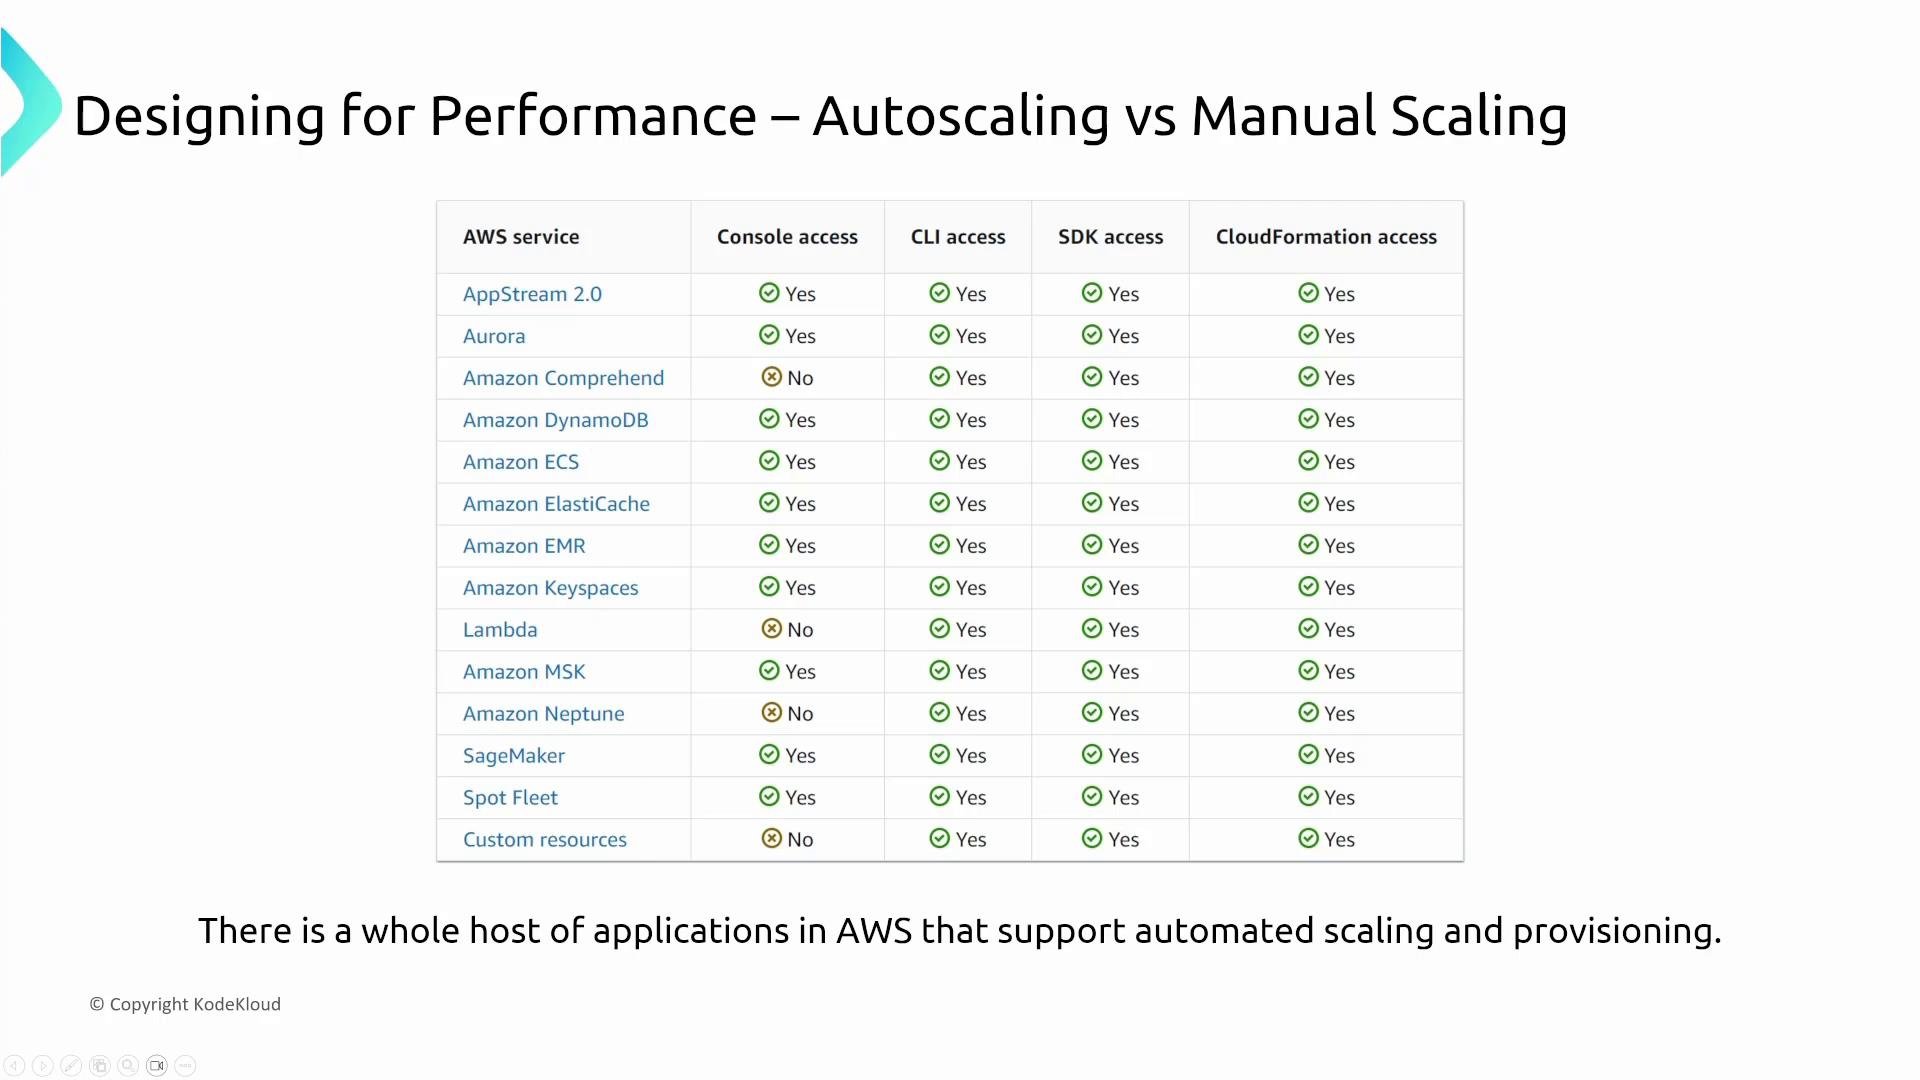
A presentation slide titled "Designing for Performance – Autoscaling vs Manual Scaling" showing a table of AWS services and icons indicating whether each supports Console, CLI, SDK, and CloudFormation access. A footer note reads that many AWS applications support automated scaling and provisioning.
Key points:
  • EC2 Auto Scaling uses Auto Scaling groups and policies (target tracking, step scaling, scheduled scaling).
  • Many managed services offer autoscaling that’s configured for you (serverless) or configurable via Application Auto Scaling.
  • For exam scenarios that require low operational overhead and reliable scaling, select the managed/autoscaled option if constraints (latency, custom OS, stateful needs) permit.
Quick reference table — when to choose autoscaling vs manual scaling

Offloading and Load Distribution

Offloading moves specific work away from your primary system into specialized components so the core system handles less load. Offloading pairs naturally with load balancers and caching mechanisms. Common offloading patterns:
  • Use ELB/ALB/NLB to distribute incoming traffic and prevent any single backend node from being a bottleneck.
  • Offload static content to S3 and serve it via CloudFront so web servers process only dynamic requests.
  • Place proxies or edge logic (NGINX, API Gateway, CloudFront Functions) in front of origins to handle routing, TLS termination, request shaping, or caching.
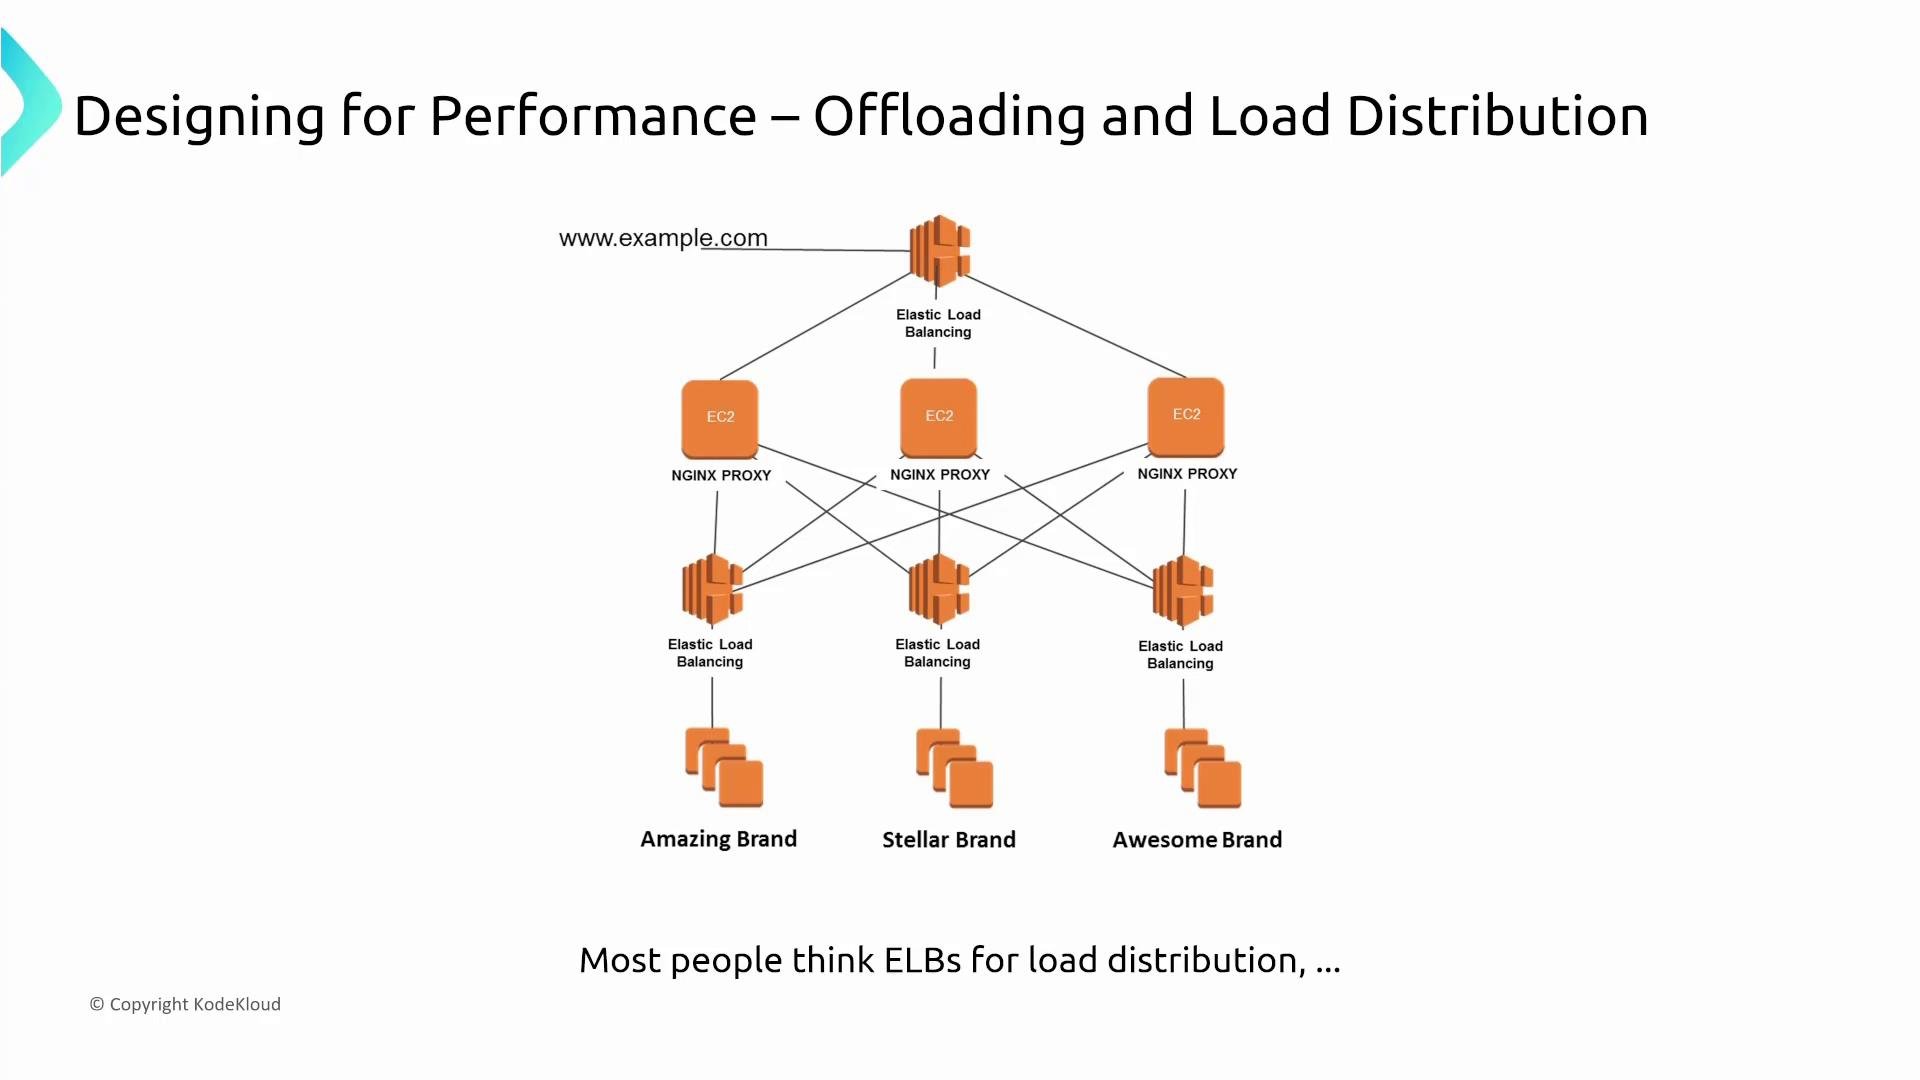
The diagram below illustrates a scenario where client traffic hits an external load balancer, flows through NGINX proxy instances, and then is redistributed to multiple backend load balancers and application groups. While most architectures do not require a proxy layer between load balancers and application load balancers, an intermediary can offload responsibilities such as URL routing, TLS termination, or custom filtering.
A slide titled "Designing for Performance – Offloading and Load Distribution" showing a cloud architecture diagram. Traffic flows from www.example.com through an Elastic Load Balancer to three EC2 NGINX proxy servers, which forward to multiple ELBs and backend instance groups labeled Amazing Brand, Stellar Brand, and Awesome Brand.
Database read/write separation is a classic offloading pattern. Many relational and NoSQL engines let you direct reads to replicas while sending writes to the primary writer.
  • Read replicas absorb the majority of read traffic for read-heavy workloads (for example, workloads with 80/20 read/write ratios or similar). Directing reads to replicas reduces load on the primary writer and lets you scale reads independently.
  • Some services support multi-master or alternative replication modes—these change routing and conflict-handling behaviors, so always examine the service’s replication model before designing.
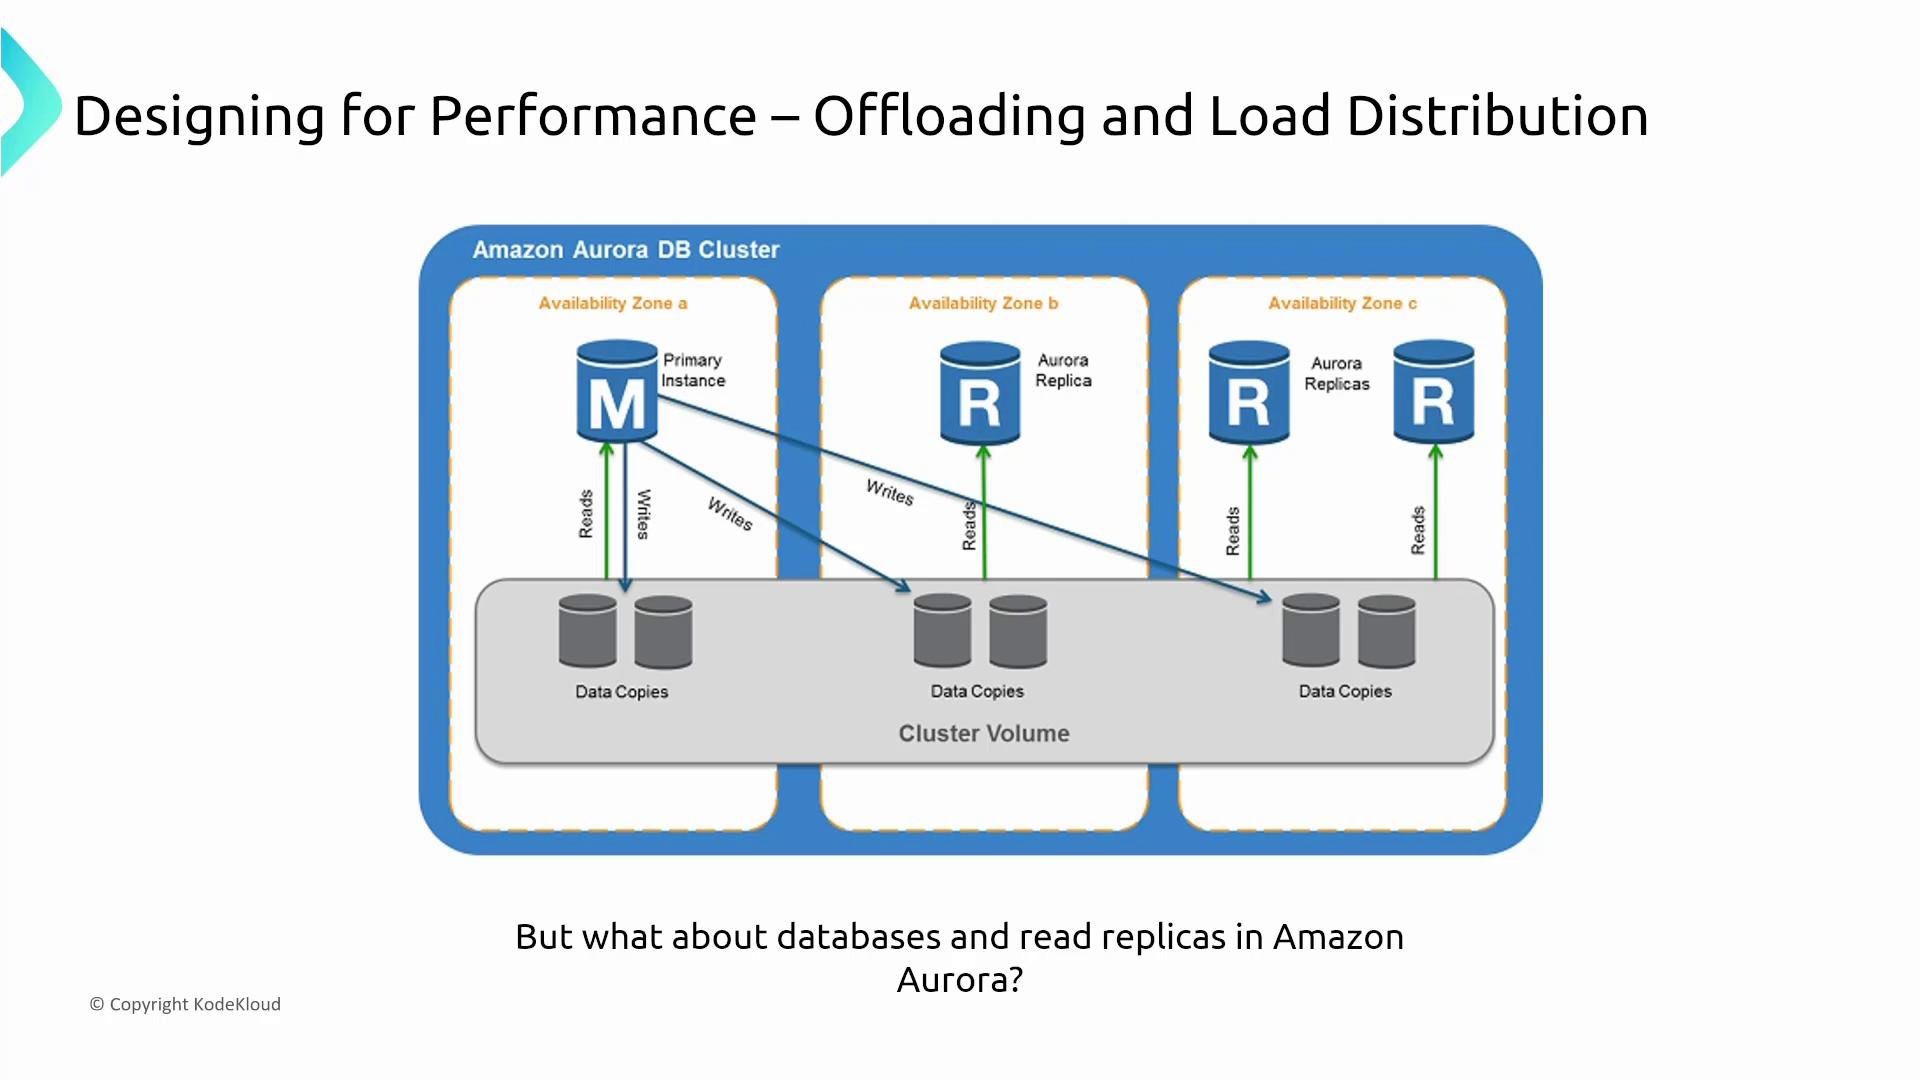
A slide diagram titled "Designing for Performance – Offloading and Load Distribution" showing an Amazon Aurora DB cluster across three availability zones with a primary instance (master) and multiple read replicas. It illustrates a shared cluster volume with data copies and arrows indicating writes to the primary and reads served by the replicas.
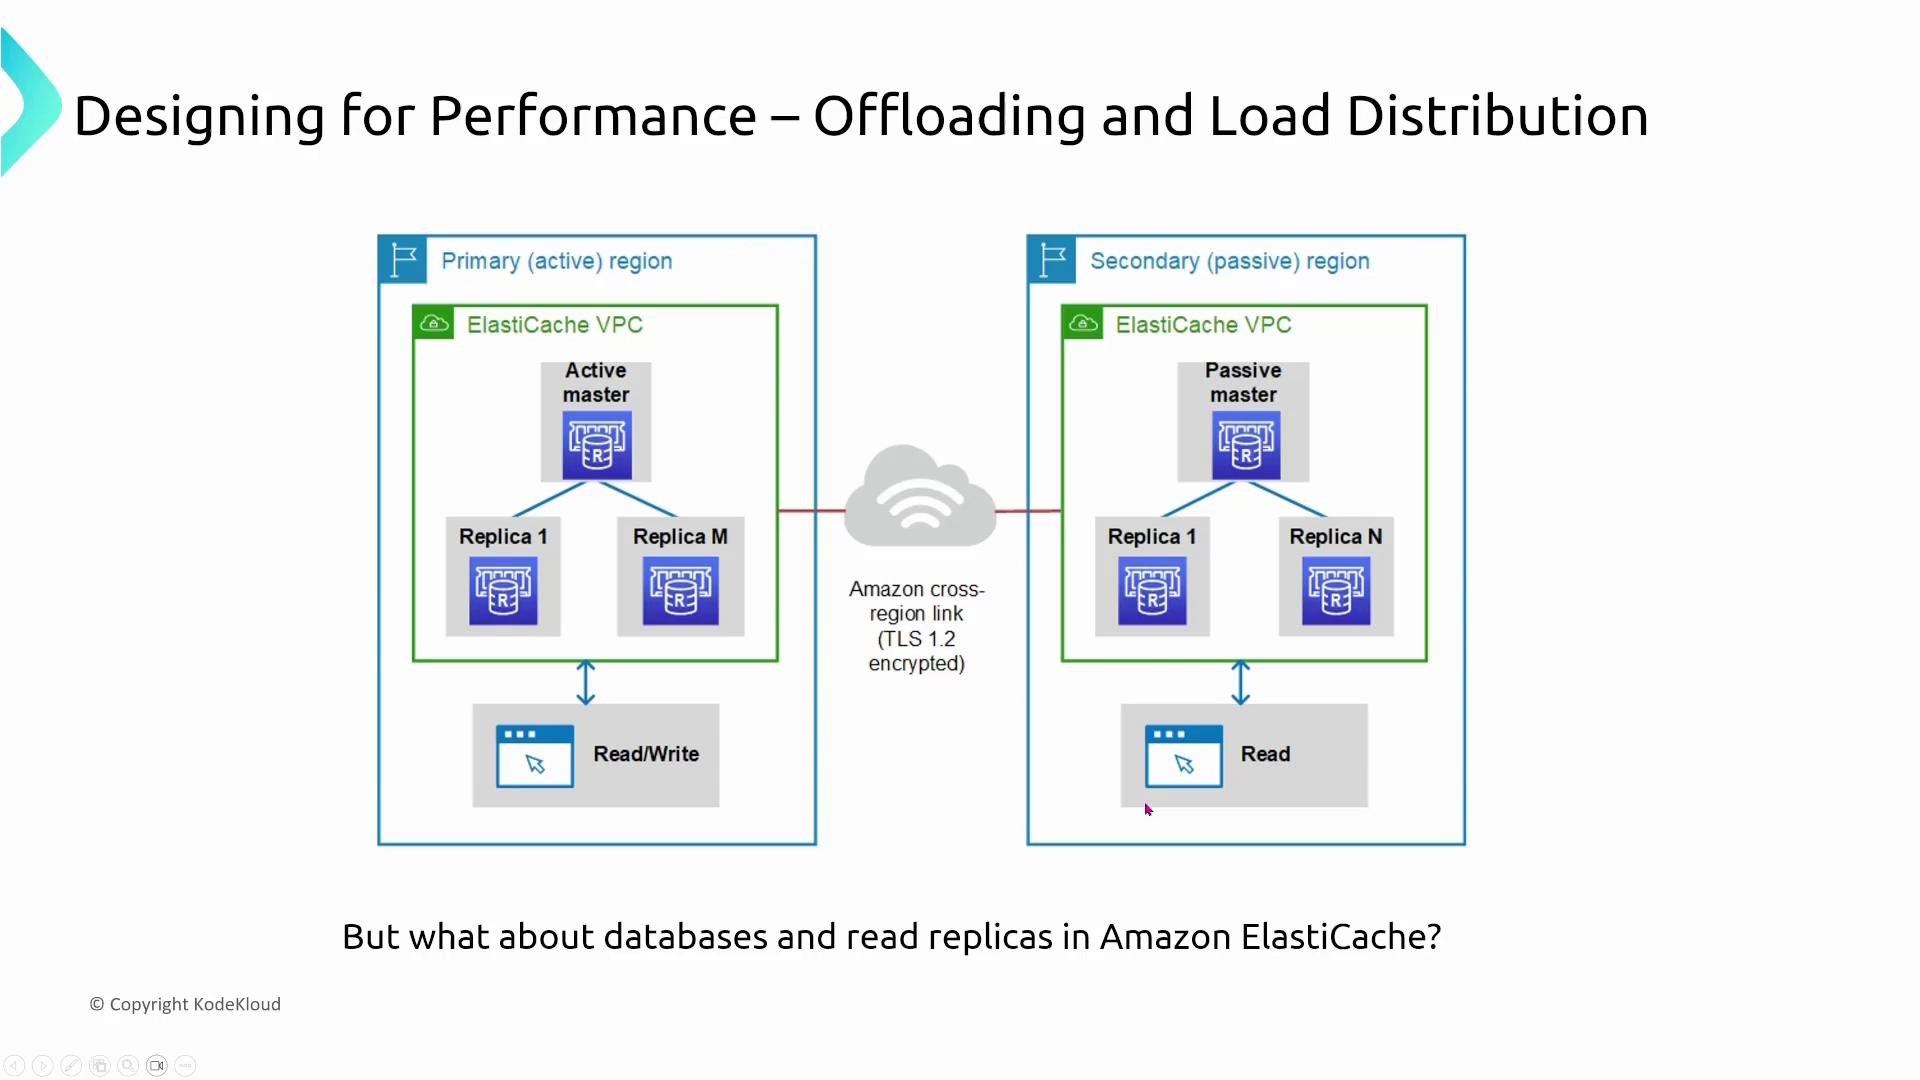
Caching layers are another important offload technique. ElastiCache (Redis or Memcached) can buffer frequently requested data and reduce queries to your primary database. In multi-region or active/passive setups, a passive master may be on standby for failover while replicas continue serving reads.
A diagram of an Amazon ElastiCache multi-region setup showing a primary (active) region with an active master and read/write replicas and a secondary (passive) region with a passive master and read replicas. The two regions are linked by an Amazon cross-region TLS-encrypted connection.
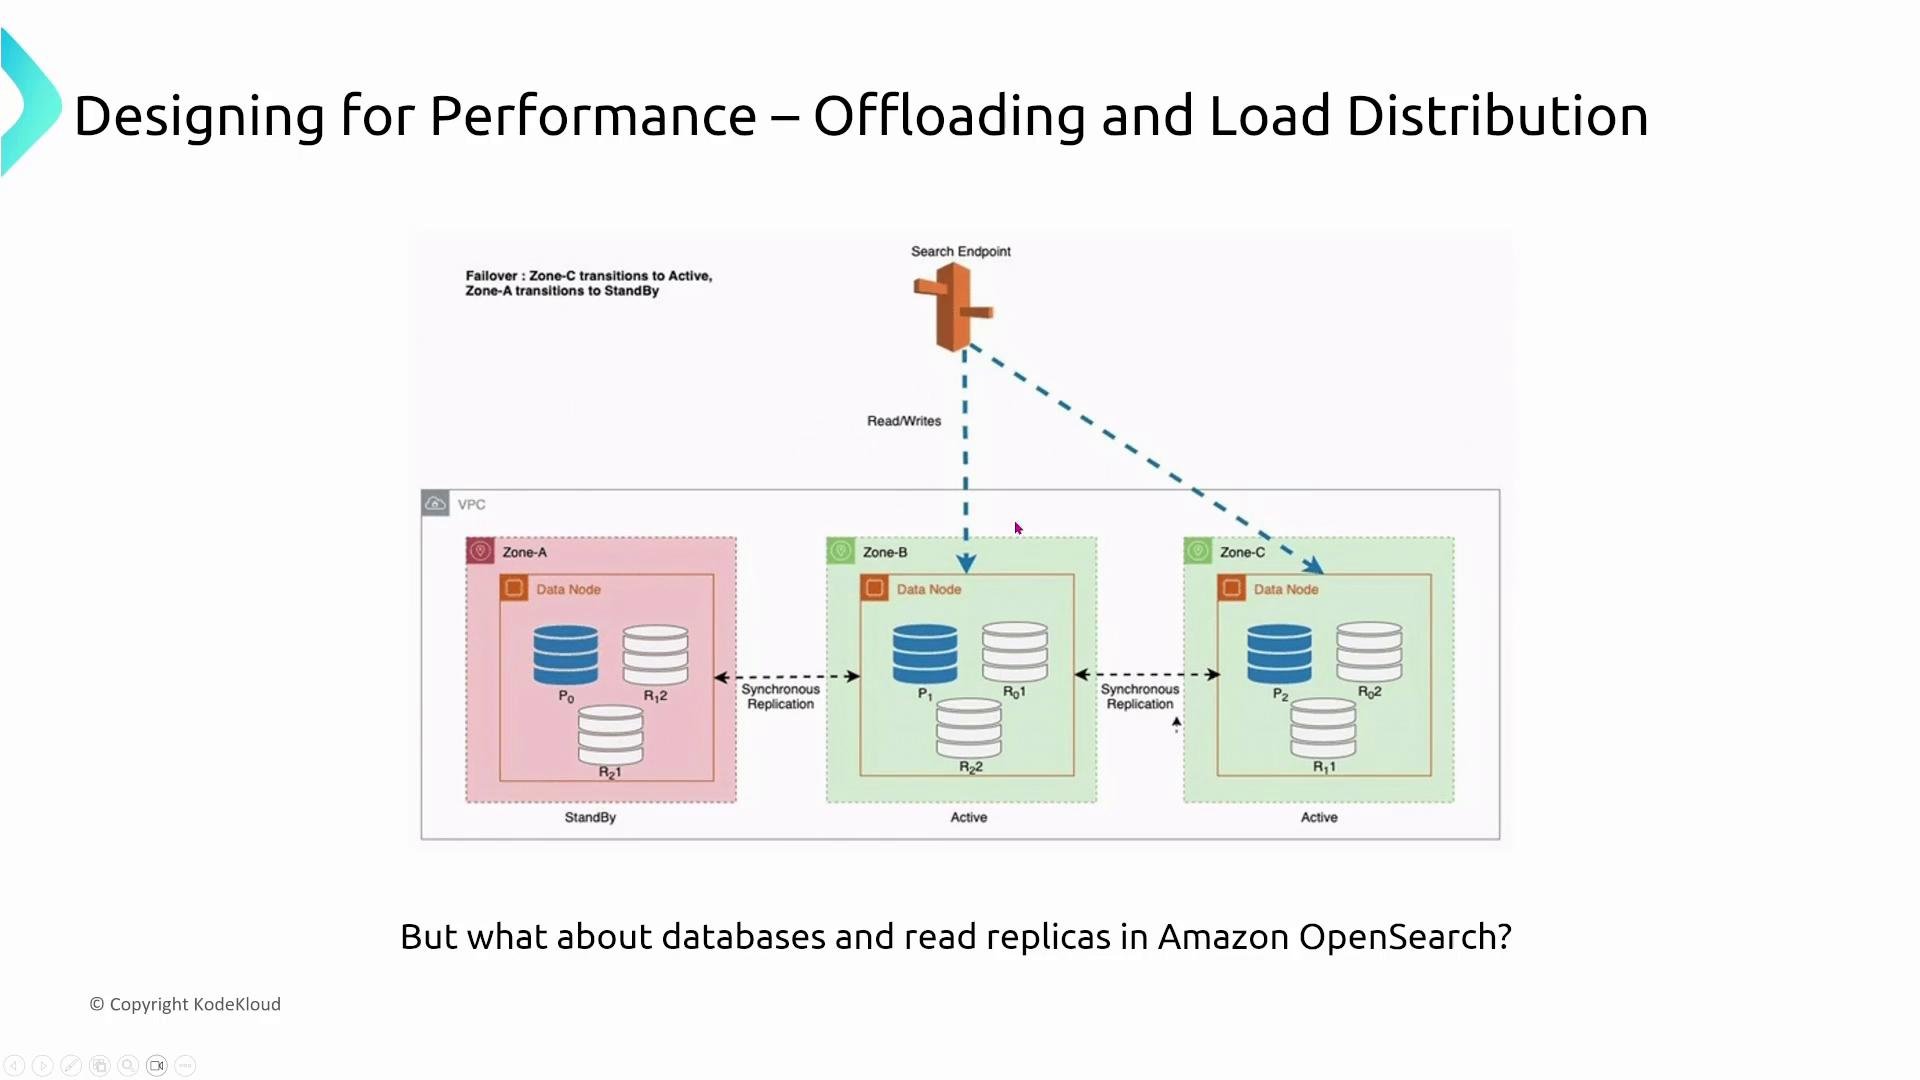
Search and indexing systems (e.g., OpenSearch, DocumentDB when used for queries) separate roles such as data nodes and coordination nodes; they distribute primary/replica shards to balance read/write workloads. Proper shard and replica strategies improve throughput and availability.
A slide titled "Designing for Performance – Offloading and Load Distribution" showing an AWS/OpenSearch architecture with three availability zones. It diagrams data nodes, primary/replica shards, synchronous replication between zones, and a search endpoint routing read/write traffic.
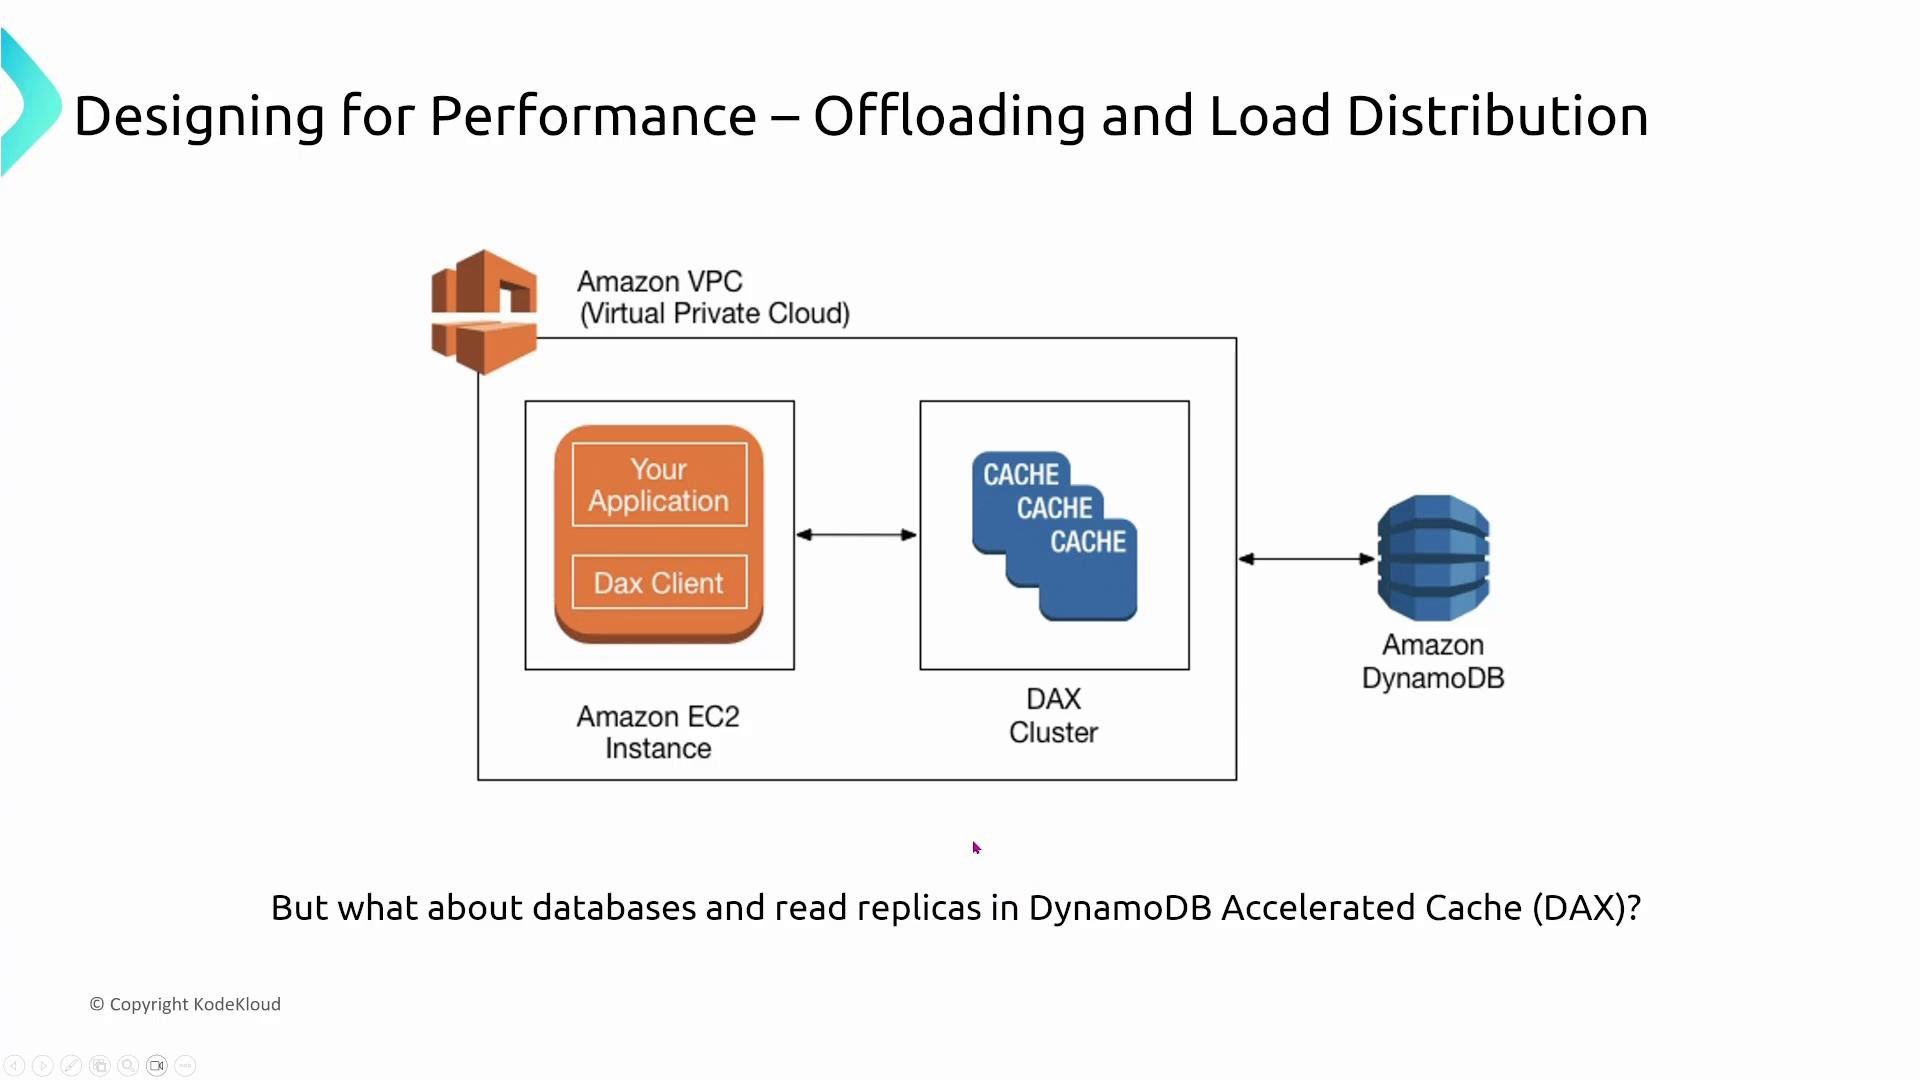
DAX (DynamoDB Accelerator) is an in-memory cache built for DynamoDB that reduces latency for read-heavy workloads and offloads repeated requests from DynamoDB.
A diagram of an AWS architecture in a VPC showing an Amazon EC2 instance (running your application and a DAX client) connecting to a DAX cache cluster, which in turn communicates with Amazon DynamoDB.
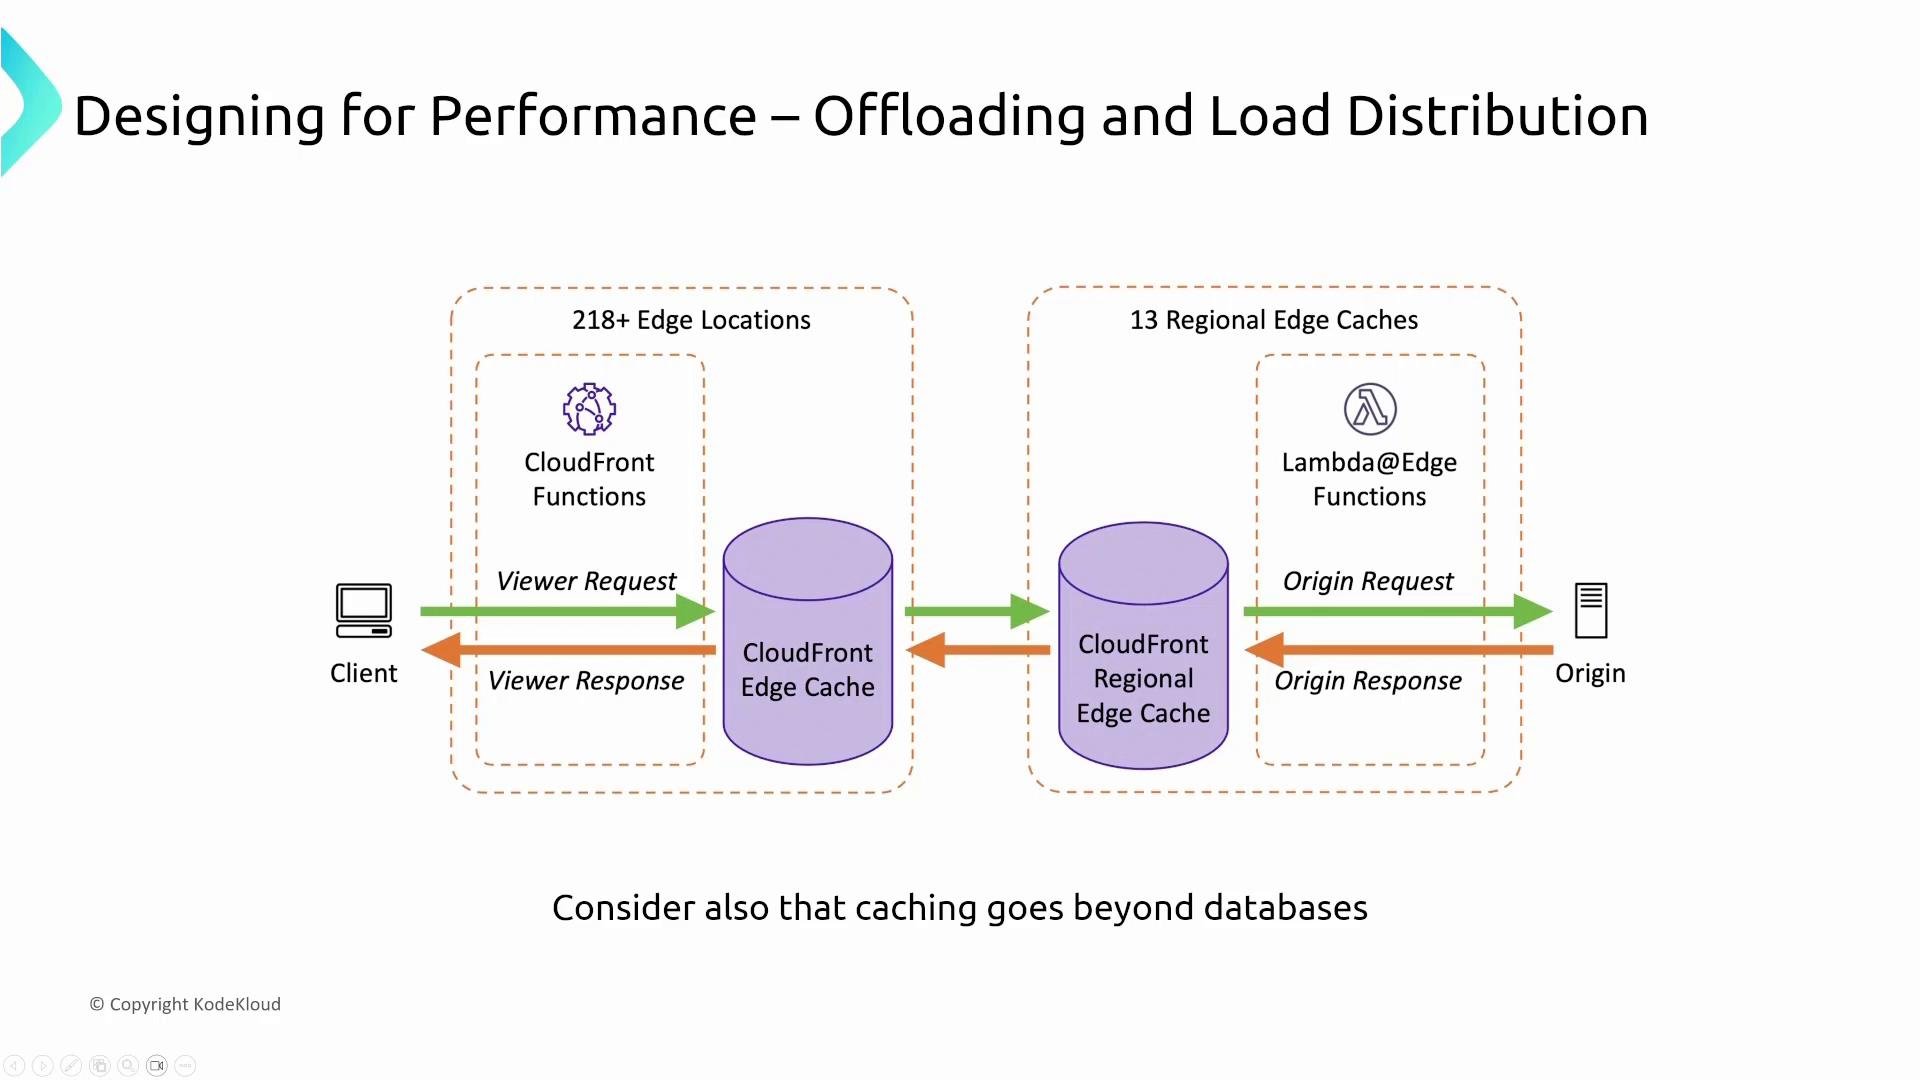
Content Delivery Networks such as CloudFront are global offloading engines for static and cacheable content. CloudFront replicates content to many edge locations and regional caches, reducing latency and origin load. CloudFront also supports lightweight edge logic via CloudFront Functions and Lambda@Edge for request/response manipulation closer to the viewer.
A network diagram titled "Designing for Performance – Offloading and Load Distribution" showing a client, CloudFront edge caches (218+ edge locations) and regional edge caches (13 regional edge caches), and the origin server. It highlights CloudFront Functions handling viewer requests/responses and Lambda@Edge functions handling origin requests/responses to illustrate caching and request flow.
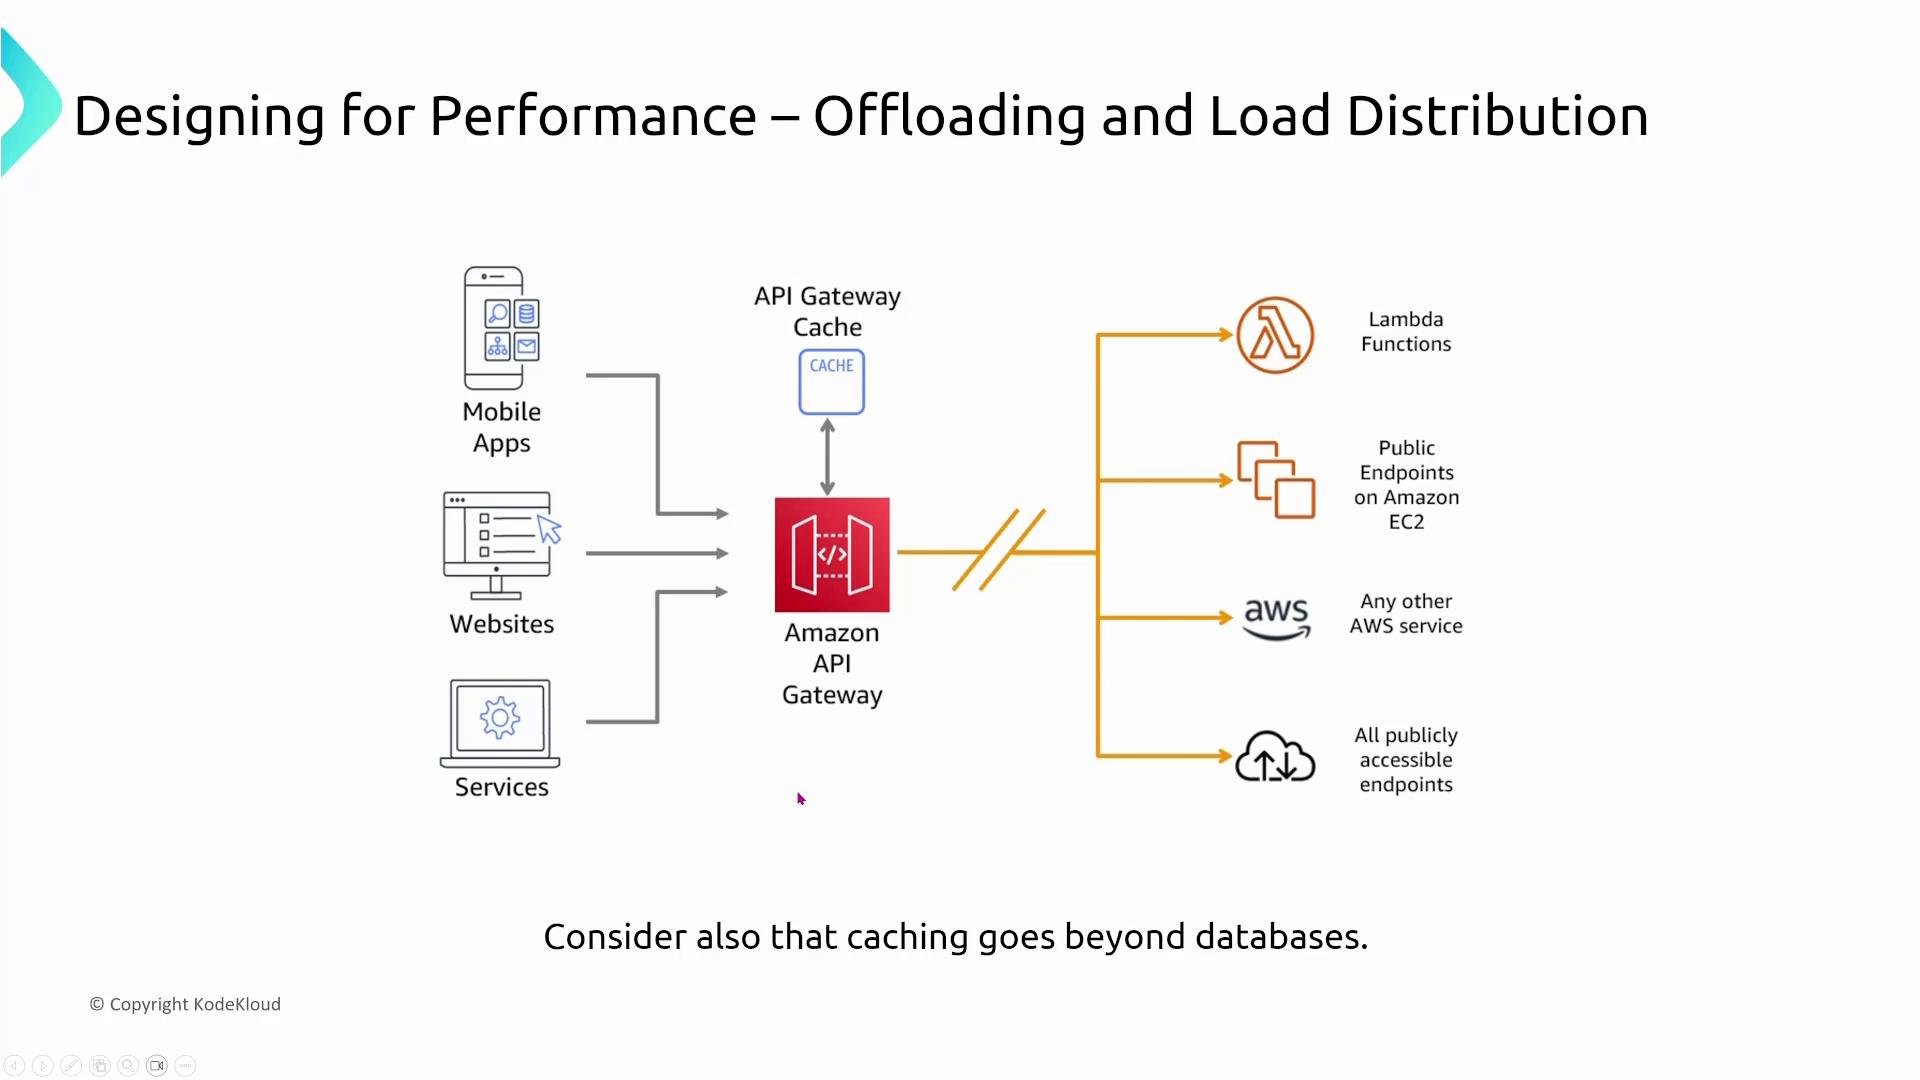
API Gateway supports caching for REST and HTTP APIs, which is useful to accelerate read-only or idempotent endpoints and reduce backend compute load.
A diagram titled "Designing for Performance – Offloading and Load Distribution" showing mobile apps, websites and services sending requests to an Amazon API Gateway with an API cache. The gateway then routes traffic to backends such as Lambda functions, public EC2 endpoints, other AWS services, and publicly accessible endpoints.

Serverless: built-in scaling and lower operational overhead

Serverless services (AWS Lambda, Fargate, Aurora Serverless, Redshift Serverless, EMR Serverless, etc.) shift many operational responsibilities to AWS, including capacity, scaling, and patching. Serverless typically offers:
  • Automatic, fine-grained scaling per request or per workload
  • Minimal operational overhead compared to maintaining Auto Scaling groups and server fleets
  • Cost benefits for spiky or unpredictable workloads (pay-per-use)
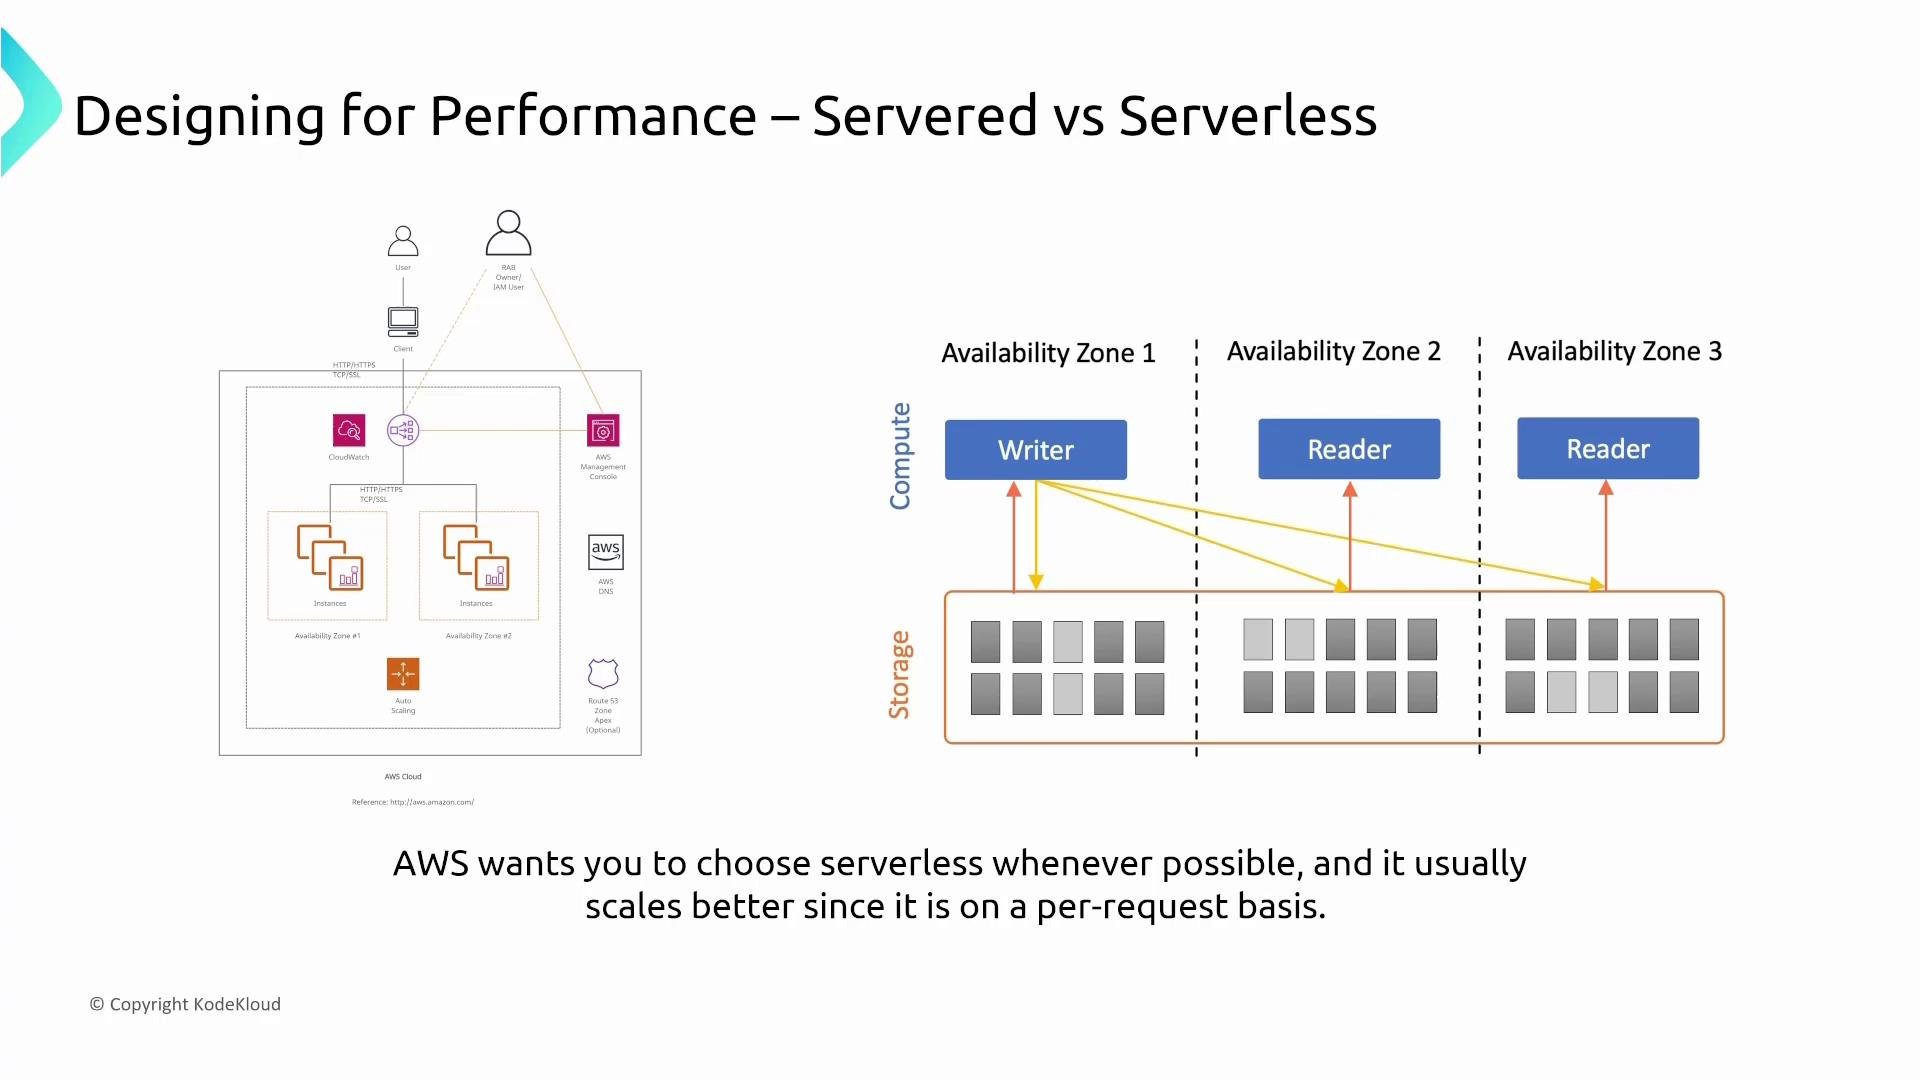
When requirements emphasize minimizing operational overhead and per-request scalability, serverless options are frequently the best answer—if they meet constraints such as latency, runtime, or customization needs.
A presentation slide titled "Designing for Performance – Servered vs Serverless" showing AWS architecture diagrams. On the right it illustrates availability zones with a writer and multiple readers accessing shared storage, with a note recommending serverless for better per-request scaling.

Summary and exam guidance

This lesson emphasized three performance-focused strategies:
  1. Auto Scaling — Autoscaling is available across many AWS services (not only EC2). Prefer autoscaling when the service supports it and the use case allows.
  2. Offloading and load distribution — Use load balancers, caches, read replicas, and CDNs to separate concerns and reduce load on primary systems (e.g., reads vs writes, static vs dynamic content).
  3. Serverless — Choose serverless to reduce operational overhead and gain automatic, per-request scaling when it satisfies the application constraints.
SAA-style exam tips:
  • If an option offers autoscaling and another requires manual scaling, prefer the autoscaled option when it meets the requirements.
  • If you can offload reads, caching, or static content and that meets functional requirements, offloading usually yields better performance.
  • If multiple answers meet the requirements and one is serverless while the others are server-based, favor the serverless option from an AWS best-practices perspective (only if it meets constraints).
Exam tip: Look for options that reduce operational overhead and improve automatic scaling—managed autoscaling and serverless options are often the correct choice when they meet the requirements.
Thanks for reading. I’m Michael Forrester — see you in the community.

Watch Video